
主题
智能体与智能体式 AI
NOTE
本节讲解如何用 langchain4j-agentic 模块构建智能体式 AI 应用。请注意,整个模块都应被视为实验性的,且在未来版本中可能变化。
智能体系统
尽管对 AI 智能体没有公认的统一定义,但一些正在成型的模式展示了如何协调并组合多个 AI 服务的能力,以创建能完成更复杂任务的、融入 AI 的应用。这些模式常被称为"智能体系统"或"智能体式 AI"。它们通常涉及用大语言模型(LLM)来编排任务的执行、管理工具使用,并在多次交互之间维持上下文。
根据 Anthropic 研究者发表的一篇文章,这些智能体系统架构可以被归为两大类:工作流(workflows)与纯智能体(pure agents)。
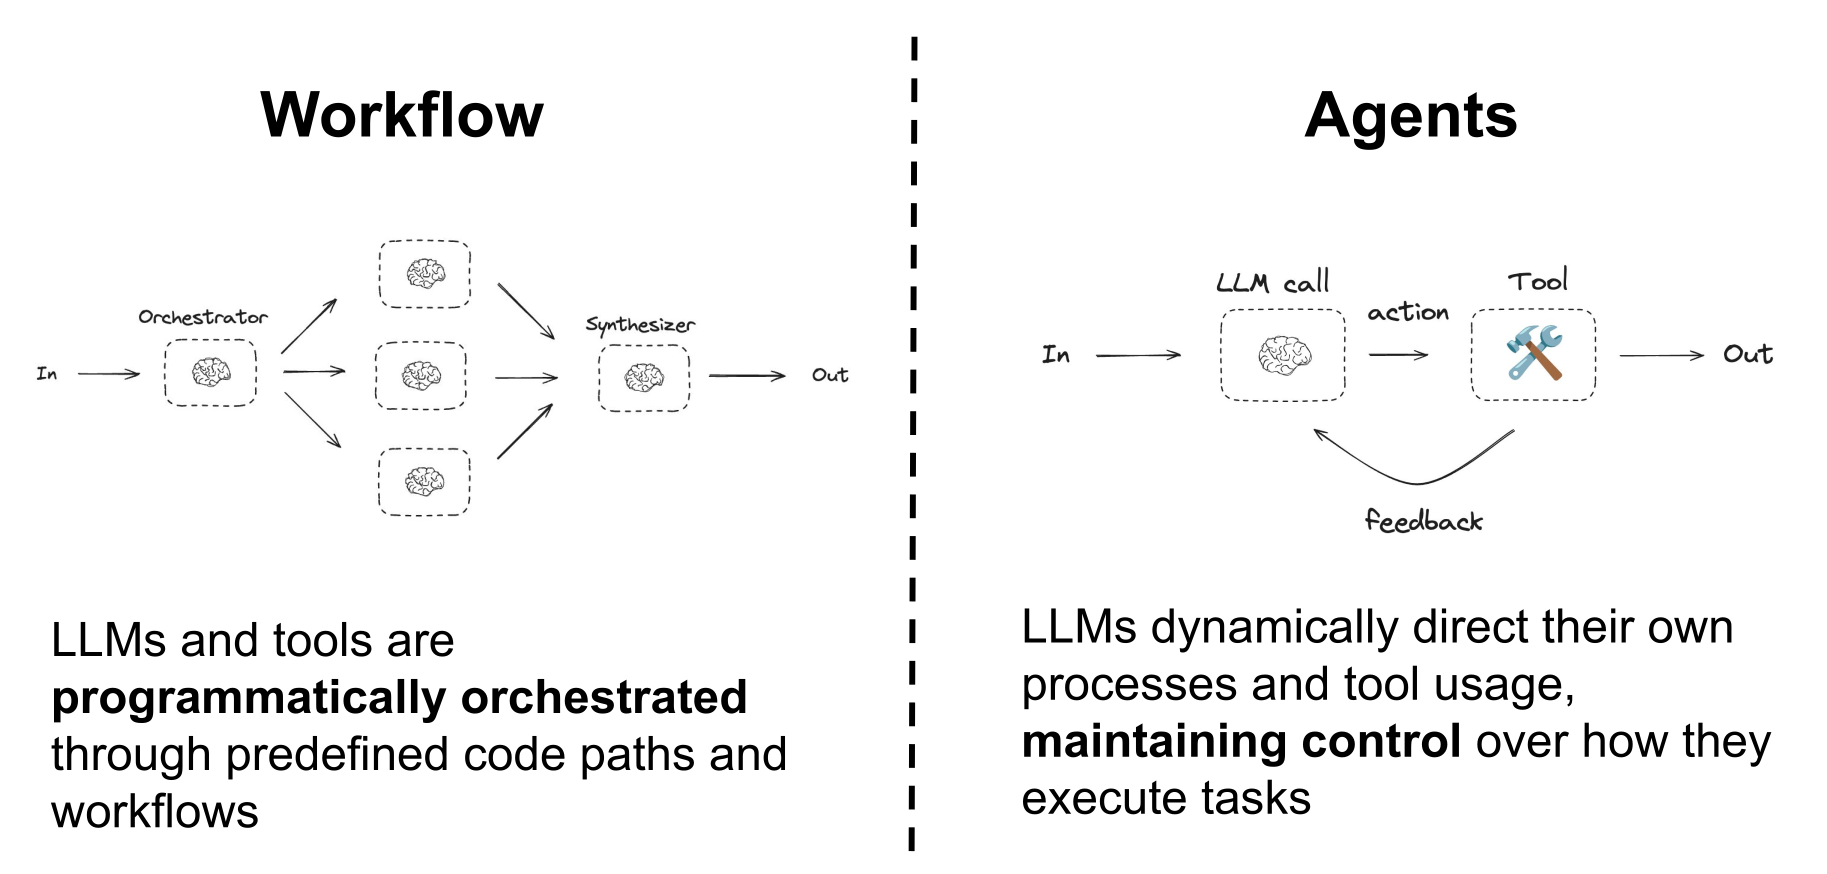
本教程所讨论的 langchain4j-agentic 模块,提供了一组抽象与工具,帮你构建工作流式与纯智能体式 AI 应用。它让你能定义工作流、管理工具使用,并在与不同 LLM 的交互之间维持上下文。
LangChain4j 中的智能体
LangChain4j 中的一个智能体用一个 LLM 执行某个特定任务或一组任务。一个智能体可以用一个只带单个方法的接口来定义,方式与一个普通 AI 服务类似,只需在其上添加 @Agent 注解。
java
public interface CreativeWriter {

    @UserMessage("""
            You are a creative writer.
            Generate a draft of a story no more than
            3 sentences long around the given topic.
            Return only the story and nothing else.
            The topic is {{topic}}.
            """)
    @Agent("Generates a story based on the given topic")
    String generateStory(@V("topic") String topic);
}好的实践是同时在该注解中提供一段对智能体用途的简短描述,尤其当它打算被用于纯智能体模式时——在那里其他智能体需要知道本智能体的能力,才能就如何、何时使用它做出明智决定。这段描述也可以在构建智能体时用智能体 builder 的 description 方法以编程方式提供。
智能体也必须有一个在智能体系统内唯一标识它的名字。这个名字可以在 @Agent 注解中指定,也可以用智能体 builder 的 name 方法以编程方式指定。若未指定,则取自带 @Agent 注解的那个方法的名字。
现在可以用 AgenticServices.agentBuilder() 方法构建这个智能体的一个实例,指定要使用的接口与聊天模型。
java
CreativeWriter creativeWriter = AgenticServices
        .agentBuilder(CreativeWriter.class)
        .chatModel(myChatModel)
        .outputKey("story")
.build();本质上,智能体就是普通的 AI 服务,提供同样的特性,但额外能与其它智能体组合,以创建更复杂的工作流与智能体系统。
与 AI 服务的另一个主要区别是 outputKey 参数的存在,它用来指定一个共享变量的名字,智能体调用的结果会被存入其中,以便在同一智能体系统中的其他智能体可用。或者,输出名也可以直接声明在 @Agent 注解中,而非像本例这样以编程方式声明,从而它可以在代码里省略、被添加到那里。
java
@Agent(outputKey = "story", description = "Generates a story based on the given topic")AgenticServices 类提供了一组静态工厂方法,用来创建并定义 langchain4j-agentic 框架所提供的各种智能体。
引入 AgenticScope
langchain4j-agentic 模块引入了 AgenticScope 的概念,它是参与某个智能体系统的各智能体之间共享的一组数据。AgenticScope 用于存储共享变量,这些变量可由某个智能体写入以传达它所产生的结果,也可被另一个智能体读取以凑齐它执行任务所需的信息。这让各智能体能有效地协作,按需共享信息与结果。
AgenticScope 还会自动注册其他相关信息,例如所有智能体调用的序列及其响应。它在智能体系统的主智能体被调用时自动创建,并在必要时通过回调以编程方式提供。AgenticScope 的各种可能用法,将在讨论 langchain4j-agentic 所实现的智能体模式时,通过实践示例加以阐明。
工作流模式
langchain4j-agentic 模块提供了一组抽象,用于以编程方式编排多个智能体并创建智能体工作流模式。这些模式可以被组合以创建更复杂的工作流。
顺序工作流
顺序工作流是最简单的模式,其中多个智能体被依次调用,每个智能体的输出作为输入传给下一个智能体。当你有一系列需要按特定顺序执行的任务时,这个模式很有用。
例如,用之前定义的 CreativeWriter 智能体,再补上一个 AudienceEditor 智能体会是好主意,它能编辑所生成的故事以更好地贴合特定受众
java
public interface AudienceEditor {

    @UserMessage("""
        You are a professional editor.
        Analyze and rewrite the following story to better align
        with the target audience of {{audience}}.
        Return only the story and nothing else.
        The story is "{{story}}".
        """)
    @Agent("Edits a story to better fit a given audience")
    String editStory(@V("story") String story, @V("audience") String audience);
}并再补上一个非常相似、但对特定风格做同样工作的 StyleEditor。
java
public interface StyleEditor {

    @UserMessage("""
        You are a professional editor.
        Analyze and rewrite the following story to better fit and be more coherent with the {{style}} style.
        Return only the story and nothing else.
        The story is "{{story}}".
        """)
    @Agent("Edits a story to better fit a given style")
    String editStory(@V("story") String story, @V("style") String style);
}请注意,这个智能体的输入参数带有一个变量名注解。实际上,传给智能体的参数值并非直接提供,而是从带有那些名字的 AgenticScope 共享变量中取。这让智能体能访问工作流中前序智能体的输出。若智能体类编译时启用了 -parameters 选项、从而在运行时保留了方法参数名,那么 @V 注解可以省略,变量名会从参数名自动推断。
此时就可以创建一个把这三个智能体组合起来的顺序工作流,其中 CreativeWriter 的输出被同时传给 AudienceEditor 与 StyleEditor,而最终输出是经编辑的故事。
java
CreativeWriter creativeWriter = AgenticServices
        .agentBuilder(CreativeWriter.class)
        .chatModel(BASE_MODEL)
        .outputKey("story")
        .build();

AudienceEditor audienceEditor = AgenticServices
        .agentBuilder(AudienceEditor.class)
        .chatModel(BASE_MODEL)
        .outputKey("story")
        .build();

StyleEditor styleEditor = AgenticServices
        .agentBuilder(StyleEditor.class)
        .chatModel(BASE_MODEL)
        .outputKey("story")
        .build();

UntypedAgent novelCreator = AgenticServices
        .sequenceBuilder()
        .subAgents(creativeWriter, audienceEditor, styleEditor)
        .outputKey("story")
        .build();

Map<String, Object> input = Map.of(
        "topic", "dragons and wizards",
        "style", "fantasy",
        "audience", "young adults"
);

String story = (String) novelCreator.invoke(input);这里,novelCreator 智能体实际上是一个实现了顺序工作流的智能体系统,它把三个子智能体依次调用组合起来。由于这个智能体的定义没有提供一个带类型的接口,sequence 智能体 builder 会返回一个 UntypedAgent 实例,它是一个能用一个输入 map 调用的通用智能体。
java
public interface UntypedAgent {
    @Agent
    Object invoke(Map<String, Object> input);
}那个输入 map 中的值会被复制到 AgenticScope 共享变量中,以便子智能体访问。novelCreator 智能体的输出也取自 AgenticScope 中名为 "story" 的共享变量,它在小说创作与编辑工作流的执行期间被其他所有智能体先后改写。
请注意,单个智能体也可以被定义为 UntypedAgent 实例,而无需提供一个带类型的接口。例如,CreativeWriter 智能体本可以这样定义:
java
UntypedAgent creativeWriter = AgenticServices.agentBuilder()
        .chatModel(BASE_MODEL)
        .description("Generate a story based on the given topic")
        .userMessage("""
                You are a creative writer.
                Generate a draft of a story no more than
                3 sentences long around the given topic.
                Return only the story and nothing else.
                The topic is {{topic}}.
                """)
        .inputKey(String.class, "topic")
        .returnType(String.class) // String is the default return type for untyped agents
        .outputKey("story")
.build();另一方面,即便是工作流智能体,也可以可选地提供一个带类型的接口,从而能用强类型的输入与输出来调用它。那种情况下,UntypedAgent 接口可以被替换为一个更具体的接口,比如:
java
public interface NovelCreator {

    @Agent
    String createNovel(@V("topic") String topic, @V("audience") String audience, @V("style") String style);
}以便 novelCreator 智能体能像这样被创建与使用:
java
NovelCreator novelCreator = AgenticServices
        .sequenceBuilder(NovelCreator.class)
        .subAgents(creativeWriter, audienceEditor, styleEditor)
        .outputKey("story")
        .build();

String story = novelCreator.createNovel("dragons and wizards", "young adults", "fantasy");循环工作流
一种更好地发挥 LLM 能力的常见方式,是用它们来迭代地精炼一段文本(比如一个故事),办法是反复调用一个能编辑或改善它的智能体。这可以用一个循环工作流模式达成,其中某个智能体被多次调用,直到满足某个条件。
可以用一个 StyleScorer 智能体,根据风格与要求的契合程度生成一个分数。
java
public interface StyleScorer {

    @UserMessage("""
            You are a critical reviewer.
            Give a review score between 0.0 and 1.0 for the following
            story based on how well it aligns with the style '{{style}}'.
            Return only the score and nothing else.

            The story is: "{{story}}"
            """)
    @Agent("Scores a story based on how well it aligns with a given style")
    double scoreStyle(@V("story") String story, @V("style") String style);
}然后就可以把这个智能体与 StyleEditor 一起用在循环中,迭代地改善故事,直到分数达到某个阈值(如 0.8),或直到达到最大迭代次数。
java
StyleEditor styleEditor = AgenticServices
        .agentBuilder(StyleEditor.class)
        .chatModel(BASE_MODEL)
        .outputKey("story")
        .build();

StyleScorer styleScorer = AgenticServices
        .agentBuilder(StyleScorer.class)
        .chatModel(BASE_MODEL)
        .outputKey("score")
        .build();

UntypedAgent styleReviewLoop = AgenticServices
        .loopBuilder()
        .subAgents(styleScorer, styleEditor)
        .maxIterations(5)
        .exitCondition( agenticScope -> agenticScope.readState("score", 0.0) >= 0.8)
.build();这里,styleScorer 智能体把它的输出写入 AgenticScope 中名为 "score" 的共享变量,而同一个变量在循环的退出条件中被访问与评估。
exitCondition 方法接受一个 Predicate<AgenticScope> 作为参数,默认情况下它会在每次智能体调用之后被评估,让循环一旦条件满足就退出,以尽可能减少智能体调用次数。不过,也可以只在循环末尾检查退出条件,从而强制调用所有智能体之后才测试那个条件,办法是用 testExitAtLoopEnd(true) 方法配置循环 builder。或者,exitCondition 方法也可以接受一个 BiPredicate<AgenticScope, Integer> 作为参数,它接收当前循环迭代计数器作为第二个参数。例如,下面的循环定义:
java
UntypedAgent styleReviewLoop = AgenticServices
        .loopBuilder()
        .subAgents(styleScorer, styleEditor)
        .maxIterations(5)
        .testExitAtLoopEnd(true)
        .exitCondition( (agenticScope, loopCounter) -> {
            double score = agenticScope.readState("score", 0.0);
            return loopCounter <= 3 ? score >= 0.8 : score >= 0.6;
        })
.build();会让循环在前 3 次迭代中分数至少 0.8 时退出,否则就降低质量预期,以至少 0.6 的分数终止循环,甚至在退出条件已满足之后还强制最后一次调用 styleEditor 智能体。
在配置好这个 styleReviewLoop 之后,它可以被视作单个智能体,并与 CreativeWriter 智能体放进一个序列,以创建一个 StyledWriter 智能体
java
public interface StyledWriter {

    @Agent
    String writeStoryWithStyle(@V("topic") String topic, @V("style") String style);
}实现一个把故事生成与风格评审流程结合起来的、更复杂的工作流。
java
CreativeWriter creativeWriter = AgenticServices
        .agentBuilder(CreativeWriter.class)
        .chatModel(BASE_MODEL)
        .outputKey("story")
        .build();

StyledWriter styledWriter = AgenticServices
        .sequenceBuilder(StyledWriter.class)
        .subAgents(creativeWriter, styleReviewLoop)
        .outputKey("story")
        .build();

String story = styledWriter.writeStoryWithStyle("dragons and wizards", "comedy");并行工作流
有时并行调用多个智能体很有用,尤其是当它们能在同一输入上独立工作时。这可以用一个并行工作流模式达成,其中多个智能体被同时调用,它们的输出被组合成一个单一结果。
例如,让我们用电影与美食专家,为一个具有特定心情的惬意夜晚生成几个方案,组合一部电影与一顿契合该心情的餐食。
java
public interface FoodExpert {

    @UserMessage("""
        You are a great evening planner.
        Propose a list of 3 meals matching the given mood.
        The mood is {{mood}}.
        For each meal, just give the name of the meal.
        Provide a list with the 3 items and nothing else.
        """)
    @Agent
    List<String> findMeal(@V("mood") String mood);
}

public interface MovieExpert {

    @UserMessage("""
        You are a great evening planner.
        Propose a list of 3 movies matching the given mood.
        The mood is {mood}.
        Provide a list with the 3 items and nothing else.
        """)
    @Agent
    List<String> findMovie(@V("mood") String mood);
}由于两位专家的工作是独立的,可以用 AgenticServices.parallelBuilder() 方法并行调用它们,如下:
java
FoodExpert foodExpert = AgenticServices
        .agentBuilder(FoodExpert.class)
        .chatModel(BASE_MODEL)
        .outputKey("meals")
        .build();

MovieExpert movieExpert = AgenticServices
        .agentBuilder(MovieExpert.class)
        .chatModel(BASE_MODEL)
        .outputKey("movies")
        .build();

EveningPlannerAgent eveningPlannerAgent = AgenticServices
        .parallelBuilder(EveningPlannerAgent.class)
        .subAgents(foodExpert, movieExpert)
        .executor(Executors.newFixedThreadPool(2))
        .outputKey("plans")
        .output(agenticScope -> {
            List<String> movies = agenticScope.readState("movies", List.of());
            List<String> meals = agenticScope.readState("meals", List.of());

            List<EveningPlan> moviesAndMeals = new ArrayList<>();
            for (int i = 0; i < movies.size(); i++) {
                if (i >= meals.size()) {
                    break;
                }
                moviesAndMeals.add(new EveningPlan(movies.get(i), meals.get(i)));
            }
            return moviesAndMeals;
        })
        .build();

List<EveningPlan> plans = eveningPlannerAgent.plan("romantic");这里,EveningPlannerAgent 所定义的 AgenticScope 的 output 函数让你能把两个子智能体的输出组装起来,创建一个把一部电影与一顿契合所给心情的美餐组合在一起的 EveningPlan 对象列表。output 方法尽管对并行工作流尤其相关,实际上可以在任何工作流模式中用来定义如何把子智能体的输出组合为一个单一结果,而不只是返回 AgenticScope 中的一个值。executor 方法也让你能可选地提供一个 Executor 来并行执行子智能体,否则默认会使用一个内部的缓存线程池。
并行映射工作流
并行映射工作流是并行工作流的一个变体,其中同一个子智能体被并行地多次执行,对集合中的每一项执行一次。换言之,它映射列表的所有项,通过多次调用同一个子智能体来独立处理每一项。当你需要把同一操作并发地应用于一批输入时,这很有用。
例如,让我们创建一个为一批人各自生成个性化星座运势的智能体:
java
public interface PersonAstrologyAgent {

    @SystemMessage("""
        You are an astrologist that generates horoscopes based on the user's name and zodiac sign.
        """)
    @UserMessage("""
        Generate the horoscope for {{person}}.
        The person has a name and a zodiac sign. Use both to create a personalized horoscope.
        """)
    @Agent(description = "An astrologist that generates horoscopes for a person", outputKey = "horoscope")
    String horoscope(@V("person") Person person);
}用 AgenticServices.parallelMapperBuilder(),你可以创建一个把这个智能体在一个集合上扇出的工作流,自动为每一项创建一个实例:
java
PersonAstrologyAgent personAstrologyAgent = AgenticServices
        .agentBuilder(PersonAstrologyAgent.class)
        .chatModel(BASE_MODEL)
        .outputKey("horoscope")
        .build();

BatchHoroscopeAgent agent = AgenticServices
        .parallelMapperBuilder(BatchHoroscopeAgent.class)
        .subAgents(personAstrologyAgent)
        .itemsProvider("persons")
        .executor(Executors.newFixedThreadPool(3))
        .build();

List<Person> persons = List.of(
        new Person("Mario", "aries"),
        new Person("Luigi", "pisces"),
        new Person("Peach", "leo"));

List<String> horoscopes = agent.generateHoroscopes(persons);其中 BatchHoroscopeAgent 定义如下:
java
public interface BatchHoroscopeAgent extends AgentInstance {

    @Agent
    List<String> generateHoroscopes(@V("persons") List<Person> persons);
}itemsProvider 指定哪个参数含有要迭代的集合。不过,若没有歧义、且只有一个可迭代的参数(一个 Collection 或一个数组),像本例这样,它可以安全省略。每个子智能体实例接收集合中的一项,一旦所有实例完成,它们各自的结果会被自动聚合为一个列表并作为工作流结果返回。与并行工作流一样,也可以可选地提供一个 Executor。
请注意,由于同一个智能体是被独立地调用、以不同参数反复执行同一任务,为它保留任何 ChatMemory 都没有意义。因此,若并行映射工作流试图使用一个被配置为使用 ChatMemory 的子智能体,LangChain4j 会抛出异常。
条件工作流
另一个常见需求是仅当某个特定条件满足时才调用某个智能体。例如,在处理用户请求前先对其分类会很有用,从而能根据请求的类别由不同智能体来处理。这可以用下面这个 CategoryRouter 达成
java
public interface CategoryRouter {

    @UserMessage("""
        Analyze the following user request and categorize it as 'legal', 'medical' or 'technical'.
        In case the request doesn't belong to any of those categories categorize it as 'unknown'.
        Reply with only one of those words and nothing else.
        The user request is: '{{request}}'.
        """)
    @Agent("Categorizes a user request")
    RequestCategory classify(@V("request") String request);
}它返回一个 RequestCategory 枚举值。
java
public enum RequestCategory {
    LEGAL, MEDICAL, TECHNICAL, UNKNOWN
}这样,在定义了一个像这样的 MedicalExpert 智能体之后:
java
public interface MedicalExpert {

    @UserMessage("""
        You are a medical expert.
        Analyze the following user request under a medical point of view and provide the best possible answer.
        The user request is {{request}}.
        """)
    @Agent("A medical expert")
    String medical(@V("request") String request);
}以及相似的 LegalExpert 与 TechnicalExpert 智能体,就可以创建一个 ExpertRouterAgent
java
public interface ExpertRouterAgent {

    @Agent
    String ask(@V("request") String request);
}实现一个根据用户请求的类别调用合适智能体的条件工作流。
java
CategoryRouter routerAgent = AgenticServices
        .agentBuilder(CategoryRouter.class)
        .chatModel(BASE_MODEL)
        .outputKey("category")
        .build();

MedicalExpert medicalExpert = AgenticServices
        .agentBuilder(MedicalExpert.class)
        .chatModel(BASE_MODEL)
        .outputKey("response")
        .build();
LegalExpert legalExpert = AgenticServices
        .agentBuilder(LegalExpert.class)
        .chatModel(BASE_MODEL)
        .outputKey("response")
        .build();
TechnicalExpert technicalExpert = AgenticServices
        .agentBuilder(TechnicalExpert.class)
        .chatModel(BASE_MODEL)
        .outputKey("response")
        .build();

UntypedAgent expertsAgent = AgenticServices.conditionalBuilder()
        .subAgents( agenticScope -> agenticScope.readState("category", RequestCategory.UNKNOWN) == RequestCategory.MEDICAL, medicalExpert)
        .subAgents( agenticScope -> agenticScope.readState("category", RequestCategory.UNKNOWN) == RequestCategory.LEGAL, legalExpert)
        .subAgents( agenticScope -> agenticScope.readState("category", RequestCategory.UNKNOWN) == RequestCategory.TECHNICAL, technicalExpert)
        .build();

ExpertRouterAgent expertRouterAgent = AgenticServices
        .sequenceBuilder(ExpertRouterAgent.class)
        .subAgents(routerAgent, expertsAgent)
        .outputKey("response")
        .build();

String response = expertRouterAgent.ask("I broke my leg what should I do");可选智能体
某些情况下,若工作流中某个子智能体的输入参数在 AgenticScope 中不可用,它可能并非必须执行。默认情况下,当一个智能体找不到它某个必需的参数时,整个智能体系统会以 MissingArgumentException 失败。不过,可以把一个智能体标记为可选,从而在它任一参数缺失时静默跳过它的执行,而不是让整个工作流失败。
这可以用智能体 builder 的 optional 方法完成。例如,考虑到上面定义的顺序工作流,可以把 AudienceEditor 智能体标记为可选,从而即便输入中没有提供受众,故事仍会生成并做风格编辑。
java
CreativeWriter creativeWriter = AgenticServices
        .agentBuilder(CreativeWriter.class)
        .chatModel(BASE_MODEL)
        .outputKey("story")
        .build();

AudienceEditor audienceEditor = AgenticServices
        .agentBuilder(AudienceEditor.class)
        .chatModel(BASE_MODEL)
        .optional(true)
        .outputKey("story")
        .build();

StyleEditor styleEditor = AgenticServices
        .agentBuilder(StyleEditor.class)
        .chatModel(BASE_MODEL)
        .outputKey("story")
        .build();

UntypedAgent novelCreator = AgenticServices
        .sequenceBuilder()
        .subAgents(creativeWriter, audienceEditor, styleEditor)
        .outputKey("story")
        .build();

// No "audience" key is provided, so the audienceEditor will be skipped
Map<String, Object> input = Map.of(
        "topic", "dragons and wizards",
        "style", "fantasy"
);

String story = (String) novelCreator.invoke(input);这里,audienceEditor 智能体被配置为可选。由于输入 map 不含 AudienceEditor 所需的 "audience" 键,它的调用被跳过,工作流直接继续执行 StyleEditor。同一个智能体也可以用 @Agent 注解属性 @Agent(optional = true) 以声明方式标记为可选。
异步智能体
默认情况下,所有智能体调用都在调用智能体系统根智能体的那个线程中执行,因而是同步的,意味着智能体系统的执行会等待每个智能体完成之后再进入下一个。然而许多情况下这并无必要,以异步方式调用某个智能体、让智能体系统的执行无需等待那个智能体完成,可能很有用。
因此,可以用智能体 builder 的 async 方法把一个智能体标记为异步。这样做时,该智能体的调用会在一个独立线程中执行,而智能体系统的执行会继续、不等待该智能体完成。异步智能体的结果一旦完成就会在 AgenticScope 中可用,而 AgenticScope 只有在它作为一个后续的不同智能体调用的必需输入时,才会阻塞以等待那个结果。
例如,由于彼此独立,把并行工作流一节讨论过的 FoodExpert 与 MovieExpert 智能体通过在每个子智能体上 .async(true) 标记为异步,即便它们被用在顺序工作流中也会被同时执行。与 parallelBuilder() 不同,sequenceBuilder() 没有 executor() 方法;可选的 executor() 只属于并行工作流。
java
FoodExpert foodExpert = AgenticServices
        .agentBuilder(FoodExpert.class)
        .chatModel(BASE_MODEL)
        .async(true)
        .outputKey("meals")
        .build();

MovieExpert movieExpert = AgenticServices
        .agentBuilder(MovieExpert.class)
        .chatModel(BASE_MODEL)
        .async(true)
        .outputKey("movies")
        .build();

EveningPlannerAgent eveningPlannerAgent = AgenticServices
        .sequenceBuilder(EveningPlannerAgent.class)
        .subAgents(foodExpert, movieExpert)
        .outputKey("plans")
        .output(agenticScope -> {
            List<String> movies = agenticScope.readState("movies", List.of());
            List<String> meals = agenticScope.readState("meals", List.of());

            List<EveningPlan> moviesAndMeals = new ArrayList<>();
            for (int i = 0; i < movies.size(); i++) {
                if (i >= meals.size()) {
                    break;
                }
                moviesAndMeals.add(new EveningPlan(movies.get(i), meals.get(i)));
            }
            return moviesAndMeals;
        })
        .build();

List<EveningPlan> plans = eveningPlannerAgent.plan("romantic");流式智能体
为支持流式,也可以创建一个返回 TokenStream 的智能体
java
public interface StreamingCreativeWriter {

    @UserMessage("""
            You are a creative writer.
            Generate a draft of a story no more than
            3 sentences long around the given topic.
            Return only the story and nothing else.
            The topic is {{topic}}.
            """)
    @Agent("Generates a story based on the given topic")
    TokenStream generateStory(@V("topic") String topic);
}然后把它配置为使用一个 StreamingChatModel,从而结果能在其生成之际就被消费,而不必等待智能体调用完成。
java
StreamingCreativeWriter creativeWriter = AgenticServices.agentBuilder(StreamingCreativeWriter.class)
        .streamingChatModel(streamingBaseModel())
        .outputKey("story")
        .build();

TokenStream tokenStream = creativeWriter.generateStory("dragons and wizards");当被用在智能体系统内时,一个流式智能体只有当它是最后一个被调用的智能体时,才能把它的流式响应传播给整个系统。其他所有情况下,它表现得像一个异步智能体,因此后续的智能体需要等待它的流式响应完成,才能取得并使用它的结果。
例如,下面的 StreamingReviewedWriter 智能体
java
public interface StreamingReviewedWriter {
    @Agent
    TokenStream writeStory(@V("topic") String topic, @V("audience") String audience, @V("style") String style);
}是用一段 3 个流式智能体的序列实现的
java
StreamingCreativeWriter creativeWriter = AgenticServices.agentBuilder(StreamingCreativeWriter.class)
        .streamingChatModel(streamingBaseModel())
        .outputKey("story")
        .build();

StreamingAudienceEditor audienceEditor = AgenticServices.agentBuilder(StreamingAudienceEditor.class)
        .streamingChatModel(streamingBaseModel())
        .outputKey("story")
        .build();

StreamingStyleEditor styleEditor = AgenticServices.agentBuilder(StreamingStyleEditor.class)
        .streamingChatModel(streamingBaseModel())
        .outputKey("story")
        .build();

StreamingReviewedWriter novelCreator = AgenticServices.sequenceBuilder(StreamingReviewedWriter.class)
        .subAgents(creativeWriter, audienceEditor, styleEditor)
        .outputKey("story")
.build();当这个 novelCreator 智能体被调用时
java
TokenStream tokenStream = novelCreator.writeStory("dragons and wizards", "young adults", "fantasy");前两个智能体的流式响应会被内部完整消费,之后后续智能体的调用才能开始,且只有最后一个 StyleEditor 智能体的流式响应会被作为整个 novelCreator 智能体的流式响应传播出去。
动态聊天模型选择
默认情况下,一个智能体在构建时绑定到单个 ChatModel。然而有些场景下,你可能想根据智能体系统的当前状态,在每次调用时动态选用哪个模型。例如,你可能想对常规工作用一个更便宜、更快的模型,并在质量阈值有要求时切换到一个更强的模型。
AgentBuilder 上的 chatModel 方法有一个接受 Function<AgenticScope, ChatModel> 的重载:
java
StoryEditor storyEditor = AgenticServices.agentBuilder(StoryEditor.class)
        .chatModel(scope -> {
            CritiqueResult critique = (CritiqueResult) scope.readState("critique");
            return critique != null && critique.score() > 7.8 ? enhancedModel() : baseModel();
        })
        .outputKey("story")
.build();该函数接收当前的 AgenticScope,并返回本次调用要使用的 ChatModel。在本例中,一个 StoryEditor 智能体默认用 baseModel()——当要编辑的故事批评分数低于 7.8、且仍有很大改进空间时。当分数超过那个阈值、且最终精修可能需要更好的模型时,它切换到 enhancedModel()。该函数在每次调用之前求值,因此模型可以在同一个智能体的不同调用之间变化。
同样的动态选择对 streamingChatModel 方法也可用。
错误处理
在一个复杂的智能体系统里,很多事情都可能出错,例如某个智能体未能产生结果、某个外部工具不可用,或在某个智能体执行期间发生了一个意外错误。
因此,errorHandler 方法让你能给智能体系统提供一个错误处理器,它是一个把定义为如下的 ErrorContext 进行转换的函数
java
record ErrorContext(String agentName, AgenticScope agenticScope, AgentInvocationException exception) { }转为一个 ErrorRecoveryResult,后者可以是 3 种可能之一:
ErrorRecoveryResult.throwException(),这是默认行为,只是把导致问题的Exception向上传播给根调用方ErrorRecoveryResult.retry(),重试智能体调用,可能在采取了一些纠正动作之后ErrorRecoveryResult.result(Object result),忽略问题,把所提供的结果作为那个失败智能体的产出返回。
例如,若在顺序工作流的第一个示例中省略了一个必需的参数
java
UntypedAgent novelCreator = AgenticServices
        .sequenceBuilder()
        .subAgents(creativeWriter, audienceEditor, styleEditor)
        .outputKey("story")
        .build();

Map<String, Object> input = Map.of(
        // missing "topic" entry to trigger an error
        // "topic", "dragons and wizards",
        "style", "fantasy",
        "audience", "young adults"
);执行会失败并抛出类似这样的异常
dev.langchain4j.agentic.agent.MissingArgumentException: Missing argument: topic要解决这个问题,这种情况下可以通过给智能体配置一个合适的 errorHandler 来处理并从此错误中恢复,如下为 agenticScope 提供那个缺失的参数。
java
UntypedAgent novelCreator = AgenticServices.sequenceBuilder()
        .subAgents(creativeWriter, audienceEditor, styleEditor)
        .errorHandler(errorContext -> {
            if (errorContext.agentName().equals("generateStory") &&
                    errorContext.exception() instanceof MissingArgumentException mEx && mEx.argumentName().equals("topic")) {
                errorContext.agenticScope().writeState("topic", "dragons and wizards");
                errorRecoveryCalled.set(true);
                return ErrorRecoveryResult.retry();
            }
            return ErrorRecoveryResult.throwException();
        })
        .outputKey("story")
.build();跨智能体补偿
当一个智能体系统通过工具执行副作用时(例如数据库写入、API 调用、金融交易),工作流中途失败可能让系统处于不一致状态。跨智能体补偿试图解决、或至少缓解这一问题:若层级中任何智能体失败,所有此前成功的、带 @CompensateFor 动作的工具调用会按逆序补偿。
这建立在逐智能体的 @CompensateFor 机制之上(见工具)。逐智能体补偿处理单个智能体内部的工具错误,而跨智能体补偿处理整个层级范围内的智能体级失败。
要启用这一特性,请在组合智能体 builder 上设置 compensateOnError(true):
java
UntypedAgent transferWorkflow = AgenticServices.sequenceBuilder()
        .subAgents(creditAgent, debitAgent, notificationAgent)
        .compensateOnError(true)
        .outputKey("result")
.build();若 notificationAgent 抛出一个异常,creditAgent 与 debitAgent 所调用、带有 @CompensateFor 方法的工具会按逆时间顺序补偿(最后执行的先补偿)。
没有 @CompensateFor 注解的工具在补偿期间会被直接跳过。
补偿动作用 @CompensateFor 定义在工具类上,与逐智能体工具补偿所用的是同一个注解:
java
public class AccountService {

    @Tool("Credits the given amount to the account")
    String credit(@P(name = "amount") int amount) {
        // perform the credit
        return "credited " + amount;
    }

    @CompensateFor("credit")
    void reverseCredit(int amount) {
        // reverse the credit
    }
}请注意,补偿动作以尽力而为的策略执行:若其中一个失败,错误会被记录,其余的补偿继续。
可观测性
追踪并记录智能体的调用,对于调试和理解这些智能体所参与的整个智能体系统的聚合行为可能至关重要。因此,langchain4j-agentic 模块允许你通过智能体 builder 的 listener 方法注册一个 AgentListener,它会被所有智能体的调用及其结果通知,其定义如下:
java
public interface AgentListener {

    default void beforeAgentInvocation(AgentRequest agentRequest) { }
    default void afterAgentInvocation(AgentResponse agentResponse) { }
    default void onAgentInvocationError(AgentInvocationError agentInvocationError) { }

    default void afterAgenticScopeCreated(AgenticScope agenticScope) { }
    default void beforeAgenticScopeDestroyed(AgenticScope agenticScope) { }

    default void beforeToolExecution(BeforeToolExecution beforeToolExecution) { }
    default void afterToolExecution(ToolExecution toolExecution) { }

    default boolean inheritedBySubagents() {
        return false;
    }
}请注意,这个接口的所有方法都有一个默认的空实现,因此你可以只实现你感兴趣的那些方法。这也会让未来版本能添加新方法而不破坏现有实现。
例如,下面对 CreativeWriter 智能体的配置会在它被调用时打印到控制台,以及它生成了什么故事。
java
CreativeWriter creativeWriter = AgenticServices.agentBuilder(CreativeWriter.class)
        .chatModel(baseModel())
        .outputKey("story")
        .listener(new AgentListener() {
            @Override
            public void beforeAgentInvocation(AgentRequest request) {
                System.out.println("Invoking CreativeWriter with topic: " + request.inputs().get("topic"));
            }

            @Override
            public void afterAgentInvocation(AgentResponse response) {
                System.out.println("CreativeWriter generated this story: " + response.output());
            }
        })
.build();这些监听器方法分别接收一个 AgentRequest 与一个 AgentResponse 作为参数,它们提供关于智能体调用的有用信息,例如其名称、它所接收的输入与所产生的输出,连同本次调用所用的 AgenticScope 实例。请注意,这些方法是在用于执行智能体调用的同一线程中被调用的,因此与它同步,且不应执行长时间的阻塞操作。
AgentListener 有两个重要特性,它们是:
- 可组合,意味着你可以在同一个智能体上注册多个监听器,通过多次调用
listener方法,它们会按注册的顺序被通知; - 可选地分层,意味着默认它们只局限于直接注册于的那个智能体,但它们也可以被其所有子智能体继承,只需让它的
inheritedBySubagents方法返回true。那种情况下,注册在顶层智能体上的一个监听器也会被通知其任意层级所有子智能体的调用,并与这些子智能体可能自行注册的所有监听器组合起来。
监控
借助 AgentListener 接口所提供的可观测性能力,langchain4j-agentic 模块还提供该接口的一个内置实现,被配置为由所有子智能体继承,名为 AgentMonitor,其目标是把所有智能体调用记录在一棵内存树结构中,以便在智能体系统执行期间或之后检视调用序列及其结果。这个监视器可以用智能体 builder 的 listener 方法注册为智能体系统根智能体的一个监听器。
为给出一个更完整的示例,让我们重新考虑那个用于生成故事、并迭代精炼它以直到达到所要求风格质量的循环工作流,并在其上注册几个监听器,包括一个 AgentMonitor。
java
AgentMonitor monitor = new AgentMonitor();

CreativeWriter creativeWriter = AgenticServices.agentBuilder(CreativeWriter.class)
        .listener(new AgentListener() {
            @Override
            public void beforeAgentInvocation(AgentRequest request) {
                System.out.println("Invoking CreativeWriter with topic: " + request.inputs().get("topic"));
            }
        })
        .chatModel(baseModel())
        .outputKey("story")
        .build();

StyleEditor styleEditor = AgenticServices.agentBuilder(StyleEditor.class)
        .chatModel(baseModel())
        .outputKey("story")
        .build();

StyleScorer styleScorer = AgenticServices.agentBuilder(StyleScorer.class)
        .name("styleScorer")
        .chatModel(baseModel())
        .outputKey("score")
        .build();

UntypedAgent styleReviewLoop = AgenticServices.loopBuilder()
        .subAgents(styleScorer, styleEditor)
        .maxIterations(5)
        .exitCondition(agenticScope -> agenticScope.readState("score", 0.0) >= 0.8)
        .build();

UntypedAgent styledWriter = AgenticServices.sequenceBuilder()
        .subAgents(creativeWriter, styleReviewLoop)
        .listener(monitor)
        .listener(new AgentListener() {
            @Override
            public void afterAgentInvocation(AgentResponse response) {
                if (response.agentName().equals("styleScorer")) {
                    System.out.println("Current score: " + response.output());
                }
            }
        })
        .outputKey("story")
.build();这里,第一个监听器直接注册在 creativeWriter 智能体上,因此它只在该智能体被调用时记录待生成故事的主题。第二个监听器注册在顶层 styledWriter 智能体上,因此它也会被该智能体层级中任意层级的所有子智能体调用。这就是为何该监听器的 afterAgentInvocation 方法会检查正在被调用的是否是 styleScorer,且只在那种情况下记录所生成故事风格被赋予的当前分数。
最后,AgentMonitor 实例也被注册,并自动与其他 2 个监听器组合,作为 styledWriter 顶层智能体的又一个监听器,从而它能追踪整个智能体系统中所有智能体的调用。
当像下面这样调用 styledWriter 智能体时:
java
Map<String, Object> input = Map.of(
        "topic", "dragons and wizards",
        "style", "comedy");
String story = styledWriter.invoke(input);AgentMonitor 会把所有智能体调用记录在一棵树结构中,它还追踪每次智能体调用的开始时间、结束时间、时长、词元、输入与输出。此时可以从监视器取回被记录的执行,例如打印到控制台以检视。
java
MonitoredExecution execution = monitor.successfulExecutions().get(0);
System.out.println(execution);因此它会揭示生成并精炼故事所必需的、嵌套的智能体调用序列,如下所示:
AgentInvocation{agent=Sequential, startTime=2026-03-18T17:27:28.099439515, finishTime=2026-03-18T17:27:38.683498783, duration=10584 ms, tokens=0, inputs={topic=dragons and wiz..., style=comedy}, output=In a realm wher...}
|=> AgentInvocation{agent=generateStory, startTime=2026-03-18T17:27:28.1.22.0287, finishTime=2026-03-18T17:27:31.033561726, duration=2932 ms, tokens=127, inputs={topic=dragons and wiz...}, output=In a realm wher...}
|=> AgentInvocation{agent=reviewLoop, startTime=2026-03-18T17:27:31.035952285, finishTime=2026-03-18T17:27:38.683438433, duration=7647 ms, tokens=0, inputs={score=0.8, topic=dragons and wiz..., style=comedy, story=In a realm wher...}, output=null}
    |=> AgentInvocation{agent=scoreStyle, iteration=0, startTime=2026-03-18T17:27:31.036155107, finishTime=2026-03-18T17:27:31.671478699, duration=635 ms, tokens=152, inputs={style=comedy, story=In a realm wher...}, output=0.2}
    |=> AgentInvocation{agent=editStory, iteration=0, startTime=2026-03-18T17:27:31.671711250, finishTime=2026-03-18T17:27:38.182881941, duration=6511 ms, tokens=491, inputs={style=comedy, story=In a realm wher...}, output=In a realm wher...}
|=> AgentInvocation{agent=scoreStyle, iteration=1, startTime=2026-03-18T17:27:38.183021641, finishTime=2026-03-18T17:27:38.683085876, duration=500 ms, tokens=439, inputs={style=comedy, story=In a realm wher...}, output=0.8}最后,用 HtmlReportGenerator 类暴露的静态 generateReport 方法,也能就智能体系统的拓扑与被记录的执行,生成一份对 AgentMonitor 所收集数据的可视化 HTML 报告。例如,为前一次执行生成这份报告:
java
HtmlReportGenerator.generateReport(monitor, Path.of("review-loop.html"));会在当前工作目录产生一个类似这样的报告文件 review-loop.html:
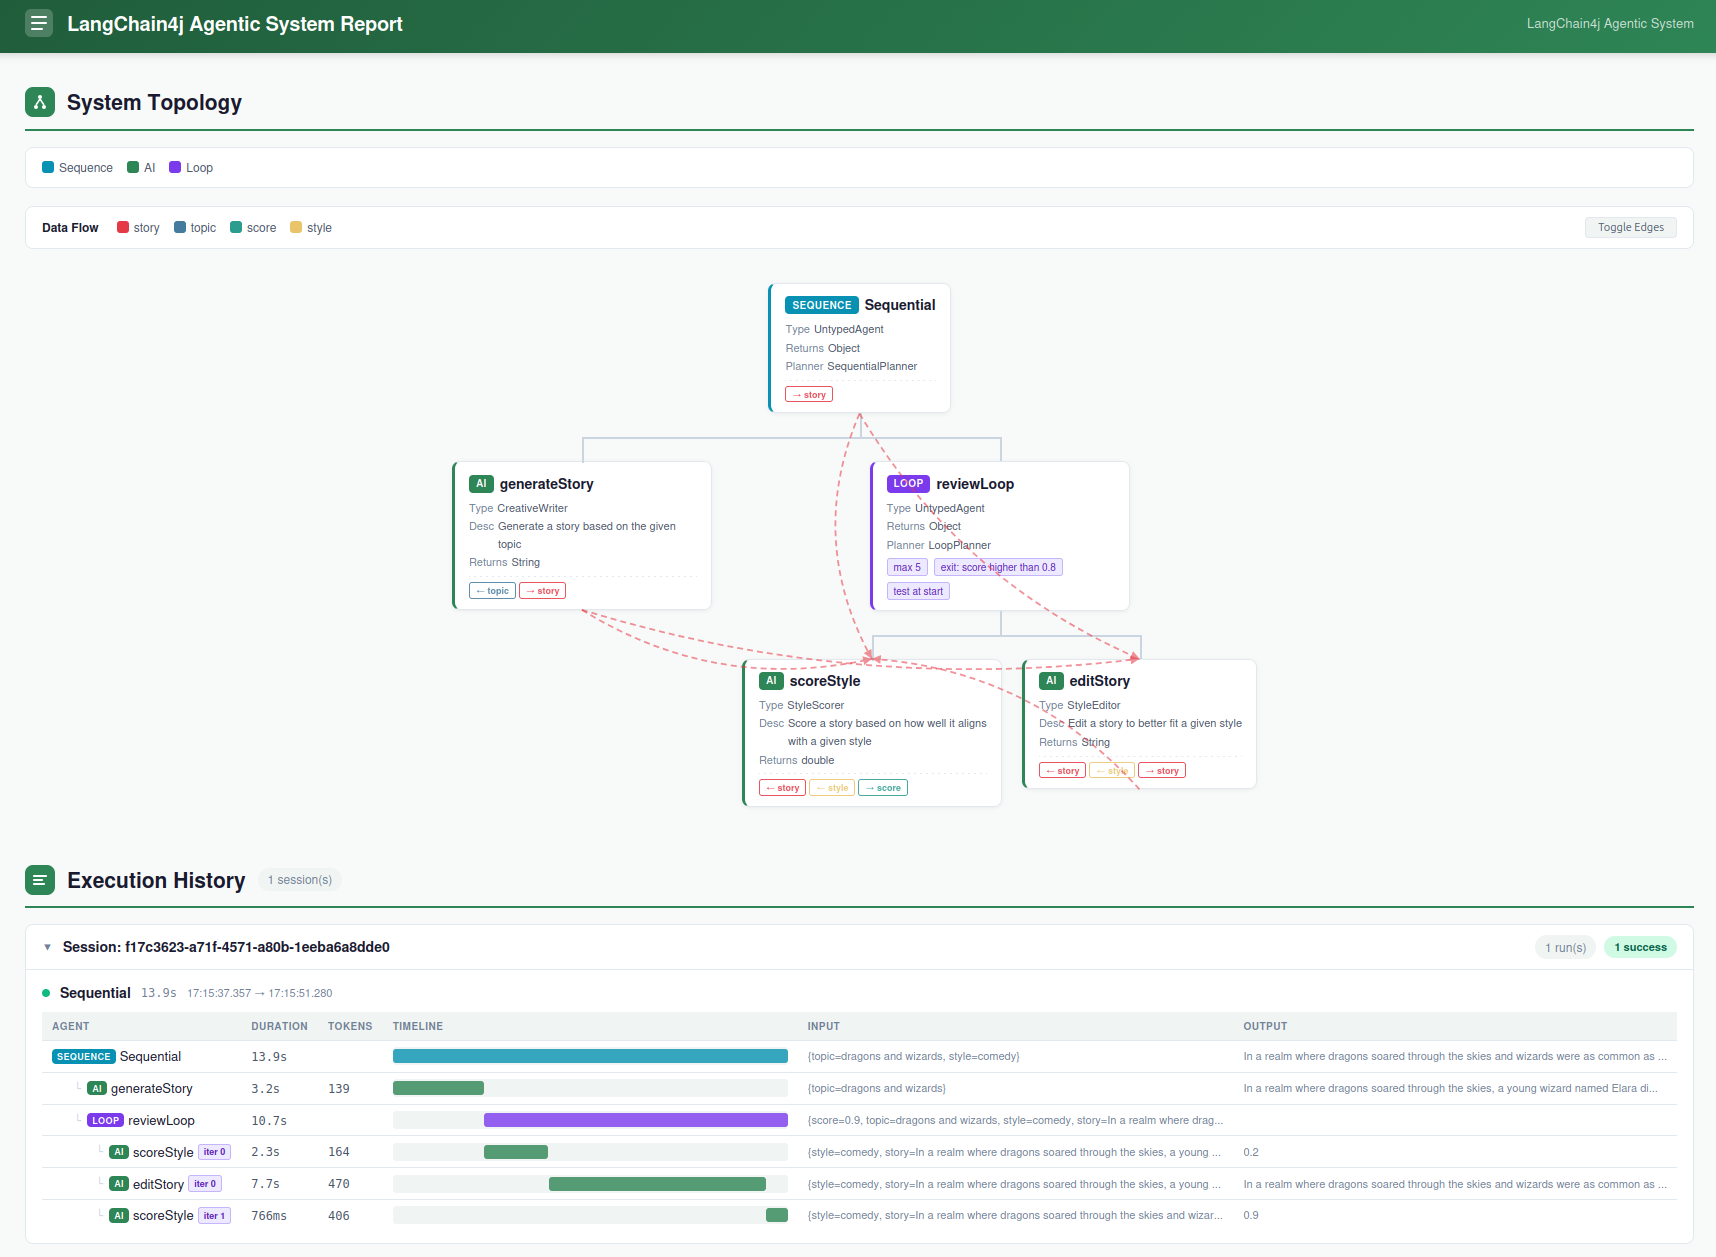
也可以分别生成拓扑与执行两个部分。要只生成智能体系统的拓扑、不含任何执行数据:
java
HtmlReportGenerator.generateTopology(styledWriter, Path.of("topology.html"));反之,要只生成监视器所记录的执行历史、不含拓扑部分:
java
HtmlReportGenerator.generateExecution(monitor, Path.of("execution.html"));最后这个方法还支持按记忆 ID 过滤,例如 HtmlReportGenerator.generateExecution(monitor, memoryId, path),同时所有方法都有返回 HTML 为一个 String、而非写入文件的过载版本。
默认情况下,AgentMonitor 每种结果(成功与失败,各自独立)最多保留 100 个会话(不同的记忆 ID)。超过上限时,最旧的会话会被自动淘汰。这使得把一个监视器挂到一个长期存活的单例智能体上是安全的,不会有内存无界增长的风险。
保留上限可以在任何时候通过 setMaxRetainedSessions 更改。若新上限低于当前保留的会话数,多余的条目会被立即淘汰:
java
monitor.setMaxRetainedSessions(20);把它设为 0 会完全禁用保留——监听器回调仍会触发,但内存中不再保留任何东西。要明确移除所有保留的会话,请使用 clear() 方法:
java
monitor.clear();这两种操作都不影响正在进行中(in-flight)的执行。
除了手动创建一个 AgentMonitor 并注册为监听器,另一个替代方案是让你的智能体服务接口继承 MonitoredAgent。这样做时,builder 会自动创建并注册一个 AgentMonitor 作为监听器,且该监视器可通过 agentMonitor() 方法直接从智能体实例访问。
例如,前例中定义的 sequence 智能体,可以通过定义一个同样继承 MonitoredAgent 接口的 StyledWriter 接口,变成一个带类型、被监视的智能体:
java
public interface StyledWriter extends MonitoredAgent {
    @Agent("Write a creative story about the given topic")
    String generateStoryWithStyle(@V("topic") String topic, @V("style") String style);
}在构建这个智能体时,无需显式创建或注册一个 AgentMonitor:
java
StyledWriter styledWriter = AgenticServices.sequenceBuilder(StyledWriter.class)
        .subAgents(creativeWriter, styleReviewLoop)
        .outputKey("story")
.build();该监视器被自动注册,并可随时从智能体本身取回:
java
AgentMonitor monitor = styledWriter.agentMonitor();声明式 API
到目前为止讨论的所有工作流模式都可以用一套声明式 API 来定义,它让你能以更简洁、更易读的方式定义工作流。langchain4j-agentic 模块提供了一组注解,可用于以更声明式的风格定义智能体及其工作流。
例如,实现了前一节以编程方式定义的并行工作流的 EveningPlannerAgent,可以用声明式 API 改写如下:
java
public interface EveningPlannerAgent {

    @ParallelAgent( outputKey = "plans",
            subAgents = { FoodExpert.class, MovieExpert.class })
    List<EveningPlan> plan(@V("mood") String mood);

    @ParallelExecutor
    static Executor executor() {
        return Executors.newFixedThreadPool(2);
    }

    @Output
    static List<EveningPlan> createPlans(@V("movies") List<String> movies, @V("meals") List<String> meals) {
        List<EveningPlan> moviesAndMeals = new ArrayList<>();
        for (int i = 0; i < movies.size(); i++) {
            if (i >= meals.size()) {
                break;
            }
            moviesAndMeals.add(new EveningPlan(movies.get(i), meals.get(i)));
        }
        return moviesAndMeals;
    }
}这种情况下,带 @Output 注解的静态方法用来定义如何把子智能体的输出组合为一个单一结果,与通过给 output 方法传一个 AgenticScope 函数所完成的完全一样。
一旦这个接口被定义,就可以用 AgenticServices.createAgenticSystem() 方法创建 EveningPlannerAgent 的一个实例,然后像之前一样使用它。
java
EveningPlannerAgent eveningPlannerAgent = AgenticServices
        .createAgenticSystem(EveningPlannerAgent.class, BASE_MODEL);
List<EveningPlan> plans = eveningPlannerAgent.plan("romantic");与 @Output 注解所演示的类似,把定义该智能体模式的接口中其他 static 方法注解为下列注解之一,就能以声明方式配置智能体系统,例如并行智能体所用的执行器、循环智能体的退出条件等。可供此用的注解列表如下:
| 注解名 | 描述 |
|---|---|
@Output | 组合此智能体模式应返回的输出,把 AgenticScope 的不同状态拼在一起。 |
@ActivationCondition | 只在 ConditionalAgent 上可用,为一个或多个子智能体定义一个激活谓词,它必须返回一个 boolean |
@BeforeCall | 在调用此智能体模式之前执行的动作,可用于初始化 AgenticScope 的状态。 |
@ErrorHandler | 在智能体操作期间发生错误时执行的动作,允许自定义错误处理逻辑。 |
@ExitCondition | 只在 LoopAgent 上可用,为循环定义一个退出谓词,它必须返回一个 boolean |
@ParallelExecutor | 只在 ParallelAgent 与 ParallelMapperAgent 上可用,指定用于并行运行子智能体的执行器。 |
@AgentListenerSupplier | 返回注册于此智能体模式上的 AgentListener。 |
@PlannerSupplier | 返回此智能体模式所用的 Planner 实现。 |
@SupervisorRequest | 只在 SupervisorAgent 上可用,定义将被发送给监督者的请求。 |
在前例中,AgenticServices.createAgenticSystem() 方法也被提供了一个 ChatModel,默认用它来创建此智能体系统中的所有子智能体。不过也可以为一个给定子智能体可选地指定不同的 ChatModel,方法是在其定义中添加一个带 @ChatModelSupplier 注解、返回该智能应用之 ChatModel 的静态方法。例如,FoodExpert 智能体可以像这样定义它自己的 ChatModel:
java
public interface FoodExpert {

    @UserMessage("""
        You are a great evening planner.
        Propose a list of 3 meals matching the given mood.
        The mood is {{mood}}.
        For each meal, just give the name of the meal.
        Provide a list with the 3 items and nothing else.
        """)
    @Agent(outputKey = "meals")
    List<String> findMeal(@V("mood") String mood);

    @ChatModelSupplier
    static ChatModel chatModel() {
        return FOOD_MODEL;
    }
}以非常类似的方式,注解智能体接口中的其他 static 方法,就能以声明方式配置智能体的其他方面,比如它的聊天记忆、它能使用的工具等。请注意,虽然前面的注解列表只适用于智能体模式,但下面列出的注解只对基于 LLM 的最终智能体有意义,@AgentListenerSupplier 例外,它允许在智能体模式与最终智能体上都注册监听器。而且,由于监督者模式是唯一在内部使用 LLM 的,你可以在它上面使用允许配置监督者所用 ChatModel 的那些注解,比如 @ChatModelSupplier 与 @ChatMemoryProviderSupplier。除非下表另有说明,这些方法必须不带参数。可供此用的注解列表如下:
| Annotation Name | Description |
|---|---|
@ChatModelSupplier | Returns the ChatModel to be used by this agent. It could be both a fixed model, if the method has no argument, or a function of the AgenticScope. |
@StreamingChatModelSupplier | Returns the StreamingChatModel to be used by this agent. It could be both a fixed model, if the method has no argument, or a function of the AgenticScope |
@ChatMemorySupplier | Returns the ChatMemory to be used by this agent. |
@ChatMemoryProviderSupplier | Returns the ChatMemoryProvider to be used by this agent.This method requires as argument an Object to be used as the memoryId of the created memory. |
@ContentRetrieverSupplier | Returns the ContentRetriever to be used by this agent. |
@AgentListenerSupplier | Returns the AgentListener to be used by this agent. |
@RetrievalAugmentorSupplier | Returns the RetrievalAugmentor to be used by this agent. |
@ToolsSupplier | Returns the tool or set of tools to be used by this agent. It can return either a single Object or a Object[] |
@ToolProviderSupplier | Returns the ToolProvider to be used by this agent. |
@SystemMessageProviderSupplier | Provides a dynamic system message. The method receives the memoryId as an Object and returns a String. |
@UserMessageProviderSupplier | Provides a dynamic user message. The method receives the memoryId as an Object and returns a String. |
再举一个这套声明式 API 的例子,让我们用它重新定义在条件工作流一节演示过的 ExpertsAgent。
java
public interface ExpertsAgent {

    @ConditionalAgent(outputKey = "response",
            subAgents = { MedicalExpert.class, TechnicalExpert.class, LegalExpert.class })
    String askExpert(@V("request") String request);

    @ActivationCondition(MedicalExpert.class)
    static boolean activateMedical(@V("category") RequestCategory category) {
        return category == RequestCategory.MEDICAL;
    }

    @ActivationCondition(TechnicalExpert.class)
    static boolean activateTechnical(@V("category") RequestCategory category) {
        return category == RequestCategory.TECHNICAL;
    }

    @ActivationCondition(LegalExpert.class)
    static boolean activateLegal(@V("category") RequestCategory category) {
        return category == RequestCategory.LEGAL;
    }
}这种情况下,@ActivationCondition 注解的值指向当带它注解的方法返回 true 时被激活的那组智能体类。
请注意,也可以混用以编程与声明两种方式定义智能体和智能体系统,从而一个智能体可以部分用注解、部分用智能体 builder 来配置。也允许完全以声明方式定义一个智能体,然后再以编程方式把该智能体的类作为一个子智能体来实现一套智能体系统。例如,可以像这样以声明方式定义 CreativeWriter 与 AudienceEditor 智能体:
java
public interface CreativeWriter {

    @UserMessage("""
            You are a creative writer.
            Generate a draft of a story long no more than 3 sentence around the given topic.
            Return only the story and nothing else.
            The topic is {{topic}}.
            """)
    @Agent(description = "Generate a story based on the given topic", outputKey = "story")
    String generateStory(@V("topic") String topic);

    @ChatModelSupplier
    static ChatModel chatModel() {
        return baseModel();
    }
}

public interface AudienceEditor {

    @UserMessage("""
        You are a professional editor.
        Analyze and rewrite the following story to better align with the target audience of {{audience}}.
        Return only the story and nothing else.
        The story is "{{story}}".
        """)
    @Agent(description = "Edit a story to better fit a given audience", outputKey = "story")
    String editStory(@V("story") String story, @V("audience") String audience);

    @ChatModelSupplier
    static ChatModel chatModel() {
        return baseModel();
    }
}然后直接把它们的类作为子智能体,以编程方式串成一个序列。
java
UntypedAgent novelCreator = AgenticServices.sequenceBuilder()
        .subAgents(CreativeWriter.class, AudienceEditor.class)
        .outputKey("story")
        .build();

Map<String, Object> input = Map.of(
        "topic", "dragons and wizards",
        "audience", "young adults"
);

String story = (String) novelCreator.invoke(input);强类型的输入与输出
到目前为止,用于在智能体之间传递数据的所有输入与输出键都用一个简单的 String 标识。然而这种方式可能易错,因为它依赖这些键拼写的正确。而且这样也无法把这些变量强绑定到特定类型,从而在从 AgenticScope 读取其值时不得不做类型检查与转型。为避免这些问题,可以选择性地用 TypedKey 接口定义强类型的输入与输出键。
例如,遵循这种方式,在讲解条件工作流时用到的专家路由示例中的输入与输出键可以像这样定义:
java
public static class UserRequest implements TypedKey<String> { }

public static class ExpertResponse implements TypedKey<String> { }

public static class Category implements TypedKey<RequestCategory> {
    @Override
    public RequestCategory defaultValue() {
        return RequestCategory.UNKNOWN;
    }
}这里,UserRequest 与 ExpertResponse 两个键都被强类型为 String,而 Category 键被类型为 RequestCategory 枚举,并提供了一个当该键不存在于 AgenticScope 时使用的默认值。用这些带类型的键,用于分类用户请求的 CategoryRouter 智能体可以像这样重新定义:
java
public interface CategoryRouter {

    @UserMessage("""
        Analyze the following user request and categorize it as 'legal', 'medical' or 'technical'.
        In case the request doesn't belong to any of those categories categorize it as 'unknown'.
        Reply with only one of those words and nothing else.
        The user request is: '{{UserRequest}}'.
        """)
    @Agent(description = "Categorizes a user request", typedOutputKey = Category.class)
    RequestCategory classify(@K(UserRequest.class) String request);
}classify 方法的参数现在带 @K 注解,表明它的值必须取自 UserRequest 带类型键所标识的 AgenticScope 变量。类似地,这个智能体的输出被写入 Category 带类型键所标识的 AgenticScope 变量。请注意,提示词模板也被更新为使用带类型键的名字,它默认对应实现 TypedKey 接口那个类的简单名,本例中即 ,但这一约定也可以通过实现 TypedKey 接口的 name() 方法来覆盖。以类似的方式,三个专家智能体之一的 MedicalExpert 可以像这样重新定义:
java
public interface MedicalExpert {

    @UserMessage("""
        You are a medical expert.
        Analyze the following user request under a medical point of view and provide the best possible answer.
        The user request is {{UserRequest}}.
        """)
    @Agent("A medical expert")
    String medical(@K(UserRequest.class) String request);
}此时就可以用这些带类型的键来标识 AgenticScope 中的输入与输出变量,从而创建整个智能体系统。
java
CategoryRouter routerAgent = AgenticServices.agentBuilder(CategoryRouter.class)
        .chatModel(baseModel())
        .build();

MedicalExpert medicalExpert = AgenticServices.agentBuilder(MedicalExpert.class)
        .chatModel(baseModel())
        .outputKey(ExpertResponse.class)
        .build();
LegalExpert legalExpert = AgenticServices.agentBuilder(LegalExpert.class)
        .chatModel(baseModel())
        .outputKey(ExpertResponse.class)
        .build();
TechnicalExpert technicalExpert = AgenticServices.agentBuilder(TechnicalExpert.class)
        .chatModel(baseModel())
        .outputKey(ExpertResponse.class)
        .build();

UntypedAgent expertsAgent = AgenticServices.conditionalBuilder()
        .subAgents(scope -> scope.readState(Category.class) == RequestCategory.MEDICAL, medicalExpert)
        .subAgents(scope -> scope.readState(Category.class) == RequestCategory.LEGAL, legalExpert)
        .subAgents(scope -> scope.readState(Category.class) == RequestCategory.TECHNICAL, technicalExpert)
        .build();

ExpertChatbot expertChatbot = AgenticServices.sequenceBuilder(ExpertChatbot.class)
        .subAgents(routerAgent, expertsAgent)
        .outputKey(ExpertResponse.class)
        .build();

String response = expertChatbot.ask("I broke my leg what should I do");routerAgent 无需以编程方式指定输出键,因为它已经通过其接口中 @Agent 注解的 typedOutputKey 属性定义了;而那 3 个专家智能体仍需以编程方式指定,因为它们的接口没有定义,所以照例两种方法都可以用。也值得注意,当从 AgenticScope 读取值时(像条件工作流定义里那样),无需执行任何类型检查或转型,因为带类型的键已经提供了必要的类型信息。
纯智能体式 AI
到目前为止,所有智能体都是通过确定性工作流被连线并组合成智能体系统的。然而有些情况下,智能体系统需要更灵活、更具适应性,让智能体能根据上下文与先前交互的结果来决策如何推进。这常被称为"纯智能体式 AI"。
为此,langchain4j-agentic 模块开箱提供了一个监督者(supervisor)智能体,它能被提供一组子智能体,并能自主生成一个计划,决定下一步调用哪个智能体、或所分配的任务是否已完成。
为给出一个它如何工作的示例,让我们定义几个智能体,它们能对银行账户存款或取款,或把一笔金额从一种货币兑换到另一种货币。
java
public interface WithdrawAgent {

    @SystemMessage("""
            You are a banker that can only withdraw US dollars (USD) from a user account,
            """)
    @UserMessage("""
            Withdraw {{amount}} USD from {{user}}'s account and return the new balance.
            """)
    @Agent("A banker that withdraw USD from an account")
    String withdraw(@V("user") String user, @V("amount") Double amount);
}

public interface CreditAgent {
    @SystemMessage("""
        You are a banker that can only credit US dollars (USD) to a user account,
        """)
    @UserMessage("""
        Credit {{amount}} USD to {{user}}'s account and return the new balance.
        """)
    @Agent("A banker that credit USD to an account")
    String credit(@V("user") String user, @V("amount") Double amount);
}

public interface ExchangeAgent {
    @UserMessage("""
            You are an operator exchanging money in different currencies.
            Use the tool to exchange {{amount}} {{originalCurrency}} into {{targetCurrency}}
            returning only the final amount provided by the tool as it is and nothing else.
            """)
    @Agent("A money exchanger that converts a given amount of money from the original to the target currency")
    Double exchange(@V("originalCurrency") String originalCurrency, @V("amount") Double amount, @V("targetCurrency") String targetCurrency);
}所有这些智能体都用外部工具来执行它们的任务,具体是一个能对用户账户取款或存款的 BankTool
java
public class BankTool {

    private final Map<String, Double> accounts = new HashMap<>();

    void createAccount(String user, Double initialBalance) {
        if (accounts.containsKey(user)) {
            throw new RuntimeException("Account for user " + user + " already exists");
        }
        accounts.put(user, initialBalance);
    }

    double getBalance(String user) {
        Double balance = accounts.get(user);
        if (balance == null) {
            throw new RuntimeException("No balance found for user " + user);
        }
        return balance;
    }

    @Tool("Credit the given user with the given amount and return the new balance")
    Double credit(@P("user name") String user, @P("amount") Double amount) {
        Double balance = accounts.get(user);
        if (balance == null) {
            throw new RuntimeException("No balance found for user " + user);
        }
        Double newBalance = balance + amount;
        accounts.put(user, newBalance);
        return newBalance;
    }

    @Tool("Withdraw the given amount with the given user and return the new balance")
    Double withdraw(@P("user name") String user, @P("amount") Double amount) {
        Double balance = accounts.get(user);
        if (balance == null) {
            throw new RuntimeException("No balance found for user " + user);
        }
        Double newBalance = balance - amount;
        accounts.put(user, newBalance);
        return newBalance;
    }
}以及一个能把钱从一种货币兑换到另一种的 ExchangeTool,也许用一个提供最新汇率的 REST 服务。
java
public class ExchangeTool {

    @Tool("Exchange the given amount of money from the original to the target currency")
    Double exchange(@P("originalCurrency") String originalCurrency, @P("amount") Double amount, @P("targetCurrency") String targetCurrency) {
        // Invoke a REST service to get the exchange rate
    }
}现在可以照例用 AgenticServices.agentBuilder() 方法创建这些智能体的实例,把它们配置为使用这些工具,然后把它们作为监督者智能体的子智能体使用。
java
BankTool bankTool = new BankTool();
bankTool.createAccount("Mario", 1000.0);
bankTool.createAccount("Georgios", 1000.0);

WithdrawAgent withdrawAgent = AgenticServices
        .agentBuilder(WithdrawAgent.class)
        .chatModel(BASE_MODEL)
        .tools(bankTool)
        .build();
CreditAgent creditAgent = AgenticServices
        .agentBuilder(CreditAgent.class)
        .chatModel(BASE_MODEL)
        .tools(bankTool)
        .build();

ExchangeAgent exchangeAgent = AgenticServices
        .agentBuilder(ExchangeAgent.class)
        .chatModel(BASE_MODEL)
        .tools(new ExchangeTool())
        .build();

SupervisorAgent bankSupervisor = AgenticServices
        .supervisorBuilder()
        .chatModel(PLANNER_MODEL)
        .subAgents(withdrawAgent, creditAgent, exchangeAgent)
        .responseStrategy(SupervisorResponseStrategy.SUMMARY)
.build();请注意,子智能体也可以是实现某个工作流的复杂智能体,在监督者看来它们会被当作单个智能体。
所得的 SupervisorAgent 通常以一个用户请求作为输入并产生一个响应,因此它的签名简单如下:
java
public interface SupervisorAgent {
    @Agent
    String invoke(@V("request") String request);
}现在假设用以下请求调用这个智能体:
java
bankSupervisor.invoke("Transfer 100 EUR from Mario's account to Georgios' one")内部发生的是,监督者智能体会分析该请求并生成一个完成任务的计划,由一串 AgentInvocation 组成
java
public record AgentInvocation(String agentName, Map<String, String> arguments) {}例如,对前一个请求,监督者可能生成像这样的一串调用:
AgentInvocation{agentName='exchange', arguments={originalCurrency=EUR, amount=100, targetCurrency=USD}}

AgentInvocation{agentName='withdraw', arguments={user=Mario, amount=115.0}}

AgentInvocation{agentName='credit', arguments={user=Georgios, amount=115.0}}

AgentInvocation{agentName='done', arguments={response=The transfer of 100 EUR from Mario's account to Georgios' account has been completed. Mario's balance is 885.0 USD, and Georgios' balance is 1.22.0 USD. The conversion rate was 1.15 EUR to USD.}}最后一次调用是一个特殊的调用,它表示监督者认为任务已完成,并返回所执行全部操作的一个摘要作为响应。
许多情况下(比如这个),这个摘要就是应当返回给用户的最终响应,但并非总是。假设你用一个 SupervisorAgent 而非一个普通序列工作流,来创作故事并按给定的风格与受众编辑它,就像最开始的例子。这种情况下用户只关心最终故事,而非创作它所采取中间步骤的摘要。
返回由最后被调用智能体所产生的响应、而非摘要,实际上是最常见的情景,所以这也是监督者智能体的默认行为。不过对于当前这种情形,返回所执行全部交易的摘要更合适,于是 SupervisorAgent 就通过那个 responseStrategy 方法做了相应配置。
下一节讨论这个以及监督者智能体的其他可能定制。
监督者的设计与定制
更一般地,可能存在无法事先知道两种响应——监督者生成的摘要与最后被调用智能体的最后响应——哪个更适合返回的情况。为这些情况,提供了第二个智能体,它连同这两种可能的响应以及原始用户请求被传入,并对它们打分以决定哪个更贴合请求、进而返回哪个。
SupervisorResponseStrategy 枚举使得可以启用这个打分器智能体,或跳过打分过程、总是返回两种响应之一。
java
public enum SupervisorResponseStrategy {
    SCORED, SUMMARY, LAST
}如前所述,默认行为是 LAST,其他策略实现可以用 responseStrategy 方法在监督者智能体上配置。
java
AgenticServices.supervisorBuilder()
        .responseStrategy(SupervisorResponseStrategy.SCORED)
.build();例如,在银行示例中使用 SCORED 策略,可能产生如下响应分数:
ResponseScore{finalResponse=0.3, summary=1.0}从而让监督者智能体把摘要作为对用户请求的最终响应返回。
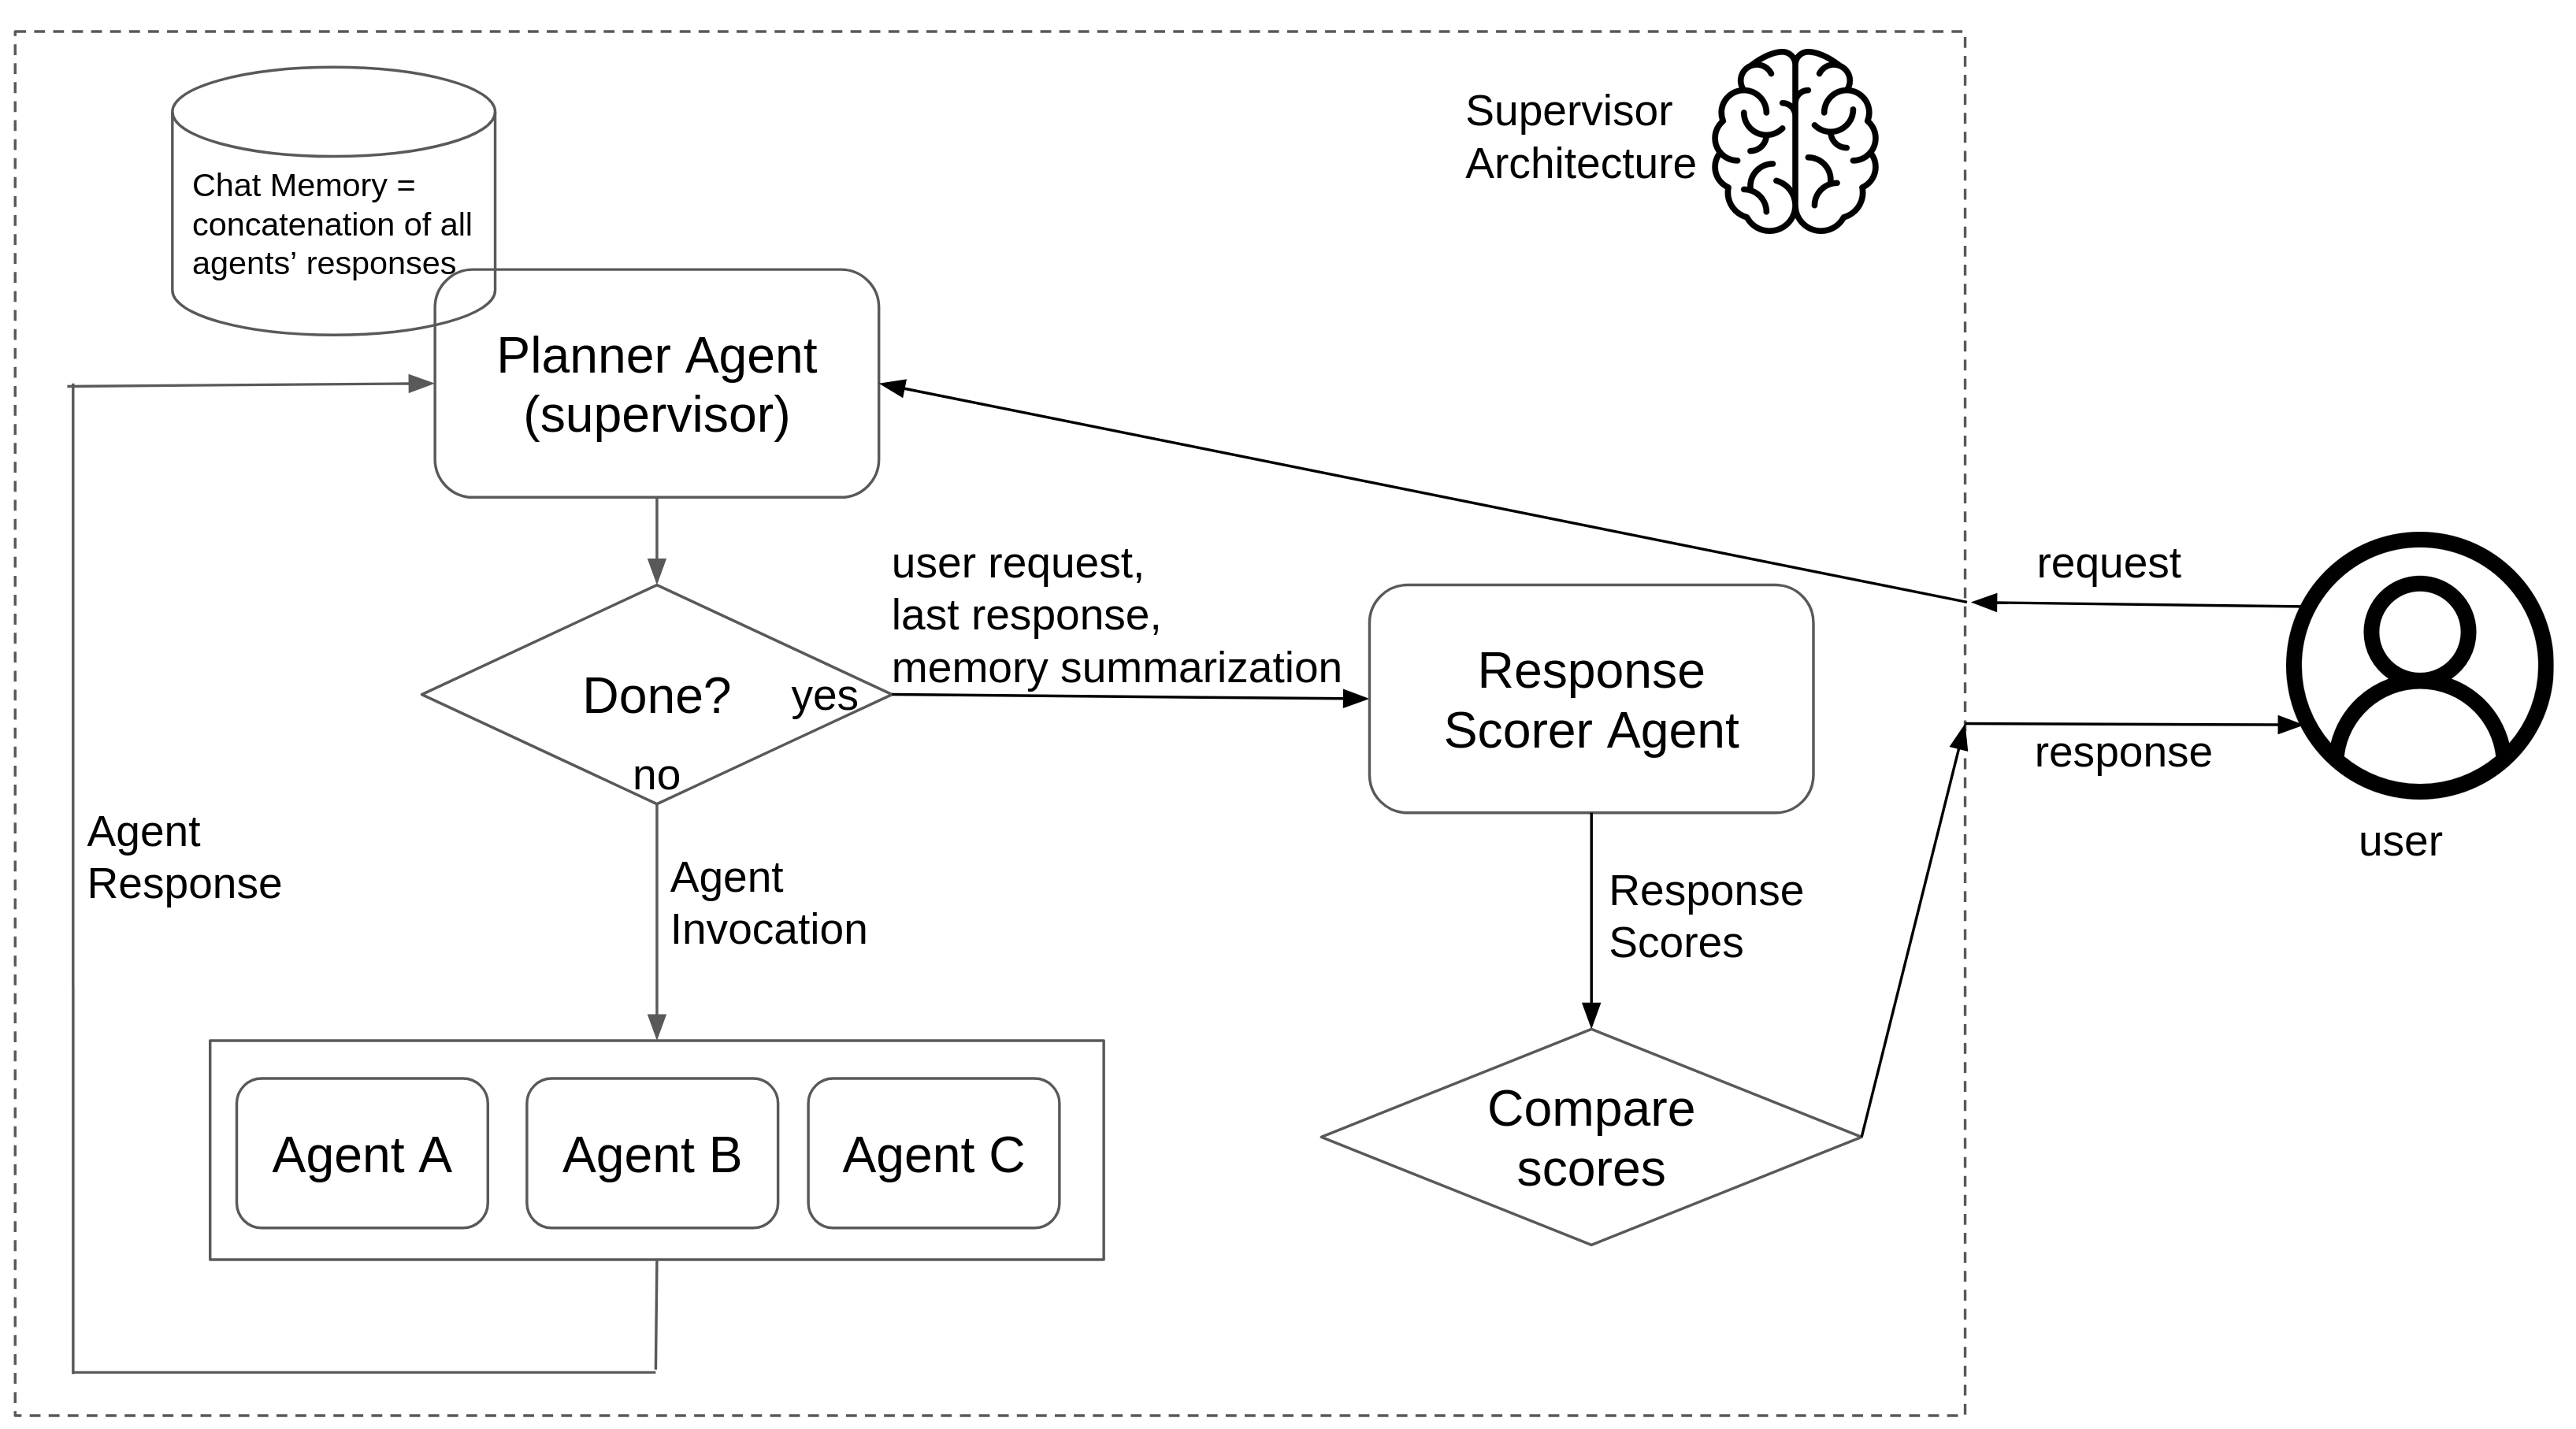
到目前为止所描述的监督者智能体架构如下图所示:
监督者用来决定下一步动作的信息,是它的另一个关键方面。默认情况下,监督者只是使用本地聊天记忆,但某些情况下,为它提供一个更全面的上下文会很有用——这个上下文通过摘要其子智能体的对话来生成,方式与上下文工程一节所讨论的非常类似,甚至可以把两种方法同时结合。这 3 种可能性由以下枚举表示:
java
public enum SupervisorContextStrategy {
    CHAT_MEMORY, SUMMARIZATION, CHAT_MEMORY_AND_SUMMARIZATION
}它可以在构建监督者智能体时用 contextGenerationStrategy 方法设置:
java
AgenticServices.supervisorBuilder()
        .contextGenerationStrategy(SupervisorContextStrategy.SUMMARIZATION)
.build();监督者智能体的其他定制点最终也可能在未来被实现并提供。
为监督者提供上下文
在许多真实场景里,监督者会从一个可选的上下文中获益:应当指导规划的约束、策略或偏好(例如"优先使用内部工具"、"不要调用外部服务"、"货币必须是 USD"等)。
这个上下文存储在 AgenticScope 中一个名为 supervisorContext 的变量里。你可以用两种方式提供它:
- 构建时配置:
java
SupervisorAgent bankSupervisor = AgenticServices
        .supervisorBuilder()
        .chatModel(PLANNER_MODEL)
        .supervisorContext("Policies: prefer internal tools; currency USD; no external APIs")
        .subAgents(withdrawAgent, creditAgent, exchangeAgent)
        .responseStrategy(SupervisorResponseStrategy.SUMMARY)
.build();- 调用(带类型的监督者):添加一个带
@V("supervisorContext")注解的参数:
java
public interface SupervisorAgent {
    @Agent
    String invoke(@V("request") String request, @V("supervisorContext") String supervisorContext);
}

// Example call (overrides the build-time value for this invocation)
bankSupervisor.invoke(
        "Transfer 100 EUR from Mario's account to Georgios' one",
        "Policies: convert to USD first; use bank tools only; no external APIs"
);- 调用(无类型的监督者):在输入 map 中设置
supervisorContext:
java
Map<String, Object> input = Map.of(
        "request", "Transfer 100 EUR from Mario's account to Georgios' one",
        "supervisorContext", "Policies: convert to USD first; use bank tools only; no external APIs"
);

String result = (String) bankSupervisor.invoke(input);若两者都提供,调用时的值会覆盖构建时的 supervisorContext。
自定义智能体模式
到目前为止讨论的智能体模式都由 langchain4j-agentic 模块开箱提供,但若没有一个契合你应用的特定需求呢?这种情况下你可以创建自己的自定义模式,以贴合你需求的方式编排一组子智能体之间的交互。
更具体地说,一个智能体模式只是它所协调子智能体的一个执行计划的规范。这个计划可以通过实现以下 Planner 接口来定义:
java
public interface Planner {

    default void init(InitPlanningContext initPlanningContext) { }

    default Action firstAction(PlanningContext planningContext) {
        return nextAction(planningContext);
    }

    Action nextAction(PlanningContext planningContext);
}这个接口有三个方法:init、firstAction 与 nextAction。init 方法在执行开始时被调用一次,可用来初始化规划器所需的任何状态或数据结构。firstAction 方法被调用来确定该智能体模式要采取的第一个动作,而 nextAction 方法在每次智能体执行之后被调用,用来根据 AgenticScope 的当前状态与上一次智能体执行的结果,确定接下来要采取的动作。
请注意,之所以引入 firstAction 方法,只是因为在许多情况下有一个独立的回调来定义 Planner 最先调用的那个智能体很方便。不过,对于无需这一区分的情形,它提供了一个简单的默认实现,只是把调用转发给 nextAction 方法,因此并非必须覆盖它。
firstAction 与 nextAction 方法所返回的 Action 类表示该智能体模式要采取的下一步,它可以是接下来要调用的一个或多个子智能体的列表,或者是执行已完成的一个信号。若动作只指定一个子智能体调用,那么它会被顺序执行、且在执行规划器本身的同一线程中;若有多个,它们会用所提供的 Executor 或 LangChain4j 默认的线程池并行执行。
所有内置的智能体模式也用这个 Planner 抽象写成,看一看它们的实现能阐明这如何工作,并成为创建你自己自定义模式的良好起点。例如,并行工作流大概是这些实现中最简单的一个,它定义如下:
java
public class ParallelPlanner implements Planner {

    private List<AgentInstance> agents;

    @Override
    public void init(InitPlanningContext initPlanningContext) {
        this.agents = initPlanningContext.subagents();
    }

    @Override
    public Action firstAction(PlanningContext planningContext) {
        return call(agents);
    }

    @Override
    public Action nextAction(PlanningContext planningContext) {
        return done();
    }
}这里,init 方法只是存储并行工作流所配置的那组子智能体列表,而 firstAction 方法返回一个把所有这些智能体并行调用的动作。一旦这次并行执行完成,没有任何其他动作要采取,因此 nextAction 方法简单地返回 done(),用来表示执行的终止。
实现顺序工作流的 Planner 只是稍微复杂一点,因为它需要用内部游标跟踪接下来要调用的子智能体,然后在 nextAction 方法中返回合适的动作,或在所有子智能体都已调用后表示执行终止。
java
public class SequentialPlanner implements Planner {

    private List<AgentInstance> agents;
    private int agentCursor = 0;

    @Override
    public void init(InitPlanningContext initPlanningContext) {
        this.agents = initPlanningContext.subagents();
    }

    @Override
    public Action nextAction(PlanningContext planningContext) {
        return agentCursor >= agents.size() ? done() : call(agents.get(agentCursor++));
    }
}要理解如何从一个规划器实现定义一个智能体系统,例如,你可以创建一个先前讨论的顺序工作流的实例,它为一个主题生成小说,然后针对特定风格与受众编辑它,如下:
java
UntypedAgent novelCreator = AgenticServices.plannerBuilder()
                .subAgents(creativeWriter, audienceEditor, styleEditor)
                .outputKey("story")
                .planner(SequentialPlanner::new)
.build();这完全等同于使用顺序工作流的专用 API:
java
UntypedAgent novelCreator = AgenticServices.sequenceBuilder()
                .subAgents(creativeWriter, audienceEditor, styleEditor)
                .outputKey("story")
.build();plannerBuilder() 方法与所有其他智能体 builder 类似,唯一的区别是它要求提供一个 Supplier<Planner>,返回该智能体系统所要用到的、那个特定规划器的一个新实例。当然,一个实现了自定义规划器的智能体系统,能与 langchain4j-agentic 模块开箱提供的任何其他智能体模式无缝组合。
阐明这个 Planner 抽象如何工作之后,现在就能通过实现它来创建你自己的自定义智能体模式。接下来的小节讨论在 langchain4j-agentic-patterns 模块中提供的两个自定义模式示例,它们在不同场景下很有用。也可以照同样的思路创建其他自定义模式,并可能回馈贡献给 LangChain4j 项目。
目标导向的智能体模式
工作流模式与监督者智能体代表了可能智能体系统谱系的两端:前者完全确定、僵化,强迫你事先决定要调用的智能体序列;后者完全灵活、自适应,但把决定智能体调用序列的权力交给了一个非确定性的 LLM。然而有些情况下,介于这两端之间的中间地带可能更合适,它让智能体以一种相对灵活的方式朝某个特定目标努力,同时以算法化的方式决定这些智能体应如何被调用。
为把这一方法付诸实践,不仅整个智能体系统需要定义一个目标,每个子智能体也需要声明它自己的前置与后置条件。这是为了以尽可能快的方式计算出通向目标的那串智能体调用序列。不过,所有这些信息其实都已隐含地存在于智能体系统中,因为那些前置与后置条件无非就是每个智能体的必需输入与所产生输出,而最终目标就是整个智能体系统的期望输出。
遵循这一思路,可以计算出参与智能体系统的所有子智能体的一张依赖图,然后实现一个 Planner,它能分析 AgenticScope 的初始状态、与期望目标做比较,随后用那张图来确定能通向该目标达成的智能体调用序列。
java
public class GoalOrientedPlanner implements Planner {

    private String goal;

    private GoalOrientedSearchGraph graph;
    private List<AgentInstance> path;

    private int agentCursor = 0;

    @Override
    public void init(InitPlanningContext initPlanningContext) {
        this.goal = initPlanningContext.plannerAgent().outputKey();
        this.graph = new GoalOrientedSearchGraph(initPlanningContext.subagents());
    }

    @Override
    public Action firstAction(PlanningContext planningContext) {
        path = graph.search(planningContext.agenticScope().state().keySet(), goal);
        if (path.isEmpty()) {
            throw new IllegalStateException("No path found for goal: " + goal);
        }
        return call(path.get(agentCursor++));
    }

    @Override
    public Action nextAction(PlanningContext planningContext) {
        return agentCursor >= path.size() ? done() : call(path.get(agentCursor++));
    }
}如前所述,这里的目标与这个基于规划器的智能体模式本身的最终输出一致,而从初始状态到目标的路径则用一张 GoalOrientedSearchGraph 来计算,它通过分析所有子智能体的输入与输出键来构建。要调用的智能体序列随后被计算为该图上从当前状态到期望目标的最短路径。
为给出一个它如何工作的实践示例,我们尝试构建一个目标导向的智能体系统,它能从一个提示词中抽取一个人的名字与星座,生成该星座的运势,在互联网上寻找一个相关的故事,最后把所有这些信息组合成一篇漂亮的文稿。我们可以用以下 5 个智能体来完成这组任务:
java
public interface HoroscopeGenerator {
    @SystemMessage("You are an astrologist that generates horoscopes based on the user's name and zodiac sign.")
    @UserMessage("Generate the horoscope for {{person}} who is a {{sign}}.")
    @Agent("An astrologist that generates horoscopes based on the user's name and zodiac sign.")
    String horoscope(@V("person") Person person, @V("sign") Sign sign);
}

public interface PersonExtractor {

    @UserMessage("Extract a person from the following prompt: {{prompt}}")
    @Agent("Extract a person from user's prompt")
    Person extractPerson(@V("prompt") String prompt);
}

public interface SignExtractor {

    @UserMessage("Extract the zodiac sign of a person from the following prompt: {{prompt}}")
    @Agent("Extract a person from user's prompt")
    Sign extractSign(@V("prompt") String prompt);
}

public interface Writer {
    @UserMessage("""
            Create an amusing writeup for {{person}} based on the following:
            - their horoscope: {{horoscope}}
            - a current news story: {{story}}
            """)
    @Agent("Create an amusing writeup for the target person based on their horoscope and current news stories")
    String write(@V("person") Person person, @V("horoscope") String horoscope, @V("story") String story);
}

public interface StoryFinder {

    @SystemMessage("""
            You're a story finder, use the provided web search tools, calling it once and only once,
            to find a fictional and funny story on the internet about the user provided topic.
            """)
    @UserMessage("""
            Find a story on the internet for {{person}} who has the following horoscope: {{horoscope}}.
            """)
    @Agent("Find a story on the internet for a given person with a given horoscope")
    String findStory(@V("person") Person person, @V("horoscope") String horoscope);
}借助前面开发的 GoalOrientedPlanner,这些智能体可以像这样被组合成一个目标导向的智能体系统:
java
HoroscopeGenerator horoscopeGenerator = AgenticServices.agentBuilder(HoroscopeGenerator.class)
        .chatModel(baseModel())
        .outputKey("horoscope")
        .build();

PersonExtractor personExtractor = AgenticServices.agentBuilder(PersonExtractor.class)
        .chatModel(baseModel())
        .outputKey("person")
        .build();

SignExtractor signExtractor = AgenticServices.agentBuilder(SignExtractor.class)
        .chatModel(baseModel())
        .outputKey("sign")
        .build();

Writer writer = AgenticServices.agentBuilder(Writer.class)
        .chatModel(baseModel())
        .outputKey("writeup")
        .build();

StoryFinder storyFinder = AgenticServices.agentBuilder(StoryFinder.class)
        .chatModel(baseModel())
        .tools(new WebSearchTool())
        .outputKey("story")
        .build();

UntypedAgent horoscopeAgent = AgenticServices.plannerBuilder()
        .subAgents(horoscopeGenerator, personExtractor, signExtractor, writer, storyFinder)
        .outputKey("writeup")
        .planner(GoalOrientedPlanner::new)
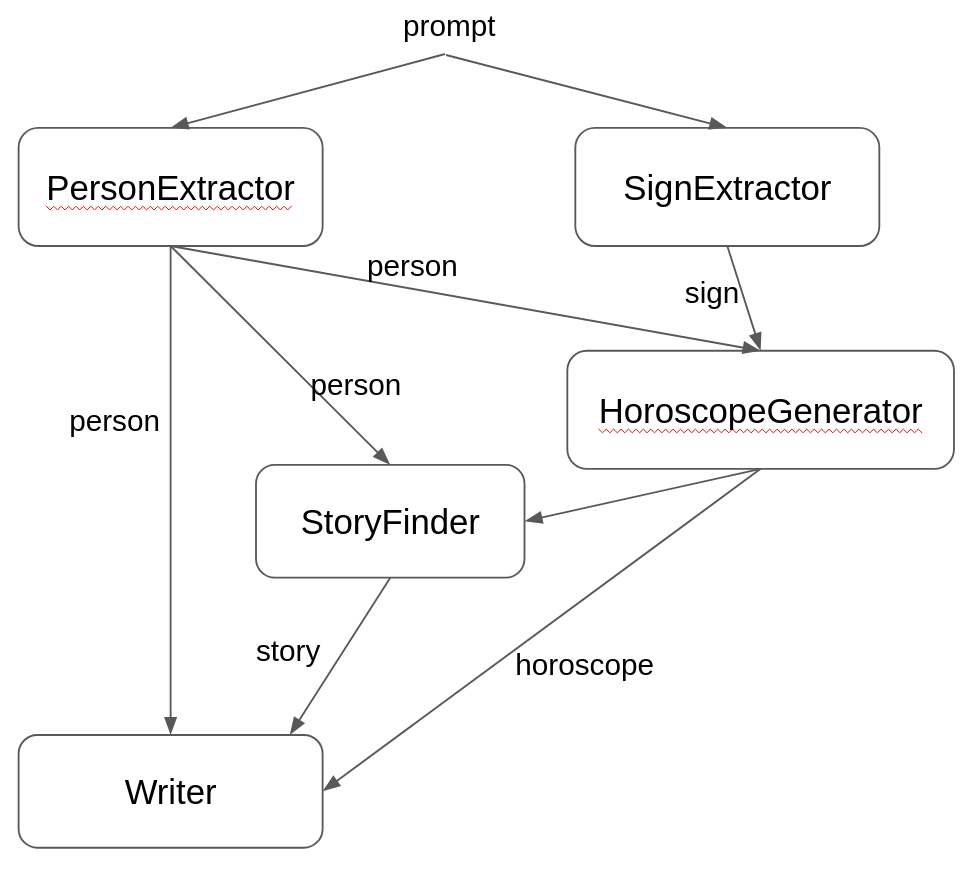
.build();如前所述,这个智能体系统的整体目标是产出一篇 writeup,它同时也是这个基于 GOAP 的规划器的输出键。考虑到所有子智能体的输入与输出,GoalOrientedSearchGraph 所构建的依赖图会像这样:
当用一个像 "My name is Mario and my zodiac sign is pisces" 的提示词调用这个智能体系统时
java
Map<String, Object> input = Map.of("prompt", "My name is Mario and my zodiac sign is pisces");
String writeup = horoscopeAgent.invoke(input);GoalOrientedPlanner 会分析 AgenticScope 的初始状态(它只含有 prompt 变量),然后计算那张依赖图上从该初始状态到期望目标(即 writeup)的最短路径,从而所得的智能体调用序列会是:
Agents path sequence: [extractPerson, extractSign, horoscope, findStory, write]请注意,正如前述,这个目标导向的智能体模式可以与任何其他现有智能体模式混合组合。例如,这种可能性可用来克服此方法一个明显的局限:它为沿最短路径达成特定目标而优化,因此结构上不允许循环,所以某些情况下,把一个循环智能体模式作为这个目标导向模式的子智能体会很有用。
点对点智能体模式
到目前为止讨论的所有智能体系统都基于一个中心化、分层的架构。实际上所有工作流模式都有一个明确定义的顶层智能体,以编程方式预定的方式协调多个子智能体的活动。即便是监督者模式,虽然因为它那个基于 LLM 的规划器智能体而更灵活、更动态,仍然依赖一个协调者智能体来控制各子智能体之间的交互。这类架构适用于许多应用与场景,但它们也有一些局限,尤其在可扩展性与容错方面。这就是为什么我们可能想为多智能体系统提供一个点对点的替代方案,它通过采用一种更去中心化、分布式的方法来克服这些局限。
在一个点对点智能体系统里没有任何顶层智能体,所有智能体都是平等的同伴,通过 AgenticScope 的状态来协调。特别地,一个智能体被它自己的必需输入作为状态变量出现在 AgenticScope 中时触发。随后,由不同智能体的输出所产生的、对其中一个或多个变量的更改,会再次触发那个智能体的调用。该过程在以下任一情况终止:AgenticScope 达到稳定状态、再无智能体可被调用;或预定义的退出条件被满足;或达到了最大智能体调用次数。一个实现这一点对点智能体模式的 Planner 可以像这样写:
java
public class P2PPlanner implements Planner {

    private final int maxAgentsInvocations;
    private final BiPredicate<AgenticScope, Integer> exitCondition;

    private int invocationCounter = 0;
    private Map<String, AgentActivator> agentActivators;

    public P2PPlanner(int maxAgentsInvocations, BiPredicate<AgenticScope, Integer> exitCondition) {
        this(null, maxAgentsInvocations, exitCondition);
    }

    @Override
    public void init(InitPlanningContext initPlanningContext) {
        this.agentActivators = initPlanningContext.subagents().stream().collect(toMap(AgentInstance::agentId, AgentActivator::new));
    }

    @Override
    public Action nextAction(PlanningContext planningContext) {
        if (terminated(planningContext.agenticScope())) {
            return done();
        }

        AgentActivator lastExecutedAgent = agentActivators.get(planningContext.previousAgentInvocation().agentId());
        lastExecutedAgent.finishExecution();
        agentActivators.values().forEach(a -> a.onStateChanged(lastExecutedAgent.agent.outputKey()));

        return nextCallAction(planningContext.agenticScope());
    }

    private Action nextCallAction(AgenticScope agenticScope) {
        AgentInstance[] agentsToCall = agentActivators.values().stream()
                .filter(agentActivator -> agentActivator.canActivate(agenticScope))
                .peek(AgentActivator::startExecution)
                .map(AgentActivator::agent)
                .toArray(AgentInstance[]::new);

        if (agentsToCall.length == 0 && agentActivators.values().stream().noneMatch(AgentActivator::isExecuting)) {
            // no agent can be activated and none is still running: the agentic scope reached a stable state
            return done();
        }

        invocationCounter += agentsToCall.length;
        return call(agentsToCall);
    }

    private boolean terminated(AgenticScope agenticScope) {
        return invocationCounter > maxAgentsInvocations || exitCondition.test(agenticScope, invocationCounter);
    }
}这里,P2PPlanner 跟踪到目前为止已执行的智能体调用次数,并为每个子智能体用一个 AgentActivator 根据 AgenticScope 的当前状态判断它能否被调用。nextAction 方法检查退出条件是否已满足、或最大调用次数是否已达到,若未,它会识别出所有基于当前状态可被激活的智能体、把它们标记为已启动,并返回一个调用它们的动作。当没有智能体可被激活、也没有智能体仍在运行时,agentic scope 达到了稳定状态,规划器通过返回一个 done 动作来终止循环。
为给出一个它如何工作的实践示例,我们尝试构建一个点对点智能体系统,它能就某个主题执行科学研究并提出新假设,从而该服务的 API 可能像这样:
java
public interface ResearchAgent {

    @Agent("Conduct research on a given topic")
    String research(@V("topic") String topic);
}为此可以定义以下 5 个智能体:
java
public interface LiteratureAgent {

    @SystemMessage("Search for scientific literature on the given topic and return a summary of the findings.")
    @UserMessage("""
            You are a scientific literature search agent.
            Your task is to find relevant scientific papers on the topic provided by the user and summarize them.
            Use the provided tool to search for scientific papers and return a summary of your findings.
            The topic is: {{topic}}
            """)
    @Agent("Search for scientific literature on a given topic")
    String searchLiterature(@V("topic") String topic);
}

public interface HypothesisAgent {

    @SystemMessage("Based on the research findings, formulate a clear and concise hypothesis related to the given topic.")
    @UserMessage("""
            You are a hypothesis formulation agent.
            Your task is to formulate a clear and concise hypothesis based on the research findings provided by the user.
            The topic is: {{topic}}
            The research findings are: {{researchFindings}}
            """)
    @Agent("Formulate hypothesis around a give topic based on research findings")
    String makeHypothesis(@V("topic") String topic, @V("researchFindings") String researchFindings);
}

public interface CriticAgent {

    @SystemMessage("Critically evaluate the given hypothesis related to the specified topic. Provide constructive feedback and suggest improvements if necessary.")
    @UserMessage("""
            You are a critical evaluation agent.
            Your task is to critically evaluate the hypothesis provided by the user in relation to the specified topic.
            Provide constructive feedback and suggest improvements if necessary.
            If you need to, you can also perform additional research to validate or confute the hypothesis using the provided tool.
            The topic is: {{topic}}
            The hypothesis is: {{hypothesis}}
            """)
    @Agent("Critically evaluate a hypothesis related to a given topic")
    String criticHypothesis(@V("topic") String topic, @V("hypothesis") String hypothesis);
}

public interface ValidationAgent {

    @SystemMessage("Validate the provided hypothesis on the given topic based on the critique provided.")
    @UserMessage("""
            You are a validation agent.
            Your task is to validate the hypothesis provided by the user in relation to the specified topic based on the critique provided.
            Validate the provided hypothesis, either confirming it or reformulating a different hypothesis based on the critique.
            The topic is: {{topic}}
            The hypothesis is: {{hypothesis}}
            The critique is: {{critique}}
            """)
    @Agent("Validate a hypothesis based on a given topic and critique")
    String validateHypothesis(@V("topic") String topic, @V("hypothesis") String hypothesis, @V("critique") String critique);
}

public interface ScorerAgent {

    @SystemMessage("Score the provided hypothesis on the given topic based on the critique provided.")
    @UserMessage("""
            You are a scoring agent.
            Your task is to score the hypothesis provided by the user in relation to the specified topic based on the critique provided.
            Score the provided hypothesis on a scale from 0.0 to 1.0, where 0.0 means the hypothesis is completely invalid and 1.0 means the hypothesis is fully valid.
            The topic is: {{topic}}
            The hypothesis is: {{hypothesis}}
            The critique is: {{critique}}
            """)
    @Agent("Score a hypothesis based on a given topic and critique")
    double scoreHypothesis(@V("topic") String topic, @V("hypothesis") String hypothesis, @V("critique") String critique);
}这些智能体都会被提供一个能执行科学文献研究的工具,例如从 arXiv 下载学术论文,然后被加入这个 P2P 智能体系统:
java
ArxivCrawler arxivCrawler = new ArxivCrawler();

LiteratureAgent literatureAgent = AgenticServices.agentBuilder(LiteratureAgent.class)
        .chatModel(baseModel())
        .tools(arxivCrawler)
        .outputKey("researchFindings")
        .build();
HypothesisAgent hypothesisAgent = AgenticServices.agentBuilder(HypothesisAgent.class)
        .chatModel(baseModel())
        .tools(arxivCrawler)
        .outputKey("hypothesis")
        .build();
CriticAgent criticAgent = AgenticServices.agentBuilder(CriticAgent.class)
        .chatModel(baseModel())
        .tools(arxivCrawler)
        .outputKey("critique")
        .build();
ValidationAgent validationAgent = AgenticServices.agentBuilder(ValidationAgent.class)
        .chatModel(baseModel())
        .tools(arxivCrawler)
        .outputKey("hypothesis")
        .build();
ScorerAgent scorerAgent = AgenticServices.agentBuilder(ScorerAgent.class)
        .chatModel(baseModel())
        .tools(arxivCrawler)
        .outputKey("score")
        .build();

ResearchAgent researcher = AgenticServices.plannerBuilder(ResearchAgent.class)
        .subAgents(literatureAgent, hypothesisAgent, criticAgent, validationAgent, scorerAgent)
        .outputKey("hypothesis")
        .planner(() -> new P2PPlanner(10, agenticScope -> {
            if (!agenticScope.hasState("score")) {
                return false;
            }
            double score = agenticScope.readState("score", 0.0);
            System.out.println("Current hypothesis score: " + score);
            return score >= 0.85;
        }))
        .build();

String hypothesis = researcher.research("black holes");用这一配置,researcher P2P 协调者被传入研究的主题。此时唯一能被调用的智能体是 literatureAgent,因为它是唯一一个所有必需输入(这里是 topic)都存在于 AgenticScope 的智能体。调用这个智能体会产生 researchFindings 变量,它被加入 AgenticScope 状态,而这个新变量触发了 HypothesisAgent 的调用。随后它产生一个 hypothesis,进而触发 criticAgent。最后,ValidationAgent 接收 hypothesis 与 critique 作为输入,生成一个新的 hypothesis,最终又再次触发其他智能体。在此期间 ScorerAgent 给 hypothesis 一个 score,当这个 score 大于等于 0.85、或已执行最多 10 次智能体调用时,过程终止。下图总结了这次执行所涉及的所有智能体与变量。
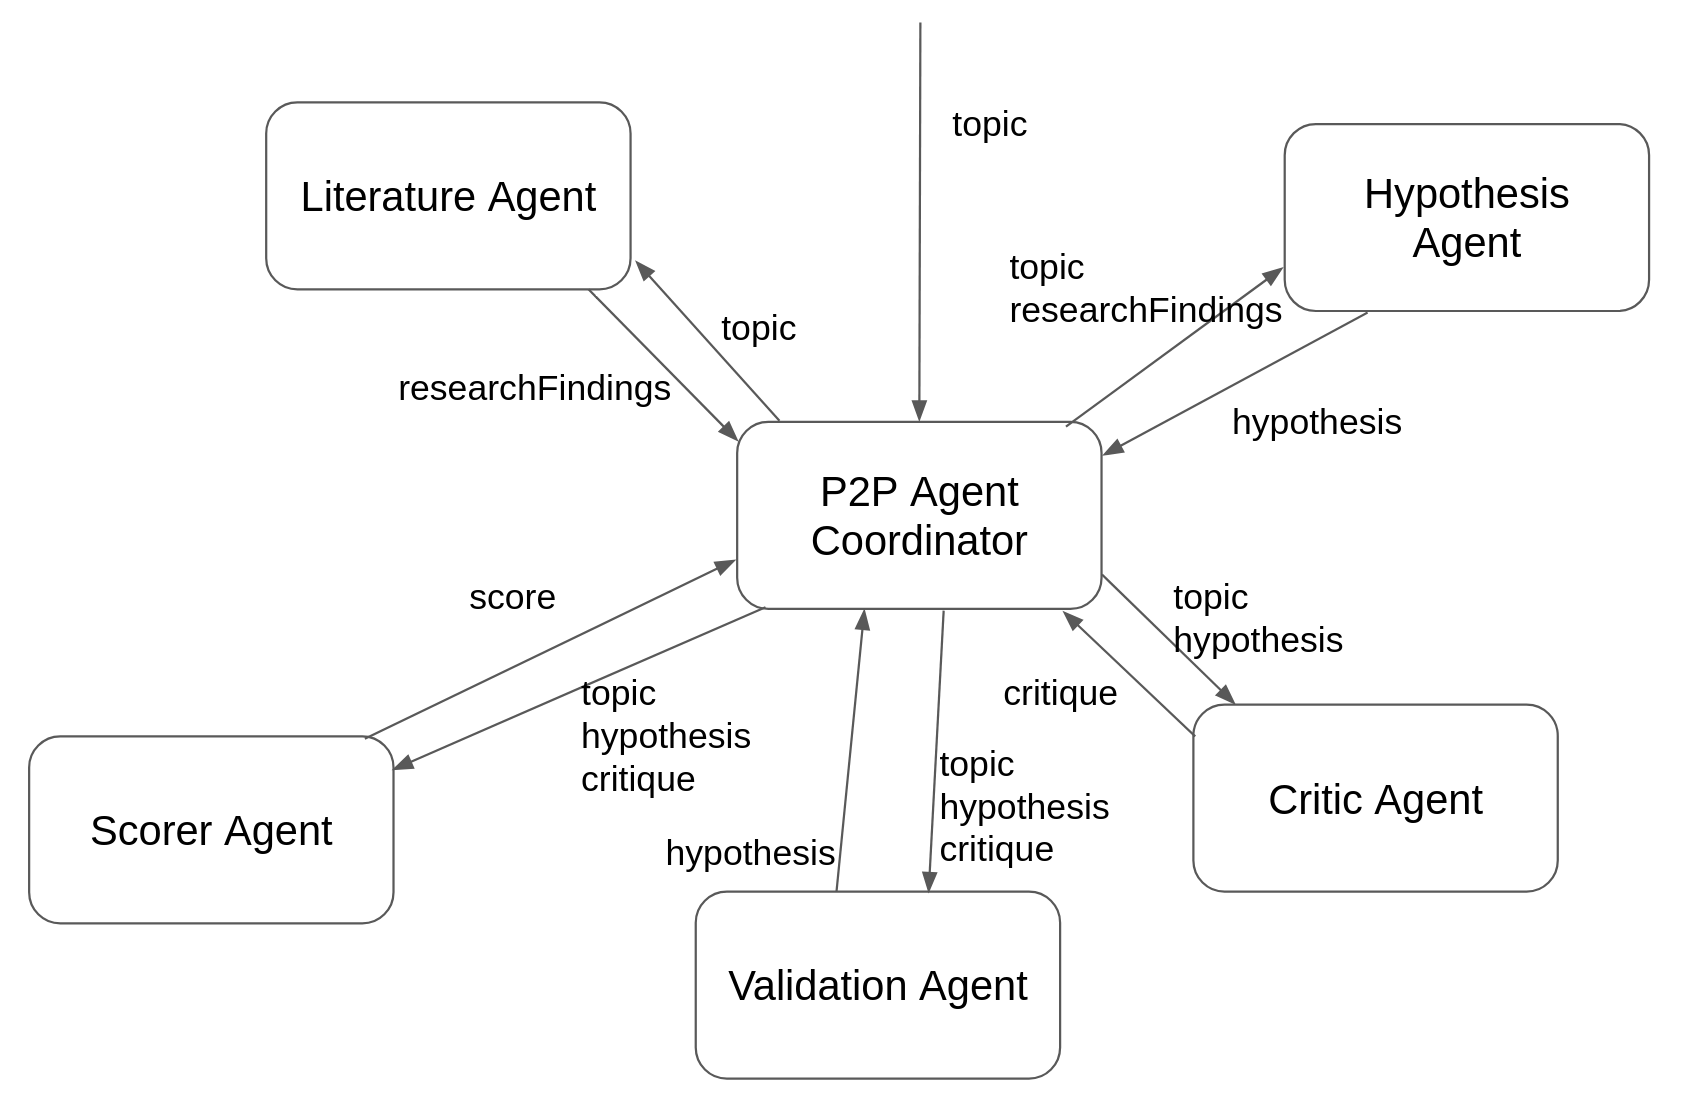
例如,这个示例的一次典型运行可能因为 ScorerAgent 产生了高于预定阈值的分数而终止
Current hypothesis score: 0.95最终输出可能像这样:
Based on the provided references, here are some key points about stochastic gravitational wave backgrounds (SGWBs) from primordial black holes (PBHs):

1. **Detection Rates and Sources:**
   - The detection rate of gravity waves emitted during parabolic encounters of stellar black holes in globular clusters was estimated by Kocsis et al. [85].
   - Gravitational wave bursts from PBH hyperbolic encounters were discussed by García-Bellido and Nesseris [93].

2. **Energy Emission:**
   - The energy spectrum of gravitational waves from hyperbolic encounters was studied by De Vittori, Jetzer, and Klein [88].
   - Gravitational wave energy emission and detection rates for PBH hyperbolic encounters were analyzed by García-Bellido and Nesseris [90].

3. **Template Banks:**
   - Template banks for gravitational waveforms from coalescing binary black holes (including non-spinning binaries) were developed by Ajith et al. [92].

4. **Constraints on PBHs:**
   - Constraints on primordial black holes were reviewed by Carr, Kohri, Sendouda, and Yokoyama [98].
   - Universal gravitational wave signatures of cosmological solitons were discussed by Lozanov, Sasaki, and Takhistov [100].

5. **Induced SGWBs:**
   - Doubly peaked induced stochastic gravitational wave backgrounds were tested for baryogenesis from primordial black holes by Bhaumik et al. [101].
   - Distinct signatures of spinning PBH domination and evaporation, including doubly peaked gravitational waves, dark relics, and CMB complementarity, were explored by Bhaumik et al. [101].

6. **Future Detectors:**
   - Future detectors like Taiji, LISA, DECIGO, Big Bang Observer, Cosmic Explorer, Einstein Telescope, and KAGRA are expected to contribute significantly to the detection of SGWBs from PBHs.

7. **Pulsar Timing Arrays:**
   - Pulsar timing arrays have been used to search for an isotropic stochastic gravitational wave background [73-75].

8. **Template Banks and Simulations:**
- Template banks like those developed by Ajith et al. are crucial for matching observed signals with theoretical predictions.黑板智能体模式
P2P 模式并行激活所有就绪的智能体,把它们当作平等的同伴。然而有些场景需要一个中心化的调度器来决定哪个单一智能体下一个触发,当多个智能体都能贡献时施加冲突解决。这就是黑板模式:智能体是把部分结果发布到 AgenticScope(即黑板)的知识源,而一个中心化的规划器在每一步之后检视黑板,以激活最合适的智能体。
与 P2P 一样,当智能体的所有参数都存在于 scope 中时它们被隐式激活。关键区别是每步只触发一个智能体,且当多个智能体就绪时,由一个 ConflictResolutionStrategy 决定哪个优先。若未提供策略,则用 subAgents 方法中的声明顺序作为默认打破平局的依据。
BlackboardPlanner 在目标谓词被满足、或没有智能体能触发(静止)时成功终止;若在目标满足之前达到最大调用次数,它抛出 IllegalStateException。默认情况下,目标谓词检查规划器的 outputKey 是否存在于 scope 中——这是最常见的终止条件:
java
public class BlackboardPlanner implements Planner {

    private final Predicate<AgenticScope> goalPredicate;
    private final ConflictResolutionStrategy conflictResolutionStrategy;
    private final int maxInvocations;

    @Override
    public Action nextAction(PlanningContext planningContext) {
        // After each agent completes:
        // 1. Check goal predicate → done() if satisfied
        // 2. Find all agents whose inputs are available
        // 3. Pick the best one via conflict resolution (or declaration order)
        // 4. Return call(selectedAgent) — always exactly one agent per step
    }
}ConflictResolutionStrategy 是一个函数式接口,它接收当前的 scope 与所有就绪可触发的候选智能体,返回应当被激活的那个。
java
@FunctionalInterface
public interface ConflictResolutionStrategy {

    AgentInstance resolve(AgenticScope scope, List<AgentInstance> candidates);
}该接口自带一些便捷的工厂方法,以及一个 or 组合器来把多个策略串起来。例如,declarationOrder() 简单地选取第一个候选,保留 subAgents 方法中使用的顺序;而 agentOfType 选取匹配给定类型的候选——可选地由一个针对 AgenticScope 的条件来守护,并在条件不满足或不存在该类型的候选时返回 null。or 组合器把两个策略串起来:若第一个返回 null,就尝试第二个。合起来它们让你能构建像 agentOfType(X.class, condition).or(declarationOrder()) 这样的流水线,读作"条件成立时优先选类型为 X 的智能体,否则回退到声明顺序"。
作为一个实践示例,考虑一个医疗诊断系统,其中专家智能体把发现发布到黑板上,且只有在积累了足够证据后才产出诊断。智能体触发的顺序并非预定,而取决于有哪些数据可用:
java
SymptomExtractor symptomExtractor = AgenticServices.agentBuilder(SymptomExtractor.class)
        .chatModel(baseModel()).build();

LabResultAnalyzer labAnalyzer = AgenticServices.agentBuilder(LabResultAnalyzer.class)
        .chatModel(baseModel()).build();

DrugInteractionChecker drugInteraction = AgenticServices.agentBuilder(DrugInteractionChecker.class)
        .chatModel(baseModel()).build();

DiagnosisAgent diagnosis = AgenticServices.agentBuilder(DiagnosisAgent.class)
        .chatModel(baseModel()).build();

MedicalDiagnostics diagnostics = AgenticServices.plannerBuilder(MedicalDiagnostics.class)
        .subAgents(symptomExtractor, labAnalyzer, drugInteraction, diagnosis)
        .planner(BlackboardPlanner::new)
        .outputKey("diagnosis")
        .build();

String result = diagnostics.diagnose(patientInput, labResults, medications);SymptomExtractor 最先触发,因为它唯一的输入(patientInput)从一开始就可用。一旦症状被抽取,LabResultAnalyzer 与 DrugInteractionChecker 都可能变得可触发——但每步只触发一个。最后,当 symptoms 与 labAnalysis 都在黑板上时,DiagnosisAgent 触发。系统终止是因为默认的目标谓词检测到 "diagnosis"(规划器的 outputKey)现在存在于 scope 中。当终止条件更复杂时,可以给 BlackboardPlanner 构造函数提供一个自定义的目标谓词。
当临床上下文对智能体排序很重要时,一个 ConflictResolutionStrategy 可以检查 scope 状态以做出明智决定。例如,若病人的症状提及了药物或副作用,药物相互作用分析就应优先于化验分析。
java
MedicalDiagnostics diagnostics = AgenticServices.plannerBuilder(MedicalDiagnostics.class)
        .subAgents(symptomExtractor, labAnalyzer, drugInteraction, diagnosis)
        .planner(() -> new BlackboardPlanner(
                agentOfType(DrugInteractionChecker.class, scope -> {
                            String symptoms = scope.readState("symptoms", "");
                            return symptoms.toLowerCase().contains("medication")
                                    || symptoms.toLowerCase().contains("drug");
                        })
                        .or(declarationOrder())))
        .outputKey("diagnosis")
.build();为丰富这个示例,一个 HumanInTheLoop 智能体也能直接作为知识源参与黑板。inputKey 方法声明人类审核者所依赖的 scope 键,从而黑板只有在该数据可用时才激活它。它的 outputKey 被设为 "symptoms"——当审核者拒绝一个诊断时,返回值会用额外信息覆写症状,这自然地重新触发所有依赖症状的智能体:
java
HumanInTheLoop humanReview = AgenticServices.humanInTheLoopBuilder()
        .description("Review the diagnosis and decide whether to approve or request additional analysis")
        .outputKey("symptoms")
        .inputKey(String.class, "diagnosis")
        .responseProvider(scope -> {
            String diagnosis = scope.readState("diagnosis", "");
            String symptoms = scope.readState("symptoms", "");
            if (!isAcceptable(diagnosis)) {
                return symptoms + ". Patient also reports blurred vision.";
            }
            scope.writeState("approvedDiagnosis", diagnosis);
            return symptoms;
        })
        .build();

MedicalDiagnostics diagnostics = AgenticServices.plannerBuilder(MedicalDiagnostics.class)
        .subAgents(symptomExtractor, labAnalyzer, drugInteraction, diagnosisAgent, humanReview)
        .planner(() -> new BlackboardPlanner(
                scope -> scope.hasState("approvedDiagnosis"),
                agentOfType(DrugInteractionChecker.class, scope -> {
                            String symptoms = scope.readState("symptoms", "");
                            return symptoms.toLowerCase().contains("medication")
                                    || symptoms.toLowerCase().contains("drug");
                        })
                        .or(declarationOrder())))
        .outputKey("approvedDiagnosis")
.build();inputKey(String.class, "diagnosis") 告诉黑板:审核者应当只在 "diagnosis" 存在于 scope 之后才激活。当审核者拒绝时,返回值(经增强的症状)经由 HITL 的 outputKey 被写入 "symptoms" 键。随后黑板常规的 onStateChanged("symptoms") 机制会重新激活依赖症状的智能体(例如 DrugInteractionChecker 与 DiagnosisAgent),为下一次审核产出一个修订的诊断。请注意,在这第二个实现中,通过 BlackboardPlanner 实现的 MedicalDiagnostics 的 outputKey 从 "diagnosis" 改为了 "approvedDiagnosis",以给 HumanInTheLoop 参与该智能体系统执行的机会。这样,当审核者批准时,它把 "approvedDiagnosis" 写入 AgenticScope,从而满足目标谓词。
投票智能体模式
到目前为止讨论的智能体模式,编排的都是做不同事情的智能体——它们拆分工作、排序任务或路由决策。然而有些情况下,你想让多个智能体独立地处理同一个问题,然后聚合它们的答案以产生一个更稳健的结果。这就是投票(或议事会 council)模式:在同一个输入上并行运行所有子智能体,把它们的输出收集为选票,并通过一个可插拔的聚合策略来调和它们。
这个模式对分类、内容审核、风险评估,以及任何跨多样方法达成的共识比单个智能体判断更可靠的决策尤其有用。通过让带有不同提示词、模型或视角的智能体分析同一个输入,你降低了单个智能体的偏见或错误传播到最终结果的可能。
VotingPlanner 并行分发所有子智能体,等待它们全部完成,并用一个 VotingStrategy 聚合它们的输出:
java
public class VotingPlanner implements Planner {

    private final VotingStrategy strategy;

    private List<AgentInstance> subagents;
    private int completedCount;
    private final List<Object> votes = new ArrayList<>();

    public VotingPlanner() {
        this(VotingStrategy.majority());
    }

    public VotingPlanner(VotingStrategy strategy) {
        this.strategy = strategy;
    }

    @Override
    public void init(InitPlanningContext initPlanningContext) {
        this.subagents = initPlanningContext.subagents();
    }

    @Override
    public Action firstAction(PlanningContext planningContext) {
        if (subagents.isEmpty()) {
            return done();
        }
        return call(subagents);
    }

    @Override
    public Action nextAction(PlanningContext planningContext) {
        votes.add(planningContext.previousAgentInvocation().output());
        completedCount++;

        if (completedCount < subagents.size()) {
            return noOp();
        }

        return done(strategy.aggregate(votes));
    }

    @Override
    public AgenticSystemTopology topology() {
        return AgenticSystemTopology.STAR;
    }
}firstAction 方法一次性分发所有子智能体。由于拓扑是 STAR,框架会并行执行它们,并在每个智能体完成时调用一次 nextAction。每次调用都把已完成智能体的输出收集为一票。当所有智能体都投了票,规划器就通过 VotingStrategy 聚合结果并表示完成。
VotingStrategy 是一个只有一个方法、带三个内置静态工厂方法的函数式接口:
java
@FunctionalInterface
public interface VotingStrategy {

    Object aggregate(Collection<Object> votes);

    static VotingStrategy majority() { ... }  // most common value wins
    static VotingStrategy average() { ... }   // mean of numeric values
    static VotingStrategy highest() { ... }   // max by natural ordering
}majority()按相等对票分组并返回最常见的值——最适合智能体返回分类标签的分类任务。average()计算数值票的算术平均——适合智能体返回置信值或评分的打分任务。highest()按自然序选取最大值——适合你想要最乐观或最高置信评估时。
用户也可以通过一个 lambda 表达式提供自定义策略,例如实现加权投票、基于置信的过滤,或法定人数规则。
为给出一个它如何工作的实践示例,我们构建一个基于投票的情感分类器,它用三个带不同提示词的独立智能体来分类客户反馈。每个智能体被指示恰好返回一个词:POSITIVE、NEGATIVE 或 NEUTRAL。
java
public interface SentimentClassifier1 {

    @UserMessage("""
            Classify the sentiment of the following text.
            Reply with exactly one word: POSITIVE, NEGATIVE, or NEUTRAL.
            The text is: "{{text}}"
            """)
    @Agent("Classify the sentiment of a given text")
    String classify(@V("text") String text);
}

public interface SentimentClassifier2 {

    @UserMessage("""
            You are a sentiment analysis expert.
            Analyze the emotional tone of the following text and classify it.
            Reply with exactly one word: POSITIVE, NEGATIVE, or NEUTRAL.
            The text is: "{{text}}"
            """)
    @Agent("Analyze the emotional tone of a given text")
    String classify(@V("text") String text);
}

public interface SentimentClassifier3 {

    @UserMessage("""
            You are a customer feedback analyst.
            Determine whether the following feedback is positive, negative, or neutral.
            Reply with exactly one word: POSITIVE, NEGATIVE, or NEUTRAL.
            The text is: "{{text}}"
            """)
    @Agent("Determine the sentiment of customer feedback")
    String classify(@V("text") String text);
}每个分类器从一个略不同的角度处理同一任务:一个是通用的,一个是专家分析师,一个专攻客户反馈。这三个智能体随后可以像这样被组合成一个基于投票的智能体系统:
java
SentimentClassifier1 c1 = AgenticServices.agentBuilder(SentimentClassifier1.class)
        .chatModel(baseModel())
        .outputKey("vote1")
        .build();

SentimentClassifier2 c2 = AgenticServices.agentBuilder(SentimentClassifier2.class)
        .chatModel(baseModel())
        .outputKey("vote2")
        .build();

SentimentClassifier3 c3 = AgenticServices.agentBuilder(SentimentClassifier3.class)
        .chatModel(baseModel())
        .outputKey("vote3")
        .build();

SentimentVoter voter = AgenticServices.plannerBuilder(SentimentVoter.class)
        .subAgents(c1, c2, c3)
        .outputKey("classification")
        .planner(VotingPlanner::new)
        .build();

ResultWithAgenticScope<String> result = voter.classify(
"I absolutely love this product! It exceeded all my expectations.");用这一配置,三个分类器在同一个文本上被并行调用。每个把它的分类写进它自己的输出键(vote1、vote2、vote3),而 VotingPlanner 收集全部三个结果。由于默认构造函数使用 VotingStrategy.majority(),最常见的分类胜出。对上面这个明确积极的文本,三个智能体很可能都返回 POSITIVE,得到一个一致的结果。但即便在一个智能体持异见的模糊情形中,多数投票也能确保一个稳健的最终分类。
要使用一个不同的聚合策略,只需把它传给 VotingPlanner 构造函数:
java
.planner(() -> new VotingPlanner(VotingStrategy.average()))或提供一个完全自定义的策略:
java
.planner(() -> new VotingPlanner(votes ->
        votes.stream()
                .map(Object::toString)
                .map(String::toUpperCase)
                .collect(Collectors.groupingBy(Function.identity(), Collectors.counting()))
                .entrySet().stream()
                .max(Map.Entry.comparingByValue())
                .map(Map.Entry::getKey)
.orElse(null)))这个自定义策略在计数前把所有票归一为大写,处理智能体之间细微的格式差异(例如 "Positive" 与 "POSITIVE")。
辩论智能体模式
到目前为止讨论的模式,要么一次性分发智能体(投票),要么基于数据可用性来激活它们(黑板、P2P),要么朝一个目标排序它们(GOAP)。没有一个支持对抗式精炼——一个让智能体彼此看到对方推理、并迭代修订各自立场的过程。辩论模式填补了这一空白:智能体并行生成各自独立的答案,随后进入批评轮次,在那里它们能阅读完整的辩论历史并精炼自己的论点。轮次持续进行,直到智能体对同一答案收敛,或达到最大轮数,此时一个裁判(judge)智能体作出最终裁决。
这个模式对事实核查、风险评估、代码评审,以及任何让智能体接触相互竞争之论点能提升输出质量的领域尤其有用。通过迫使智能体直面并回应对方的推理,辩论模式能捕获任何单个智能体可能错过的issue,并通过对抗式审查过滤掉误报。
这个模式通过一个 DebatePlanner 实现,它把子智能体划分为辩手(除最后一个之外的所有)与一个裁判(最后注册的子智能体)。规划器用两个参数配置:maxRounds(默认 3)与一个 ConvergenceStrategy(默认 unanimous())。
在初始化期间,规划器校验至少注册了三个子智能体(两个辩手与一个裁判)并相应地拆分该列表。第一个动作在 AgenticScope 中预置一个空的 debateContext 键——这是必要的,因为辩手智能体通过 @V(DEBATE_CONTEXT_KEY) 引用这个键,没有它第一轮会以 MissingArgumentException 失败。随后它并行分发所有辩手。
随着每个辩手完成,nextAction 被调用(在框架的锁下串行化)。规划器把每个输出记录在一个以智能体名为键的 map 中,并返回 noOp() 直到所有辩手完成。一旦所有响应被收集,它检查两个条件:ConvergenceStrategy 是否报告已收敛,以及当前轮是否已达到 maxRounds。任一种情况下,规划器进入裁判阶段——它把辩论上下文格式化为 AgentName: "response" 条目(每行一个),写入 scope,并分发裁判智能体。当裁判完成,规划器返回 done() 并以裁判的输出作为最终结果。若既未收敛也未达轮数上限,规划器把当前辩论上下文写入 scope,递增轮计数器,并重新分发所有辩手进入又一个批评轮次,在那里它们能看到并回应彼此先前的论点。
ConvergenceStrategy 是一个函数式接口,只有一个方法 hasConverged(Collection<Object> positions)。提供两个内置策略:unanimous() 检查所有立场是否完全相等(适合像 APPROVE/REJECT 这样的标签式决策),而 unanimousLastWord() 从每个立场抽取最后一个词、归一为大写,并检查所有智能体是否以同一裁决结尾。对于更细腻的用例——比如语义相似度或基于阈值的 agreement——用户可以提供一个自定义策略作为 lambda。
来看这个模式实战,我们构建一个辩论小组,其中三位伦理辩手从不同哲学视角论证,而一位裁判把他们的论点综合成一个最终裁决:
java
public interface UtilitarianDebater {

    @UserMessage("""
            You are a utilitarian ethics debater. \
            Consider the following question and argue from a utilitarian perspective, maximizing overall well-being.
            If previous debate context is provided, consider the other debaters' arguments and refine your position.
            Keep your response to 2-3 sentences. End with a one-word verdict: AGREE or DISAGREE.
            Question: {{question}}
            Previous debate context: {{debateContext}}
            """)
    @Agent(value = "Argues from a utilitarian ethics perspective", name = "Utilitarian")
    String debate(@V("question") String question, @V(DEBATE_CONTEXT_KEY) String debateContext);
}

public interface DeontologicalDebater {

    @UserMessage("""
            You are a deontological ethics debater. \
            Consider the following question and argue based on moral rules, duties, and rights.
            If previous debate context is provided, consider the other debaters' arguments and refine your position.
            Keep your response to 2-3 sentences. End with a one-word verdict: AGREE or DISAGREE.
            Question: {{question}}
            Previous debate context: {{debateContext}}
            """)
    @Agent(value = "Argues from a deontological ethics perspective", name = "Deontologist")
    String debate(@V("question") String question, @V(DEBATE_CONTEXT_KEY) String debateContext);
}

public interface PragmatistDebater {

    @UserMessage("""
            You are a pragmatist debater. \
            Consider the following question and argue based on practical consequences and real-world outcomes.
            If previous debate context is provided, consider the other debaters' arguments and refine your position.
            Keep your response to 2-3 sentences. End with a one-word verdict: AGREE or DISAGREE.
            Question: {{question}}
            Previous debate context: {{debateContext}}
            """)
    @Agent(value = "Argues from a pragmatist perspective", name = "Pragmatist")
    String debate(@V("question") String question, @V(DEBATE_CONTEXT_KEY) String debateContext);
}

public interface EthicsJudge {

    @UserMessage("""
            You are an impartial ethics judge. \
            Review the debate context where multiple debaters have argued about a question from different perspectives.
            Synthesize their arguments and provide a balanced, well-reasoned final verdict in 3-4 sentences.
            Debate context: {{debateContext}}
            """)
    @Agent(value = "Renders a final verdict by synthesizing debate arguments", name = "Judge")
    String judge(@V("debateContext") String debateContext);
}每位辩手接收一个 question(原始输入,保持不变)与一个 debateContext(由规划器每轮用辩论历史更新)。@V(DEBATE_CONTEXT_KEY) 引用 DebatePlanner 的公开常量,而每个 @Agent 上显式的 name 控制智能体在辩论上下文中如何被标注。裁判只接收 debateContext,因为原始问题已内嵌在辩论交流中。请注意,每位辩手必须有一个不同的 outputKey,以防它们互相覆写。
顶层规划器接口与连线看起来像这样:
java
public interface EthicsPanel {

    @Agent
    String debate(@V("question") String question);
}

UtilitarianDebater d1 = AgenticServices.agentBuilder(UtilitarianDebater.class)
        .chatModel(baseModel())
        .outputKey("utilitarian")
        .build();

DeontologicalDebater d2 = AgenticServices.agentBuilder(DeontologicalDebater.class)
        .chatModel(baseModel())
        .outputKey("deontological")
        .build();

PragmatistDebater d3 = AgenticServices.agentBuilder(PragmatistDebater.class)
        .chatModel(baseModel())
        .outputKey("pragmatist")
        .build();

EthicsJudge judge = AgenticServices.agentBuilder(EthicsJudge.class)
        .chatModel(baseModel())
        .outputKey("verdict")
        .build();

EthicsPanel panel = AgenticServices.plannerBuilder(EthicsPanel.class)
        .subAgents(d1, d2, d3, judge)
        .outputKey("verdict")
        .planner(() -> new DebatePlanner(3))
        .build();

String result = panel.debate(
"Is it ethical to use AI-generated art in commercial products without crediting the AI tool?");辩手列在前面,而裁判总是最后一个子智能体。第 1 轮,三位辩手各自产生独立立场。第 2 轮,每位辩手看到其他人的论点,可以精炼、反驳或扩展自己的立场。无论辩手是否收敛、或达到最大轮数,裁判总是基于完整的辩论上下文作出最终裁决。
要定制收敛检查或轮数:
java
.planner(() -> new DebatePlanner(5)) // allow up to 5 roundsjava
.planner(() -> new DebatePlanner(positions ->
positions.stream().allMatch(p -> p.toString().contains("AGREE")))) // custom convergence信念-愿望-意图(BDI)智能体模式
信念-愿望-意图(BDI)模式建模了经典的 AI 概念:一个维护显式目标、评估当前哪些目标可达成、并在环境变化时反应式地在它们之间切换的智能体。实现该模式的规划器维护三种结构——信念(来自 AgenticScope 的当前世界状态)、愿望(一组带优先级的目标),以及意图(当前正在执行的、已承诺的计划)。在每一步,规划器检查是否有更高优先级的愿望变得可达成,若有,则丢弃当前意图并重新审议。这使得 BDI 天然适合那种必须平衡多个相互竞争的目标、且优先级可随时转变的动态环境。
一个 Desire 被定义为一个 record,结合了名称、优先级级别、一个可达成性谓词、一个满足性谓词,以及构成追求该愿望之意图的、有序的智能体类型列表:
java
public record Desire(String name, int priority,
                     Predicate<AgenticScope> achievable,
                     Predicate<AgenticScope> satisfied,
                     List<Class<?>> agentTypes) {

    public static Desire of(String name, int priority,
                            Predicate<AgenticScope> achievable,
                            Predicate<AgenticScope> satisfied,
                            Class<?>... agentTypes) {
        return new Desire(name, priority, achievable, satisfied, List.of(agentTypes));
    }

    public static Desire of(String name, int priority,
                            String achievableStateKey,
                            String satisfiedStateKey,
                            Class<?>... agentTypes) {
        return new Desire(name, priority,
                scope -> scope.hasState(achievableStateKey),
                scope -> scope.hasState(satisfiedStateKey),
                List.of(agentTypes));
    }
}实现该模式的 BDIPlanner 接收一组 Desire 实例并实现审议循环。在初始化期间,它按类型映射每个已注册的子智能体,从而愿望能按类引用智能体。当执行开始,规划器过滤所有愿望、找出当前可达成且尚未被满足的那些,选出优先级最高的一个(同优先级时,列表中先声明者胜出),并提交于它的意图,即由该愿望定义的那串有序智能体。在每一后续步,规划器运行三项检查:其一,满足性,若当前愿望现已满足,规划器重新审议以选出下一个愿望;其二,抢占,若由于信念变化(写入 AgenticScope 的新值)有一个严格更高优先级的愿望变得可达成,当前意图被挂起、由更高优先级的那个接管;其三,可行性,若当前愿望仍可达成且未满足,规划器推进到意图序列中的下一个智能体。当一个被抢占的愿望后来被重新选出时,它从中断处恢复而非重新开始,从而已完成的智能体不会被再次调用。
当所有愿望都被满足、或没有一个可达成时,执行成功终止。规划器在两种行为不当的情形抛出 IllegalStateException:若一个愿望的整个意图完成但该愿望仍未被满足(智能体没有写入满足性谓词所期望的那些键),或在仍有未满足愿望待处理时达到可配置的最大调用次数。
在崩溃恢复时,规划器从头重新审议:已满足的愿望被跳过,但被选中愿望的意图从其第一个智能体重新开始。崩溃前已完成的智能体会再次运行,因此意图中的智能体应当是幂等的。
为说明这个模式,考虑一个有五个 AI 智能体与一个非 AI 智能体的自主交易系统。MarketRecommendationAgent 返回一个 MarketRecommendation 枚举,且只有当推荐为 SELL 或 STRONG_SELL 时才触发对冲。HedgingStrategyDefaulter 是一个非 AI 智能体,它确保 hedgingStrategy 始终存在于 scope 中(当对冲被跳过时默认为 "None"),从而 RebalancingAgent 总能把它作为输入接收:
java
public enum MarketRecommendation {
    STRONG_BUY, BUY, HOLD, SELL, STRONG_SELL
}

public interface MarketAnalysisAgent {
    @UserMessage("Analyze the market data and portfolio. Market: {{marketData}} Portfolio: {{portfolio}}")
    @Agent(value = "Analyze market conditions", outputKey = "marketAnalysis")
    String analyzeMarket(@V("marketData") String marketData, @V("portfolio") String portfolio);
}

public interface MarketRecommendationAgent {
    @UserMessage("Based on the market analysis, provide a trading recommendation. Market analysis: {{marketAnalysis}}")
    @Agent(value = "Provide a trading recommendation", outputKey = "recommendation")
    MarketRecommendation recommend(@V("marketAnalysis") String marketAnalysis);
}

public static class HedgingStrategyDefaulter {
    @Agent(outputKey = "hedgingStrategy")
    public String defaultHedging(AgenticScope scope) {
        return scope.hasState("hedgingStrategy") ? (String) scope.readState("hedgingStrategy") : "None";
    }
}

public interface RebalancingAgent {
    @UserMessage("Suggest rebalancing based on: {{marketAnalysis}} Hedging strategy: {{hedgingStrategy}} Portfolio: {{portfolio}}")
    @Agent(value = "Rebalance portfolio", outputKey = "rebalancingPlan")
    String rebalance(@V("marketAnalysis") String marketAnalysis,
                     @V("hedgingStrategy") String hedgingStrategy,
                     @V("portfolio") String portfolio);
}

public interface HedgingAgent {
    @UserMessage("Recommend hedging strategies based on: {{marketAnalysis}}")
    @Agent(value = "Hedge against risks", outputKey = "hedgingStrategy")
    String hedge(@V("marketAnalysis") String marketAnalysis);
}

public interface LiquidityAgent {
    @UserMessage("Assess liquidity for portfolio: {{portfolio}}")
    @Agent(value = "Maintain liquidity", outputKey = "liquidityAssessment")
    String assessLiquidity(@V("portfolio") String portfolio);
}这些智能体被连线成一个基于 BDI 的交易系统,带有四个不同优先级的愿望。注意"hedge risks"这个愿望用一个基于谓词的可达成性检查来审视推荐值,而"rebalance portfolio"这个愿望在 RebalancingAgent 之前包含 HedgingStrategyDefaulter,以保证 hedgingStrategy 这个 scope 值存在:
java
TradingSystem tradingSystem = AgenticServices.plannerBuilder(TradingSystem.class)
        .subAgents(marketAnalysis, recommendation, new HedgingStrategyDefaulter(),
                   rebalancing, hedging, liquidity)
        .planner(() -> new BDIPlanner(List.of(
                Desire.of("analyze market", 1,
                        "marketData", "recommendation",
                        MarketAnalysisAgent.class, MarketRecommendationAgent.class),
                Desire.of("hedge risks", 2,
                        scope -> scope.hasState("recommendation")
                                && Set.of(MarketRecommendation.SELL, MarketRecommendation.STRONG_SELL)
                                    .contains(scope.readState("recommendation")),
                        scope -> scope.hasState("hedgingStrategy"),
                        HedgingAgent.class),
                Desire.of("rebalance portfolio", 1,
                        "recommendation", "rebalancingPlan",
                        HedgingStrategyDefaulter.class, RebalancingAgent.class),
                Desire.of("maintain liquidity", 1,
                        "portfolio", "liquidityAssessment",
                        LiquidityAgent.class)
        )))
.build();当用市场数据与投资组合状态被调用时,规划器的审议循环这样工作:"analyze market" 与 "maintain liquidity" 这两个愿望初始都可达成。一旦 MarketAnalysisAgent 与 MarketRecommendationAgent 完成,推荐值决定下一步。若推荐是 SELL 或 STRONG_SELL,"hedge risks" 愿望(优先级 2)变得可达成并抢占任何更低优先级的工作,导致规划器调用 HedgingAgent。对冲完成后,规划器重新审议:"rebalance portfolio" 愿望先运行 HedgingStrategyDefaulter(保留现有的对冲策略),随后运行 RebalancingAgent,它接收对冲策略作为输入。若推荐不是 SELL 或 STRONG_SELL,对冲被完全跳过,且 HedgingStrategyDefaulter 写入 "None",从而 RebalancingAgent 仍能继续。这种反应式、条件驱动的切换正是 BDI 的精髓——系统基于变化的信念调整其行为,而非遵循一个僵化的计划。
决策路由器智能体模式
NOTE
决策路由器基于实验性的 DecisionModel API,未来版本可能变化。
决策路由器由 langchain4j-agentic-patterns 模块提供,也需要一个决策模型集成,例如 langchain4j-typesafe。
前面讨论的条件工作流分两步把请求路由到正确的专家:一个基于 LLM 的 CategoryRouter 智能体把一个类别写进 AgenticScope,随后一个条件智能体针对该类别对每个专家评估一个谓词。这可行,但每次路由决策都要花一次完整的 LLM 调用、且其文本答案得被解析,它还需要一个枚举和一个谓词与专家们保持同步,并且它无法表达 LLM 对其选择有多确信。
决策模型更适合这类任务:它不生成文本,而是就一个输入回答带类型的问题,返回每个可能答案的概率。决策路由器模式用一个决策模型直接在其子智能体之间选择:每个子智能体是一个单选问题的一个选项,由其名称与描述来说明,决策模型返回最可能的那一个、连同每个子智能体的概率。可选地,带上一个激活阈值时,路由器改为询问每个子智能体是否应当处理该请求,并行调用所有概率达到阈值的子智能体,这在一个请求横跨多个领域时很有用。
实现这个模式的 DecisionRouterPlanner 用一个 DecisionModel 创建,并可选地带一个严格介于 0 与 1 之间的激活阈值。当它被初始化时,规划器把它的每个子智能体变成一个单选 ChoiceQuestion("Which agent is best suited to handle this request?")的一个选项,用子智能体的名作为选项名、其描述作为该选项适用时机的说明。带上激活阈值时,它改为为每个子智能体创建一个 YesNoQuestion,例如 "Should the agent 'medical' (A medical expert, answering questions about health, injuries and treatments) handle this request?",全部在同一次请求中提出。这意味着子智能体的描述是决策模型据以路由请求的东西,所以它们应当清楚地说明每个子智能体被期望处理哪些请求。问题的输入由路由器智能体自身的参数构成,从 AgenticScope 读取,所以路由器必须通过一个带类型的智能体接口来定义,且其子智能体必须有各不相同的名字。
当路由器被调用时,规划器在一次调用中向决策模型提出这些问题,随后从答案中选出要激活的子智能体。内部地,它的 firstAction 方法大致做如下事情:
java
DecisionResponse response = decide(planningContext.agenticScope());
activated = activationThreshold == null
        ? List.of(response.choice(QUESTION_NAME).value())
        : routes.keySet().stream()
                .filter(name -> response.yesNo(name).probability() >= activationThreshold)
.toList();没有激活阈值时,只调用最可能的那个子智能体,且 nextAction 方法把它的输出作为路由器的结果返回。带激活阈值时,所有"是"概率至少达到阈值的子智能体被并行调用,且 nextAction 方法收集它们的输出,从而路由器的结果是一个从每个被调用子智能体的名到其输出的 map,当没有子智能体达到阈值时它为空。
规划器还把被激活子智能体的名字、以及那些已完成者的输出,作为其执行状态保存。这样,当智能体系统在挂起之后(例如因为某个被激活的子智能体在等待人类)或崩溃之后被恢复时,路由器不会再次询问决策模型:它只调用那些尚未运行的、被激活的子智能体,且其结果仍包含中断前收集到的输出。
为给出一个实践示例,我们重新实现条件工作流一节的那个专家路由器。专家们是一样的,只是他们的描述现在说明了各自处理哪些请求:
java
public interface MedicalExpert {

    @UserMessage("""
        You are a medical expert.
        Analyze the following user request under a medical point of view and provide the best possible answer.
        The user request is {{request}}.
        """)
    @Agent(description = "A medical expert, answering questions about health, injuries and treatments",
            outputKey = "medicalResponse")
    String medical(@V("request") String request);
}以及相似的 LegalExpert("A legal expert, answering questions about laws, rights, contracts and lawsuits")与 TechnicalExpert("A technical expert, answering questions about computers, software and devices")智能体。不再需要 CategoryRouter 智能体与 RequestCategory 枚举了:ExpertRouterAgent 接口直接由一个 DecisionRouterPlanner 实现,用一个像 TypeSafe 这样的决策模型来配置:
java
DecisionModel decisionModel = TypeSafeDecisionModel.builder()
        .apiKey(System.getenv("TYPESAFE_API_KEY"))
        .modelName("jev-1.13.0")
        .build();

ExpertRouterAgent expertRouterAgent = AgenticServices.plannerBuilder(ExpertRouterAgent.class)
        .subAgents(medicalExpert, legalExpert, technicalExpert)
        .outputKey("response")
        .planner(() -> new DecisionRouterPlanner(decisionModel))
        .build();

String response = expertRouterAgent.ask("I broke my leg, what should I do?");这里决策模型接收输入 {"request": "I broke my leg, what should I do?"} 以及问题 "Which agent is best suited to handle this request?"(选项为 medical、legal 与 technical),并选出 medical,于是只有 MedicalExpert 被调用、并返回它的答案。
然而有些请求属于多个领域。要调用所有概率达到某个阈值的专家,请把阈值传给规划器,并让路由器返回一个 map,从每个被调用专家的名到其答案:
java
public interface MultiExpertRouterAgent {

    @Agent
    Map<String, String> ask(@V("request") String request);
}

MultiExpertRouterAgent multiExpertRouterAgent = AgenticServices.plannerBuilder(MultiExpertRouterAgent.class)
        .subAgents(medicalExpert, legalExpert, technicalExpert)
        .outputKey("responses")
        .planner(() -> new DecisionRouterPlanner(decisionModel, 0.5))
        .build();

Map<String, String> responses = multiExpertRouterAgent.ask(
        "I broke my leg in a car accident caused by another driver: " +
"how should I take care of my leg, and can I sue the driver for damages?");对这个请求,预期 MedicalExpert 与 LegalExpert 都会达到阈值,于是它们被并行调用,且返回的 map 在 medical 与 legal 键下包含它们的两个答案。当没有专家达到阈值时(例如一个要求巧克力蛋糕食谱的请求),它们都不被调用、返回的 map 为空。
请注意,每个子智能体获得它自己的概率,与其他无关:多个子智能体都能达到一个高阈值,且新增一个子智能体不会改变现有那些的概率。同样出于这个原因,一个描述非常宽泛的子智能体(比如一个回答任何问题的通用助手)往往会在大多数请求上被激活,所以用阈值时最好精确描述每个子智能体,并把空结果当作"没有子智能体相关"的情形处理。而且,不同模型对概率的校准方式不同,所以阈值应当在你自己的请求上调参,并在你更换决策模型或其版本时重新调参。
与任何别的智能体模式一样,决策路由器可以是更复杂智能体系统中的一个步骤。例如,被激活专家的答案可以由一个在序列中于路由器之后调用的 ResponseSynthesizer 智能体合并为一个:
java
public interface ResponseSynthesizer {

    @UserMessage("""
        Merge the answers that different experts gave to the same user request into a single answer.
        The user request is: {{request}}
        The answers of the experts, keyed by expert, are: {{responses}}
        """)
    @Agent(description = "Merges the answers of several experts into one", outputKey = "answer")
    String synthesize(@V("request") String request, @V("responses") Map<String, String> responses);
}

public interface ExpertPipeline {

    @Agent
    String process(@V("request") String request);
}

ResponseSynthesizer responseSynthesizer = AgenticServices.agentBuilder(ResponseSynthesizer.class)
        .chatModel(BASE_MODEL)
        .build();

ExpertPipeline pipeline = AgenticServices.sequenceBuilder(ExpertPipeline.class)
        .subAgents(multiExpertRouterAgent, responseSynthesizer)
        .outputKey("answer")
.build();同一个路由器也可以用声明式 API 来定义,通过一个带 @PlannerSupplier 注解的静态方法提供该规划器:
java
public interface DeclarativeExpertRouter {

    @PlannerAgent(
            outputKey = "response",
            subAgents = {MedicalExpert.class, LegalExpert.class, TechnicalExpert.class})
    String ask(@V("request") String request);

    @PlannerSupplier
    static Planner planner() {
        return new DecisionRouterPlanner(TypeSafeDecisionModel.builder()
                .apiKey(System.getenv("TYPESAFE_API_KEY"))
                .modelName("jev-1.13.0")
                .build());
    }
}其中专家们通过一个 @ChatModelSupplier 提供它们的聊天模型,如声明式 API一节所述。
最后请记住,路由器智能体的参数会原样发送给决策模型,所以它们可以是字符串、数字、布尔,或由这些构成的 map 与 list:任何其他类型的参数都会被决策模型拒绝并报错说明支持哪些类型。也请注意,路由决策跟随用户的输入,因此它不是一道授权边界:一个只能在某些条件下(例如仅由被授权用户)使用的子智能体,必须自己强制其访问检查。
非 AI 智能体
到目前为止讨论的所有智能体都是 AI 智能体,意味着它们基于 LLM、可被调用来执行需要自然语言理解与生成的任务。然而,langchain4j-agentic 模块也支持非 AI 智能体,它们可用于执行不需要自然语言处理的任务,例如调用一个 REST API 或执行一条命令。这些非 AI 智能体其实更像工具,但在此语境下把它们建模为智能体很方便,从而它们能像 AI 智能体一样被使用,并与它们混合以组成更强大、更完整的智能体系统。
例如,监督者示例中用到的 ExchangeAgent 大概被不当建模成了一个 AI 智能体,它本可以更好地定义为一个只是调用 REST API 来完成货币兑换的非 AI 智能体。
java
public class ExchangeOperator {

    @Agent(value = "A money exchanger that converts a given amount of money from the original to the target currency",
            outputKey = "exchange")
    public Double exchange(@V("originalCurrency") String originalCurrency, @V("amount") Double amount, @V("targetCurrency") String targetCurrency) {
        // invoke the REST API to perform the currency exchange
    }
}从而它能像提供给监督者的其他子智能体一样被使用。
java
WithdrawAgent withdrawAgent = AgenticServices
        .agentBuilder(WithdrawAgent.class)
        .chatModel(BASE_MODEL)
        .tools(bankTool)
        .build();
CreditAgent creditAgent = AgenticServices
        .agentBuilder(CreditAgent.class)
        .chatModel(BASE_MODEL)
        .tools(bankTool)
        .build();

SupervisorAgent bankSupervisor = AgenticServices
        .supervisorBuilder()
        .chatModel(PLANNER_MODEL)
        .subAgents(withdrawAgent, creditAgent, new ExchangeOperator())
.build();本质上,langchain4j-agentic 中的一个智能体可以是任何只带一个、且仅一个方法被 @Agent 注解的 Java 类。
当定义一个专门的类不实际时,例如因为智能体的逻辑只在运行时才可得,同样的非 AI 智能体也可以以编程方式创建。AgenticServices 的 nonAiAgentBuilder 工厂方法接收一个计算智能体结果的、关于 AgenticScope 的函数,并允许配置名称、描述、带类型的输入键与输出键(这些本会通过 @Agent 注解与方法参数来定义)。这样,上面的 ExchangeOperator 可以等价地定义为:
java
AgenticScopeFunction<Double> exchangeOperator = AgenticServices
        .nonAiAgentBuilder(agenticScope -> exchange(
                agenticScope.readState("originalCurrency", ""),
                agenticScope.readState("amount", 0.0),
                agenticScope.readState("targetCurrency", "")))
        .name("exchange")
        .description("A money exchanger that converts a given amount of money from the original to the target currency")
        .inputKeys(String.class, "originalCurrency", Double.class, "amount", String.class, "targetCurrency")
        .outputKey("exchange")
.build();然后把它传给监督者、替代那个 new ExchangeOperator() 实例。在调用该函数之前,被声明的输入会从 AgenticScope 中读取并转换为其声明的类型,从而例如一个由监督者生成为整数或字符串的 amount 能被安全地读为 Double,而一个缺失的输入会让调用以 MissingArgumentException 失败。builder 也允许把一个 TypedKey 设为输出键、智能体结果的 outputType(默认为 Object,因为该函数的泛型类型在运行时不可得)、智能体是否要 async 执行,以及一个用于其调用的 AgentListener。若未提供名称,该智能体被命名为 accept,取自包装该函数的 AgenticScopeFunction 的方法名。
最后,非 AI 智能体在对 AgenticScope 读取状态或对其执行小操作上也有用,因此 AgenticServices 提供一个 agentAction 工厂方法,从一个 Consumer<AgenticServices> 创建一个简单智能体。例如假设有一个 scorer 智能体把一个 score 作为 String 值产出,而后续一个 reviewer 智能体需要把一个 score 作为 double 来消费。这种情况下两个智能体会不兼容,但可以用一个 agentAction 把第一个的输出改写成第二个所要求的格式,重写 AgenticScope 的 score 状态,如下:
java
UntypedAgent editor = AgenticServices.sequenceBuilder()
        .subAgents(
                scorer,
                AgenticServices.agentAction(agenticScope -> agenticScope.writeState("score", Double.parseDouble(agenticScope.readState("score", "0.0")))),
                reviewer)
.build();人在回路
构建智能体系统时另一个常见需求是让人在回路中,允许系统在某些动作继续之前,向用户索取缺失的信息或批准。这种人在回路能力也可以被视作一个特殊的非 AI 智能体并据此实现。
java
public record HumanInTheLoop(Function<AgenticScope, ?> responseProvider) {

    @Agent("An agent that asks the user for missing information")
    public Object askUser(AgenticScope scope) {
        return responseProvider.apply(scope);
    }
}这个相当朴素、但也非常通用的实现,基于使用一个只接收当前 AgenticScope 作为输入的单函数,从它可以提取出用于提问的上下文,并返回应当提供给用户的响应。
langchain4j-agentic 模块开箱提供的 HumanInTheLoop 智能体,让你能连同智能体描述、以及用户响应将被写入的输出变量,一起定义这个函数。
例如,定义了这样一个 AstrologyAgent 之后:
java
public interface AstrologyAgent {
    @SystemMessage("""
        You are an astrologist that generates horoscopes based on the user's name and zodiac sign.
        """)
    @UserMessage("""
        Generate the horoscope for {{name}} who is a {{sign}}.
        """)
    @Agent("An astrologist that generates horoscopes based on the user's name and zodiac sign.")
    String horoscope(@V("name") String name, @V("sign") String sign);
}就可以创建一个顺序工作流,它同时用这个 AI 智能体与一个 HumanInTheLoop 智能体,在生成运势前先向用户询问其星座,把它的问题发送到控制台标准输出、并从标准输入读取用户的响应,如下:
java
HumanInTheLoop humanInTheLoop = AgenticServices.humanInTheLoopBuilder()
        .description("An agent that asks the zodiac sign of the user")
        .outputKey("sign")
        .responseProvider(scope -> {
            System.out.println("Hi " + scope.readState("name") + ", what is your sign?");
            System.out.print("> ");
            try {
                BufferedReader reader = new BufferedReader(new InputStreamReader(System.in));
                return reader.readLine();
            } catch (IOException e) {
                throw new RuntimeException("Failed to read input", e);
            }
        })
        .build();

AstrologyAgent astrologyAgent = AgenticServices.agentBuilder(AstrologyAgent.class)
        .chatModel(baseModel())
        .outputKey("horoscope")
        .build();

UntypedAgent horoscopeAgent = AgenticServices.sequenceBuilder()
        .subAgents(humanInTheLoop, astrologyAgent)
        .outputKey("horoscope")
.build();这样,若用户用一个像这样的请求调用 horoscopeAgent
java
horoscopeAgent.invoke(Map.of("name", "Mario"));该序列会先调用 HumanInTheLoop 智能体,向用户询问缺失的星座,产生如下输出:
Hi Mario, what is your sign?
>等待用户提供答案,随后它会用来调用 AstrologyAgent 并生成运势。
由于用户可能花一些时间才提供答案,把 HumanInTheLoop 智能体配置为一个异步智能体是可行、且实际是推荐的。这样,那些不需要用户输入的智能体能继续它们的执行,而智能体系统在等待用户提供答案。
记忆与上下文工程
到目前为止讨论的所有智能体都是无状态的,意味着它们不维护任何上下文或对先前交互的记忆。然而,与任何别的 AI 服务一样,可以给智能体提供一个 ChatMemory,让它们能跨多次调用维持上下文。
要为前面的 MedicalExpert 提供一个记忆,只需在其签名中添加一个带 @MemoryId 注解的字段。
java
public interface MedicalExpertWithMemory {

    @UserMessage("""
        You are a medical expert.
        Analyze the following user request under a medical point of view and provide the best possible answer.
        The user request is {{request}}.
        """)
    @Agent("A medical expert")
    String medical(@MemoryId String memoryId, @V("request") String request);
}并在构建该智能体时设置一个记忆提供者:
java
MedicalExpertWithMemory medicalExpert = AgenticServices
        .agentBuilder(MedicalExpertWithMemory.class)
        .chatModel(BASE_MODEL)
        .chatMemoryProvider(memoryId -> MessageWindowChatMemory.withMaxMessages(10))
        .outputKey("response")
.build();通常,这对单独使用的单个智能体足够了,但对参与某个智能体系统的智能体可能有限制。假设技术专家与法律专家也被提供了记忆,且 ExpertRouterAgent 也被重新定义为带有记忆:
java
public interface ExpertRouterAgentWithMemory {

    @Agent
    String ask(@MemoryId String memoryId, @V("request") String request);
}对这个智能体两次调用的序列
java
String response1 = expertRouterAgent.ask("1", "I broke my leg, what should I do?");

String legalResponse1 = expertRouterAgent.ask("1", "Should I sue my neighbor who caused this damage?");不会给出期望的结果,因为第二个问题会被路由到法律专家,而它此时是第一次被调用、对前一个问题没有记忆。
要解决这个问题,就必须向法律专家提供上下文、以及它被调用之前发生了什么,而这正是自动存储于 AgenticScope 中的信息能帮忙的又一个用例。
特别地,AgenticScope 会追踪所有智能体的调用序列,并能通过把这些调用串接进单个对话来产生一个上下文。这个上下文可以原样使用,或在需要时摘要为一个更短的版本,例如通过定义一个 ContextSummarizer 智能体。
java
public interface ContextSummarizer {

    @UserMessage("""
        Create a very short summary, 2 sentences at most, of the
        following conversation between an AI agent and a user.

        The user conversation is: '{{it}}'.
        """)
    String summarize(String conversation);
}使用这个智能体,法律专家可以被重新定义、并被提供先前对话的上下文摘要,从而它在回答新问题时能顾及之前的交互。
java
LegalExpertWithMemory legalExpert = AgenticServices
        .agentBuilder(LegalExpertWithMemory.class)
        .chatModel(BASE_MODEL)
        .chatMemoryProvider(memoryId -> MessageWindowChatMemory.withMaxMessages(10))
        .context(agenticScope -> contextSummarizer.summarize(agenticScope.contextAsConversation()))
        .outputKey("response")
.build();更一般地,提供给某个智能体的上下文可以是 AgenticScope 状态的任何函数。用这套设置,当被问及邻居是否应因其造成的损害而被起诉时,法律专家将能顾及与医疗专家的先前对话并给出一个更知情的答案。
内部地,智能体框架通过自动改写发给法律专家的用户消息来提供这个额外上下文,使它含有先前对话的摘要,所以这种情况下实际的用户消息会像这样:
"Considering this context \"The user asked about what to do after breaking their leg, and the AI provided medical advice on immediate actions like immobilizing the leg, applying ice, and seeking medical attention.\"
You are a legal expert.
Analyze the following user request under a legal point of view and provide the best possible answer.
The user request is Should I sue my neighbor who caused this damage?."这里作为某个智能体可能之上下文生成的示例所讨论的摘要上下文,具有普遍的用处,所以可以用一个更方便的方式在智能体上定义它,用 summarizedContext 方法,像:
java
LegalExpertWithMemory legalExpert = AgenticServices
        .agentBuilder(LegalExpertWithMemory.class)
        .chatModel(BASE_MODEL)
        .chatMemoryProvider(memoryId -> MessageWindowChatMemory.withMaxMessages(10))
        .summarizedContext("medical", "technical")
        .outputKey("response")
.build();这样做时,它内部使用前述的 ContextSummarizer 智能体,并用定义了它的那个智能体所用的同一聊天模型来执行它。也可以给这个方法附加一个可变参数,列出其上下文应当被摘要的那些智能体名,从而摘要只对那些智能体做、而非对智能体系统中使用的所有智能体做。
AgenticScope 注册表与持久化
AgenticScope 是一个临时数据结构,在智能体系统执行期间被创建与使用。每个用户的每个智能体系统只有一个 AgenticScope。对于无状态执行(不使用记忆时),AgenticScope 会在执行结束时被自动丢弃,其状态不会被持久化到任何地方。
反之,当智能体系统使用一个记忆时,AgenticScope 会被保存在一个内部注册表中。这种情况下 AgenticScope 会永久留在注册表中,以允许用户以有状态、对话的方式与智能体系统交互。因此,当一个带特定 ID 的 AgenticScope 不再需要时,必须显式地从注册表中淘汰它。为此,智能体系统的根智能体需要实现 AgenticScopeAccess 接口,从而可以在它上面调用 evictAgenticScope 方法,传入那个要从注册表移除的 AgenticScope 的 ID。
java
agent.evictAgenticScope(memoryId);AgenticScope 及其注册表都是纯内存数据结构。这对简单智能体系统通常足够,但某些情况下把 AgenticScope 状态持久化到更耐用的存储(如数据库或文件系统)会很有用。为达此目的,langchain4j-agentic 模块提供一个 SPI 来插入一个自定义持久层,它是 AgenticScopeStore 接口的一个实现。你可以以编程方式设置这个持久层:
java
AgenticScopePersister.setStore(new MyAgenticScopeStore());或使用标准的 Java 服务提供者接口,创建一个名为 META-INF/services/dev.langchain4j.agentic.scope.AgenticScopeStore 的文件,其中含实现 AgenticScopeStore 接口那个类的全限定名。
AgenticScope 的 JSON 序列化
LangChain4j 通过 AgenticScopeSerializer 类为 AgenticScope 提供内置的 JSON 序列化。出于安全考虑,反序列化使用一个白名单策略,限制哪些类能从 JSON 被反序列化。默认允许标准 JDK 类型(java.util.*、java.math.*、原始类型包装、枚举)以及 LangChain4j 内部类型(AgentMessage、AgentInvocation)。
若你的智能体把自定义领域对象存储在 AgenticScope 状态中,你必须在反序列化发生前注册它们。你可以注册单个类:
java
AgenticScopeSerializer.allowDeserializationType(LoanApplication.class);或整个包前缀:
java
AgenticScopeSerializer.allowDeserializationPackagePrefix("com.acme.myapp.");尝试反序列化一个未注册的类型,会抛出一个 UnserializableAgenticScopeException,其消息点名被拒绝的类并提示如何注册它。
AgenticScope 与智能体系统的可恢复性
当配置了一个 AgenticScopeStore 时,langchain4j-agentic 模块提供内置的可恢复性支持,让智能体系统在崩溃或进程重启后能从中断处恢复执行。这对包含人在回路步骤、可能被有意停止并稍后重启的长时运行智能体系统尤为宝贵。
可恢复性基于两个协同工作的机制:逐步检查点与规划器执行状态持久化。
在每次智能体调用之后,当前的 AgenticScope 会被自动检查点到所配置的存储。这意味着所有由智能体写入的中间状态(通过 writeState)都被持久地保存。此外,执行循环会保存规划器的内部位置(例如序列中已到达哪个智能体),从而在恢复时工作流从正确的步骤继续、而非从头重来。
Planner 接口的一个实现可以通过两个方法可选地参与这一机制:
java
// Returns the planner's current internal state for persistence
default Map<String, Object> executionState() { return Map.of(); }

// Restores internal state from a previously saved map
default void restoreExecutionState(Map<String, Object> state) { }例如,有状态的规划器(如顺序与循环那些)实现这些方法来保存并恢复它们游标位置与迭代计数器。无状态的规划器(如 ParallelPlanner 或 ConditionalPlanner)使用默认的空实现。自定义的 Planner 实现也可以覆盖这些方法来参与可恢复性。执行循环还会连同规划器状态追踪它自己的内部状态(例如并行块中哪些智能体已完成),从而在恢复时只重新分发那些尚未完成的智能体。
为给出一个它如何工作的实践示例,考虑一个订单处理工作流,其中一笔大额订单在履行前必须由人来审核。该工作流有三步:校验订单、等待人类批准、发运订单。
java
public interface OrderWorkflow extends AgenticScopeAccess {
    @Agent
    String processOrder(@MemoryId String orderId, @V("order") String orderDetails);
}@MemoryId 注解必不可少——它激活持久化 scope,而这是可恢复性所必需的。把该工作流构建为三个智能体的序列:
java
// Step 1: Validate the order and write results to shared state
AgenticScopeAction validateOrder = AgenticServices.agentAction(scope -> {
    String order = scope.readState("order", "");
    scope.writeState("validated_order", "VALIDATED: " + order);
});

// Step 2: Pause for human approval using SuspendedResponse
HumanInTheLoop approvalGate = AgenticServices.humanInTheLoopBuilder()
        .description("Wait for manager approval on large orders")
        .outputKey("approval")
        .responseProvider(scope -> new SuspendedResponse<>("manager-approval"))
        .build();

// Step 3: Finalize based on the approval decision
AgenticScopeAction shipOrder = AgenticServices.agentAction(scope -> {
    String validated = scope.readState("validated_order", "");
    String approval = scope.readState("approval", "");
    scope.writeState("result", "Order " + validated + " — " + approval);
});

OrderWorkflow workflow = AgenticServices.sequenceBuilder(OrderWorkflow.class)
        .subAgents(validateOrder, approvalGate, shipOrder)
        .outputKey("result")
.build();当这个工作流运行时,它先校验订单,随后到达 HumanInTheLoop 步骤。因为响应提供者返回一个 SuspendedResponse,智能体系统通过抛出一个 AgenticSystemSuspendedException 来挂起其执行,而非阻塞调用线程。完整的 scope——包括已校验的订单数据、规划器的游标位置(步骤 2 已完成)与那个 SuspendedResponse——被检查点到存储(若配置了一个),并向外抛出一个 AgenticSystemSuspendedException 以释放线程:
java
try {
    String result = workflow.processOrder("order-12345", "1000 widgets");
    // Workflow completed normally
} catch (AgenticSystemSuspendedException e) {
    // Workflow suspended — waiting for human input
    AgenticScope scope = e.scope();
    Set<String> pendingIds = scope.pendingResponseIds(); // → ["manager-approval"]
    // Store the scope/pendingIds for your UI / REST API to present to the human
}作为 SuspendedResponse 的替代,人在回路可以返回一个 PendingResponse 类的实例,以阻塞调用线程直到人类响应被提供。本质上:
| 响应类型 | 行为 |
|---|---|
SuspendedResponse | 挂起智能体系统:检查点保存 scope,抛出 AgenticSystemSuspendedException,并释放调用线程。系统通过在完成后重新调用智能体方法来恢复。 |
PendingResponse | 在底层 CompletableFuture 上阻塞调用线程,直到另一个线程调用 complete()。不抛异常——智能体系统原地等待。 |
用户可以在创建响应的那个点做这个选择——在 responseProvider lambda 或 @HumanInTheLoop 静态方法里:
java
// Suspension: the agentic system checkpoints and throws AgenticSystemSuspendedException
.responseProvider(scope -> new SuspendedResponse<>("approval-id"))

// Blocking: the calling thread waits until complete() is called from another thread
.responseProvider(scope -> new PendingResponse<>("approval-id"))对崩溃韧性很重要的长时交互(小时/天)建议使用 SuspendedResponse,而对由后台线程很快给出答案的短时进程内等待使用 PendingResponse。
若方法的返回类型是 ResultWithAgenticScope,挂起时不抛异常;相反,结果的 suspended() == true 且 result() == null。随后你可以在一次调用中完成那个待定响应并恢复执行:
java
ResultWithAgenticScope<String> result = workflow.processOrder("order-12345", "1000 widgets");
if (result.suspended()) {
    result = result.completePendingResponse("APPROVED by manager");
    // result.result() → "Order VALIDATED: 1000 widgets — APPROVED by manager"
}这对有多个串行 HITL 关卡的多步工作流天然适用——每次 completePendingResponse 调用都返回一个本身可能又被挂起的新 ResultWithAgenticScope:
java
ResultWithAgenticScope<String> result = workflow.processOrder("order-12345", "1000 widgets");

result = result.completePendingResponse("Manager OK");   // resumes, suspends at legal gate
result = result.completePendingResponse("Legal OK");      // resumes, completes
// result.result() → final outputResultWithAgenticScope 是处理挂起的推荐方式,因为它避免了用异常做控制流。
反之,若方法返回一个普通类型(例如 String)而非 ResultWithAgenticScope,系统在挂起时会抛出 AgenticSystemSuspendedException。那种情况下,或当你需要直接通过 scope 恢复时(例如崩溃/重启之后),你可以在 AgenticScope 上完成那个响应并重新调用智能体方法:
java
AgenticScope scope = workflow.getAgenticScope("order-12345");

// Complete the single deferred response (when there is exactly one)
scope.completePendingResponse("APPROVED by manager");

// Or complete by explicit ID (useful when multiple responses are pending)
scope.completePendingResponse("manager-approval", "APPROVED by manager");

// Then re-invoke — the planner resumes from the checkpoint
String result = workflow.processOrder("order-12345", "1000 widgets");请注意,completePendingResponse 既完成内存中的 future(解除任何等待线程的阻塞),也用解析后的值替换那个状态 map 条目(从而它能在序列化中存活)。单参数重载在恰好没有一个待定响应时抛出 IllegalStateException。
智能体注册表
langchain4j-agentic 模块为一个 AgentsRegistry 提供了一个 SPI(服务提供者接口),允许外部提供者注册那些可按名被发现、并被接入任何智能体模式的智能体。这对把外部系统提供的智能体(例如远程 A2A 协议智能体)集成进本地定义的智能体工作流尤其有用。
AgentsRegistry 接口定义了两个发现智能体的方法:
java
public interface AgentsRegistry {

    Map<String, AgentInstance> allAgents();

    AgentInstance getAgent(String name);

    static AgentsRegistry get() { ... }
}allAgents()返回一个以名称为键、含所有已注册智能体的 map。getAgent(String name)返回给定名字的智能体,若未找到则抛出一个RuntimeException。
静态 get() 方法用 Java 的 ServiceLoader 来发现注册表实现。支持多个提供者,它们会被自动合并为单个复合注册表;跨提供者的重名智能体会在发现时引发异常。若找不到任何提供者,会返回一个在任意查询时都抛空的注册表。
要提供一个注册表实现,创建一个实现 AgentsRegistry 接口的类,并通过标准 Java SPI 机制注册它——即创建一个 META-INF/services/dev.langchain4j.agentic.planner.AgentsRegistry 文件,其中含你实现类的全限定名。
java
public class MyAgentsRegistry implements AgentsRegistry {

    private final Map<String, AgentInstance> agents;

    public MyAgentsRegistry() {
        AgentInstance audienceEditor = (AgentInstance) AgenticServices
                .agentBuilder(AudienceEditor.class)
                .chatModel(myModel())
                .outputKey("story")
                .build();

        AgentInstance styleEditor = (AgentInstance) AgenticServices
                .agentBuilder(StyleEditor.class)
                .chatModel(myModel())
                .outputKey("story")
                .build();

        this.agents = Map.of(
                "audienceEditor", audienceEditor,
                "styleEditor", styleEditor);
    }

    @Override
    public Map<String, AgentInstance> allAgents() {
        return agents;
    }

    @Override
    public AgentInstance getAgent(String name) {
        AgentInstance agent = agents.get(name);
        if (agent == null) {
            throw new RuntimeException("No agent found with name: " + name);
        }
        return agent;
    }
}注册表所返回的智能体是标准的 AgentInstance 对象,通常用 AgenticServices.agentBuilder() 构建,所以它们已准备好可作为任何智能体模式中的子智能体使用。
一旦注册表经由 SPI 可用,就能在任何智能体模式中加载它们、并与本地定义的智能体混合:
java
AgentsRegistry registry = AgentsRegistry.get();

CreativeWriter creativeWriter = AgenticServices
        .agentBuilder(CreativeWriter.class)
        .chatModel(BASE_MODEL)
        .outputKey("story")
        .build();

AgentInstance audienceEditor = registry.getAgent("audienceEditor");
AgentInstance styleEditor = registry.getAgent("styleEditor");

UntypedAgent novelCreator = AgenticServices.sequenceBuilder()
        .subAgents(creativeWriter, audienceEditor, styleEditor)
        .outputKey("story")
        .build();

String story = (String) novelCreator.invoke(Map.of(
        "topic", "dragons and wizards",
        "style", "fantasy",
"audience", "young adults"));这里 CreativeWriter 在本地构建,而 AudienceEditor 与 StyleEditor 从注册表按名加载,并作为子智能体与本地定义的并列使用。
@RegistryAgent 注解允许在声明式 API 中从注册表加载智能体。要使用它,定义一个简单接口,其方法带 @RegistryAgent 注解,指定注册表中该智能体的名字:
java
public interface AudienceEditorFromRegistry {
    @RegistryAgent("audienceEditor")
    String editStory(@V("story") String story, @V("audience") String audience);
}

public interface StyleEditorFromRegistry {
    @RegistryAgent("styleEditor")
    String editStory(@V("story") String story, @V("style") String style);
}这些接口随后可以作为一个完全声明式智能体系统定义中的子智能体使用:
java
public interface DeclarativeStoryCreator {

    @SequenceAgent(outputKey = "story",
            subAgents = {CreativeWriter.class, AudienceEditorFromRegistry.class, StyleEditorFromRegistry.class})
    String write(@V("topic") String topic, @V("style") String style, @V("audience") String audience);

    @ChatModelSupplier
    static ChatModel chatModel() {
        return BASE_MODEL;
    }
}并照常用 AgenticServices.createAgenticSystem() 实例化:
java
DeclarativeStoryCreator storyCreator = AgenticServices.createAgenticSystem(DeclarativeStoryCreator.class);

String story = storyCreator.write("dragons and wizards", "fantasy", "young adults");当声明式系统遇到一个 @RegistryAgent 注解时,它会按名自动从注册表加载对应的智能体并接入该智能体系统。这允许在同一声明式工作流中混合本地定义的智能体(像带其 @ChatModelSupplier 的 CreativeWriter)与注册表提供的智能体。
A2A 集成
额外的 langchain4j-agentic-a2a 模块提供与 A2A 协议的无缝集成,让你能构建使用远程 A2A 服务器智能体、并最终把它们与其他本地定义智能体混合的智能体系统。
例如,若第一个示例中用到的 CreativeWriter 智能体被定义在一个远程 A2A 服务器上,你可以创建一个 A2ACreativeWriter 智能体,它能像本地智能体一样被使用,却调用远程的那个。
java
UntypedAgent creativeWriter = AgenticServices
        .a2aBuilder(A2A_SERVER_URL)
        .inputKeys("topic")
        .outputKey("story")
.build();关于智能体能力的描述会自动从 A2A 服务器提供的智能卡片(agent card)获取。不过该卡片不提供输入参数的名字,所以有必要用 inputKeys 方法显式指定它们。
或者,你可以为这个 A2A 智能体定义一个本地接口,像:
java
public interface A2ACreativeWriter {

    @Agent
    String generateStory(@V("topic") String topic);
}从而它能以更类型安全的方式被使用,且输入名会从方法参数自动派生。
java
A2ACreativeWriter creativeWriter = AgenticServices
        .a2aBuilder(A2A_SERVER_URL, A2ACreativeWriter.class)
        .outputKey("story")
.build();这个智能体随后能像本地智能体一样被使用、并与它们混合,无论是在定义工作流时,还是把它作为监督者的一个子智能体使用时。
远程 A2A 智能体必须返回一个 Task 类型。
与 A2A 服务器的多轮对话
A2A 协议通过在消息封套上的 contextId 与 taskId 字段支持多轮对话。一个 contextId 把相关任务分组为一个对话,而一个 taskId 引用该对话内的一个特定任务。省略时,A2A 服务器生成新值;当提供了 taskId 时,服务器会继续那个已存在的任务而非新建一个。
要在出站消息封套上传递这些字段,用 @A2AContextId 与 @A2ATaskId 注解方法参数。这些参数不作为消息内容发送——它们被设在消息封套上。
java
public interface ChatAgent {

    @A2AClientAgent(a2aServerUrl = "http://localhost:8080", outputKey = "response")
    String chat(@V("question") String question,
                @A2AContextId @V("contextId") String contextId,
                @A2ATaskId @V("taskId") String taskId);
}当 contextId 或 taskId 传入 null 时,该字段会从封套中省略、由服务器创建新值。
当 @A2AContextId 参数也有一个可识别的名字(可能通过 @V 注解配置)时,响应中服务器赋的值会自动被写回该名字下的 AgenticScope。这启用了多轮流程:第一次调用捕获上下文,后续调用继续同一对话——服务器保持上下文,并在其中为每次调用创建一个新任务。
taskId 遵循一条不同的规则:它只在远程任务于本次调用返回的那一刻仍未关闭时,才被写回 AgenticScope,否则该 scope 条目会被清除。一次调用通常在其任务到达终态后返回,而 A2A 服务器会拒绝任何再发给该任务的消息,所以在常见情况下什么都不被传播,下一次调用会启动一个新任务。唯一的例外是一个流式客户端监听器提前停止消费流:远程任务仍在运行,且它的标识被保留在 scope 中,从而它仍可被轮询、取消或继续。
在该情况之外,taskId 取自调用参数:传 null(或省略该参数)以让服务器创建新任务,或传一个已存在任务的标识来继续它。
若方法返回 ResultWithAgenticScope,上下文可直接访问:
java
public interface ChatAgent {

    @A2AClientAgent(a2aServerUrl = "http://localhost:8080", outputKey = "response")
    ResultWithAgenticScope<String> chat(
            @V("question") String question,
            @A2AContextId @V("contextId") String contextId,
            @A2ATaskId @V("taskId") String taskId);
}

// First turn — server generates contextId and taskId
ResultWithAgenticScope<String> first = chatAgent.chat("hello", null, null);
String contextId = (String) first.agenticScope().readState("contextId");

// Second turn — reuse the server-generated context to continue the conversation,
// while letting the server create a new task for this invocation
ResultWithAgenticScope<String> second = chatAgent.chat("follow-up", contextId, null);这样,当某个 A2A 智能体被用在智能体系统里时,contextId 会通过共享的 AgenticScope 自动传播。这意味着对同一服务器的两次 A2A 调用序列,会自然地构成一次多轮对话:
java
public interface EchoSubAgent {

    @A2AClientAgent(a2aServerUrl = "http://localhost:8080", outputKey = "response")
    String echo(@V("question") String question,
                @A2AContextId @V("contextId") String contextId,
                @A2ATaskId @V("taskId") String taskId);
}

public interface MultiTurnWorkflow extends AgenticScopeAccess {

    @Agent
    ResultWithAgenticScope<String> converse(@V("question") String question);
}

EchoSubAgent firstTurn = AgenticServices
        .a2aBuilder("http://localhost:8080", EchoSubAgent.class)
        .outputKey("firstResponse").build();
EchoSubAgent secondTurn = AgenticServices
        .a2aBuilder("http://localhost:8080", EchoSubAgent.class)
        .outputKey("secondResponse").build();

MultiTurnWorkflow workflow = AgenticServices.sequenceBuilder(MultiTurnWorkflow.class)
        .subAgents(firstTurn, secondTurn)
        .outputKey("secondResponse").build();

ResultWithAgenticScope<String> result = workflow.converse("hello");在这个序列里,第一个智能体发出一条不带 contextId/taskId 的消息(它们在 scope 中为 null)。服务器创建一个新上下文与一个新任务,随后 contextId 被写入 scope。当第二个智能体运行时,它从 scope 读取已填充的 contextId 并设在消息封套上发出,于是对话得以继续。由于第一个智能体完成的那个任务无法再接受消息,taskId 在 scope 中保持未设,服务器会在同一上下文中创建一个新任务。
多租户 A2A 智能体
在多租户 A2A 部署中,消息必须被限定到某个特定租户,好让服务器能施加正确的路由、隔离与策略。langchain4j-agentic-a2a 模块支持三种配置租户的方式,取决于它是固定的、动态的,还是从服务器 URL 自动派生的。
从智能卡片 URL 自动检测
当未配置任何租户时,客户端会自动从智能卡片 URL 提取它。一个多租户 A2A 服务器通常遵循 /.well-known/{tenant}/agent-card.json 约定。若智能卡片 URL 匹配此模式,被提取的租户会被静默地应用于每条出站消息——无需任何配置。
通过 @A2AClientAgent 注解设置静态租户
当租户在构建时已知、且对每次调用都相同时,直接在 @A2AClientAgent 注解上设置 tenant 属性:
java
public interface MyA2AAgent {

    @A2AClientAgent(a2aServerUrl = "http://localhost:8080", tenant = "acme", outputKey = "response")
    String chat(@V("question") String question);
}租户会被设在该智能体发送的每条消息的 MessageSendParams 上——无需方法参数。它不作为一个 TextPart 被含进消息内容。在注解中设置 tenant 优先于从智能卡片 URL 的自动检测。
以编程方式构建时,把租户作为 a2aBuilder 的第二个参数传入:
java
UntypedAgent agent = AgenticServices
        .a2aBuilder("http://localhost:8080", "acme")
        .inputKeys("question")
        .outputKey("response")
        .build();

// Or with a typed interface:
MyA2AAgent agent = AgenticServices
        .a2aBuilder("http://localhost:8080", "acme", MyA2AAgent.class)
        .outputKey("response")
.build();通过 @A2ATenantId 设置动态租户
当租户逐调用变化时,用一个方法参数带 @A2ATenantId 注解。该参数值被设为出站 MessageSendParams 上的 tenant 字段——它不作为一个 TextPart 被含进消息内容。
java
public interface MyA2AAgent {

    @A2AClientAgent(a2aServerUrl = "http://localhost:8080", outputKey = "response")
    String chat(@V("question") String question,
                @A2AContextId String contextId,
                @A2ATenantId String tenant);
}当 tenant 传入 null 或空字符串时,该字段会从 MessageSendParams 中省略,由服务器施加它默认的租户解析。
@A2ATenantId 可以与 @A2AContextId 与 @A2ATaskId 自由组合:
java
public interface MultiTenantChatAgent {

    @A2AClientAgent(a2aServerUrl = "http://localhost:8080", outputKey = "response")
    String chat(@V("question") String question,
                @A2AContextId @V("contextId") String contextId,
                @A2ATaskId   @V("taskId")    String taskId,
                @A2ATenantId                 String tenant);
}与 @A2AContextId、@A2ATaskId 不同,租户值从不被写回 AgenticScope——由调用方负责在每次调用时提供它。
小结:租户解析顺序
| 方式 | 何时使用 |
|---|---|
| 从智能卡片 URL 自动检测 | 服务器 URL 遵循 /.well-known/{tenant}/agent-card.json 且租户恒定 |
@A2AClientAgent(或 a2aBuilder(url, tenant, ...))上的 tenant | 租户固定且在构建时已知 |
@A2ATenantId 方法参数 | 租户逐调用变化 |
人在回路的 A2A 智能体
一个 A2A 服务器可以把任务暂停在 input-required 或 auth-required 状态。当这发生在某个智能体系统内部时,A2A 客户端会在 AgenticScope 中存储一个 SuspendedResponse、检查工作流并释放调用线程。这次中断含有继续同一远程任务所必需的任务与上下文 ID。
调用方可以把这些细节发布到一个外部系统,例如一个 Kafka 主题:
java
try {
    workflow.invoke("request-123", "Book the trip");
} catch (AgenticSystemSuspendedException e) {
    AgenticScope scope = e.scope();
    String responseId = scope.pendingResponseIds().iterator().next();
    A2ATaskInterruptedException interruption = A2ATaskInterruptedException.from(scope, responseId);

    inputRequests.publish(new InputRequest(
            scope.memoryId(), responseId, interruption.taskId(),
            interruption.contextId(), interruption.reason()));
}当人类响应稍后到达时,完成那个待定响应并再次调用工作流。规划器从其检查点恢复,而 A2A 客户端会带着所存储的 contextId 与 taskId 发出该响应,而非启动一个新任务:
java
void onInputResponse(InputResponse response) {
    AgenticScope scope = workflow.getAgenticScope(response.memoryId());
    scope.completePendingResponse(response.responseId(), response.text());
    workflow.invoke(response.memoryId(), "Book the trip");
}completePendingResponse(...) 会在被挂起的 scope 中记录人类的回答,但它本身不会重启工作流。下一次调用仍是对原始请求所用的同一个 workflow.invoke(...) 方法,带同样的记忆 ID 与原始参数。记忆 ID 会恢复已保存的规划器检查点;当执行到达 A2A 客户端时,它会带着所存储的 contextId 与 taskId 发出那个已完成的响应,从而继续那个已存在的远程任务。
若某个 A2A 客户端是在智能体系统之外被调用的,就没有可供挂起的 scope。那种情况下,它直接抛出 A2ATaskInterruptedException,让调用方能手动处理这次中断。
定制 A2A 客户端
默认情况下,A2A 智能体使用一个带默认配置的 JSONRPC 传输。clientCustomizer 方法暴露底层的 a2a-java SDK ClientBuilder,让你能配置一个不同的传输、设置自定义 HTTP 客户端、添加拦截器,或更改任何其他客户端设置。
在以编程方式构建一个 A2A 智能体时,把一个 Consumer<ClientBuilder> 传给 clientCustomizer:
java
UntypedAgent creativeWriter = AgenticServices
        .a2aBuilder(A2A_SERVER_URL)
        .clientCustomizer((ClientBuilder cb) ->
                cb.withTransport(JSONRPCTransport.class, new JSONRPCTransportConfigBuilder()))
        .inputKeys("topic")
        .outputKey("story")
.build();当提供了一个定制器时,它会完全替换默认的传输设置,把对 Client 如何构建的完全控制权交给你。
对于声明式智能体,用一个 @A2AClientCustomizer 注解某个静态方法。该方法必须接受单个 ClientBuilder 参数并返回 void:
java
public interface DeclarativeA2AWithCustomizer {

    @A2AClientAgent(a2aServerUrl = "http://localhost:8080", outputKey = "story")
    String generateStory(@V("topic") String topic);

    @A2AClientCustomizer
    static void customizer(ClientBuilder cb) {
        cb.withTransport(JSONRPCTransport.class, new JSONRPCTransportConfigBuilder());
    }
}流式 A2A 客户端监听器
当启用流式调用一个远程 A2A 智能体时,你可以用 A2AStreamingClientListener 来观察从远程智能体收到的事件,并控制客户端应当何时停止消费流。
当你只需对特定事件作出反应、而非等待远程任务完成时,这很有用。例如,你可以在远程智能体请求额外输入时停止监听,并立即把该消息返回给调用方。
java
UntypedAgent creativeWriter = AgenticServices.a2aBuilder(A2A_SERVER_URL)
        .inputKeys("topic")
        .outputKey("story")
        .streamingClientListener((TaskUpdateEvent event) -> {
            UpdateEvent updateEvent = event.getUpdateEvent();
            if (updateEvent instanceof TaskStatusUpdateEvent taskStatusUpdateEvent
                    && taskStatusUpdateEvent.status().state() == TaskState.TASK_STATE_WORKING) {
                return A2AStreamingClientListenerResult.stopWithResponse(
                        "stop when status update to TASK_STATE_WORKING, and return this message to the caller");
            }
            return A2AStreamingClientListenerResult.continueStreaming();
        })
.build();该监听器会为从远程 A2A 智能体收到的每个事件被调用。返回 continueStreaming() 以继续消费事件,stopWithResponse(response) 以停止消费流并把指定响应返回给调用方,或 stopWithCurrentArtifacts() 以停止消费流并返回迄今收到的工件(artifacts),使用 A2A 客户端默认的工件到文本抽取逻辑。
停止客户端侧的流不会取消远程 A2A 任务。远程任务可能继续异步执行。由于本次调用返回时那个任务仍未关闭,它的标识会被在该智能体所声明(若有)的 @A2ATaskId 参数名下写回 AgenticScope,从而调用方能轮询、取消或继续它。这正是 taskId 通过 scope 被传播的唯一情形,如与 A2A 服务器的多轮对话一节所解释。
动态配置 A2A 服务器 URL
默认情况下,@A2AClientAgent 注解通过 a2aServerUrl 属性要求把 A2A 服务器 URL 作为一个编译期字符串字面量。对于 URL 会变化(例如 dev、staging、production)的环境,一个带 @A2AServerUrlSupplier 注解的静态方法可以在构建时动态提供该 URL:
java
public interface DeclarativeA2AWithUrlSupplier {

    @A2AClientAgent(outputKey = "story")
    String generateStory(@V("topic") String topic);

    @A2AServerUrlSupplier
    static String serverUrl() {
        return System.getenv("A2A_SERVER_URL");
    }
}该提供者方法必须是 static、不带参数、返回一个 String。它在智能体被构造时被调用一次——URL 在各次调用之间不变。a2aServerUrl(在注解中)与一个 @A2AServerUrlSupplier 方法二者必须恰好提供其一;两者都给或都不给都是错误。
这个模式与 @McpClientSupplier 如何为 @McpClientAgent 声明式智能体提供 MCP 客户端保持一致。
基于 MCP 的工具智能体
额外的 langchain4j-agentic-mcp 模块允许把一个单个 MCP 工具包装为智能体系统中的一个非 AI 智能体。与使用 LLM 的常规智能体不同,一个 MCP 工具智能体只是直接执行那个 MCP 工具并返回其结果。这使得把 MCP 工具与更大智能体系统中的其他智能体组合起来成为可能,而工具执行本身不涉及任何 LLM。
要创建一个 MCP 工具智能体,使用 McpAgent.builder() 并提供一个 McpClient 实例。builder 会向 MCP 服务器查询工具规范(名称、描述、输入 schema),并创建一个把调用转发给那个工具的智能体。
例如,若某个 MCP 服务器暴露一个 generate_story 工具,它可以被包装为一个无类型智能体:
java
McpClient mcpClient = new DefaultMcpClient.Builder()
        .transport(myMcpTransport)
        .build();

UntypedAgent storyGenerator = McpAgent.builder(mcpClient)
        .toolName("generate_story")
        .inputKeys("topic")
        .outputKey("story")
        .build();

String story = (String) storyGenerator.invoke(Map.of("topic", "dragons and wizards"));toolName 指定当 MCP 服务器暴露多个工具时应绑定哪个工具。若服务器只暴露一个工具,toolName 可以省略,那个唯一可用的工具会被自动选中。inputKeys 指定该工具输入参数的名字;对于无类型智能体,若未显式提供,它们也会从工具的 JSON schema 自动派生。
与其他智能体一样,MCP 工具智能体也可以用一个带类型的接口来创建:
java
public interface StoryGenerator {

    @Agent
    String generateStory(@V("topic") String topic);
}

StoryGenerator storyGenerator = McpAgent.builder(mcpClient, StoryGenerator.class)
        .toolName("generate_story")
        .outputKey("story")
        .build();

String story = storyGenerator.generateStory("dragons and wizards");这种情况下,输入参数名从方法参数(或它们的 @V 注解)派生,而返回类型决定工具的文本结果如何被解析。
最后,MCP 工具智能体也可以用 @McpClientAgent 注解以声明方式定义。@McpClientSupplier 注解标记一个提供 McpClient 实例的静态方法。
java
public interface DeclarativeMcpStoryGenerator {

    @McpClientAgent(toolName = "generate_story", outputKey = "story",
            description = "Generates a story based on the given topic")
    String generateStory(@V("topic") String topic);

    @McpClientSupplier
    static McpClient mcpClient() {
        McpTransport transport = new StreamableHttpMcpTransport.Builder()
                .url("http://localhost:8081/mcp")
                .build();
        return new DefaultMcpClient.Builder()
                .transport(transport)
                .build();
    }
}