
主题
记忆
AI 应用需要记忆来在多次交互之间共享上下文。在 LangGraph 中,你可以添加两种类型的记忆:
添加短期记忆
短期记忆(线程级持久化)使智能体能够跟踪多轮对话。要添加短期记忆:
python
from langgraph.checkpoint.memory import InMemorySaver
from langgraph.graph import StateGraph

checkpointer = InMemorySaver()

builder = StateGraph(...)
graph = builder.compile(checkpointer=checkpointer)

graph.invoke(
    {"messages": [{"role": "user", "content": "hi! i am Bob"}]},
    {"configurable": {"thread_id": "1"}},
)在生产环境中使用
在生产环境中,请使用由数据库支持的检查点器:
python
from langgraph.checkpoint.postgres import PostgresSaver

DB_URI = "postgresql://postgres:postgres@localhost:5432/postgres?sslmode=disable"
with PostgresSaver.from_conn_string(DB_URI) as checkpointer:
    builder = StateGraph(...)
graph = builder.compile(checkpointer=checkpointer) 示例:使用 Postgres 检查点器
pip install -U "psycopg[binary,pool]" langgraph langgraph-checkpoint-postgresTIP
首次使用 Postgres 检查点器时,你需要调用 checkpointer.setup()
python
from langchain.chat_models import init_chat_model
from langgraph.graph import StateGraph, MessagesState, START
from langgraph.checkpoint.postgres import PostgresSaver

model = init_chat_model(model="claude-haiku-4-5-20251001")

DB_URI = "postgresql://postgres:postgres@localhost:5432/postgres?sslmode=disable"
with PostgresSaver.from_conn_string(DB_URI) as checkpointer:
    # checkpointer.setup()

    def call_model(state: MessagesState):
        response = model.invoke(state["messages"])
        return {"messages": response}

    builder = StateGraph(MessagesState)
    builder.add_node(call_model)
    builder.add_edge(START, "call_model")

    graph = builder.compile(checkpointer=checkpointer)

    config = {
        "configurable": {
            "thread_id": "1"
        }
    }

    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "hi! I'm bob"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
        print(snapshot)

    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "what's my name?"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
print(snapshot)示例:使用 MongoDB 检查点器
pip install -U pymongo langgraph langgraph-checkpoint-mongodbTIP
环境准备 要使用 MongoDB 检查点器,你需要一个 MongoDB 集群。如果还没有,请按照本指南创建一个集群。如需面向智能体的完整演示,请参阅使用 MongoDB Atlas 的短期记忆。
python
from langchain.chat_models import init_chat_model
from langgraph.graph import StateGraph, MessagesState, START
from langgraph.checkpoint.mongodb import MongoDBSaver

model = init_chat_model(model="claude-haiku-4-5-20251001")

MONGODB_URI = "localhost:27017"
with MongoDBSaver.from_conn_string(MONGODB_URI) as checkpointer:

    def call_model(state: MessagesState):
        response = model.invoke(state["messages"])
        return {"messages": response}

    builder = StateGraph(MessagesState)
    builder.add_node(call_model)
    builder.add_edge(START, "call_model")

    graph = builder.compile(checkpointer=checkpointer)

    config = {
        "configurable": {
            "thread_id": "1"
        }
    }

    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "hi! I'm bob"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
        print(snapshot)

    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "what's my name?"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
print(snapshot)示例:使用 Redis 检查点器
pip install -U langgraph langgraph-checkpoint-redisTIP
首次使用 Redis 检查点器时,你需要调用 checkpointer.setup()。
python
from langchain.chat_models import init_chat_model
from langgraph.graph import StateGraph, MessagesState, START
from langgraph.checkpoint.redis import RedisSaver

model = init_chat_model(model="claude-haiku-4-5-20251001")

DB_URI = "redis://localhost:6379"
with RedisSaver.from_conn_string(DB_URI) as checkpointer:
    # checkpointer.setup()

    def call_model(state: MessagesState):
        response = model.invoke(state["messages"])
        return {"messages": response}

    builder = StateGraph(MessagesState)
    builder.add_node(call_model)
    builder.add_edge(START, "call_model")

    graph = builder.compile(checkpointer=checkpointer)

    config = {
        "configurable": {
            "thread_id": "1"
        }
    }

    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "hi! I'm bob"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
        print(snapshot)

    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "what's my name?"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
print(snapshot)示例:使用 Oracle 检查点器
pip install -U langgraph langgraph-oracledbNOTE
环境准备 要使用 Oracle 检查点器,你需要一个 Oracle AI Database 实例。本地容器(例如 gvenzl/oracle-free:23-slim)或 OCI 中的 Oracle Autonomous Database 都可以。
TIP
首次使用 Oracle 检查点器时,你需要调用 checkpointer.setup()。
python
from langchain.chat_models import init_chat_model
from langgraph.graph import StateGraph, MessagesState, START
from langgraph_oracledb.checkpoint.oracle import OracleSaver

model = init_chat_model(model="claude-haiku-4-5-20251001")

DB_URI = "user/password@localhost:1521/FREEPDB1"
with OracleSaver.from_conn_string(DB_URI) as checkpointer:
    # checkpointer.setup()

    def call_model(state: MessagesState):
        response = model.invoke(state["messages"])
        return {"messages": response}

    builder = StateGraph(MessagesState)
    builder.add_node(call_model)
    builder.add_edge(START, "call_model")

    graph = builder.compile(checkpointer=checkpointer)

    config = {
        "configurable": {
            "thread_id": "1"
        }
    }

    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "hi! I'm bob"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
        print(snapshot)

    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "what's my name?"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
print(snapshot)在子图中使用
如果你的图中包含子图,你只需在编译父图时提供检查点器。LangGraph 会自动将检查点器传播到子图中。
python
from langgraph.graph import START, StateGraph
from langgraph.checkpoint.memory import InMemorySaver
from typing import TypedDict

class State(TypedDict):
    foo: str

# Subgraph

def subgraph_node_1(state: State):
    return {"foo": state["foo"] + "bar"}

subgraph_builder = StateGraph(State)
subgraph_builder.add_node(subgraph_node_1)
subgraph_builder.add_edge(START, "subgraph_node_1")
subgraph = subgraph_builder.compile()

# Parent graph

builder = StateGraph(State)
builder.add_node("node_1", subgraph)
builder.add_edge(START, "node_1")

checkpointer = InMemorySaver()
graph = builder.compile(checkpointer=checkpointer) 你可以配置子图特定的检查点行为。有关持久化级别(包括中断支持和有状态续接)的详细信息,请参阅子图持久化。
python
subgraph_builder = StateGraph(...)
subgraph = subgraph_builder.compile(checkpointer=True) 添加长期记忆
使用长期记忆在不同对话之间存储用户特定或应用特定的数据。
python
from langgraph.store.memory import InMemoryStore
from langgraph.graph import StateGraph

store = InMemoryStore()

builder = StateGraph(...)
graph = builder.compile(store=store) 在节点内访问 store
当你编译一个带有 store 的图后,LangGraph 会自动将 store 注入到你的节点函数中。访问 store 的推荐方式是通过 Runtime 对象。
python
from dataclasses import dataclass
from langgraph.runtime import Runtime
from langgraph.graph import StateGraph, MessagesState, START
import uuid

@dataclass
class Context:
    user_id: str

async def call_model(state: MessagesState, runtime: Runtime[Context]):
    user_id = runtime.context.user_id
    namespace = (user_id, "memories")

    # Search for relevant memories
    memories = await runtime.store.asearch(
        namespace, query=state["messages"][-1].content, limit=3
    )
    info = "\n".join([d.value["data"] for d in memories])

    # ... Use memories in model call

    # Store a new memory
    await runtime.store.aput(
        namespace, str(uuid.uuid4()), {"data": "User prefers dark mode"}
    )

builder = StateGraph(MessagesState, context_schema=Context)
builder.add_node(call_model)
builder.add_edge(START, "call_model")
graph = builder.compile(store=store)

# Pass context at invocation time
graph.invoke(
    {"messages": [{"role": "user", "content": "hi"}]},
    {"configurable": {"thread_id": "1"}},
    context=Context(user_id="1"),
)在生产环境中使用
在生产环境中,请使用由数据库支持的 store:
python
from langgraph.store.postgres import PostgresStore

DB_URI = "postgresql://postgres:postgres@localhost:5432/postgres?sslmode=disable"
with PostgresStore.from_conn_string(DB_URI) as store:
    builder = StateGraph(...)
graph = builder.compile(store=store) 示例:使用 Postgres store
pip install -U "psycopg[binary,pool]" langgraph langgraph-checkpoint-postgresTIP
首次使用 Postgres store 时,你需要调用 store.setup()
python
from dataclasses import dataclass
from langchain.chat_models import init_chat_model
from langgraph.graph import StateGraph, MessagesState, START
from langgraph.checkpoint.postgres.aio import AsyncPostgresSaver
from langgraph.store.postgres.aio import AsyncPostgresStore
from langgraph.runtime import Runtime
import uuid

model = init_chat_model(model="claude-haiku-4-5-20251001")

@dataclass
class Context:
    user_id: str

async def call_model(
    state: MessagesState,
    runtime: Runtime[Context],
):
    user_id = runtime.context.user_id
    namespace = ("memories", user_id)
    memories = await runtime.store.asearch(namespace, query=str(state["messages"][-1].content))
    info = "\n".join([d.value["data"] for d in memories])
    system_msg = f"You are a helpful assistant talking to the user. User info: {info}"

    # Store new memories if the user asks the model to remember
    last_message = state["messages"][-1]
    if "remember" in last_message.content.lower():
        memory = "User name is Bob"
        await runtime.store.aput(namespace, str(uuid.uuid4()), {"data": memory})

    response = await model.ainvoke(
        [{"role": "system", "content": system_msg}] + state["messages"]
    )
    return {"messages": response}

DB_URI = "postgresql://postgres:postgres@localhost:5432/postgres?sslmode=disable"

async with (
    AsyncPostgresStore.from_conn_string(DB_URI) as store,
    AsyncPostgresSaver.from_conn_string(DB_URI) as checkpointer,
):
    # await store.setup()
    # await checkpointer.setup()

    builder = StateGraph(MessagesState, context_schema=Context)
    builder.add_node(call_model)
    builder.add_edge(START, "call_model")

    graph = builder.compile(
        checkpointer=checkpointer,
        store=store,
    )

    config = {"configurable": {"thread_id": "1"}}
    stream = await graph.astream_events(
        {"messages": [{"role": "user", "content": "Hi! Remember: my name is Bob"}]},
        config,
        version="v3",
        context=Context(user_id="1"),
    )
    async for message in stream.messages:
        async for token in message.text:
            print(token, end="", flush=True)

    config = {"configurable": {"thread_id": "2"}}
    stream = await graph.astream_events(
        {"messages": [{"role": "user", "content": "what is my name?"}]},
        config,
        version="v3",
        context=Context(user_id="1"),
    )
    async for message in stream.messages:
        async for token in message.text:
print(token, end="", flush=True)示例:使用 MongoDB store
示例:使用 Redis store
pip install -U langgraph langgraph-checkpoint-redisTIP
首次使用 Redis store 时,你需要调用 store.setup()。
python
from dataclasses import dataclass
from langchain.chat_models import init_chat_model
from langgraph.graph import StateGraph, MessagesState, START
from langgraph.checkpoint.redis.aio import AsyncRedisSaver
from langgraph.store.redis.aio import AsyncRedisStore
from langgraph.runtime import Runtime
import uuid

model = init_chat_model(model="claude-haiku-4-5-20251001")

@dataclass
class Context:
    user_id: str

async def call_model(
    state: MessagesState,
    runtime: Runtime[Context],
):
    user_id = runtime.context.user_id
    namespace = ("memories", user_id)
    memories = await runtime.store.asearch(namespace, query=str(state["messages"][-1].content))
    info = "\n".join([d.value["data"] for d in memories])
    system_msg = f"You are a helpful assistant talking to the user. User info: {info}"

    # Store new memories if the user asks the model to remember
    last_message = state["messages"][-1]
    if "remember" in last_message.content.lower():
        memory = "User name is Bob"
        await runtime.store.aput(namespace, str(uuid.uuid4()), {"data": memory})

    response = await model.ainvoke(
        [{"role": "system", "content": system_msg}] + state["messages"]
    )
    return {"messages": response}

DB_URI = "redis://localhost:6379"

async with (
    AsyncRedisStore.from_conn_string(DB_URI) as store,
    AsyncRedisSaver.from_conn_string(DB_URI) as checkpointer,
):
    # await store.setup()
    # await checkpointer.asetup()

    builder = StateGraph(MessagesState, context_schema=Context)
    builder.add_node(call_model)
    builder.add_edge(START, "call_model")

    graph = builder.compile(
        checkpointer=checkpointer,
        store=store,
    )

    config = {"configurable": {"thread_id": "1"}}
    stream = await graph.astream_events(
        {"messages": [{"role": "user", "content": "Hi! Remember: my name is Bob"}]},
        config,
        version="v3",
        context=Context(user_id="1"),
    )
    async for snapshot in stream.values:
        snapshot["messages"][-1].pretty_print()

    config = {"configurable": {"thread_id": "2"}}
    stream = await graph.astream_events(
        {"messages": [{"role": "user", "content": "what is my name?"}]},
        config,
        version="v3",
        context=Context(user_id="1"),
    )
    async for snapshot in stream.values:
snapshot["messages"][-1].pretty_print()Example: using Oracle store
pip install -U langgraph langgraph-oracledb langchain-openaiNOTE
环境准备 要使用 Oracle store,你需要一个 Oracle AI Database 实例——用于语义 search 的向量索引需要 Oracle AI Vector Search。
TIP
首次使用 Oracle store 和检查点器时,你需要调用 store.setup() 和 checkpointer.setup()。
python
import uuid

from langchain.chat_models import init_chat_model
from langchain.embeddings import init_embeddings
from langchain_core.runnables import RunnableConfig
from langgraph.graph import StateGraph, MessagesState, START
from langgraph.store.base import BaseStore
from langgraph_oracledb.checkpoint.oracle import OracleSaver
from langgraph_oracledb.store.oracle import OracleStore

model = init_chat_model(model="claude-haiku-4-5-20251001")
embeddings = init_embeddings("openai:text-embedding-3-small")

DB_URI = "user/password@localhost:1521/FREEPDB1"

with (
    OracleStore.from_conn_string(
        DB_URI,
        index={"embed": embeddings, "dims": 1536},
    ) as store,
    OracleSaver.from_conn_string(DB_URI) as checkpointer,
):
    store.setup()
    checkpointer.setup()

    def call_model(
        state: MessagesState,
        config: RunnableConfig,
        *,
        store: BaseStore,
    ):
        user_id = config["configurable"]["user_id"]
        namespace = ("memories", user_id)
        memories = store.search(namespace, query=str(state["messages"][-1].content))
        info = "\n".join([d.value["data"] for d in memories])
        system_msg = f"You are a helpful assistant talking to the user. User info: {info}"

        # Store new memories if the user asks the model to remember
        last_message = state["messages"][-1]
        if "remember" in last_message.content.lower():
            memory = "User name is Bob"
            store.put(namespace, str(uuid.uuid4()), {"data": memory})

        response = model.invoke(
            [{"role": "system", "content": system_msg}] + state["messages"]
        )
        return {"messages": response}

    builder = StateGraph(MessagesState)
    builder.add_node(call_model)
    builder.add_edge(START, "call_model")

    graph = builder.compile(
        checkpointer=checkpointer,
        store=store,
    )

    config = {
        "configurable": {
            "thread_id": "1",
            "user_id": "1",
        }
    }
    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "Hi! Remember: my name is Bob"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
        snapshot["messages"][-1].pretty_print()

    config = {
        "configurable": {
            "thread_id": "2",
            "user_id": "1",
        }
    }

    stream = graph.stream_events(
        {"messages": [{"role": "user", "content": "what is my name?"}]},
        config,
        version="v3",
    )
    for snapshot in stream.values:
snapshot["messages"][-1].pretty_print()使用语义搜索
在图记忆存储中启用语义搜索,让图智能体能够按语义相似性在 store 中搜索条目。
python
from langchain.embeddings import init_embeddings
from langgraph.store.memory import InMemoryStore

# Create store with semantic search enabled
embeddings = init_embeddings("openai:text-embedding-3-small")
store = InMemoryStore(
    index={
        "embed": embeddings,
        "dims": 1536,
    }
)

store.put(("user_123", "memories"), "1", {"text": "I love pizza"})
store.put(("user_123", "memories"), "2", {"text": "I am a plumber"})

items = store.search(
    ("user_123", "memories"), query="I'm hungry", limit=1
)带有语义搜索的长期记忆
python
from langchain.embeddings import init_embeddings
from langchain.chat_models import init_chat_model
from langgraph.store.memory import InMemoryStore
from langgraph.graph import START, MessagesState, StateGraph
from langgraph.runtime import Runtime

model = init_chat_model("gpt-5.4-mini")

# Create store with semantic search enabled
embeddings = init_embeddings("openai:text-embedding-3-small")
store = InMemoryStore(
    index={
        "embed": embeddings,
        "dims": 1536,
    }
)

store.put(("user_123", "memories"), "1", {"text": "I love pizza"})
store.put(("user_123", "memories"), "2", {"text": "I am a plumber"})

async def chat(state: MessagesState, runtime: Runtime):
    # Search based on user's last message
    items = await runtime.store.asearch(
        ("user_123", "memories"), query=state["messages"][-1].content, limit=2
    )
    memories = "\n".join(item.value["text"] for item in items)
    memories = f"## Memories of user\n{memories}" if memories else ""
    response = await model.ainvoke(
        [
            {"role": "system", "content": f"You are a helpful assistant.\n{memories}"},
            *state["messages"],
        ]
    )
    return {"messages": [response]}

builder = StateGraph(MessagesState)
builder.add_node(chat)
builder.add_edge(START, "chat")
graph = builder.compile(store=store)

stream = await graph.astream_events(
    {"messages": [{"role": "user", "content": "I'm hungry"}]},
    version="v3",
)
async for message in stream.messages:
    async for token in message.text:
print(token, end="", flush=True)管理短期记忆
启用短期记忆后,长对话可能会超出 LLM 的上下文窗口。常见的解决方案有:
- 修剪消息:移除最前或最后的 N 条消息(在调用 LLM 之前)
- 从 LangGraph 状态中永久删除消息
- 总结消息:总结历史中较早的消息,并用摘要替换它们
- 管理检查点,以存储和检索消息历史
- 自定义策略(例如消息过滤等)
这使智能体能够跟踪对话,同时不超出 LLM 的上下文窗口。
裁剪消息
大多数 LLM 都有一个最大支持的上下文窗口(以 token 计)。决定何时截断消息的一种方法是统计消息历史中的 token 数量,并在接近该上限时进行截断。如果你使用 LangChain,可以使用消息修剪工具,指定要从列表中保留的 token 数量,以及用于处理边界的 strategy(例如保留最后的 max_tokens)。
要修剪消息历史,请使用 trim_messages 函数:
python
from langchain_core.messages.utils import (
    trim_messages,
    count_tokens_approximately
)

def call_model(state: MessagesState):
    messages = trim_messages(
        state["messages"],
        strategy="last",
        token_counter=count_tokens_approximately,
        max_tokens=128,
        start_on="human",
        end_on=("human", "tool"),
    )
    response = model.invoke(messages)
    return {"messages": [response]}

builder = StateGraph(MessagesState)
builder.add_node(call_model)
...完整示例:修剪消息
python
from langchain_core.messages.utils import (
    trim_messages,
    count_tokens_approximately
)
from langchain.chat_models import init_chat_model
from langgraph.graph import StateGraph, START, MessagesState

model = init_chat_model("claude-sonnet-4-6")
summarization_model = model.bind(max_tokens=128)

def call_model(state: MessagesState):
    messages = trim_messages(
        state["messages"],
        strategy="last",
        token_counter=count_tokens_approximately,
        max_tokens=128,
        start_on="human",
        end_on=("human", "tool"),
    )
    response = model.invoke(messages)
    return {"messages": [response]}

checkpointer = InMemorySaver()
builder = StateGraph(MessagesState)
builder.add_node(call_model)
builder.add_edge(START, "call_model")
graph = builder.compile(checkpointer=checkpointer)

config = {"configurable": {"thread_id": "1"}}
graph.invoke({"messages": "hi, my name is bob"}, config)
graph.invoke({"messages": "write a short poem about cats"}, config)
graph.invoke({"messages": "now do the same but for dogs"}, config)
final_response = graph.invoke({"messages": "what's my name?"}, config)

final_response["messages"][-1].pretty_print()================================== Ai Message ==================================
Your name is Bob, as you mentioned when you first introduced yourself.删除消息
你可以从图状态中删除消息以管理消息历史。当你想移除特定消息或清空整个消息历史时,这很有用。
要从图状态中删除消息,你可以使用 RemoveMessage。要让 RemoveMessage 正常工作,你需要使用带有 add_messages 归约器 的状态键,例如 MessagesState。
要删除特定消息:
python
from langchain.messages import RemoveMessage

def delete_messages(state):
    messages = state["messages"]
    if len(messages) > 2:
        # remove the earliest two messages
return {"messages": [RemoveMessage(id=m.id) for m in messages[:2]]} 要删除所有消息:
python
from langgraph.graph.message import REMOVE_ALL_MESSAGES

def delete_messages(state):
return {"messages": [RemoveMessage(id=REMOVE_ALL_MESSAGES)]} WARNING
删除消息时,请确保生成的消息历史是有效的。检查你所使用的 LLM 服务商的限制。例如:
- 某些服务商期望消息历史以
user消息开头 - 大多数服务商要求带有工具调用的
assistant消息后跟对应的tool结果消息。
完整示例:删除消息
python
from langchain.messages import RemoveMessage

def delete_messages(state):
    messages = state["messages"]
    if len(messages) > 2:
        # remove the earliest two messages
        return {"messages": [RemoveMessage(id=m.id) for m in messages[:2]]}

def call_model(state: MessagesState):
    response = model.invoke(state["messages"])
    return {"messages": response}

builder = StateGraph(MessagesState)
builder.add_sequence([call_model, delete_messages])
builder.add_edge(START, "call_model")

checkpointer = InMemorySaver()
app = builder.compile(checkpointer=checkpointer)
config = {"configurable": {"thread_id": "1"}}

stream = app.stream_events(
    {"messages": [{"role": "user", "content": "hi! I'm bob"}]},
    config,
    version="v3"
)
for snapshot in stream.values:
    print([(message.type, message.content) for message in snapshot["messages"]])

stream = app.stream_events(
    {"messages": [{"role": "user", "content": "what's my name?"}]},
    config,
    version="v3"
)
for snapshot in stream.values:
print([(message.type, message.content) for message in snapshot["messages"]])[('human', "hi! I'm bob")]
[('human', "hi! I'm bob"), ('ai', 'Hi Bob! How are you doing today? Is there anything I can help you with?')]
[('human', "hi! I'm bob"), ('ai', 'Hi Bob! How are you doing today? Is there anything I can help you with?'), ('human', "what's my name?")]
[('human', "hi! I'm bob"), ('ai', 'Hi Bob! How are you doing today? Is there anything I can help you with?'), ('human', "what's my name?"), ('ai', 'Your name is Bob.')]
[('human', "what's my name?"), ('ai', 'Your name is Bob.')]摘要消息
如上所示,修剪或删除消息的问题在于,消息队列的剔除可能会让你丢失信息。因此,一些应用受益于使用聊天模型总结消息历史的更精细方法。
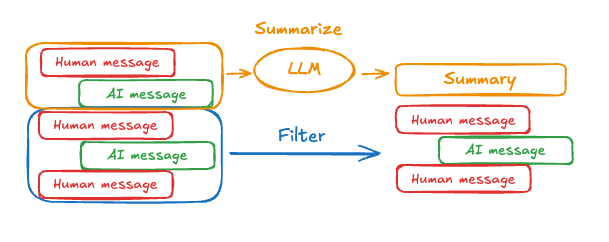
可以使用提示词和编排逻辑来总结消息历史。例如,在 LangGraph 中,你可以扩展 MessagesState 以包含一个 summary 键:
python
from langgraph.graph import MessagesState
class State(MessagesState):
summary: str然后,你可以生成聊天历史的摘要,并将任何现有摘要用作下一次摘要的上下文。这个 summarize_conversation 节点可以在 messages 状态键中累积了一定数量的消息后被调用。
python
def summarize_conversation(state: State):

    # First, we get any existing summary
    summary = state.get("summary", "")

    # Create our summarization prompt
    if summary:

        # A summary already exists
        summary_message = (
            f"This is a summary of the conversation to date: {summary}\n\n"
            "Extend the summary by taking into account the new messages above:"
        )

    else:
        summary_message = "Create a summary of the conversation above:"

    # Add prompt to our history
    messages = state["messages"] + [HumanMessage(content=summary_message)]
    response = model.invoke(messages)

    # Delete all but the 2 most recent messages
    delete_messages = [RemoveMessage(id=m.id) for m in state["messages"][:-2]]
return {"summary": response.content, "messages": delete_messages}完整示例:总结消息
python
from typing import Any, TypedDict

from langchain.chat_models import init_chat_model
from langchain.messages import AnyMessage
from langchain_core.messages.utils import count_tokens_approximately
from langgraph.graph import StateGraph, START, MessagesState
from langgraph.checkpoint.memory import InMemorySaver
from langmem.short_term import SummarizationNode, RunningSummary

model = init_chat_model("claude-sonnet-4-6")
summarization_model = model.bind(max_tokens=128)

class State(MessagesState):
    context: dict[str, RunningSummary]

class LLMInputState(TypedDict):
    summarized_messages: list[AnyMessage]
    context: dict[str, RunningSummary]

summarization_node = SummarizationNode(
    token_counter=count_tokens_approximately,
    model=summarization_model,
    max_tokens=256,
    max_tokens_before_summary=256,
    max_summary_tokens=128,
)

def call_model(state: LLMInputState):
    response = model.invoke(state["summarized_messages"])
    return {"messages": [response]}

checkpointer = InMemorySaver()
builder = StateGraph(State)
builder.add_node(call_model)
builder.add_node("summarize", summarization_node)
builder.add_edge(START, "summarize")
builder.add_edge("summarize", "call_model")
graph = builder.compile(checkpointer=checkpointer)

# Invoke the graph
config = {"configurable": {"thread_id": "1"}}
graph.invoke({"messages": "hi, my name is bob"}, config)
graph.invoke({"messages": "write a short poem about cats"}, config)
graph.invoke({"messages": "now do the same but for dogs"}, config)
final_response = graph.invoke({"messages": "what's my name?"}, config)

final_response["messages"][-1].pretty_print()
print("\nSummary:", final_response["context"]["running_summary"].summary)- 我们将在
context字段中跟踪我们的运行摘要
(SummarizationNode 所期望的)。
- 定义仅用于过滤
call_model 节点输入的私有状态。
- 我们在这里传入一个私有输入状态,以隔离由总结节点返回的消息
================================== Ai Message ==================================

From our conversation, I can see that you introduced yourself as Bob. That's the name you shared with me when we began talking.

Summary: In this conversation, I was introduced to Bob, who then asked me to write a poem about cats. I composed a poem titled "The Mystery of Cats" that captured cats' graceful movements, independent nature, and their special relationship with humans. Bob then requested a similar poem about dogs, so I wrote "The Joy of Dogs," which highlighted dogs' loyalty, enthusiasm, and loving companionship. Both poems were written in a similar style but emphasized the distinct characteristics that make each pet special.管理检查点
你可以查看并删除检查点器存储的信息。
查看线程状态
python
config = {
"configurable": {
"thread_id": "1",
# optionally provide an ID for a specific checkpoint,
# otherwise the latest checkpoint is shown
# "checkpoint_id": "1f029ca3-1f5b-6704-8004-820c16b69a5a" #
StateSnapshot(
    values={'messages': [HumanMessage(content="hi! I'm bob"), AIMessage(content='Hi Bob! How are you doing today?), HumanMessage(content="what's my name?"), AIMessage(content='Your name is Bob.')]}, next=(),
    config={'configurable': {'thread_id': '1', 'checkpoint_ns': '', 'checkpoint_id': '1f029ca3-1f5b-6704-8004-820c16b69a5a'}},
    metadata={
        'source': 'loop',
        'writes': {'call_model': {'messages': AIMessage(content='Your name is Bob.')}},
        'step': 4,
        'parents': {},
        'thread_id': '1'
    },
    created_at='2025-05-05T16:01:24.680462+00:00',
    parent_config={'configurable': {'thread_id': '1', 'checkpoint_ns': '', 'checkpoint_id': '1f029ca3-1790-6b0a-8003-baf965b6a38f'}},
    tasks=(),
    interrupts=()
)查看线程的历史记录
python
config = {
    "configurable": {
        "thread_id": "1"
    }
}
list(graph.get_state_history(config)) [
StateSnapshot(
values={'messages': [HumanMessage(content="hi! I'm bob"), AIMessage(content='Hi Bob! How are you doing today? Is there anything I can help you with?'), HumanMessage(content="what's my name?"), AIMessage(content='Your name is Bob.')]},
next=(),
config={'configurable': {'thread_id': '1', 'checkpoint_ns': '', 'checkpoint_id': '1f029ca3-1f5b-6704-8004-820c16b69a5a'}},
metadata={'source': 'loop', 'writes': {'call_model': {'messages': AIMessage(content='Your name is Bob.')}}, 'step': 4, 'parents': {}, 'thread_id': '1'},
created_at='2025-05-05T16:01:24.680462+00:00',
parent_config={'configurable': {'thread_id': '1', 'checkpoint_ns': '', 'checkpoint_id': '1f029ca3-1790-6b0a-8003-baf965b6a38f'}},
tasks=(),
interrupts=()
),
StateSnapshot(
values={'messages': [HumanMessage(content="hi! I'm bob"), AIMessage(content='Hi Bob! How are you doing today? Is there anything I can help you with?'), HumanMessage(content="what's my name?")]},
next=('call_model',),
config={'configurable': {'thread_id': '1', 'checkpoint_ns': '', 'checkpoint_id': '1f029ca3-1790-6b0a-8003-baf965b6a38f'}},
metadata={'source': 'loop', 'writes': None, 'step': 3, 'parents': {}, 'thread_id': '1'},
created_at='2025-05-05T16:01:23.863421+00:00',
parent_config={...}
tasks=(PregelTask(id='8ab4155e-6b15-b885-9ce5-bed69a2c305c', name='call_model', path=('__pregel_pull', 'call_model'), error=None, interrupts=(), state=None, result={'messages': AIMessage(content='Your name is Bob.')}),),
interrupts=()
),
StateSnapshot(
values={'messages': [HumanMessage(content="hi! I'm bob"), AIMessage(content='Hi Bob! How are you doing today? Is there anything I can help you with?')]},
next=('__start__',),
config={...},
metadata={'source': 'input', 'writes': {'__start__': {'messages': [{'role': 'user', 'content': "what's my name?"}]}}, 'step': 2, 'parents': {}, 'thread_id': '1'},
created_at='2025-05-05T16:01:23.863173+00:00',
parent_config={...}
tasks=(PregelTask(id='24ba39d6-6db1-4c9b-f4c5-682aeaf38dcd', name='__start__', path=('__pregel_pull', '__start__'), error=None, interrupts=(), state=None, result={'messages': [{'role': 'user', 'content': "what's my name?"}]}),),
interrupts=()
),
StateSnapshot(
values={'messages': [HumanMessage(content="hi! I'm bob"), AIMessage(content='Hi Bob! How are you doing today? Is there anything I can help you with?')]},
next=(),
config={...},
metadata={'source': 'loop', 'writes': {'call_model': {'messages': AIMessage(content='Hi Bob! How are you doing today? Is there anything I can help you with?')}}, 'step': 1, 'parents': {}, 'thread_id': '1'},
created_at='2025-05-05T16:01:23.862295+00:00',
parent_config={...}
tasks=(),
interrupts=()
),
StateSnapshot(
values={'messages': [HumanMessage(content="hi! I'm bob")]},
next=('call_model',),
config={...},
metadata={'source': 'loop', 'writes': None, 'step': 0, 'parents': {}, 'thread_id': '1'},
created_at='2025-05-05T16:01:22.278960+00:00',
parent_config={...}
tasks=(PregelTask(id='8cbd75e0-3720-b056-04f7-71ac805140a0', name='call_model', path=('__pregel_pull', 'call_model'), error=None, interrupts=(), state=None, result={'messages': AIMessage(content='Hi Bob! How are you doing today? Is there anything I can help you with?')}),),
interrupts=()
),
StateSnapshot(
values={'messages': []},
next=('__start__',),
config={'configurable': {'thread_id': '1', 'checkpoint_ns': '', 'checkpoint_id': '1f029ca3-0870-6ce2-bfff-1f3f14c3e565'}},
metadata={'source': 'input', 'writes': {'__start__': {'messages': [{'role': 'user', 'content': "hi! I'm bob"}]}}, 'step': -1, 'parents': {}, 'thread_id': '1'},
created_at='2025-05-05T16:01:22.277497+00:00',
parent_config=None,
tasks=(PregelTask(id='d458367b-8265-812c-18e2-33001d199ce6', name='__start__', path=('__pregel_pull', '__start__'), error=None, interrupts=(), state=None, result={'messages': [{'role': 'user', 'content': "hi! I'm bob"}]}),),
interrupts=()
)
]删除某个线程的所有检查点
python
thread_id = "1"
checkpointer.delete_thread(thread_id)数据库管理
如果你使用任何基于数据库的持久化实现(例如 Postgres、Redis 或 Oracle)来存储短期和/或长期记忆,那么在与你的数据库配合使用之前,你需要运行迁移来设置所需的 schema。
按照惯例,大多数数据库专用库会在检查点器或存储实例上定义一个 setup() 方法,用于运行所需的迁移。不过,你应该查阅你对 BaseCheckpointSaver 或 BaseStore 的具体实现,以确认确切的方法名和用法。
我们建议将迁移作为单独的部署步骤来运行,或者你可以确保它们作为服务器启动的一部分来运行。