
主题
优化分类器
本教程展示如何基于用户反馈优化分类器。分类器非常适合优化,因为收集期望输出通常相当简单,这使得基于用户反馈创建 few-shot 示例变得容易。这正是本示例要做的。
目标
在本示例中,我们将构建一个根据标题对 GitHub issue 进行分类的机器人。它接收标题并将其归入多个不同类别之一。然后,我们将开始收集用户反馈,并利用这些反馈来塑造分类器的表现。
入门
首先,我们会将所有追踪发送到特定项目。可以通过设置环境变量来实现:
python
import os
os.environ["LANGSMITH_PROJECT"] = "classifier"然后我们可以创建初始应用。这将是一个非常简单的函数,只接收 GitHub issue 标题并尝试为其打标签。
python
import openai
from langsmith import traceable, Client
import uuid

client = openai.Client()

available_topics = [
    "bug",
    "improvement",
    "new_feature",
    "documentation",
    "integration",
]

prompt_template = """Classify the type of the issue as one of {topics}.
Issue: {text}"""

@traceable(
    run_type="chain",
    name="Classifier",
)
def topic_classifier(
    topic: str):
    return client.chat.completions.create(
        model="gpt-5.4-mini",
        temperature=0,
        messages=[
            {
                "role": "user",
                "content": prompt_template.format(
                    topics=','.join(available_topics),
                    text=topic,
                )
            }
        ],
).choices[0].message.content然后我们可以开始与它交互。交互时,我们会提前生成 LangSmith run id 并将其传入该函数。这样做是为了稍后能够附加反馈。
以下是调用应用的方式:
python
from langsmith import uuid7

run_id = uuid7()
topic_classifier(
    "fix bug in LCEL",
langsmith_extra={"run_id": run_id})以下是稍后附加反馈的方式。我们可以收集两种形式的反馈。
首先,我们可以收集 "positive" 反馈——用于模型分类正确的示例。
python
ls_client = Client()
run_id = uuid7()
topic_classifier(
    "fix bug in LCEL",
    langsmith_extra={"run_id": run_id})
# Resolve the UUID of the project that owns the trace
session_id = ls_client.create_project(project_name="classifier", upsert=True).id
ls_client.create_feedback(
    run_id,
    key="user-score",
    score=1.0,
    session_id=session_id,
)接下来,我们可以专注于收集对应于生成 "correction" 的反馈。在此示例中,模型会将其分类为 bug,而实际上我希望它被分类为 documentation。
python
ls_client = Client()
run_id = uuid7()
topic_classifier(
    "fix bug in documentation",
    langsmith_extra={"run_id": run_id})
session_id = ls_client.create_project(project_name="classifier", upsert=True).id
ls_client.create_feedback(
    run_id,
    key="correction",
    correction="documentation",
session_id=session_id)设置自动化
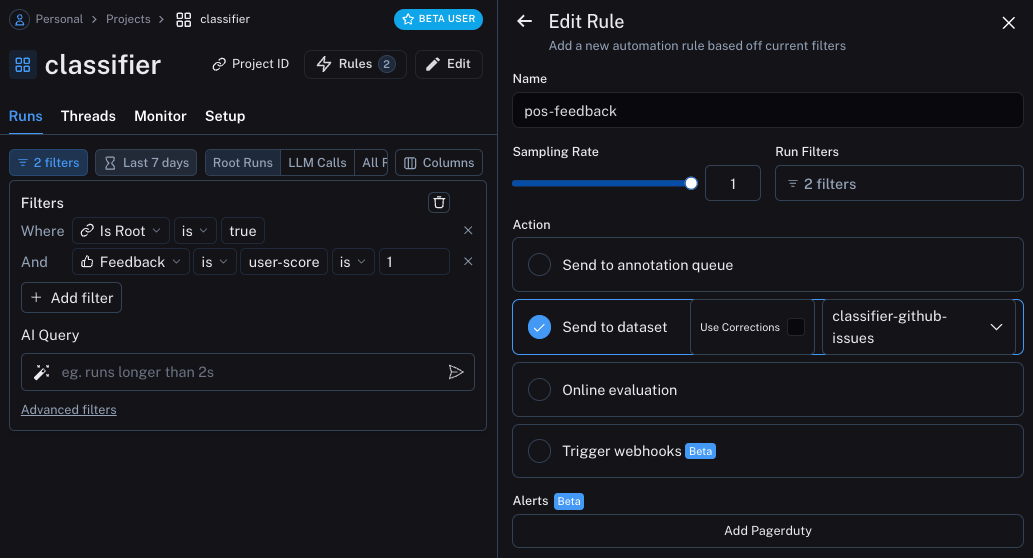
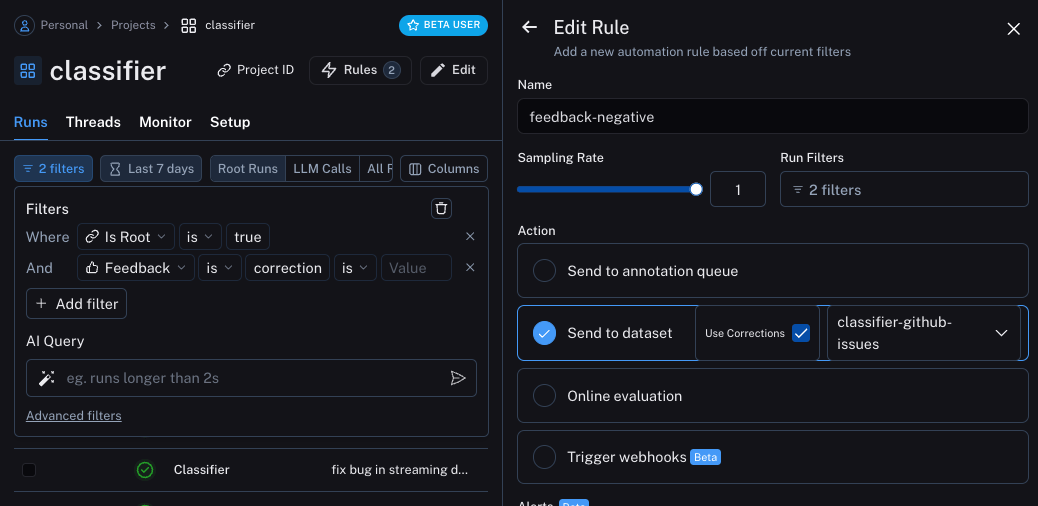
现在我们可以设置自动化,将带有某种形式反馈的示例移入数据集。我们将设置两个自动化,一个用于正向反馈,另一个用于负向反馈。
第一个自动化会将所有带正向反馈的 run 自动添加到数据集。其逻辑是,任何带正向反馈的 run 都可以作为未来迭代中的良好示例。我们创建一个名为 classifier-github-issues 的数据集来添加这些数据。
第二个自动化会获取所有带有 correction 的 run,并使用 webhook 将它们添加到数据集。创建此 webhook 时,我们将选择 "Use Corrections" 选项。该选项使得从 run 创建数据集时,不使用 run 的输出作为数据点的标准答案,而是使用 correction。
更新应用
现在我们可以更新代码,拉取接收 run 的数据集。拉取后,我们可以用其中的示例构造一个字符串,然后将该字符串放入提示词中!
python
### NEW CODE ###
# Initialize the LangSmith Client so we can use to get the dataset
ls_client = Client()

# Create a function that will take in a list of examples and format them into a string
def create_example_string(examples):
    final_strings = []
    for e in examples:
        final_strings.append(f"Input: {e.inputs['topic']}\n> {e.outputs['output']}")
    return "\n\n".join(final_strings)
### NEW CODE ###

client = openai.Client()

available_topics = [
    "bug",
    "improvement",
    "new_feature",
    "documentation",
    "integration",
]

prompt_template = """Classify the type of the issue as one of {topics}.

Here are some examples:
{examples}

Begin!
Issue: {text}
>"""

@traceable(
    run_type="chain",
    name="Classifier",
)
def topic_classifier(
    topic: str):
    # We can now pull down the examples from the dataset
    # We do this inside the function so it always get the most up-to-date examples,
    # But this can be done outside and cached for speed if desired
    examples = list(ls_client.list_examples(dataset_name="classifier-github-issues"))  # <- New Code
    example_string = create_example_string(examples)
    return client.chat.completions.create(
        model="gpt-5.4-mini",
        temperature=0,
        messages=[
            {
                "role": "user",
                "content": prompt_template.format(
                    topics=','.join(available_topics),
                    text=topic,
                    examples=example_string,
                )
            }
        ],
).choices[0].message.content如果现在用与之前类似的输入运行应用,可以看到它正确学会了将任何与文档相关的内容(即使是一个 bug)分类为 documentation
python
ls_client = Client()
run_id = uuid7()
topic_classifier(
    "address bug in documentation",
langsmith_extra={"run_id": run_id})对示例进行语义搜索
我们还可以做一件事:只使用语义上最相似的示例。当示例积累得很多时,这很有用。
为此,我们可以先定义一个查找 k 个最相似示例的示例:
python
import numpy as np

def find_similar(examples, topic, k=5):
    inputs = [e.inputs['topic'] for e in examples] + [topic]
    vectors = client.embeddings.create(input=inputs, model="text-embedding-3-small")
    vectors = [e.embedding for e in vectors.data]
    vectors = np.array(vectors)
    args = np.argsort(-vectors.dot(vectors[-1])[:-1])[:5]
    examples = [examples[i] for i in args]
return examples然后我们可以在应用中使用它
python
ls_client = Client()

def create_example_string(examples):
    final_strings = []
    for e in examples:
        final_strings.append(f"Input: {e.inputs['topic']}\n> {e.outputs['output']}")
    return "\n\n".join(final_strings)

client = openai.Client()

available_topics = [
    "bug",
    "improvement",
    "new_feature",
    "documentation",
    "integration",
]

prompt_template = """Classify the type of the issue as one of {topics}.

Here are some examples:
{examples}

Begin!
Issue: {text}
>"""

@traceable(
    run_type="chain",
    name="Classifier",
)
def topic_classifier(
    topic: str):
    examples = list(ls_client.list_examples(dataset_name="classifier-github-issues"))
    examples = find_similar(examples, topic)
    example_string = create_example_string(examples)
    return client.chat.completions.create(
        model="gpt-5.4-mini",
        temperature=0,
        messages=[
            {
                "role": "user",
                "content": prompt_template.format(
                    topics=','.join(available_topics),
                    text=topic,
                    examples=example_string,
                )
            }
        ],
    ).choices[0].message.content