
主题
评估一个复杂的 agent
在本教程中,我们将构建一个帮助用户在数字音乐商店中导航的客户支持机器人。然后,我们将走过对聊天机器人最有效的三种评估:
- 最终响应:评估 agent 的最终响应。
- 轨迹:评估 agent 是否采取了预期的路径(例如工具调用序列)以得出最终答案。
- 单步:孤立地评估任何 agent 步骤(例如它是否为某个给定步骤选对了第一个工具)。
我们用 LangGraph 构建我们的 agent,但这里展示的技术和 LangSmith 功能是与框架无关的。
设置
配置环境
我们来安装所需的依赖:
bash
pip install -U langgraph "langchain[openai]"bash
uv add langgraph "langchain[openai]"我们来为 OpenAI 和 LangSmith 设置环境变量:
python
import getpass
import os

def _set_env(var: str) -> None:
    if not os.environ.get(var):
        os.environ[var] = getpass.getpass(f"Set {var}: ")

os.environ["LANGSMITH_TRACING"] = "true"
_set_env("LANGSMITH_API_KEY")
_set_env("OPENAI_API_KEY")下载数据库
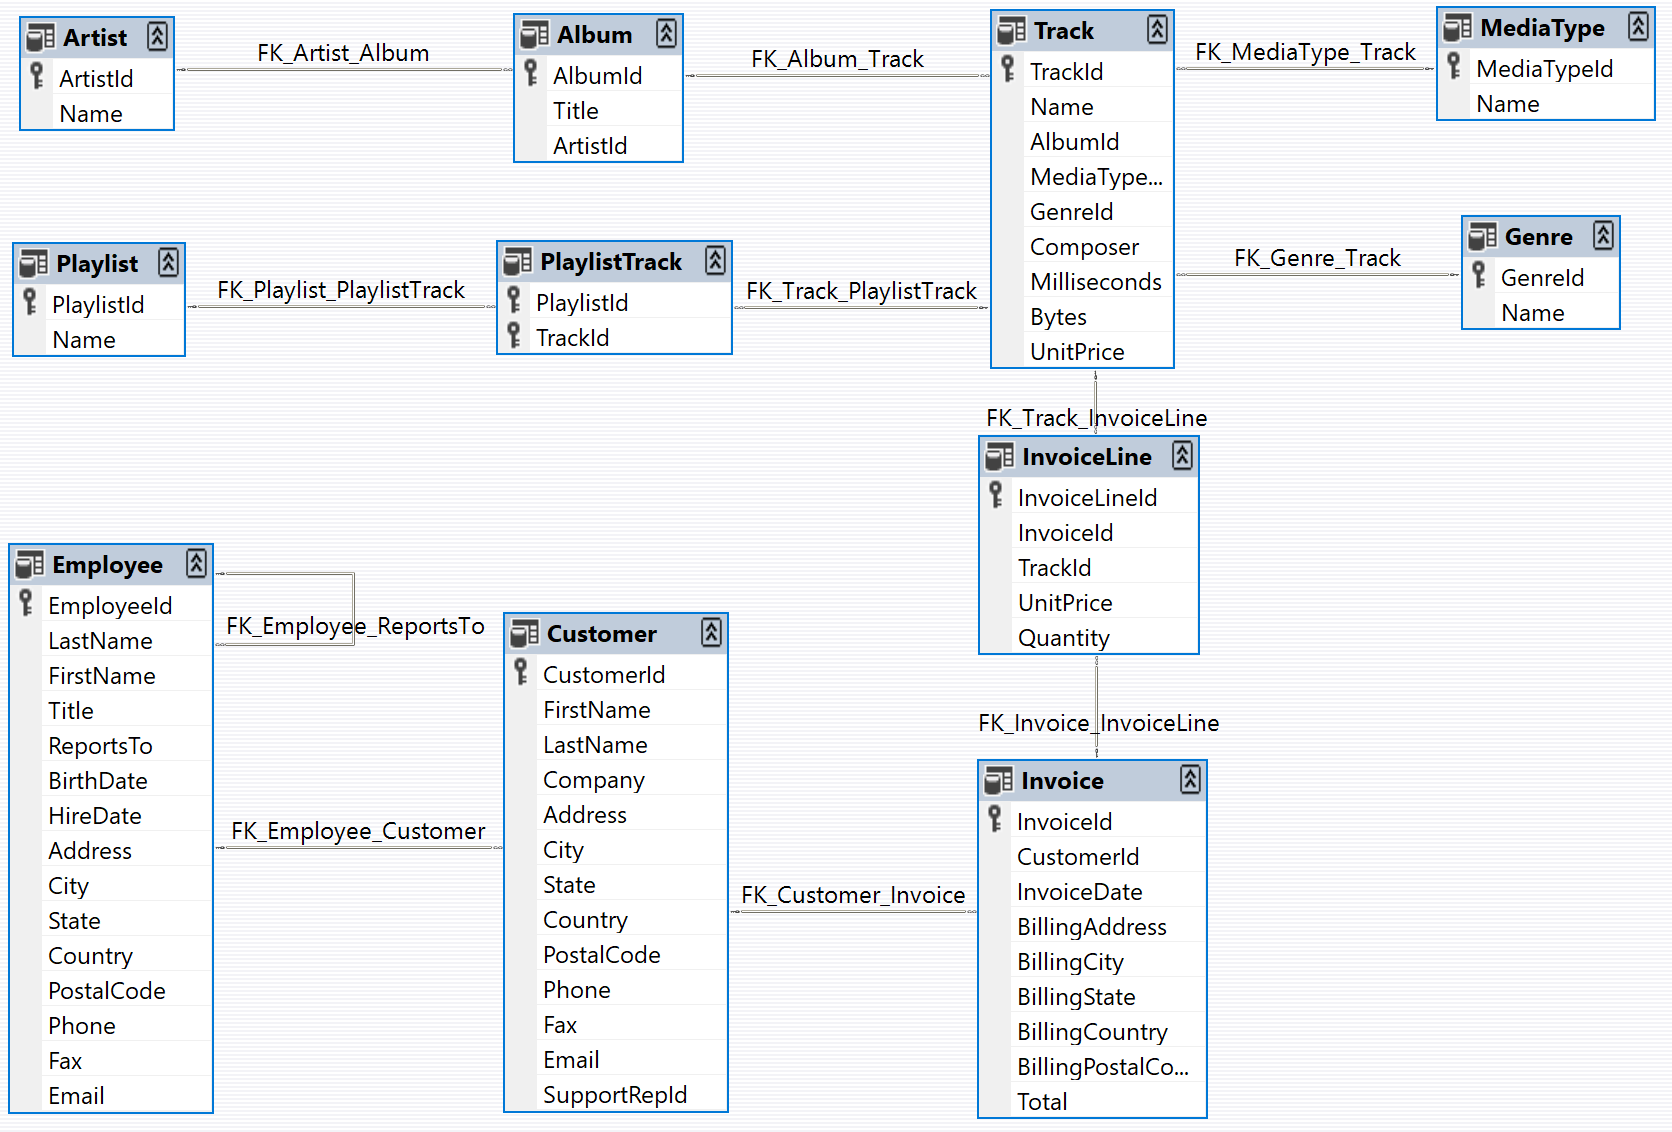
我们将为此教程创建一个 SQLite 数据库。SQLite 是一个轻量、易于设置和使用的数据库。我们将加载 chinook 数据库,它是一个代表数字媒体商店的示例数据库。更多信息参阅 Chinook 示例数据库。
为便于使用,我们把该数据库托管在一个公共 GCS 存储桶中:
python
import requests

url = "https://storage.googleapis.com/benchmarks-artifacts/chinook/Chinook.db"
response = requests.get(url)

if response.status_code == 200:
    # Open a local file in binary write mode
    with open("chinook.db", "wb") as file:
        # Write the content of the response (the file) to the local file
        file.write(response.content)
    print("File downloaded and saved as Chinook.db")
else:
print(f"Failed to download the file. Status code: {response.status_code}")以下是数据库中数据的一个样本:
python
import sqlite3
# ... database connection and query code[(1, 'AC/DC'), (2, 'Accept'), (3, 'Aerosmith'), (4, 'Alanis Morissette'), (5, 'Alice In Chains'), (6, 'Antônio Carlos Jobim'), (7, 'Apocalyptica'), (8, 'Audioslave'), (9, 'BackBeat'), (10, 'Billy Cobham')]这里是数据库 schema(图片来自 https://github.com/lerocha/chinook-database):
定义客户支持 agent
我们将创建一个对我们数据库有受限访问的 LangGraph agent。为演示目的,我们的 agent 支持两类基本请求:
- 查询:客户可以根据其他标识信息查询歌曲标题、艺术家名和专辑。例如:"你有哪些 Jimi Hendrix 的歌?"
- 退款:客户可以对他们的过往购买请求退款。例如:"我叫 Claude Shannon,我想对我上周的一笔购买申请退款,你能帮我吗?"
为在这个演示中简化,我们通过删除对应的数据库记录来实现退款。我们会跳过实现用户身份验证和其他生产安全措施。
agent 的逻辑将被构建为两个独立的子图(一个用于查询,一个用于退款),外加一个把请求路由到合适子图的父图。
退款 agent
我们来构建退款处理 agent。这个 agent 需要:
- 在数据库中找到客户的购买记录
- 删除相关的 Invoice 和 InvoiceLine 记录以处理退款
我们将创建两个 SQL 辅助函数:
- 一个通过删除记录执行退款的函数
- 一个查询客户购买历史的函数
为使测试更容易,我们会给这些函数加一个"mock"模式。当启用 mock 模式时,这些函数会模拟数据库操作而实际不修改任何数据。
python
import sqlite3

def _refund(invoice_id: int | None, invoice_line_ids: list[int] | None, mock: bool = False) -> float:
    ...

def _lookup( ...现在来定义我们的图。我们会用一个带三条主路径的简单架构:
从对话中提取客户和购买信息
把请求路由到三条路径之一:
- 退款路径:如果我们有足够的购买详情(Invoice ID 或 Invoice Line ID)来处理退款
- 查询路径:如果我们有足够的客户信息(姓名和电话)来搜索其购买历史
- 响应路径:如果我们需要更多信息,回复用户请求所需的具体细节
图的状态将跟踪:
- 对话历史(用户与 agent 之间的消息)
- 从对话中提取的所有客户和购买信息
- 要发给用户的下一条消息(followup 文本)
python
from typing import Literal
import json

from langchain.chat_models import init_chat_model
from langchain_core.runnables import RunnableConfig
from langgraph.graph import END, StateGraph
from langgraph.graph.message import AnyMessage, add_messages
from langgraph.types import Command, interrupt
from tabulate import tabulate
from typing_extensions import Annotated, TypedDict

# Graph state.
class State(TypedDict):
    """Agent state."""
    messages: Annotated[list[AnyMessage], add_messages]
    followup: str | None

    invoice_id: int | None
    invoice_line_ids: list[int] | None
    customer_first_name: str | None
    customer_last_name: str | None
    customer_phone: str | None
    track_name: str | None
    album_title: str | None
    artist_name: str | None
    purchase_date_iso_8601: str | None

# Instructions for extracting the user/purchase info from the conversation.
gather_info_instructions = """You are managing an online music store that sells song tracks. \
Customers can buy multiple tracks at a time and these purchases are recorded in a database as \
an Invoice per purchase and an associated set of Invoice Lines for each purchased track.

Your task is to help customers who would like a refund for one or more of the tracks they've \
purchased. In order for you to be able refund them, the customer must specify the Invoice ID \
to get a refund on all the tracks they bought in a single transaction, or one or more Invoice \
Line IDs if they would like refunds on individual tracks.

Often a user will not know the specific Invoice ID(s) or Invoice Line ID(s) for which they \
would like a refund. In this case you can help them look up their invoices by asking them to \
specify:
- Required: Their first name, last name, and phone number.
- Optionally: The track name, artist name, album name, or purchase date.

If the customer has not specified the required information (either Invoice/Invoice Line IDs \
or first name, last name, phone) then please ask them to specify it."""

# Extraction schema, mirrors the graph state.
class PurchaseInformation(TypedDict):
    """All of the known information about the invoice / invoice lines the customer would like refunded. Do not make up values, leave fields as null if you don't know their value."""

    invoice_id: int | None
    invoice_line_ids: list[int] | None
    customer_first_name: str | None
    customer_last_name: str | None
    customer_phone: str | None
    track_name: str | None
    album_title: str | None
    artist_name: str | None
    purchase_date_iso_8601: str | None
    followup: Annotated[
        str | None,
        ...,
        "If the user hasn't enough identifying information, please tell them what the required information is and ask them to specify it.",
    ]

# Model for performing extraction.
info_llm = init_chat_model("gpt-5.4-mini").with_structured_output(
    PurchaseInformation, method="json_schema", include_raw=True
)

# Graph node for extracting user info and routing to lookup/refund/END.
async def gather_info(state: State) -> Command[Literal["lookup", "refund", END]]:
    info = await info_llm.ainvoke(
        [
            {"role": "system", "content": gather_info_instructions},
            *state["messages"],
        ]
    )
    parsed = info["parsed"]
    if any(parsed[k] for k in ("invoice_id", "invoice_line_ids")):
        goto = "refund"
    elif all(
        parsed[k]
        for k in ("customer_first_name", "customer_last_name", "customer_phone")
    ):
        goto = "lookup"
    else:
        goto = END
    update = {"messages": [info["raw"]], **parsed}
    return Command(update=update, goto=goto)

# Graph node for executing the refund.
# Note that here we inspect the runtime config for an "env" variable.
# If "env" is set to "test", then we don't actually delete any rows from our database.
# This will become important when we're running our evaluations.
def refund(state: State, config: RunnableConfig) -> dict:
    # Whether to mock the deletion. True if the configurable var 'env' is set to 'test'.
    mock = config.get("configurable", {}).get("env", "prod") == "test"
    refunded = _refund(
        invoice_id=state["invoice_id"], invoice_line_ids=state["invoice_line_ids"], mock=mock
    )
    response = f"You have been refunded a total of: ${refunded:.2f}. Is there anything else I can help with?"
    return {
        "messages": [{"role": "assistant", "content": response}],
        "followup": response,
    }

# Graph node for looking up the users purchases
def lookup(state: State) -> dict:
    args = (
        state[k]
        for k in (
            "customer_first_name",
            "customer_last_name",
            "customer_phone",
            "track_name",
            "album_title",
            "artist_name",
            "purchase_date_iso_8601",
        )
    )
    results = _lookup(*args)
    if not results:
        response = "We did not find any purchases associated with the information you've provided. Are you sure you've entered all of your information correctly?"
        followup = response
    else:
        response = f"Which of the following purchases would you like to be refunded for?\n\n```json{json.dumps(results, indent=2)}\n```"
        followup = f"Which of the following purchases would you like to be refunded for?\n\n{tabulate(results, headers='keys')}"
    return {
        "messages": [{"role": "assistant", "content": response}],
        "followup": followup,
        "invoice_line_ids": [res["invoice_line_id"] for res in results],
    }

# Building our graph
graph_builder = StateGraph(State)

graph_builder.add_node(gather_info)
graph_builder.add_node(refund)
graph_builder.add_node(lookup)

graph_builder.set_entry_point("gather_info")
graph_builder.add_edge("lookup", END)
graph_builder.add_edge("refund", END)

refund_graph = graph_builder.compile()我们可以可视化我们的退款图:
# Assumes you're in an interactive Python environmentfrom IPython.display import Image, display ...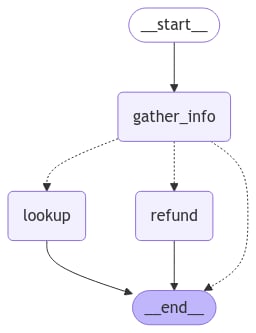
查询 agent
对于查询(即问答)agent,我们会用一个简单的 ReACT 架构,并给 agent 提供按各种过滤器查询曲目名、艺术家名和专辑名的工具。例如,你可以查询某个特定艺术家的专辑、发布了某个特定名歌曲的艺术家,等等。
python
from langchain.embeddings import init_embeddings
from langchain.tools import tool
from langchain_core.vectorstores import InMemoryVectorStore
from langchain.agents import create_agent

# Our SQL queries will only work if we filter on the exact string values that are in the DB.
# To ensure this, we'll create vectorstore indexes for all of the artists, tracks and albums
# ahead of time and use those to disambiguate the user input. E.g. if a user searches for
# songs by "prince" and our DB records the artist as "Prince", ideally when we query our
# artist vectorstore for "prince" we'll get back the value "Prince", which we can then
# use in our SQL queries.
def index_fields() -> tuple[InMemoryVectorStore, InMemoryVectorStore, InMemoryVectorStore]: ...

track_store, artist_store, album_store = index_fields()

# Agent tools
@tool
def lookup_track( ...

@tool
def lookup_album( ...

@tool
def lookup_artist( ...

# Agent model
qa_llm = init_chat_model("claude-sonnet-4-6")
# The prebuilt ReACT agent only expects State to have a 'messages' key, so the
# state we defined for the refund agent can also be passed to our lookup agent.
qa_graph = create_agent(qa_llm, tools=[lookup_track, lookup_artist, lookup_album])display(Image(qa_graph.get_graph(xray=True).draw_mermaid_png()))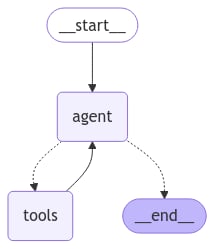
父 agent
现在来定义一个把我们两个任务专属 agent 组合起来的父 agent。父 agent 的唯一职责是通过分类用户当前的意图路由到某个子 agent,并把输出汇编成一条 followup 消息。
python
# Schema for routing user intent.
# We'll use structured output to enforce that the model returns only
# the desired output.
class UserIntent(TypedDict):
    """The user's current intent in the conversation"""

    intent: Literal["refund", "question_answering"]

# Routing model with structured output
router_llm = init_chat_model("gpt-5.4-mini").with_structured_output(
    UserIntent, method="json_schema", strict=True
)

# Instructions for routing.
route_instructions = """You are managing an online music store that sells song tracks. \
You can help customers in two types of ways: (1) answering general questions about \
tracks sold at your store, (2) helping them get a refund on a purhcase they made at your store.

Based on the following conversation, determine if the user is currently seeking general \
information about song tracks or if they are trying to refund a specific purchase.

Return 'refund' if they are trying to get a refund and 'question_answering' if they are \
asking a general music question. Do NOT return anything else. Do NOT try to respond to \
the user.
"""

# Node for routing.
async def intent_classifier(
    state: State,
) -> Command[Literal["refund_agent", "question_answering_agent"]]:
    response = router_llm.invoke(
        [{"role": "system", "content": route_instructions}, *state["messages"]]
    )
    return Command(goto=response["intent"] + "_agent")

# Node for making sure the 'followup' key is set before our agent run completes.
def compile_followup(state: State) -> dict:
    """Set the followup to be the last message if it hasn't explicitly been set."""
    if not state.get("followup"):
        return {"followup": state["messages"][-1].content}
    return {}

# Agent definition
graph_builder = StateGraph(State)
graph_builder.add_node(intent_classifier)
# Since all of our subagents have compatible state,
# we can add them as nodes directly.
graph_builder.add_node("refund_agent", refund_graph)
graph_builder.add_node("question_answering_agent", qa_graph)
graph_builder.add_node(compile_followup)

graph_builder.set_entry_point("intent_classifier")
graph_builder.add_edge("refund_agent", "compile_followup")
graph_builder.add_edge("question_answering_agent", "compile_followup")
graph_builder.add_edge("compile_followup", END)

graph = graph_builder.compile()我们可以可视化我们已编译的、包括其所有子图的父图:
python
display(Image(graph.get_graph().draw_mermaid_png()))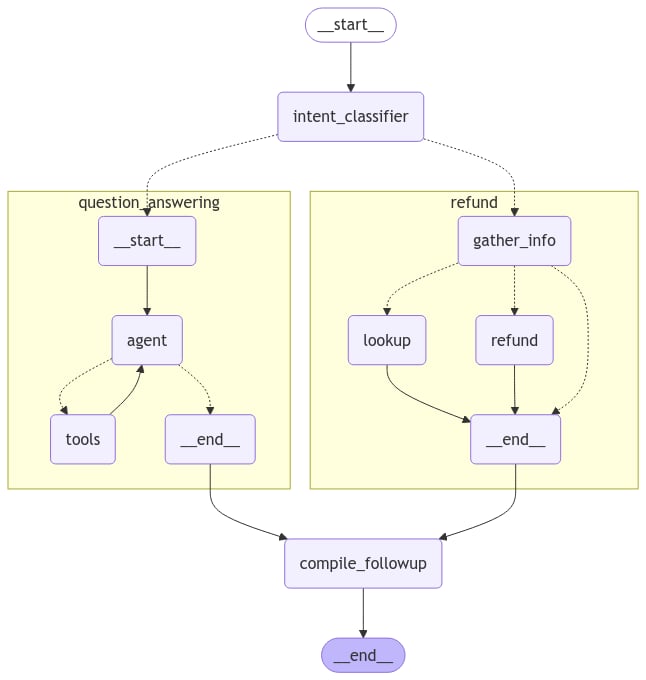
试一试
让我们来试试我们的自定义支持 agent!
python
state = await graph.ainvoke(
    {"messages": [{"role": "user", "content": "what james brown songs do you have"}]}
)
print(state["followup"])I found 20 James Brown songs in the database, all from the album "Sex Machine". Here they are: ...python
state = await graph.ainvoke({"messages": [
    {
        "role": "user",
        "content": "my name is Aaron Mitchell and my number is +1 (204) 452-6452. I bought some songs by Led Zeppelin that i'd like refunded",
    }
]})
print(state["followup"])Which of the following purchases would you like to be refunded for? ...评估
现在我们有了 agent 一个可测试的版本,让我们来运行一些评估。agent 评估至少可以聚焦三件事:
- 最终响应:输入是一个提示和一个可选的工具列表。输出是最终的 agent 响应。
- 轨迹:同前,输入是一个提示和一个可选的工具列表。输出是工具调用的列表
- 单步:同前,输入是一个提示和一个可选的工具列表。输出是工具调用。
让我们运行每种评估:
最终响应评估器
首先,让我们创建一个数据集来评估 agent 的端到端表现。为简单起见,我们会对最终响应和轨迹评估用同一个数据集,因此我们会为每个示例问题加上真值响应和轨迹。我们会在下一节涵盖轨迹。
python
from langsmith import Client

client = Client()

# Create a dataset
examples = [
    {
        "inputs": {
            "question": "How many songs do you have by James Brown",
        },
        "outputs": {
            "response": "We have 20 songs by James Brown",
            "trajectory": ["question_answering_agent", "lookup_track"]
        }
    },
    {
        "inputs": {
            "question": "My name is Aaron Mitchell and I'd like a refund.",
        },
        "outputs": {
            "response": "I need some more information to help you with the refund. Please specify your phone number, the invoice ID, or the line item IDs for the purchase you'd like refunded.",
            "trajectory": ["refund_agent"],
        }
    },
    {
        "inputs": {
            "question": "My name is Aaron Mitchell and I'd like a refund on my Led Zeppelin purchases. My number is +1 (204) 452-6452",
        },
        "outputs": {
            "response": 'Which of the following purchases would you like to be refunded for?\n\n  invoice_line_id  track_name                        artist_name    purchase_date          quantity_purchased    price_per_unit\n-----------------  --------------------------------  -------------  -------------------  --------------------  ----------------\n              267  How Many More Times               Led Zeppelin   2009-08-06 00:00:00                     1              0.99\n              268  What Is And What Should Never Be  Led Zeppelin   2009-08-06 00:00:00                     1              0.99',
            "trajectory": ["refund_agent", "lookup"],
        },
    },
    {
        "inputs": {
            "question": "Who recorded Wish You Were Here again? What other albums of there's do you have?",
        },
        "outputs": {
            "response": "Wish You Were Here is an album by Pink Floyd",
            "trajectory": ["question_answering_agent", "lookup_album"],
        },
    },
    {
        "inputs": {
            "question": "I want a full refund for invoice 237",
        },
        "outputs": {
            "response": "You have been refunded $0.99.",
            "trajectory": ["refund_agent", "refund"],
        }
    },
]

dataset_name = "Chinook Customer Service Bot: E2E"

if not client.has_dataset(dataset_name=dataset_name):
    dataset = client.create_dataset(dataset_name=dataset_name)
    client.create_examples(
        dataset_id=dataset.id,
        examples=examples
)我们会创建一个自定义的 LLM-as-judge 评估器,用另一个模型把我们 agent 在每个示例上的输出与参考响应进行比较,并判断它们是否等价:
python
# LLM-as-judge instructions
grader_instructions = """You are a teacher grading a quiz.

You will be given a QUESTION, the GROUND TRUTH (correct) RESPONSE, and the STUDENT RESPONSE.

Here is the grade criteria to follow:
(1) Grade the student responses based ONLY on their factual accuracy relative to the ground truth answer.
(2) Ensure that the student response does not contain any conflicting statements.
(3) It is OK if the student response contains more information than the ground truth response, as long as it is factually accurate relative to the  ground truth response.

Correctness:
True means that the student's response meets all of the criteria.
False means that the student's response does not meet all of the criteria.

Explain your reasoning in a step-by-step manner to ensure your reasoning and conclusion are correct."""

# LLM-as-judge output schema
class Grade(TypedDict):
    """Compare the expected and actual answers and grade the actual answer."""
    reasoning: Annotated[str, ..., "Explain your reasoning for whether the actual response is correct or not."]
    is_correct: Annotated[bool, ..., "True if the student response is mostly or exactly correct, otherwise False."]

# Judge LLM
grader_llm = init_chat_model("gpt-5.4-mini", temperature=0).with_structured_output(Grade, method="json_schema", strict=True)

# Evaluator function
async def final_answer_correct(inputs: dict, outputs: dict, reference_outputs: dict) -> bool:
    """Evaluate if the final response is equivalent to reference response."""

    # Note that we assume the outputs has a 'response' dictionary. We'll need to make sure
    # that the target function we define includes this key.
    user = f"""QUESTION: {inputs['question']}
    GROUND TRUTH RESPONSE: {reference_outputs['response']}
    STUDENT RESPONSE: {outputs['response']}"""

    grade = await grader_llm.ainvoke([{"role": "system", "content": grader_instructions}, {"role": "user", "content": user}])
return grade["is_correct"]现在我们可以运行我们的评估。我们的评估器假定我们的目标函数返回一个 'response' 键,所以让我们定义一个这样做的目标函数。
还要记住,在我们的退款图中,我们让退款节点可配置,因此如果我们指定 config=""env": "test"",我们会 mock 掉退款而不实际更新数据库。我们会在调用图时,在目标 run_graph 方法中使用这个可配置变量:
python
# Target function
async def run_graph(inputs: dict) -> dict:
    """Run graph and track the trajectory it takes along with the final response."""
    result = await graph.ainvoke({"messages": [
        { "role": "user", "content": inputs['question']},
    ]}, config={"env": "test"})
    return {"response": result["followup"]}

# Evaluation job and results
experiment_results = await client.aevaluate(
    run_graph,
    data=dataset_name,
    evaluators=[final_answer_correct],
    experiment_prefix="sql-agent-gpt4o-e2e",
    num_repetitions=1,
    max_concurrency=4,
)
experiment_results.to_pandas()你可以在这里看到这些结果的样子:LangSmith 链接。
轨迹评估器
随着 agent 变得更复杂,它们有更多的潜在失败点。与其使用简单的通过/失败评估,不如使用能在 agent 采取了一些正确步骤(即便没得出正确的最终答案)时给予部分分数的评估,往往更好。
这就是轨迹评估的用武之地。一个轨迹评估:
- 把 agent 实际采取的步骤序列与一个预期序列进行比较
- 基于多少个预期步骤被正确完成来计算分数
对于这个示例,我们的端到端数据集包含一个我们期望 agent 采取的步骤有序列表。让我们创建一个评估器,把 agent 的实际轨迹与这些预期步骤比较,并计算完成了多少百分比:
python
def trajectory_subsequence(outputs: dict, reference_outputs: dict) -> float:
    """Check how many of the desired steps the agent took."""
    if len(reference_outputs['trajectory']) > len(outputs['trajectory']):
        return False

    i = j = 0
    while i < len(reference_outputs['trajectory']) and j < len(outputs['trajectory']):
        if reference_outputs['trajectory'][i] == outputs['trajectory'][j]:
            i += 1
        j += 1

return i / len(reference_outputs['trajectory'])现在我们可以运行我们的评估。我们的评估器假定我们的目标函数返回一个 'trajectory' 键,所以让我们定义一个这样做的目标函数。我们需要用 LangGraph 的流式能力来记录轨迹。
注意我们在复用最终响应评估所用的同一个数据集,因此我们可以把两个评估器一起运行并定义一个同时返回 "response" 和 "trajectory" 的目标函数。在实践中,为每种评估类型准备分开的数据集往往很有用,这也是我们在此把它们分开演示的原因:
python
async def run_graph(inputs: dict) -> dict:
    """Run graph and track the trajectory it takes along with the final response."""
    trajectory = []
    # Set subgraph=True to stream events from subgraphs of the main graph: https://docs.langchain.com/oss/langgraph/streaming#subgraph-outputs
    # Set stream_mode="debug" to stream all possible events: https://docs.langchain.com/oss/langgraph/streaming#debug
    async for namespace, chunk in graph.astream({"messages": [
            {
                "role": "user",
                "content": inputs['question'],
            }
        ]}, subgraphs=True, stream_mode="debug"):
        # Event type for entering a node
        if chunk['type'] == 'task':
            # Record the node name
            trajectory.append(chunk['payload']['name'])
            # Given how we defined our dataset, we also need to track when specific tools are
            # called by our question answering ReACT agent. These tool calls can be found
            # when the ToolsNode (named "tools") is invoked by looking at the AIMessage.tool_calls
            # of the latest input message.
            if chunk['payload']['name'] == 'tools' and chunk['type'] == 'task':
                for tc in chunk['payload']['input']['messages'][-1].tool_calls:
                    trajectory.append(tc['name'])
    return {"trajectory": trajectory}

experiment_results = await client.aevaluate(
    run_graph,
    data=dataset_name,
    evaluators=[trajectory_subsequence],
    experiment_prefix="sql-agent-gpt4o-trajectory",
    num_repetitions=1,
    max_concurrency=4,
)
experiment_results.to_pandas()你可以在这里看到这些结果的样子:LangSmith 链接。
单步评估器
虽然端到端测试给你的 agent 性能信号最多,但为了调试和迭代你的 agent,定位并直接评估那些困难的特定步骤可能很有帮助。
在我们的情形中,agent 的一个关键在于它把用户的意图正确路由到"退款"路径或"问答"路径。让我们创建一个数据集并运行一些评估,来直接对这一个组件做压力测试。
python
# Create dataset
examples = [
    {
        "inputs": {"messages": [{"role": "user", "content": "i bought some tracks recently and i dont like them"}]},
        "outputs": {"route": "refund_agent"},
    },
    {
        "inputs": {"messages": [{"role": "user", "content": "I was thinking of purchasing some Rolling Stones tunes, any recommendations?"}]},
        "outputs": {"route": "question_answering_agent"},
    },
    {
        "inputs": {"messages": [{"role": "user", "content": "i want a refund on purchase 237"}, {"role": "assistant", "content": "I've refunded you a total of $1.98. How else can I help you today?"}, {"role": "user", "content": "did prince release any albums in 2000?"}]},
        "outputs": {"route": "question_answering_agent"},
    },
    {
        "inputs": {"messages": [{"role": "user", "content": "i purchased a cover of Yesterday recently but can't remember who it was by, which versions of it do you have?"}]},
        "outputs": {"route": "question_answering_agent"},
    },
]

dataset_name = "Chinook Customer Service Bot: Intent Classifier"
if not client.has_dataset(dataset_name=dataset_name):
    dataset = client.create_dataset(dataset_name=dataset_name)
    client.create_examples(
        dataset_id=dataset.id,
        examples=examples
    )

# Evaluator
def correct(outputs: dict, reference_outputs: dict) -> bool:
    """Check if the agent chose the correct route."""
    return outputs["route"] == reference_outputs["route"]

# Target function for running the relevant step
async def run_intent_classifier(inputs: dict) -> dict:
    # Note that we can access and run the intent_classifier node of our graph directly.
    command = await graph.nodes['intent_classifier'].ainvoke(inputs)
    return {"route": command.goto}

# Run evaluation
experiment_results = await client.aevaluate(
    run_intent_classifier,
    data=dataset_name,
    evaluators=[correct],
    experiment_prefix="sql-agent-gpt4o-intent-classifier",
    max_concurrency=4,
)你可以在这里看到这些结果的样子:LangSmith 链接。
参考代码
这里是包含上面所有代码的一个合并脚本:
Reference code
python
import json
import sqlite3
from typing import Literal

from langchain.chat_models import init_chat_model
from langchain.embeddings import init_embeddings
from langchain_core.runnables import RunnableConfig
from langchain.tools import tool
from langchain_core.vectorstores import InMemoryVectorStore
from langgraph.graph import END, StateGraph
from langgraph.graph.message import AnyMessage, add_messages
from langchain.agents import create_agent
from langgraph.types import Command, interrupt
from langsmith import Client
import requests
from tabulate import tabulate
from typing_extensions import Annotated, TypedDict

url = "https://storage.googleapis.com/benchmarks-artifacts/chinook/Chinook.db"

response = requests.get(url)

if response.status_code == 200:
    # Open a local file in binary write mode
    with open("chinook.db", "wb") as file:
        # Write the content of the response (the file) to the local file
        file.write(response.content)
    print("File downloaded and saved as Chinook.db")
else:
    print(f"Failed to download the file. Status code: {response.status_code}")

def _refund(
    invoice_id: int | None, invoice_line_ids: list[int] | None, mock: bool = False
) -> float:
    """Given an Invoice ID and/or Invoice Line IDs, delete the relevant Invoice/InvoiceLine records in the Chinook DB.

    Args:
        invoice_id: The Invoice to delete.
        invoice_line_ids: The Invoice Lines to delete.
        mock: If True, do not actually delete the specified Invoice/Invoice Lines. Used for testing purposes.

    Returns:
        float: The total dollar amount that was deleted (or mock deleted).
    """

    if invoice_id is None and invoice_line_ids is None:
        return 0.0

    # Connect to the Chinook database
    conn = sqlite3.connect("chinook.db")
    cursor = conn.cursor()

    total_refund = 0.0

    try:
        # If invoice_id is provided, delete entire invoice and its lines
        if invoice_id is not None:
            # First get the total amount for the invoice
            cursor.execute(
                """
                SELECT Total
                FROM Invoice
                WHERE InvoiceId = ?
            """,
                (invoice_id,),
            )

            result = cursor.fetchone()
            if result:
                total_refund += result[0]

            # Delete invoice lines first (due to foreign key constraints)
            if not mock:
                cursor.execute(
                    """
                    DELETE FROM InvoiceLine
                    WHERE InvoiceId = ?
                """,
                    (invoice_id,),
                )

                # Then delete the invoice
                cursor.execute(
                    """
                    DELETE FROM Invoice
                    WHERE InvoiceId = ?
                """,
                    (invoice_id,),
                )

        # If specific invoice lines are provided
        if invoice_line_ids is not None:
            # Get the total amount for the specified invoice lines
            placeholders = ",".join(["?" for _ in invoice_line_ids])
            cursor.execute(
                f"""
                SELECT SUM(UnitPrice * Quantity)
                FROM InvoiceLine
                WHERE InvoiceLineId IN ({placeholders})
            """,
                invoice_line_ids,
            )

            result = cursor.fetchone()
            if result and result[0]:
                total_refund += result[0]

            if not mock:
                # Delete the specified invoice lines
                cursor.execute(
                    f"""
                    DELETE FROM InvoiceLine
                    WHERE InvoiceLineId IN ({placeholders})
                """,
                    invoice_line_ids,
                )

        # Commit the changes
        conn.commit()

    except sqlite3.Error as e:
        # Roll back in case of error
        conn.rollback()
        raise e

    finally:
        # Close the connection
        conn.close()

    return float(total_refund)

def _lookup(
    customer_first_name: str,
    customer_last_name: str,
    customer_phone: str,
    track_name: str | None,
    album_title: str | None,
    artist_name: str | None,
    purchase_date_iso_8601: str | None,
) -> list[dict]:
    """Find all of the Invoice Line IDs in the Chinook DB for the given filters.

    Returns:
        a list of dictionaries that contain keys: {
            'invoice_line_id',
            'track_name',
            'artist_name',
            'purchase_date',
            'quantity_purchased',
            'price_per_unit'
        }
    """

    # Connect to the database
    conn = sqlite3.connect("chinook.db")
    cursor = conn.cursor()

    # Base query joining all necessary tables
    query = """
    SELECT
        il.InvoiceLineId,
        t.Name as track_name,
        art.Name as artist_name,
        i.InvoiceDate as purchase_date,
        il.Quantity as quantity_purchased,
        il.UnitPrice as price_per_unit
    FROM InvoiceLine il
    JOIN Invoice i ON il.InvoiceId = i.InvoiceId
    JOIN Customer c ON i.CustomerId = c.CustomerId
    JOIN Track t ON il.TrackId = t.TrackId
    JOIN Album alb ON t.AlbumId = alb.AlbumId
    JOIN Artist art ON alb.ArtistId = art.ArtistId
    WHERE c.FirstName = ?
    AND c.LastName = ?
    AND c.Phone = ?
    """

    # Parameters for the query
    params = [customer_first_name, customer_last_name, customer_phone]

    # Add optional filters
    if track_name:
        query += " AND t.Name = ?"
        params.append(track_name)

    if album_title:
        query += " AND alb.Title = ?"
        params.append(album_title)

    if artist_name:
        query += " AND art.Name = ?"
        params.append(artist_name)

    if purchase_date_iso_8601:
        query += " AND date(i.InvoiceDate) = date(?)"
        params.append(purchase_date_iso_8601)

    # Execute query
    cursor.execute(query, params)

    # Fetch results
    results = cursor.fetchall()

    # Convert results to list of dictionaries
    output = []
    for row in results:
        output.append(
            {
                "invoice_line_id": row[0],
                "track_name": row[1],
                "artist_name": row[2],
                "purchase_date": row[3],
                "quantity_purchased": row[4],
                "price_per_unit": row[5],
            }
        )

    # Close connection
    conn.close()

    return output

# Graph state.
class State(TypedDict):
    """Agent state."""

    messages: Annotated[list[AnyMessage], add_messages]
    followup: str | None

    invoice_id: int | None
    invoice_line_ids: list[int] | None
    customer_first_name: str | None
    customer_last_name: str | None
    customer_phone: str | None
    track_name: str | None
    album_title: str | None
    artist_name: str | None
    purchase_date_iso_8601: str | None

# Instructions for extracting the user/purchase info from the conversation.
gather_info_instructions = """You are managing an online music store that sells song tracks. \
Customers can buy multiple tracks at a time and these purchases are recorded in a database as \
an Invoice per purchase and an associated set of Invoice Lines for each purchased track.

Your task is to help customers who would like a refund for one or more of the tracks they've \
purchased. In order for you to be able refund them, the customer must specify the Invoice ID \
to get a refund on all the tracks they bought in a single transaction, or one or more Invoice \
Line IDs if they would like refunds on individual tracks.

Often a user will not know the specific Invoice ID(s) or Invoice Line ID(s) for which they \
would like a refund. In this case you can help them look up their invoices by asking them to \
specify:
- Required: Their first name, last name, and phone number.
- Optionally: The track name, artist name, album name, or purchase date.

If the customer has not specified the required information (either Invoice/Invoice Line IDs \
or first name, last name, phone) then please ask them to specify it."""

# Extraction schema, mirrors the graph state.
class PurchaseInformation(TypedDict):
    """All of the known information about the invoice / invoice lines the customer would like refunded. Do not make up values, leave fields as null if you don't know their value."""

    invoice_id: int | None
    invoice_line_ids: list[int] | None
    customer_first_name: str | None
    customer_last_name: str | None
    customer_phone: str | None
    track_name: str | None
    album_title: str | None
    artist_name: str | None
    purchase_date_iso_8601: str | None
    followup: Annotated[
        str | None,
        ...,
        "If the user hasn't enough identifying information, please tell them what the required information is and ask them to specify it.",
    ]

# Model for performing extraction.
info_llm = init_chat_model("gpt-5.4-mini").with_structured_output(
    PurchaseInformation, method="json_schema", include_raw=True
)

# Graph node for extracting user info and routing to lookup/refund/END.
async def gather_info(state: State) -> Command[Literal["lookup", "refund", END]]:
    info = await info_llm.ainvoke(
        [
            {"role": "system", "content": gather_info_instructions},
            *state["messages"],
        ]
    )
    parsed = info["parsed"]
    if any(parsed[k] for k in ("invoice_id", "invoice_line_ids")):
        goto = "refund"
    elif all(
        parsed[k]
        for k in ("customer_first_name", "customer_last_name", "customer_phone")
    ):
        goto = "lookup"
    else:
        goto = END
    update = {"messages": [info["raw"]], **parsed}
    return Command(update=update, goto=goto)

# Graph node for executing the refund.
# Note that here we inspect the runtime config for an "env" variable.
# If "env" is set to "test", then we don't actually delete any rows from our database.
# This will become important when we're running our evaluations.
def refund(state: State, config: RunnableConfig) -> dict:
    # Whether to mock the deletion. True if the configurable var 'env' is set to 'test'.
    mock = config.get("configurable", {}).get("env", "prod") == "test"
    refunded = _refund(
        invoice_id=state["invoice_id"],
        invoice_line_ids=state["invoice_line_ids"],
        mock=mock,
    )
    response = f"You have been refunded a total of: ${refunded:.2f}. Is there anything else I can help with?"
    return {
        "messages": [{"role": "assistant", "content": response}],
        "followup": response,
    }

# Graph node for looking up the users purchases
def lookup(state: State) -> dict:
    args = (
        state[k]
        for k in (
            "customer_first_name",
            "customer_last_name",
            "customer_phone",
            "track_name",
            "album_title",
            "artist_name",
            "purchase_date_iso_8601",
        )
    )
    results = _lookup(*args)
    if not results:
        response = "We did not find any purchases associated with the information you've provided. Are you sure you've entered all of your information correctly?"
        followup = response
    else:
        response = f"Which of the following purchases would you like to be refunded for?\n\n```json{json.dumps(results, indent=2)}\n```"
        followup = f"Which of the following purchases would you like to be refunded for?\n\n{tabulate(results, headers='keys')}"
    return {
        "messages": [{"role": "assistant", "content": response}],
        "followup": followup,
        "invoice_line_ids": [res["invoice_line_id"] for res in results],
    }

# Building our graph
graph_builder = StateGraph(State)

graph_builder.add_node(gather_info)
graph_builder.add_node(refund)
graph_builder.add_node(lookup)

graph_builder.set_entry_point("gather_info")
graph_builder.add_edge("lookup", END)
graph_builder.add_edge("refund", END)

refund_graph = graph_builder.compile()

# Our SQL queries will only work if we filter on the exact string values that are in the DB.
# To ensure this, we'll create vectorstore indexes for all of the artists, tracks and albums
# ahead of time and use those to disambiguate the user input. E.g. if a user searches for
# songs by "prince" and our DB records the artist as "Prince", ideally when we query our
# artist vectorstore for "prince" we'll get back the value "Prince", which we can then
# use in our SQL queries.
def index_fields() -> (
    tuple[InMemoryVectorStore, InMemoryVectorStore, InMemoryVectorStore]
):
    """Create an index for all artists, an index for all albums, and an index for all songs."""
    try:
        # Connect to the chinook database
        conn = sqlite3.connect("chinook.db")
        cursor = conn.cursor()

        # Fetch all results
        tracks = cursor.execute("SELECT Name FROM Track").fetchall()
        artists = cursor.execute("SELECT Name FROM Artist").fetchall()
        albums = cursor.execute("SELECT Title FROM Album").fetchall()
    finally:
        # Close the connection
        if conn:
            conn.close()

    embeddings = init_embeddings("openai:text-embedding-3-small")

    track_store = InMemoryVectorStore(embeddings)
    artist_store = InMemoryVectorStore(embeddings)
    album_store = InMemoryVectorStore(embeddings)

    track_store.add_texts([t[0] for t in tracks])
    artist_store.add_texts([a[0] for a in artists])
    album_store.add_texts([a[0] for a in albums])
    return track_store, artist_store, album_store

track_store, artist_store, album_store = index_fields()

# Agent tools
@tool
def lookup_track(
    track_name: str | None = None,
    album_title: str | None = None,
    artist_name: str | None = None,
) -> list[dict]:
    """Lookup a track in Chinook DB based on identifying information about.

    Returns:
        a list of dictionaries per matching track that contain keys {'track_name', 'artist_name', 'album_name'}
    """
    conn = sqlite3.connect("chinook.db")
    cursor = conn.cursor()

    query = """
    SELECT DISTINCT t.Name as track_name, ar.Name as artist_name, al.Title as album_name
    FROM Track t
    JOIN Album al ON t.AlbumId = al.AlbumId
    JOIN Artist ar ON al.ArtistId = ar.ArtistId
    WHERE 1=1
    """
    params = []

    if track_name:
        track_name = track_store.similarity_search(track_name, k=1)[0].page_content
        query += " AND t.Name LIKE ?"
        params.append(f"%{track_name}%")
    if album_title:
        album_title = album_store.similarity_search(album_title, k=1)[0].page_content
        query += " AND al.Title LIKE ?"
        params.append(f"%{album_title}%")
    if artist_name:
        artist_name = artist_store.similarity_search(artist_name, k=1)[0].page_content
        query += " AND ar.Name LIKE ?"
        params.append(f"%{artist_name}%")

    cursor.execute(query, params)
    results = cursor.fetchall()

    tracks = [
        {"track_name": row[0], "artist_name": row[1], "album_name": row[2]}
        for row in results
    ]

    conn.close()
    return tracks

@tool
def lookup_album(
    track_name: str | None = None,
    album_title: str | None = None,
    artist_name: str | None = None,
) -> list[dict]:
    """Lookup an album in Chinook DB based on identifying information about.

    Returns:
        a list of dictionaries per matching album that contain keys {'album_name', 'artist_name'}
    """
    conn = sqlite3.connect("chinook.db")
    cursor = conn.cursor()

    query = """
    SELECT DISTINCT al.Title as album_name, ar.Name as artist_name
    FROM Album al
    JOIN Artist ar ON al.ArtistId = ar.ArtistId
    LEFT JOIN Track t ON t.AlbumId = al.AlbumId
    WHERE 1=1
    """
    params = []

    if track_name:
        query += " AND t.Name LIKE ?"
        params.append(f"%{track_name}%")
    if album_title:
        query += " AND al.Title LIKE ?"
        params.append(f"%{album_title}%")
    if artist_name:
        query += " AND ar.Name LIKE ?"
        params.append(f"%{artist_name}%")

    cursor.execute(query, params)
    results = cursor.fetchall()

    albums = [{"album_name": row[0], "artist_name": row[1]} for row in results]

    conn.close()
    return albums

@tool
def lookup_artist(
    track_name: str | None = None,
    album_title: str | None = None,
    artist_name: str | None = None,
) -> list[str]:
    """Lookup an album in Chinook DB based on identifying information about.

    Returns:
        a list of matching artist names
    """
    conn = sqlite3.connect("chinook.db")
    cursor = conn.cursor()

    query = """
    SELECT DISTINCT ar.Name as artist_name
    FROM Artist ar
    LEFT JOIN Album al ON al.ArtistId = ar.ArtistId
    LEFT JOIN Track t ON t.AlbumId = al.AlbumId
    WHERE 1=1
    """
    params = []

    if track_name:
        query += " AND t.Name LIKE ?"
        params.append(f"%{track_name}%")
    if album_title:
        query += " AND al.Title LIKE ?"
        params.append(f"%{album_title}%")
    if artist_name:
        query += " AND ar.Name LIKE ?"
        params.append(f"%{artist_name}%")

    cursor.execute(query, params)
    results = cursor.fetchall()

    artists = [row[0] for row in results]

    conn.close()
    return artists

# Agent model
qa_llm = init_chat_model("claude-sonnet-4-6")
# The prebuilt ReACT agent only expects State to have a 'messages' key, so the
# state we defined for the refund agent can also be passed to our lookup agent.
qa_graph = create_agent(qa_llm, [lookup_track, lookup_artist, lookup_album])

# Schema for routing user intent.
# We'll use structured output to enforce that the model returns only
# the desired output.
class UserIntent(TypedDict):
    """The user's current intent in the conversation"""

    intent: Literal["refund", "question_answering"]

# Routing model with structured output
router_llm = init_chat_model("gpt-5.4-mini").with_structured_output(
    UserIntent, method="json_schema", strict=True
)

# Instructions for routing.
route_instructions = """You are managing an online music store that sells song tracks. \
You can help customers in two types of ways: (1) answering general questions about \
tracks sold at your store, (2) helping them get a refund on a purhcase they made at your store.

Based on the following conversation, determine if the user is currently seeking general \
information about song tracks or if they are trying to refund a specific purchase.

Return 'refund' if they are trying to get a refund and 'question_answering' if they are \
asking a general music question. Do NOT return anything else. Do NOT try to respond to \
the user.
"""

# Node for routing.
async def intent_classifier(
    state: State,
) -> Command[Literal["refund_agent", "question_answering_agent"]]:
    response = router_llm.invoke(
        [{"role": "system", "content": route_instructions}, *state["messages"]]
    )
    return Command(goto=response["intent"] + "_agent")

# Node for making sure the 'followup' key is set before our agent run completes.
def compile_followup(state: State) -> dict:
    """Set the followup to be the last message if it hasn't explicitly been set."""
    if not state.get("followup"):
        return {"followup": state["messages"][-1].content}
    return {}

# Agent definition
graph_builder = StateGraph(State)
graph_builder.add_node(intent_classifier)
# Since all of our subagents have compatible state,
# we can add them as nodes directly.
graph_builder.add_node("refund_agent", refund_graph)
graph_builder.add_node("question_answering_agent", qa_graph)
graph_builder.add_node(compile_followup)

graph_builder.set_entry_point("intent_classifier")
graph_builder.add_edge("refund_agent", "compile_followup")
graph_builder.add_edge("question_answering_agent", "compile_followup")
graph_builder.add_edge("compile_followup", END)

graph = graph_builder.compile()

client = Client()

# Create a dataset
examples = [
    {
        "inputs": {
            "question": "How many songs do you have by James Brown"
        },
        "outputs": {
            "response": "We have 20 songs by James Brown",
            "trajectory": ["question_answering_agent", "lookup_tracks"]
        },
    },
    {
        "inputs": {
            "question": "My name is Aaron Mitchell and I'd like a refund.",
        },
        "outputs": {
            "response": "I need some more information to help you with the refund. Please specify your phone number, the invoice ID, or the line item IDs for the purchase you'd like refunded.",
            "trajectory": ["refund_agent"],
        }
    },
    {
        "inputs": {
            "question": "My name is Aaron Mitchell and I'd like a refund on my Led Zeppelin purchases. My number is +1 (204) 452-6452",
        },
        "outputs": {
            "response": "Which of the following purchases would you like to be refunded for?\n\n  invoice_line_id  track_name                        artist_name    purchase_date          quantity_purchased    price_per_unit\n-----------------  --------------------------------  -------------  -------------------  --------------------  ----------------\n              267  How Many More Times               Led Zeppelin   2009-08-06 00:00:00                     1              0.99\n              268  What Is And What Should Never Be  Led Zeppelin   2009-08-06 00:00:00                     1              0.99",
            "trajectory": ["refund_agent", "lookup"],
        },
    },
    {
        "inputs": {
            "question": "Who recorded Wish You Were Here again? What other albums of there's do you have?",
        },
        "outputs": {
            "response": "Wish You Were Here is an album by Pink Floyd",
            "trajectory": ["question_answering_agent", "lookup_album"],
        }
    },
    {
        "inputs": {
            "question": "I want a full refund for invoice 237",
        },
        "outputs": {
            "response": "You have been refunded $2.97.",
            "trajectory": ["refund_agent", "refund"],
        },
    },
]

dataset_name = "Chinook Customer Service Bot: E2E"

if not client.has_dataset(dataset_name=dataset_name):
    dataset = client.create_dataset(dataset_name=dataset_name)
    client.create_examples(
        dataset_id=dataset.id,
        examples=examples
    )

# LLM-as-judge instructions
grader_instructions = """You are a teacher grading a quiz.

You will be given a QUESTION, the GROUND TRUTH (correct) RESPONSE, and the STUDENT RESPONSE.

Here is the grade criteria to follow:
(1) Grade the student responses based ONLY on their factual accuracy relative to the ground truth answer.
(2) Ensure that the student response does not contain any conflicting statements.
(3) It is OK if the student response contains more information than the ground truth response, as long as it is factually accurate relative to the  ground truth response.

Correctness:
True means that the student's response meets all of the criteria.
False means that the student's response does not meet all of the criteria.

Explain your reasoning in a step-by-step manner to ensure your reasoning and conclusion are correct."""

# LLM-as-judge output schema
class Grade(TypedDict):
    """Compare the expected and actual answers and grade the actual answer."""

    reasoning: Annotated[
        str,
        ...,
        "Explain your reasoning for whether the actual response is correct or not.",
    ]
    is_correct: Annotated[
        bool,
        ...,
        "True if the student response is mostly or exactly correct, otherwise False.",
    ]

# Judge LLM
grader_llm = init_chat_model("gpt-5.4-mini", temperature=0).with_structured_output(
    Grade, method="json_schema", strict=True
)

# Evaluator function
async def final_answer_correct(
    inputs: dict, outputs: dict, reference_outputs: dict
) -> bool:
    """Evaluate if the final response is equivalent to reference response."""

    # Note that we assume the outputs has a 'response' dictionary. We'll need to make sure
    # that the target function we define includes this key.
    user = f"""QUESTION: {inputs['question']}
    GROUND TRUTH RESPONSE: {reference_outputs['response']}
    STUDENT RESPONSE: {outputs['response']}"""

    grade = await grader_llm.ainvoke(
        [
            {"role": "system", "content": grader_instructions},
            {"role": "user", "content": user},
        ]
    )
    return grade["is_correct"]

# Target function
async def run_graph(inputs: dict) -> dict:
    """Run graph and track the trajectory it takes along with the final response."""
    result = await graph.ainvoke(
        {
            "messages": [
                {"role": "user", "content": inputs["question"]},
            ]
        },
        config={"env": "test"},
    )
    return {"response": result["followup"]}

# Evaluation job and results
experiment_results = await client.aevaluate(
    run_graph,
    data=dataset_name,
    evaluators=[final_answer_correct],
    experiment_prefix="sql-agent-gpt4o-e2e",
    num_repetitions=1,
    max_concurrency=4,
)
experiment_results.to_pandas()

def trajectory_subsequence(outputs: dict, reference_outputs: dict) -> float:
    """Check how many of the desired steps the agent took."""
    if len(reference_outputs["trajectory"]) > len(outputs["trajectory"]):
        return False

    i = j = 0
    while i < len(reference_outputs["trajectory"]) and j < len(outputs["trajectory"]):
        if reference_outputs["trajectory"][i] == outputs["trajectory"][j]:
            i += 1
        j += 1

    return i / len(reference_outputs["trajectory"])

async def run_graph(inputs: dict) -> dict:
    """Run graph and track the trajectory it takes along with the final response."""
    trajectory = []
    # Set subgraph=True to stream events from subgraphs of the main graph: https://docs.langchain.com/oss/langgraph/streaming#subgraph-outputs
    # Set stream_mode="debug" to stream all possible events: https://docs.langchain.com/oss/langgraph/streaming#debug
    async for namespace, chunk in graph.astream(
        {
            "messages": [
                {
                    "role": "user",
                    "content": inputs["question"],
                }
            ]
        },
        subgraphs=True,
        stream_mode="debug",
    ):
        # Event type for entering a node
        if chunk["type"] == "task":
            # Record the node name
            trajectory.append(chunk["payload"]["name"])
            # Given how we defined our dataset, we also need to track when specific tools are
            # called by our question answering ReACT agent. These tool calls can be found
            # when the ToolsNode (named "tools") is invoked by looking at the AIMessage.tool_calls
            # of the latest input message.
            if chunk["payload"]["name"] == "tools" and chunk["type"] == "task":
                for tc in chunk["payload"]["input"]["messages"][-1].tool_calls:
                    trajectory.append(tc["name"])

    return {"trajectory": trajectory}

experiment_results = await client.aevaluate(
    run_graph,
    data=dataset_name,
    evaluators=[trajectory_subsequence],
    experiment_prefix="sql-agent-gpt4o-trajectory",
    num_repetitions=1,
    max_concurrency=4,
)
experiment_results.to_pandas()

# Create dataset
examples = [
    {
        "inputs": {
            "messages": [
                {
                    "role": "user",
                    "content": "i bought some tracks recently and i dont like them",
                }
            ],
        }
        "outputs": {"route": "refund_agent"},
    },
    {
        "inputs": {
            "messages": [
                {
                    "role": "user",
                    "content": "I was thinking of purchasing some Rolling Stones tunes, any recommendations?",
                }
            ],
        },
        "outputs": {"route": "question_answering_agent"},
    },
    {
        "inputs": {
            "messages": [
                    {"role": "user", "content": "i want a refund on purchase 237"},
                {
                    "role": "assistant",
                    "content": "I've refunded you a total of $1.98. How else can I help you today?",
                },
                {"role": "user", "content": "did prince release any albums in 2000?"},
            ],
        },
        "outputs": {"route": "question_answering_agent"},
    },
    {
        "inputs": {
            "messages": [
                {
                    "role": "user",
                    "content": "i purchased a cover of Yesterday recently but can't remember who it was by, which versions of it do you have?",
                }
            ],
        },
        "outputs": {"route": "question_answering_agent"},
    },
]

dataset_name = "Chinook Customer Service Bot: Intent Classifier"
if not client.has_dataset(dataset_name=dataset_name):
    dataset = client.create_dataset(dataset_name=dataset_name)
    client.create_examples(
        dataset_id=dataset.id,
        examples=examples,
    )

# Evaluator
def correct(outputs: dict, reference_outputs: dict) -> bool:
    """Check if the agent chose the correct route."""
    return outputs["route"] == reference_outputs["route"]

# Target function for running the relevant step
async def run_intent_classifier(inputs: dict) -> dict:
    # Note that we can access and run the intent_classifier node of our graph directly.
    command = await graph.nodes["intent_classifier"].ainvoke(inputs)
    return {"route": command.goto}

# Run evaluation
experiment_results = await client.aevaluate(
    run_intent_classifier,
    data=dataset_name,
    evaluators=[correct],
    experiment_prefix="sql-agent-gpt4o-intent-classifier",
    max_concurrency=4,
)
experiment_results.to_pandas()