
主题
使用图 API
本指南演示 LangGraph 图 API 的基础知识。它涵盖了状态,以及组合常见的图结构,例如序列、分支和循环。它还涵盖了 LangGraph 的控制特性,包括用于 map-reduce 工作流的 Send API,以及用于将状态更新与跨节点「跳转」相结合的 Command API。
设置
安装 langgraph:
bash
pip install -U langgraphbash
uv add langgraphTIP
设置 LangSmith 以获得更好的调试体验
注册 LangSmith,以快速发现问题并提升你的 LangGraph 项目的性能。LangSmith 让你可以使用追踪数据来调试、测试和监控使用 LangGraph 构建的 LLM 应用——在文档中阅读更多关于如何开始的内容。
定义和更新状态
这里我们展示如何在 LangGraph 中定义和更新状态。我们将演示:
定义状态
LangGraph 中的状态可以是 TypedDict、Pydantic 模型或 dataclass。下面我们将使用 TypedDict。有关使用 Pydantic 的详细信息,请参见为图状态使用 Pydantic 模型。
默认情况下,图将具有相同的输入和输出 schema,而状态决定该 schema。有关如何定义不同的输入和输出 schema,请参见定义输入和输出 schema。
让我们考虑一个使用 messages 的简单示例。它为许多 LLM 应用提供了一种通用的状态表述形式。更多细节请参阅我们的概念页面。
python
from langchain.messages import AnyMessage
from typing_extensions import TypedDict

class State(TypedDict):
    messages: list[AnyMessage]
extra_field: int该状态跟踪一个 message 对象列表,以及一个额外的整数字段。
更新状态
让我们构建一个包含单个节点的示例图。我们的节点只是一个读取图状态并对其进行更新的 Python 函数。此函数的第一个参数始终是状态:
python
from langchain.messages import AIMessage

def node(state: State):
    messages = state["messages"]
    new_message = AIMessage("Hello!")
return {"messages": messages + [new_message], "extra_field": 10}该节点只是向我们的消息列表追加一条消息,并填充一个额外字段。
WARNING
节点应直接返回对状态的更新,而不是改变状态本身。
接下来,我们定义一个包含此节点的简单图。我们使用 StateGraph 来定义一个作用于该状态的图。然后使用 add_node 填充我们的图。
python
from langgraph.graph import StateGraph

builder = StateGraph(State)
builder.add_node(node)
builder.set_entry_point("node")
graph = builder.compile()LangGraph 提供了用于可视化图的内置工具。让我们查看一下我们的图。有关可视化的详细信息,请参阅可视化你的图。
python
from IPython.display import Image, display

display(Image(graph.get_graph().draw_mermaid_png()))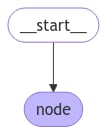
在这种情况下,我们的图只执行单个节点。让我们进行一个简单的调用:
python
from langchain.messages import HumanMessage

result = graph.invoke({"messages": [HumanMessage("Hi")]})
result{'messages': [HumanMessage(content='Hi'), AIMessage(content='Hello!')], 'extra_field': 10}注意:
- 我们通过更新状态中的单个键来发起调用。
- 我们在调用结果中收到整个状态。
为方便起见,我们经常通过 pretty-print 查看消息对象的内容:
python
for message in result["messages"]:
message.pretty_print()================================ Human Message ================================
Hi
================================== Ai Message ==================================
Hello!使用归约器处理状态更新
状态中的每个键都可以有自己的独立归约器函数,用于控制来自节点的更新如何被应用。如果未显式指定归约器函数,则假定对该键的所有更新都应覆盖它。
对于 TypedDict 状态模式,我们可以通过用归约器函数标注状态的相应字段来定义归约器。
在前面的示例中,我们的节点通过向状态中的 "messages" 键追加一条消息来更新它。下面,我们为该键添加一个归约器,使更新会自动追加:
python
from typing_extensions import Annotated

def add(left, right):
    """Can also import `add` from the `operator` built-in."""
    return left + right

class State(TypedDict):
    messages: Annotated[list[AnyMessage], add]
extra_field: int现在我们的节点可以简化了:
python
def node(state: State):
    new_message = AIMessage("Hello!")
return {"messages": [new_message], "extra_field": 10} python
from langgraph.graph import START

graph = StateGraph(State).add_node(node).add_edge(START, "node").compile()

result = graph.invoke({"messages": [HumanMessage("Hi")]})

for message in result["messages"]:
message.pretty_print()================================ Human Message ================================
Hi
================================== Ai Message ==================================
Hello!MessagesState
在实践中,更新消息列表还有一些额外的注意事项:
LangGraph 包含一个内置归约器 add_messages,可处理这些注意事项:
python
from langgraph.graph.message import add_messages

class State(TypedDict):
    messages: Annotated[list[AnyMessage], add_messages]
    extra_field: int

def node(state: State):
    new_message = AIMessage("Hello!")
    return {"messages": [new_message], "extra_field": 10}

graph = StateGraph(State).add_node(node).set_entry_point("node").compile()python
input_message = {"role": "user", "content": "Hi"}

result = graph.invoke({"messages": [input_message]})

for message in result["messages"]:
message.pretty_print()================================ Human Message ================================
Hi
================================== Ai Message ==================================
Hello!对于涉及聊天模型的应用来说,这是一种通用的状态表示形式。为方便起见,LangGraph 包含一个预构建的 MessagesState,这样我们就可以拥有:
python
from langgraph.graph import MessagesState

class State(MessagesState):
extra_field: int使用 Overwrite 绕开归约器
在某些情况下,你可能想绕开归约器并直接覆盖某个状态值。LangGraph 为此提供了 Overwrite 类型。当节点返回一个用 Overwrite 包装的值时,归约器会被绕开,通道会被直接设置为该值。
当你想要重置或替换累积的状态,而不是将其与现有值合并时,这很有用。
python
from langgraph.graph import StateGraph, START, END
from langgraph.types import Overwrite
from typing_extensions import Annotated, TypedDict
import operator

class State(TypedDict):
    messages: Annotated[list, operator.add]

def add_message(state: State):
    return {"messages": ["first message"]}

def replace_messages(state: State):
    # Bypass the reducer and replace the entire messages list
    return {"messages": Overwrite(["replacement message"])}

builder = StateGraph(State)
builder.add_node("add_message", add_message)
builder.add_node("replace_messages", replace_messages)
builder.add_edge(START, "add_message")
builder.add_edge("add_message", "replace_messages")
builder.add_edge("replace_messages", END)

graph = builder.compile()

result = graph.invoke({"messages": ["initial"]})
print(result["messages"])['replacement message']你也可以使用带有特殊键 "__overwrite__" 的 JSON 格式:
python
def replace_messages(state: State):
return {"messages": {"__overwrite__": ["replacement message"]}}WARNING
当节点并行执行时,在给定的 super-step 中,只有一个节点可以在同一个状态键上使用 Overwrite。如果多个节点试图在同一个 super-step 中覆盖同一个键,将引发 InvalidUpdateError。
定义输入和输出模式
默认情况下,StateGraph 使用单一模式运行,所有节点都应使用该模式进行通信。不过,也可以为图定义不同的输入和输出模式。
当指定了不同的模式时,节点之间的通信仍将使用一个内部模式。输入模式确保提供的输入与预期结构匹配,而输出模式则过滤内部数据,仅根据定义的输出模式返回相关信息。
下面,我们将了解如何定义不同的输入和输出模式。
python
from langgraph.graph import StateGraph, START, END
from typing_extensions import TypedDict

# Define the schema for the input
class InputState(TypedDict):
    question: str

# Define the schema for the output
class OutputState(TypedDict):
    answer: str

# Define the overall schema, combining both input and output
class OverallState(InputState, OutputState):
    pass

# Define the node that processes the input and generates an answer
def answer_node(state: InputState):
    # Example answer and an extra key
    return {"answer": "bye", "question": state["question"]}

# Build the graph with input and output schemas specified
builder = StateGraph(OverallState, input_schema=InputState, output_schema=OutputState)
builder.add_node(answer_node)  # Add the answer node
builder.add_edge(START, "answer_node")  # Define the starting edge
builder.add_edge("answer_node", END)  # Define the ending edge
graph = builder.compile()  # Compile the graph

# Invoke the graph with an input and print the result
print(graph.invoke({"question": "hi"})){'answer': 'bye'}请注意,invoke 的输出仅包含输出模式。
在节点之间传递私有状态
在某些情况下,你可能希望节点之间交换对中间逻辑至关重要但无需成为图主模式一部分的信息。这些私有数据与图的整体输入/输出无关,只应在特定节点之间共享。
下面,我们将创建一个由三个节点(node_1、node_2 和 node_3)组成的示例顺序图,其中私有数据在前两步(node_1 和 node_2)之间传递,而第三步(node_3)只能访问公开的整体状态。
python
from langgraph.graph import StateGraph, START, END
from typing_extensions import TypedDict

# The overall state of the graph (this is the public state shared across nodes)
class OverallState(TypedDict):
    a: str

# Output from node_1 contains private data that is not part of the overall state
class Node1Output(TypedDict):
    private_data: str

# The private data is only shared between node_1 and node_2
def node_1(state: OverallState) -> Node1Output:
    output = {"private_data": "set by node_1"}
    print(f"Entered node `node_1`:\n\tInput: {state}.\n\tReturned: {output}")
    return output

# Node 2 input only requests the private data available after node_1
class Node2Input(TypedDict):
    private_data: str

def node_2(state: Node2Input) -> OverallState:
    output = {"a": "set by node_2"}
    print(f"Entered node `node_2`:\n\tInput: {state}.\n\tReturned: {output}")
    return output

# Node 3 only has access to the overall state (no access to private data from node_1)
def node_3(state: OverallState) -> OverallState:
    output = {"a": "set by node_3"}
    print(f"Entered node `node_3`:\n\tInput: {state}.\n\tReturned: {output}")
    return output

# Connect nodes in a sequence
# node_2 accepts private data from node_1, whereas
# node_3 does not see the private data.
builder = StateGraph(OverallState).add_sequence([node_1, node_2, node_3])
builder.add_edge(START, "node_1")
graph = builder.compile()

# Invoke the graph with the initial state
response = graph.invoke(
    {
        "a": "set at start",
    }
)

print()
print(f"Output of graph invocation: {response}")Entered node `node_1`:
Input: {'a': 'set at start'}.
Returned: {'private_data': 'set by node_1'}
Entered node `node_2`:
Input: {'private_data': 'set by node_1'}.
Returned: {'a': 'set by node_2'}
Entered node `node_3`:
Input: {'a': 'set by node_2'}.
Returned: {'a': 'set by node_3'}
Output of graph invocation: {'a': 'set by node_3'}为图状态使用 pydantic 模型
一个 StateGraph 在初始化时接受一个 state_schema 参数,用于指定图中节点可以访问和更新的状态“形状”。
在我们的示例中,我们通常使用 Python 原生的 TypedDict 或 dataclass 作为 state_schema,但 state_schema 可以是任意类型。
在这里,我们将了解如何使用 Pydantic BaseModel 作为 state_schema,以对输入添加运行时校验。
NOTE
已知限制
- 目前,图的输出将不会是 pydantic 模型的实例。
- 运行时校验仅发生在图中第一个节点的输入上,而不会作用于后续节点或输出。
- pydantic 的校验错误追踪不会显示错误发生在哪个节点。
- Pydantic 的递归校验可能较慢。对于对性能敏感的应用,你可能需要考虑改用
dataclass。
python
from langgraph.graph import StateGraph, START, END
from typing_extensions import TypedDict
from pydantic import BaseModel

# The overall state of the graph (this is the public state shared across nodes)
class OverallState(BaseModel):
    a: str

def node(state: OverallState):
    return {"a": "goodbye"}

# Build the state graph
builder = StateGraph(OverallState)
builder.add_node(node)  # node_1 is the first node
builder.add_edge(START, "node")  # Start the graph with node_1
builder.add_edge("node", END)  # End the graph after node_1
graph = builder.compile()

# Test the graph with a valid input
graph.invoke({"a": "hello"})使用无效输入调用图
python
try:
    graph.invoke({"a": 123})  # Should be a string
except Exception as e:
    print("An exception was raised because `a` is an integer rather than a string.")
print(e)An exception was raised because `a` is an integer rather than a string.
1 validation error for OverallState
a
Input should be a valid string [type=string_type, input_value=123, input_type=int]
For further information visit https://errors.pydantic.dev/2.9/v/string_type有关 Pydantic 模型状态的其他特性,请见下文:
序列化行为
当使用 Pydantic 模型作为状态模式时,理解序列化的工作方式很重要,尤其是在以下情况:
- 将 Pydantic 对象作为输入传递
- 从图接收输出
- 处理嵌套的 Pydantic 模型
让我们看看这些行为在实际中的表现。
python
from langgraph.graph import StateGraph, START, END
from pydantic import BaseModel

class NestedModel(BaseModel):
    value: str

class ComplexState(BaseModel):
    text: str
    count: int
    nested: NestedModel

def process_node(state: ComplexState):
    # Node receives a validated Pydantic object
    print(f"Input state type: {type(state)}")
    print(f"Nested type: {type(state.nested)}")
    # Return a dictionary update
    return {"text": state.text + " processed", "count": state.count + 1}

# Build the graph
builder = StateGraph(ComplexState)
builder.add_node("process", process_node)
builder.add_edge(START, "process")
builder.add_edge("process", END)
graph = builder.compile()

# Create a Pydantic instance for input
input_state = ComplexState(text="hello", count=0, nested=NestedModel(value="test"))
print(f"Input object type: {type(input_state)}")

# Invoke graph with a Pydantic instance
result = graph.invoke(input_state)
print(f"Output type: {type(result)}")
print(f"Output content: {result}")

# Convert back to Pydantic model if needed
output_model = ComplexState(**result)
print(f"Converted back to Pydantic: {type(output_model)}")运行时类型强制转换
Pydantic 会对某些数据类型执行运行时类型强制转换。这可能很有帮助,但如果你不了解它,也可能导致意外行为。
python
from langgraph.graph import StateGraph, START, END
from pydantic import BaseModel

class CoercionExample(BaseModel):
    # Pydantic will coerce string numbers to integers
    number: int
    # Pydantic will parse string booleans to bool
    flag: bool

def inspect_node(state: CoercionExample):
    print(f"number: {state.number} (type: {type(state.number)})")
    print(f"flag: {state.flag} (type: {type(state.flag)})")
    return {}

builder = StateGraph(CoercionExample)
builder.add_node("inspect", inspect_node)
builder.add_edge(START, "inspect")
builder.add_edge("inspect", END)
graph = builder.compile()

# Demonstrate coercion with string inputs that will be converted
result = graph.invoke({"number": "42", "flag": "true"})

# This would fail with a validation error
try:
    graph.invoke({"number": "not-a-number", "flag": "true"})
except Exception as e:
print(f"\nExpected validation error: {e}")处理消息模型
在状态模式中处理 LangChain 消息类型时,序列化有一些重要的注意事项。在通过网络传输消息对象时,你应使用 AnyMessage(而不是 BaseMessage)来确保正确的序列化/反序列化。
python
from langgraph.graph import StateGraph, START, END
from pydantic import BaseModel
from langchain.messages import HumanMessage, AIMessage, AnyMessage
from typing import List

class ChatState(BaseModel):
    messages: List[AnyMessage]
    context: str

def add_message(state: ChatState):
    return {"messages": state.messages + [AIMessage(content="Hello there!")]}

builder = StateGraph(ChatState)
builder.add_node("add_message", add_message)
builder.add_edge(START, "add_message")
builder.add_edge("add_message", END)
graph = builder.compile()

# Create input with a message
initial_state = ChatState(
    messages=[HumanMessage(content="Hi")], context="Customer support chat"
)

result = graph.invoke(initial_state)
print(f"Output: {result}")

# Convert back to Pydantic model to see message types
output_model = ChatState(**result)
for i, msg in enumerate(output_model.messages):
print(f"Message {i}: {type(msg).__name__} - {msg.content}")添加运行时配置
有时你希望在调用图时能够对图进行配置。例如,你可能希望在运行时指定使用哪个 LLM 或系统提示词,而不用这些参数污染图状态。
要添加运行时配置:
- 为你的配置指定一个模式
- 将配置添加到节点或条件边的函数签名中
- 将配置传入图。
有关简单示例,请见下文:
python
from langgraph.graph import END, StateGraph, START
from langgraph.runtime import Runtime
from typing_extensions import TypedDict

# 1. Specify config schema
class ContextSchema(TypedDict):
    my_runtime_value: str

# 2. Define a graph that accesses the config in a node
class State(TypedDict):
    my_state_value: str

def node(state: State, runtime: Runtime[ContextSchema]):
    if runtime.context["my_runtime_value"] == "a":
        return {"my_state_value": 1}
    elif runtime.context["my_runtime_value"] == "b":
        return {"my_state_value": 2}
    else:
        raise ValueError("Unknown values.")

builder = StateGraph(State, context_schema=ContextSchema)
builder.add_node(node)
builder.add_edge(START, "node")
builder.add_edge("node", END)

graph = builder.compile()

# 3. Pass in configuration at runtime:
print(graph.invoke({}, context={"my_runtime_value": "a"}))
print(graph.invoke({}, context={"my_runtime_value": "b"})) {'my_state_value': 1}
{'my_state_value': 2}扩展示例:在运行时指定 LLM
下面我们演示一个实际示例,其中我们配置在运行时使用哪个 LLM。我们将同时使用 OpenAI 和 Anthropic 模型。
python
from dataclasses import dataclass

from langchain.chat_models import init_chat_model
from langgraph.graph import MessagesState, END, StateGraph, START
from langgraph.runtime import Runtime
from typing_extensions import TypedDict

@dataclass
class ContextSchema:
    model_provider: str = "anthropic"

MODELS = {
    "anthropic": init_chat_model("claude-haiku-4-5-20251001"),
    "openai": init_chat_model("gpt-5.4-mini"),
}

def call_model(state: MessagesState, runtime: Runtime[ContextSchema]):
    model = MODELS[runtime.context.model_provider]
    response = model.invoke(state["messages"])
    return {"messages": [response]}

builder = StateGraph(MessagesState, context_schema=ContextSchema)
builder.add_node("model", call_model)
builder.add_edge(START, "model")
builder.add_edge("model", END)

graph = builder.compile()

# Usage
input_message = {"role": "user", "content": "hi"}
# With no configuration, uses default (Anthropic)
response_1 = graph.invoke({"messages": [input_message]}, context=ContextSchema())["messages"][-1]
# Or, can set OpenAI
response_2 = graph.invoke({"messages": [input_message]}, context={"model_provider": "openai"})["messages"][-1]

print(response_1.response_metadata["model_name"])
print(response_2.response_metadata["model_name"])claude-haiku-4-5-20251001
gpt-5.4-mini扩展示例:在运行时指定模型和系统消息
下面我们演示一个实际示例,其中我们配置两个参数:在运行时使用的 LLM 和系统消息。
python
from dataclasses import dataclass
from langchain.chat_models import init_chat_model
from langchain.messages import SystemMessage
from langgraph.graph import END, MessagesState, StateGraph, START
from langgraph.runtime import Runtime
from typing_extensions import TypedDict

@dataclass
class ContextSchema:
    model_provider: str = "anthropic"
    system_message: str | None = None

MODELS = {
    "anthropic": init_chat_model("claude-haiku-4-5-20251001"),
    "openai": init_chat_model("gpt-5.4-mini"),
}

def call_model(state: MessagesState, runtime: Runtime[ContextSchema]):
    model = MODELS[runtime.context.model_provider]
    messages = state["messages"]
    if (system_message := runtime.context.system_message):
        messages = [SystemMessage(system_message)] + messages
    response = model.invoke(messages)
    return {"messages": [response]}

builder = StateGraph(MessagesState, context_schema=ContextSchema)
builder.add_node("model", call_model)
builder.add_edge(START, "model")
builder.add_edge("model", END)

graph = builder.compile()

# Usage
input_message = {"role": "user", "content": "hi"}
response = graph.invoke({"messages": [input_message]}, context={"model_provider": "openai", "system_message": "Respond in Italian."})
for message in response["messages"]:
message.pretty_print()================================ Human Message ================================
hi
================================== Ai Message ==================================
Ciao! Come posso aiutarti oggi?添加重试策略
在许多用例中,你可能希望节点具有自定义重试策略,例如在调用 API、查询数据库或调用 LLM 等情况下。LangGraph 允许你为节点添加重试策略。
要配置重试策略,请将 retry_policy 参数传递给 add_node。retry_policy 参数接收一个 RetryPolicy 命名元组对象。下面我们使用默认参数实例化一个 RetryPolicy 对象,并将其关联到一个节点:
python
from langgraph.types import RetryPolicy

builder.add_node(
    "node_name",
    node_function,
    retry_policy=RetryPolicy(),
)默认情况下,retry_on 参数使用 default_retry_on 函数,它会对除以下异常之外的任何异常进行重试:
ValueErrorTypeErrorArithmeticErrorImportErrorLookupErrorNameErrorSyntaxErrorRuntimeErrorReferenceErrorStopIterationStopAsyncIterationOSError
此外,对于来自 requests 和 httpx 等常用 HTTP 请求库的异常,它只会对 5xx 状态码进行重试。
扩展示例:自定义重试策略
考虑一个从 SQL 数据库读取数据的示例。下面我们向节点传递两种不同的重试策略:
python
import sqlite3
from typing_extensions import TypedDict
from langchain.chat_models import init_chat_model
from langgraph.graph import END, MessagesState, StateGraph, START
from langgraph.types import RetryPolicy
from langchain.messages import AIMessage

con = sqlite3.connect(":memory:")
model = init_chat_model("claude-haiku-4-5-20251001")

def query_database(state: MessagesState):
    cursor = con.cursor()
    cursor.execute("SELECT * FROM Artist LIMIT 10;")
    query_result = str(cursor.fetchall())
    return {"messages": [AIMessage(content=query_result)]}

def call_model(state: MessagesState):
    response = model.invoke(state["messages"])
    return {"messages": [response]}

# Define a new graph
builder = StateGraph(MessagesState)
builder.add_node(
    "query_database",
    query_database,
    retry_policy=RetryPolicy(retry_on=sqlite3.OperationalError),
)
builder.add_node("model", call_model, retry_policy=RetryPolicy(max_attempts=5))
builder.add_edge(START, "model")
builder.add_edge("model", "query_database")
builder.add_edge("query_database", END)
graph = builder.compile()设置节点超时
使用 add_node 的 timeout 参数来限制单个异步节点调用可运行的最长时间。以秒为单位或使用 datetime.timedelta 提供超时时间。
python
import asyncio
from typing_extensions import TypedDict

from langgraph.errors import NodeTimeoutError
from langgraph.graph import END, START, StateGraph

class State(TypedDict):
    value: str

async def call_model(state: State) -> State:
    await asyncio.sleep(2)
    return {"value": "done"}

builder = StateGraph(State)
builder.add_node("model", call_model, timeout=1.0)
builder.add_edge(START, "model")
builder.add_edge("model", END)
graph = builder.compile()

try:
    await graph.ainvoke({"value": "start"})
except NodeTimeoutError:
print("Node timed out")节点超时仅支持异步节点。如果你在同步节点上设置 timeout,LangGraph 会在编译图时引发错误,因为同步 Python 执行无法在进程内被安全取消。
当节点超出其超时时间时,LangGraph 会引发 NodeTimeoutError,它是 Python 内置 TimeoutError 的子类。如果该节点具有会重试 TimeoutError 或 NodeTimeoutError 的 retry_policy,则超时的尝试会被重试。超时分别适用于每次尝试,因此每次重试时计时器都会重置。
超时的尝试不会提交其缓冲的写入。这可防止状态更新或子任务调度在超时边界之后泄漏出去。
配置节点超时
add_node 上的 timeout= 参数限制单个异步节点尝试可运行的最长时间。传入一个数字(秒)、一个 timedelta,或一个 TimeoutPolicy,以便更精细地控制运行超时和空闲超时。当超出限制时,LangGraph 会引发 NodeTimeoutError,并让重试策略决定是否重试。
NOTE
逐节点超时需要 langgraph>=1.2。
python
from langgraph.types import TimeoutPolicy

builder.add_node(
    "call_model",
    call_model,
    timeout=TimeoutPolicy(run_timeout=120, idle_timeout=30),
)有关完整的超时生命周期、空闲超时刷新来源以及 runtime.heartbeat(),请参阅容错。
处理节点错误
add_node 上的 error_handler= 参数会注册一个函数,在节点失败且所有重试都已耗尽后运行。该处理器接收当前状态和一个带类型的 NodeError(其中包含失败上下文),并且可以通过 Command 路由到一个恢复分支:
NOTE
节点级错误处理器需要 langgraph>=1.2。
python
from langgraph.errors import NodeError
from langgraph.types import Command, RetryPolicy

def payment_error_handler(state: State, error: NodeError) -> Command:
    return Command(
        update={"status": f"compensated: {error.error}"},
        goto="finalize",
    )

builder.add_node(
    "charge_payment",
    charge_payment,
    retry_policy=RetryPolicy(max_attempts=3, retry_on=ConnectionError),
    error_handler=payment_error_handler,
)有关补偿模式和 Command 路由,请参阅容错。
设置图范围的节点默认值
NOTE
需要 langgraph>=1.2。
使用 set_node_defaults 为图中的每个节点一次性设置 retry_policy、timeout、cache_policy 或 error_handler,而不必在每次调用 add_node 时重复设置它们。逐节点的值始终优先,默认值在 StateGraph.compile 时应用:
python
from langgraph.types import RetryPolicy, TimeoutPolicy

graph = (
    StateGraph(State)
    .set_node_defaults(
        retry_policy=RetryPolicy(max_attempts=3),
        timeout=TimeoutPolicy(run_timeout=30),
        error_handler=fallback_handler,
    )
    .add_node("a", node_a)
    .add_node("b", node_b, retry_policy=RetryPolicy(max_attempts=5))  # overrides default
    .add_edge(START, "a")
    .compile()
)retry_policy 和 timeout 默认值应用于每个节点,包括错误处理器节点。cache_policy 和 error_handler 默认值仅应用于常规节点——处理器从不捕获自身,且缓存处理器结果是不安全的。默认值不会被子图继承。
有关完整的优先级规则和适用性表格,请参阅容错。
在节点内访问执行信息
你可以通过 runtime.execution_info 访问执行身份和重试信息。它会呈现线程、运行和检查点标识符以及重试状态,无需直接读取 config。
| 属性 | 类型 | 描述 |
|---|---|---|
thread_id | str | None | 当前执行的线程 ID。没有检查点器时为 None。 |
run_id | str | None | 当前运行的 ID。未在 config 中提供时为 None。 |
checkpoint_id | str | 当前执行的检查点 ID。 |
checkpoint_ns | str | 当前执行的检查点命名空间。 |
task_id | str | 当前执行的任务 ID。 |
node_attempt | int | 当前执行尝试次数(从 1 开始索引)。首次尝试为 1,首次重试为 2,依此类推。 |
node_first_attempt_time | float | None | 首次尝试开始时的 Unix 时间戳(秒)。在多次重试中保持不变。 |
访问线程 ID 和运行 ID
使用 execution_info 在节点内访问线程 ID、运行 ID 以及其他身份字段:
python
from langgraph.graph import StateGraph, START, END
from langgraph.runtime import Runtime
from typing_extensions import TypedDict

class State(TypedDict):
    result: str

def my_node(state: State, runtime: Runtime):
    info = runtime.execution_info
    print(f"Thread: {info.thread_id}, Run: {info.run_id}")
    return {"result": "done"}

builder = StateGraph(State)
builder.add_node("my_node", my_node)
builder.add_edge(START, "my_node")
builder.add_edge("my_node", END)
graph = builder.compile()根据重试状态调整行为
当节点具有重试策略时,使用 execution_info 检查当前尝试次数,并在首次尝试失败后切换到回退方案:
python
from langgraph.graph import StateGraph, START, END
from langgraph.runtime import Runtime
from langgraph.types import RetryPolicy
from typing_extensions import TypedDict

class State(TypedDict):
    result: str

def my_node(state: State, runtime: Runtime):
    info = runtime.execution_info
    if info.node_attempt > 1:
        # use a fallback on retries
        return {"result": call_fallback_api()}
    return {"result": call_primary_api()}

builder = StateGraph(State)
builder.add_node("my_node", my_node, retry_policy=RetryPolicy(max_attempts=3))
builder.add_edge(START, "my_node")
builder.add_edge("my_node", END)
graph = builder.compile()即使没有重试策略,execution_info 也可在 Runtime 对象上使用——node_attempt 默认为 1,node_first_attempt_time 会设置为节点开始执行的时间。
在节点内访问服务器信息
当你的图在 LangGraph Server 上运行时,你可以通过 runtime.server_info 访问特定于服务器的元数据。它会呈现 assistant ID、graph ID 和已认证用户,无需直接读取 config 元数据或 configurable 键。
| 属性 | 类型 | 描述 |
|---|---|---|
assistant_id | str | 当前部署的 assistant ID。 |
graph_id | str | 当前部署的 graph ID。 |
user | BaseUser | None | 已认证用户(如果配置了自定义身份认证)。 |
python
from langgraph.graph import StateGraph, START, END
from langgraph.runtime import Runtime
from typing_extensions import TypedDict

class State(TypedDict):
    result: str

def my_node(state: State, runtime: Runtime):
    server = runtime.server_info
    if server is not None:
        print(f"Assistant: {server.assistant_id}, Graph: {server.graph_id}")
        if server.user is not None:
            print(f"User: {server.user.identity}")
    return {"result": "done"}

builder = StateGraph(State)
builder.add_node("my_node", my_node)
builder.add_edge(START, "my_node")
builder.add_edge("my_node", END)
graph = builder.compile()当图未在 LangGraph Server 上运行时(例如在本地开发或测试期间),server_info 为 None。
NOTE
runtime.execution_info 和 runtime.server_info 需要 deepagents>=0.5.0(或 langgraph>=1.1.5)。
在节点内访问 drain 状态
当请求了优雅关闭时,runtime.drain_requested 为 True。在节点内读取它,以在下一个 superstep 边界之前跳过开销大的工作:
python
from langgraph.runtime import Runtime

def my_node(state: State, runtime: Runtime) -> State:
    if runtime.drain_requested:
        return {"status": "skipped", "reason": runtime.drain_reason}
return {"status": do_work()}| 属性 | 类型 | 描述 |
|---|---|---|
drain_requested | bool | 如果已为此运行调用 RunControl.request_drain(),则为 True。 |
drain_reason | str | None | 传递给 request_drain() 的原因字符串;如果未请求 drain,则为 None。 |
NOTE
需要 langgraph>=1.2。有关完整的 RunControl API,请参阅优雅关闭。
添加节点缓存
在你希望避免重复操作的情况下,节点缓存很有用,比如执行开销大(无论是时间还是成本)的操作时。LangGraph 允许你为图中的节点添加个性化的缓存策略。
要配置缓存策略,请将 cache_policy 参数传递给 add_node 函数。在下面的示例中,使用 120 秒的生存时间和默认的 key_func 生成器实例化一个 CachePolicy 对象。然后将其关联到一个节点:
python
from langgraph.types import CachePolicy

builder.add_node(
    "node_name",
    node_function,
    cache_policy=CachePolicy(ttl=120),
)然后,要为图启用节点级缓存,请在编译图时设置 cache 参数。下面的示例使用 InMemoryCache 来设置一个具有内存缓存的图,但 SqliteCache 也是可用的。
python
from langgraph.cache.memory import InMemoryCache

graph = builder.compile(cache=InMemoryCache())创建步骤序列
INFO
前提条件 本指南假定你熟悉上文关于状态的部分。
这里我们演示如何构造一个简单的步骤序列。我们将展示:
- 如何构建顺序图
- 用于构造类似图的内置简写。
要添加节点序列,我们使用图的 add_node 和 add_edge 方法:
python
from langgraph.graph import START, StateGraph

builder = StateGraph(State)

# Add nodes
builder.add_node(step_1)
builder.add_node(step_2)
builder.add_node(step_3)

# Add edges
builder.add_edge(START, "step_1")
builder.add_edge("step_1", "step_2")
builder.add_edge("step_2", "step_3")我们也可以使用内置简写 .add_sequence:
python
builder = StateGraph(State).add_sequence([step_1, step_2, step_3])
builder.add_edge(START, "step_1")为什么要用 LangGraph 把应用步骤拆分为序列?
LangGraph 让你能轻松为应用添加底层持久化层。 这允许在节点执行之间对状态进行检查点保存,因此你的 LangGraph 节点决定了:
它们还决定了执行步骤如何被流式输出,以及你的应用如何使用 Studio 进行可视化和调试。
让我们演示一个端到端示例。我们将创建一个包含三个步骤的序列:
- 在状态的某个键中填充一个值
- 更新同一个值
- 填充另一个不同的值
让我们首先定义我们的状态。它决定图的模式,还可以指定如何应用更新。更多细节请参阅使用归约器处理状态更新。
在我们的例子中,我们只跟踪两个值:
python
from typing_extensions import TypedDict

class State(TypedDict):
    value_1: str
value_2: int我们的节点只是读取图状态并对其进行更新的 Python 函数。此函数的第一个参数始终是状态:
python
def step_1(state: State):
    return {"value_1": "a"}

def step_2(state: State):
    current_value_1 = state["value_1"]
    return {"value_1": f"{current_value_1} b"}

def step_3(state: State):
return {"value_2": 10}NOTE
请注意,在向状态发出更新时,每个节点只需指定它希望更新的键的值。
默认情况下,这会覆盖相应键的值。你也可以使用归约器来控制更新如何处理——例如,你可以改为向某个键追加连续的更新。更多细节请参阅使用归约器处理状态更新。
最后,我们定义图。我们使用 StateGraph 来定义一个作用于该状态的图。
然后我们将使用 add_node 和 add_edge 来填充我们的图并定义其控制流。
python
from langgraph.graph import START, StateGraph

builder = StateGraph(State)

# Add nodes
builder.add_node(step_1)
builder.add_node(step_2)
builder.add_node(step_3)

# Add edges
builder.add_edge(START, "step_1")
builder.add_edge("step_1", "step_2")
builder.add_edge("step_2", "step_3")请注意:
接下来我们编译我们的图。这会对图的结构提供一些基本检查(例如,识别孤立节点)。如果我们通过检查点器为应用添加持久化,它也会在这里传入。
python
graph = builder.compile()LangGraph 提供了用于可视化图的内置工具。让我们查看一下我们的序列。有关可视化的详细信息,请参阅可视化你的图。
python
from IPython.display import Image, display

display(Image(graph.get_graph().draw_mermaid_png()))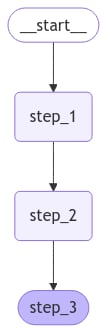
让我们进行一个简单的调用:
python
graph.invoke({"value_1": "c"}){'value_1': 'a b', 'value_2': 10}请注意:
- 我们通过为单个状态键提供一个值来发起调用。我们必须始终为至少一个键提供值。
- 我们传入的值被第一个节点覆盖。
- 第二个节点更新了该值。
- 第三个节点填充了一个不同的值。
TIP
内置简写langgraph>=0.2.46 包含一个用于添加节点序列的内置简写 add_sequence。你可以按如下方式编译同一个图:
python
builder = StateGraph(State).add_sequence([step_1, step_2, step_3])
builder.add_edge(START, "step_1")

graph = builder.compile()

graph.invoke({"value_1": "c"})创建分支
节点的并行执行对于加速整体图操作至关重要。LangGraph 原生支持节点的并行执行,这可以显著提升基于图的工作流的性能。这种并行化通过扇出和扇入机制实现,同时利用标准边和 conditional_edges。下面是一些示例,展示如何添加创建适合你的分支数据流。
并行运行图节点
在此示例中,我们从 Node A 扇出到 B and C,然后扇入到 D。在我们的状态中,我们指定了归约器加法操作。这会将状态中特定键的值合并或累积,而不是简单地覆盖现有值。对于列表,这意味着将新列表与现有列表拼接。有关使用归约器更新状态的更多细节,请参阅上文关于状态归约器的部分。
python
import operator
from typing import Annotated, Any
from typing_extensions import TypedDict
from langgraph.graph import StateGraph, START, END

class State(TypedDict):
    # The operator.add reducer fn makes this append-only
    aggregate: Annotated[list, operator.add]

def a(state: State):
    print(f'Adding "A" to {state["aggregate"]}')
    return {"aggregate": ["A"]}

def b(state: State):
    print(f'Adding "B" to {state["aggregate"]}')
    return {"aggregate": ["B"]}

def c(state: State):
    print(f'Adding "C" to {state["aggregate"]}')
    return {"aggregate": ["C"]}

def d(state: State):
    print(f'Adding "D" to {state["aggregate"]}')
    return {"aggregate": ["D"]}

builder = StateGraph(State)
builder.add_node(a)
builder.add_node(b)
builder.add_node(c)
builder.add_node(d)
builder.add_edge(START, "a")
builder.add_edge("a", "b")
builder.add_edge("a", "c")
builder.add_edge("b", "d")
builder.add_edge("c", "d")
builder.add_edge("d", END)
graph = builder.compile()python
from IPython.display import Image, display

display(Image(graph.get_graph().draw_mermaid_png()))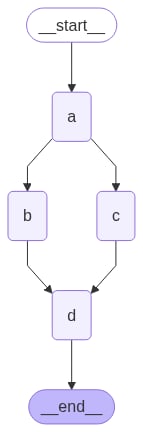
使用归约器,你可以看到每个节点中添加的值都被累积起来。
python
graph.invoke({"aggregate": []}, {"configurable": {"thread_id": "foo"}})Adding "A" to []
Adding "B" to ['A']
Adding "C" to ['A']
Adding "D" to ['A', 'B', 'C']NOTE
在上面的示例中,节点 "b" 和 "c" 在同一个 superstep 中并发执行。由于它们处于同一步中,节点 "d" 会在 "b" 和 "c" 都完成后才执行。
重要的是,来自并行 superstep 的更新可能不会按一致的顺序排列。如果你需要对来自并行 superstep 的更新进行一致且预先确定的排序,你应该将输出写入状态中的一个单独字段,并附带一个用于排序它们的值。
异常处理?
LangGraph 在 superstep 内执行节点,这意味着虽然并行分支是并行执行的,但整个 superstep 是事务性的。如果其中任何一个分支引发异常,则不会有任何更新被应用到状态(整个 superstep 出错)。
重要的是,当使用检查点器时,superstep 内成功节点的结果会被保存,并在恢复时不会重复。
如果你的节点容易出错(也许你想处理不稳定的 API 调用),LangGraph 提供了两种方法来解决:
- 你可以在节点内编写常规 Python 代码来捕获和处理异常。
- 你可以设置一个
RetryPolicy,指示图对引发某些类型异常的节点进行重试。只有失败的分支会被重试,因此你不必担心执行冗余工作。
结合起来,这些让你可以执行并行执行并完全控制异常处理。
TIP
设置最大并发数 你可以在调用图时,通过在配置中设置 max_concurrency 来控制并发任务的最大数量。max_concurrency 是一个独立的 config 键,因此应将其设置在 config 的顶层,而不是放在 configurable 内。
python
graph.invoke({"value_1": "c"}, {"max_concurrency": 10})延迟节点执行
当你希望将某个节点的执行延迟到所有其他待处理任务完成之后时,延迟节点执行很有用。当各分支长度不同时,这尤其相关,这种情况在 map-reduce 之类的流程中很常见。
上面的示例展示了当每条路径只有一步时如何进行扇出和扇入。但如果某个分支有不止一步呢?让我们在 "b" 分支中添加一个节点 "b_2":
python
import operator
from typing import Annotated, Any
from typing_extensions import TypedDict
from langgraph.graph import StateGraph, START, END

class State(TypedDict):
    # The operator.add reducer fn makes this append-only
    aggregate: Annotated[list, operator.add]

def a(state: State):
    print(f'Adding "A" to {state["aggregate"]}')
    return {"aggregate": ["A"]}

def b(state: State):
    print(f'Adding "B" to {state["aggregate"]}')
    return {"aggregate": ["B"]}

def b_2(state: State):
    print(f'Adding "B_2" to {state["aggregate"]}')
    return {"aggregate": ["B_2"]}

def c(state: State):
    print(f'Adding "C" to {state["aggregate"]}')
    return {"aggregate": ["C"]}

def d(state: State):
    print(f'Adding "D" to {state["aggregate"]}')
    return {"aggregate": ["D"]}

builder = StateGraph(State)
builder.add_node(a)
builder.add_node(b)
builder.add_node(b_2)
builder.add_node(c)
builder.add_node(d, defer=True)
builder.add_edge(START, "a")
builder.add_edge("a", "b")
builder.add_edge("a", "c")
builder.add_edge("b", "b_2")
builder.add_edge("b_2", "d")
builder.add_edge("c", "d")
builder.add_edge("d", END)
graph = builder.compile()python
from IPython.display import Image, display

display(Image(graph.get_graph().draw_mermaid_png()))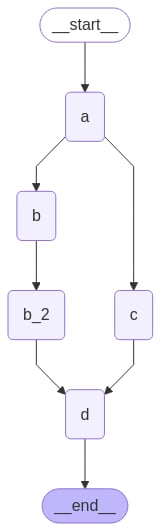
python
graph.invoke({"aggregate": []})Adding "A" to []
Adding "B" to ['A']
Adding "C" to ['A']
Adding "B_2" to ['A', 'B', 'C']
Adding "D" to ['A', 'B', 'C', 'B_2']在上面的示例中,节点 "b" 和 "c" 在同一个 superstep 中并发执行。我们在节点 d 上设置 defer=True,使其在所有待处理任务完成之前不会执行。在这种情况下,这意味着 "d" 会等待,直到整个 "b" 分支完成才执行。
当每个分支始终都会运行时,你可以用列表形式的边来等待,而不是使用 defer=True。add_edge 也接受一个起始节点列表。这并不是分开多次调用 add_edge 的简写;这两种形式的行为不同:
python
builder.add_edge(["b_2", "c"], "d") # d runs once, after both b_2 and c complete- 起始节点列表 会在所有列出的节点都完成后运行一次
d。如果其中一个节点从未运行(例如,某条条件边没有选择它的分支),d就不会运行,也不会引发错误。已完成分支的状态更新会保留在图状态中,但d不会消费它们。 - 分开的边 会在任何一个入站分支完成的每个 superstep 中运行一次
d。当分支长度相等时,这只是一次运行;当分支长度不同时,d会运行不止一次。 - 带
defer=True的分开的边(上述示例中的模式)会在每个被选中的分支都完成后运行一次d,无论扇出选择了所有分支还是只选择了其中一部分。
defer=True 会将该节点推迟到图中任何地方都没有待处理任务时才执行,而不仅仅是喂给它的那些分支。发往该节点的 Send 仍会单独调用它。
条件分支
如果你的扇出需要在运行时根据状态而变化,你可以使用 add_conditional_edges 来利用图状态选择一条或多条路径。请见下面的示例,其中节点 a 生成一个决定后续节点的状态更新。
python
import operator
from typing import Annotated, Literal, Sequence
from typing_extensions import TypedDict
from langgraph.graph import StateGraph, START, END

class State(TypedDict):
    aggregate: Annotated[list, operator.add]
    # Add a key to the state. We will set this key to determine
    # how we branch.
    which: str

def a(state: State):
    print(f'Adding "A" to {state["aggregate"]}')
    return {"aggregate": ["A"], "which": "c"}

def b(state: State):
    print(f'Adding "B" to {state["aggregate"]}')
    return {"aggregate": ["B"]}

def c(state: State):
    print(f'Adding "C" to {state["aggregate"]}')
    return {"aggregate": ["C"]}

builder = StateGraph(State)
builder.add_node(a)
builder.add_node(b)
builder.add_node(c)
builder.add_edge(START, "a")
builder.add_edge("b", END)
builder.add_edge("c", END)

def conditional_edge(state: State) -> Literal["b", "c"]:
    # Fill in arbitrary logic here that uses the state
    # to determine the next node
    return state["which"]

builder.add_conditional_edges("a", conditional_edge)

graph = builder.compile()python
from IPython.display import Image, display

display(Image(graph.get_graph().draw_mermaid_png()))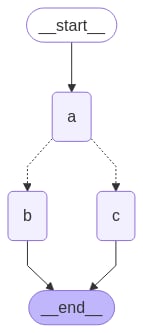
python
result = graph.invoke({"aggregate": []})
print(result)Adding "A" to []
Adding "C" to ['A']
{'aggregate': ['A', 'C'], 'which': 'c'}TIP
你的条件边可以路由到多个目标节点。例如:
python
def route_bc_or_cd(state: State) -> Sequence[str]:
    if state["which"] == "cd":
        return ["c", "d"]
return ["b", "c"]Map-Reduce 与 send API
LangGraph 支持使用 Send API 进行 map-reduce 以及其他高级分支模式。以下是如何使用它的示例:
python
from langgraph.graph import StateGraph, START, END
from langgraph.types import Send
from typing_extensions import TypedDict, Annotated
import operator

class OverallState(TypedDict):
    topic: str
    subjects: list[str]
    jokes: Annotated[list[str], operator.add]
    best_selected_joke: str

def generate_topics(state: OverallState):
    return {"subjects": ["lions", "elephants", "penguins"]}

def generate_joke(state: OverallState):
    joke_map = {
        "lions": "Why don't lions like fast food? Because they can't catch it!",
        "elephants": "Why don't elephants use computers? They're afraid of the mouse!",
        "penguins": "Why don't penguins like talking to strangers at parties? Because they find it hard to break the ice."
    }
    return {"jokes": [joke_map[state["subject"]]]}

def continue_to_jokes(state: OverallState):
    return [Send("generate_joke", {"subject": s}) for s in state["subjects"]]

def best_joke(state: OverallState):
    return {"best_selected_joke": "penguins"}

builder = StateGraph(OverallState)
builder.add_node("generate_topics", generate_topics)
builder.add_node("generate_joke", generate_joke)
builder.add_node("best_joke", best_joke)
builder.add_edge(START, "generate_topics")
builder.add_conditional_edges("generate_topics", continue_to_jokes, ["generate_joke"])
builder.add_edge("generate_joke", "best_joke")
builder.add_edge("best_joke", END)
graph = builder.compile()python
from IPython.display import Image, display

display(Image(graph.get_graph().draw_mermaid_png()))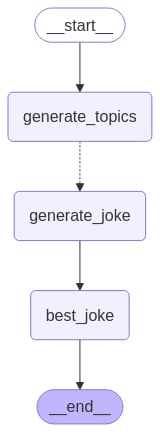
python
# Call the graph: here we call it to generate a list of jokes
stream = graph.stream_events({"topic": "animals"}, version="v3")
for message in stream.messages:
    for token in message.text:
print(token, end="", flush=True){'generate_topics': {'subjects': ['lions', 'elephants', 'penguins']}}
{'generate_joke': {'jokes': ["Why don't lions like fast food? Because they can't catch it!"]}}
{'generate_joke': {'jokes': ["Why don't elephants use computers? They're afraid of the mouse!"]}}
{'generate_joke': {'jokes': ['Why don't penguins like talking to strangers at parties? Because they find it hard to break the ice.']}}
{'best_joke': {'best_selected_joke': 'penguins'}}创建和控制循环
在创建带循环的图时,我们需要一种终止执行的机制。最常见的做法是添加一条条件边,一旦达到某个终止条件就路由到 END 节点。
你也可以在调用或流式输出图时设置图的递归限制。递归限制设置图在引发错误之前允许执行的 super-step 数量。阅读更多关于递归限制概念的内容。
让我们考虑一个带循环的简单图,以更好地理解这些机制如何工作。
TIP
要返回状态的最后一个值,而不是收到递归限制错误,请参阅下一节。
在创建循环时,你可以包含一条指定终止条件的条件边:
python
builder = StateGraph(State)
builder.add_node(a)
builder.add_node(b)

def route(state: State) -> Literal["b", END]:
    if termination_condition(state):
        return END
    else:
        return "b"

builder.add_edge(START, "a")
builder.add_conditional_edges("a", route)
builder.add_edge("b", "a")
graph = builder.compile()要控制递归限制,请在 config 中指定 "recursion_limit"。这会引发一个 GraphRecursionError,你可以捕获并处理它:
python
from langgraph.errors import GraphRecursionError

try:
    graph.invoke(inputs, {"recursion_limit": 3})
except GraphRecursionError:
print("Recursion Error")让我们定义一个带简单循环的图。请注意,我们使用条件边来实现终止条件。
python
import operator
from typing import Annotated, Literal
from typing_extensions import TypedDict
from langgraph.graph import StateGraph, START, END

class State(TypedDict):
    # The operator.add reducer fn makes this append-only
    aggregate: Annotated[list, operator.add]

def a(state: State):
    print(f'Node A sees {state["aggregate"]}')
    return {"aggregate": ["A"]}

def b(state: State):
    print(f'Node B sees {state["aggregate"]}')
    return {"aggregate": ["B"]}

# Define nodes
builder = StateGraph(State)
builder.add_node(a)
builder.add_node(b)

# Define edges
def route(state: State) -> Literal["b", END]:
    if len(state["aggregate"]) < 7:
        return "b"
    else:
        return END

builder.add_edge(START, "a")
builder.add_conditional_edges("a", route)
builder.add_edge("b", "a")
graph = builder.compile()python
from IPython.display import Image, display

display(Image(graph.get_graph().draw_mermaid_png()))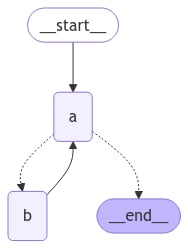
这种架构类似于一个 ReAct agent,其中节点 "a" 是一个进行工具调用的模型,节点 "b" 代表这些工具。
在我们的 route 条件边中,我们指定当状态中的 "aggregate" 列表超过阈值长度后就应结束。
调用该图,我们看到在节点 "a" 和 "b" 之间交替执行,直到达到终止条件后才终止。
python
graph.invoke({"aggregate": []})Node A sees []
Node B sees ['A']
Node A sees ['A', 'B']
Node B sees ['A', 'B', 'A']
Node A sees ['A', 'B', 'A', 'B']
Node B sees ['A', 'B', 'A', 'B', 'A']
Node A sees ['A', 'B', 'A', 'B', 'A', 'B']强制施加递归限制
在某些应用中,我们可能无法保证会达到给定的终止条件。在这些情况下,我们可以设置图的递归限制。这会在执行给定数量的 superstep 后引发一个 GraphRecursionError。然后我们可以捕获并处理这个异常:
python
from langgraph.errors import GraphRecursionError

try:
    graph.invoke({"aggregate": []}, {"recursion_limit": 4})
except GraphRecursionError:
print("Recursion Error")Node A sees []
Node B sees ['A']
Node C sees ['A', 'B']
Node D sees ['A', 'B']
Node A sees ['A', 'B', 'C', 'D']
Recursion Error扩展示例:在触及递归限制时返回状态
除了引发 GraphRecursionError,我们还可以向状态引入一个新键,用于跟踪在达到递归限制之前剩余的步数。然后我们可以使用这个键来决定是否应结束运行。
LangGraph 实现了一个特殊的 RemainingSteps 注解。在底层,它会创建一个 ManagedValue 通道——一个只在我们的图运行期间存在、之后便不再存在的状态通道。
python
import operator
from typing import Annotated, Literal
from typing_extensions import TypedDict
from langgraph.graph import StateGraph, START, END
from langgraph.managed.is_last_step import RemainingSteps

class State(TypedDict):
    aggregate: Annotated[list, operator.add]
    remaining_steps: RemainingSteps

def a(state: State):
    print(f'Node A sees {state["aggregate"]}')
    return {"aggregate": ["A"]}

def b(state: State):
    print(f'Node B sees {state["aggregate"]}')
    return {"aggregate": ["B"]}

# Define nodes
builder = StateGraph(State)
builder.add_node(a)
builder.add_node(b)

# Define edges
def route(state: State) -> Literal["b", END]:
    if state["remaining_steps"] <= 2:
        return END
    else:
        return "b"

builder.add_edge(START, "a")
builder.add_conditional_edges("a", route)
builder.add_edge("b", "a")
graph = builder.compile()

# Test it out
result = graph.invoke({"aggregate": []}, {"recursion_limit": 4})
print(result)Node A sees []
Node B sees ['A']
Node A sees ['A', 'B']
{'aggregate': ['A', 'B', 'A']}扩展示例:带分支的循环
为了更好地理解递归限制如何工作,让我们考虑一个更复杂的示例。下面我们实现一个循环,但其中一步扇出为两个节点:
python
import operator
from typing import Annotated, Literal
from typing_extensions import TypedDict
from langgraph.graph import StateGraph, START, END

class State(TypedDict):
    aggregate: Annotated[list, operator.add]

def a(state: State):
    print(f'Node A sees {state["aggregate"]}')
    return {"aggregate": ["A"]}

def b(state: State):
    print(f'Node B sees {state["aggregate"]}')
    return {"aggregate": ["B"]}

def c(state: State):
    print(f'Node C sees {state["aggregate"]}')
    return {"aggregate": ["C"]}

def d(state: State):
    print(f'Node D sees {state["aggregate"]}')
    return {"aggregate": ["D"]}

# Define nodes
builder = StateGraph(State)
builder.add_node(a)
builder.add_node(b)
builder.add_node(c)
builder.add_node(d)

# Define edges
def route(state: State) -> Literal["b", END]:
    if len(state["aggregate"]) < 7:
        return "b"
    else:
        return END

builder.add_edge(START, "a")
builder.add_conditional_edges("a", route)
builder.add_edge("b", "c")
builder.add_edge("b", "d")
builder.add_edge(["c", "d"], "a")
graph = builder.compile()python
from IPython.display import Image, display

display(Image(graph.get_graph().draw_mermaid_png()))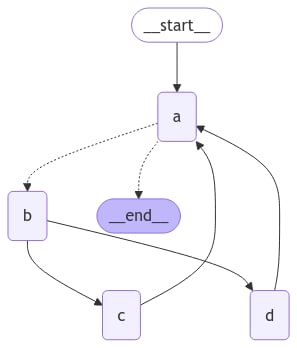
这个图看起来复杂,但可以把它概念化为 superstep 的循环:
- 节点 A
- 节点 B
- 节点 C 和 D
- 节点 A
- ...
我们有一个由四个 superstep 组成的循环,其中节点 C 和 D 并发执行。列表形式的边会等待 "c" 和 "d" 两者都完成后才返回 "a"。有关列表形式的边与进入同一节点的分开的边有何不同,请参阅延迟节点执行。
像之前一样调用该图,我们看到在触及终止条件之前完成了两个完整的“圈”:
python
result = graph.invoke({"aggregate": []})Node A sees []
Node B sees ['A']
Node D sees ['A', 'B']
Node C sees ['A', 'B']
Node A sees ['A', 'B', 'C', 'D']
Node B sees ['A', 'B', 'C', 'D', 'A']
Node D sees ['A', 'B', 'C', 'D', 'A', 'B']
Node C sees ['A', 'B', 'C', 'D', 'A', 'B']
Node A sees ['A', 'B', 'C', 'D', 'A', 'B', 'C', 'D']不过,如果我们把递归限制设置为四,我们只完成一圈,因为每一圈是四个 superstep:
python
from langgraph.errors import GraphRecursionError

try:
    result = graph.invoke({"aggregate": []}, {"recursion_limit": 4})
except GraphRecursionError:
print("Recursion Error")Node A sees []
Node B sees ['A']
Node C sees ['A', 'B']
Node D sees ['A', 'B']
Node A sees ['A', 'B', 'C', 'D']
Recursion Error异步
在并发运行 IO 密集型代码时(例如,向聊天模型服务商发起并发 API 请求),使用异步编程范式可以带来显著的性能提升。
要将图的 sync 实现转换为 async 实现,你需要:
- 将
nodes更新为使用async def而不是def。 - 更新内部代码,以适当使用
await。 - 按需使用
.ainvoke或.astream调用图。
由于许多 LangChain 对象都实现了 Runnable Protocol,它拥有所有 sync 方法的 async 变体,因此将 sync 图升级为 async 图通常相当快。
请见下面的示例。为了演示对底层 LLM 的异步调用,我们将包含一个聊天模型:
👉 阅读 OpenAI 聊天模型集成文档
bash
pip install -U "langchain[openai]"bash
uv add "langchain[openai]"python
import os
from langchain.chat_models import init_chat_model

os.environ["OPENAI_API_KEY"] = "sk-..."

model = init_chat_model("gpt-5.5")python
import os
from langchain_openai import ChatOpenAI

os.environ["OPENAI_API_KEY"] = "sk-..."

model = ChatOpenAI(model="gpt-5.5")python
from langchain.chat_models import init_chat_model
from langgraph.graph import MessagesState, StateGraph

async def node(state: MessagesState):
    new_message = await llm.ainvoke(state["messages"])
    return {"messages": [new_message]}

builder = StateGraph(MessagesState).add_node(node).set_entry_point("node")
graph = builder.compile()

input_message = {"role": "user", "content": "Hello"}
result = await graph.ainvoke({"messages": [input_message]}) TIP
异步流式传输 有关使用异步进行流式传输的示例,请参阅流式传输指南。
使用 Command 组合控制流和状态更新
将控制流(边)和状态更新(节点)组合起来可能很有用。例如,你可能希望在同一个节点中既执行状态更新,又决定下一个要前往的节点。LangGraph 提供了一种方式,即从节点函数返回一个 Command 对象:
python
def my_node(state: State) -> Command[Literal["my_other_node"]]:
    return Command(
        # state update
        update={"foo": "bar"},
        # control flow
        goto="my_other_node"
)下面我们展示一个端到端示例。让我们创建一个包含 3 个节点的简单图:A、B 和 C。我们将首先执行节点 A,然后根据节点 A 的输出来决定接下来前往节点 B 还是节点 C。
python
import random
from typing_extensions import TypedDict, Literal
from langgraph.graph import StateGraph, START
from langgraph.types import Command

# Define graph state
class State(TypedDict):
    foo: str

# Define the nodes

def node_a(state: State) -> Command[Literal["node_b", "node_c"]]:
    print("Called A")
    value = random.choice(["b", "c"])
    # this is a replacement for a conditional edge function
    if value == "b":
        goto = "node_b"
    else:
        goto = "node_c"

    # note how Command allows you to BOTH update the graph state AND route to the next node
    return Command(
        # this is the state update
        update={"foo": value},
        # this is a replacement for an edge
        goto=goto,
    )

def node_b(state: State):
    print("Called B")
    return {"foo": state["foo"] + "b"}

def node_c(state: State):
    print("Called C")
return {"foo": state["foo"] + "c"}现在我们可以用上面的节点创建 StateGraph。请注意,该图没有用于路由的条件边!这是因为控制流是在 node_a 内部用 Command 定义的。
python
builder = StateGraph(State)
builder.add_edge(START, "node_a")
builder.add_node(node_a)
builder.add_node(node_b)
builder.add_node(node_c)
# NOTE: there are no edges between nodes A, B and C!

graph = builder.compile()WARNING
你可能已经注意到,我们使用 Command 作为返回类型注解,例如 Command[Literal["node_b", "node_c"]]。这对于图渲染是必要的,并告知 LangGraph node_a 可以导航到 node_b 和 node_c。
python
from IPython.display import display, Image

display(Image(graph.get_graph().draw_mermaid_png()))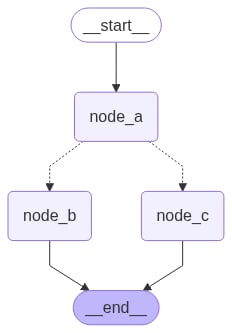
如果我们多次运行该图,我们会看到它根据节点 A 中的随机选择走不同的路径(A -> B 或 A -> C)。
python
graph.invoke({"foo": ""})Called A
Called C导航到父图中的某个节点
如果你正在使用子图,你可能希望从子图内的一个节点导航到另一个不同的子图(即父图中的另一个节点)。为此,你可以在 Command 中指定 graph=Command.PARENT:
python
def my_node(state: State) -> Command[Literal["other_subgraph"]]:
    return Command(
        update={"foo": "bar"},
        goto="other_subgraph",  # where `other_subgraph` is a node in the parent graph
        graph=Command.PARENT
)让我们用上面的示例来演示这一点。我们将把上面示例中的 nodeA 改成一个单节点图,并将其作为子图添加到我们的父图中。
python
import operator
from typing_extensions import Annotated

class State(TypedDict):
    # NOTE: we define a reducer here
    foo: Annotated[str, operator.add]

def node_a(state: State):
    print("Called A")
    value = random.choice(["a", "b"])
    # this is a replacement for a conditional edge function
    if value == "a":
        goto = "node_b"
    else:
        goto = "node_c"

    # note how Command allows you to BOTH update the graph state AND route to the next node
    return Command(
        update={"foo": value},
        goto=goto,
        # this tells LangGraph to navigate to node_b or node_c in the parent graph
        # NOTE: this will navigate to the closest parent graph relative to the subgraph
        graph=Command.PARENT,
    )

subgraph = StateGraph(State).add_node(node_a).add_edge(START, "node_a").compile()

def node_b(state: State):
    print("Called B")
    # NOTE: since we've defined a reducer, we don't need to manually append
    # new characters to existing 'foo' value. instead, reducer will append these
    # automatically (via operator.add)
    return {"foo": "b"}

def node_c(state: State):
    print("Called C")
    return {"foo": "c"}

builder = StateGraph(State)
builder.add_edge(START, "subgraph")
builder.add_node("subgraph", subgraph)
builder.add_node(node_b)
builder.add_node(node_c)

graph = builder.compile()python
graph.invoke({"foo": ""})Called A
Called C在工具内使用
一个常见用例是在工具内部更新图状态。例如,在客户支持应用中,你可能希望在对话开始时根据客户的账号或 ID 查找客户信息。要从工具更新图状态,你可以在工具中返回 Command(update=""my_custom_key": "foo", "messages": [...]"):
python
from langchain.tools import ToolRuntime

@tool
def lookup_user_info(runtime: ToolRuntime):
    """Use this to look up user information to better assist them with their questions."""
    user_info = get_user_info(runtime.server_info.user.identity)
    return Command(
        update={
            # update the state keys
            "user_info": user_info,
            # update the message history
            "messages": [ToolMessage("Successfully looked up user information", tool_call_id=runtime.tool_call_id)]
        }
)WARNING
当从工具返回 Command 时,你必须在 Command.update 中包含 messages(或用于消息历史的任何状态键),并且 messages 中的消息列表必须包含一个 ToolMessage。这对于生成的消息历史保持有效是必要的(LLM 服务商要求带有工具调用的 AI 消息后面必须跟随工具结果消息)。
如果你使用的工具会通过 Command 更新状态,我们建议使用预构建的 ToolNode,它会自动处理返回 Command 对象的工具,并将它们传播到图状态。如果你正在编写一个调用工具的自定义节点,则需要手动将工具返回的 Command 对象作为来自该节点的更新进行传播。
可视化你的图
这里我们演示如何可视化你创建的图。
你可以可视化任意 Graph,包括 StateGraph。
让我们画一些分形来找点乐子 😃。
python
import random
from typing import Annotated, Literal
from typing_extensions import TypedDict
from langgraph.graph import StateGraph, START, END
from langgraph.graph.message import add_messages

class State(TypedDict):
    messages: Annotated[list, add_messages]

class MyNode:
    def __init__(self, name: str):
        self.name = name
    def __call__(self, state: State):
        return {"messages": [("assistant", f"Called node {self.name}")]}

def route(state) -> Literal["entry_node", END]:
    if len(state["messages"]) > 10:
        return END
    return "entry_node"

def add_fractal_nodes(builder, current_node, level, max_level):
    if level > max_level:
        return
    # Number of nodes to create at this level
    num_nodes = random.randint(1, 3)  # Adjust randomness as needed
    for i in range(num_nodes):
        nm = ["A", "B", "C"][i]
        node_name = f"node_{current_node}_{nm}"
        builder.add_node(node_name, MyNode(node_name))
        builder.add_edge(current_node, node_name)
        # Recursively add more nodes
        r = random.random()
        if r > 0.2 and level + 1 < max_level:
            add_fractal_nodes(builder, node_name, level + 1, max_level)
        elif r > 0.05:
            builder.add_conditional_edges(node_name, route, node_name)
        else:
            # End
            builder.add_edge(node_name, END)

def build_fractal_graph(max_level: int):
    builder = StateGraph(State)
    entry_point = "entry_node"
    builder.add_node(entry_point, MyNode(entry_point))
    builder.add_edge(START, entry_point)
    add_fractal_nodes(builder, entry_point, 1, max_level)
    # Optional: set a finish point if required
    builder.add_edge(entry_point, END)  # or any specific node
    return builder.compile()

app = build_fractal_graph(3)Mermaid
我们也可以将图类转换为 Mermaid 语法。
python
print(app.get_graph().draw_mermaid())%%{init: {'flowchart': {'curve': 'linear'}}}%%
graph TD;
tart__([<p>__start__</p>]):::first
ry_node(entry_node)
e_entry_node_A(node_entry_node_A)
e_entry_node_B(node_entry_node_B)
e_node_entry_node_B_A(node_node_entry_node_B_A)
e_node_entry_node_B_B(node_node_entry_node_B_B)
e_node_entry_node_B_C(node_node_entry_node_B_C)
nd__([<p>__end__</p>]):::last
tart__ --> entry_node;
ry_node --> __end__;
ry_node --> node_entry_node_A;
ry_node --> node_entry_node_B;
e_entry_node_B --> node_node_entry_node_B_A;
e_entry_node_B --> node_node_entry_node_B_B;
e_entry_node_B --> node_node_entry_node_B_C;
e_entry_node_A -.-> entry_node;
e_entry_node_A -.-> __end__;
e_node_entry_node_B_A -.-> entry_node;
e_node_entry_node_B_A -.-> __end__;
e_node_entry_node_B_B -.-> entry_node;
e_node_entry_node_B_B -.-> __end__;
e_node_entry_node_B_C -.-> entry_node;
e_node_entry_node_B_C -.-> __end__;
ssDef default fill:#f2f0ff,line-height:1.2
ssDef first fill-opacity:0
ssDef last fill:#bfb6fcPNG
如果愿意,我们可以将图渲染为 .png。这里我们可以使用三种选项:
- 使用 Mermaid.ink API(不需要额外的包)
- 使用 Mermaid + Pyppeteer(需要
pip install pyppeteer) - 使用 graphviz(需要
pip install graphviz)
使用 Mermaid.Ink
默认情况下,draw_mermaid_png() 使用 Mermaid.Ink 的 API 来生成图表。
python
from IPython.display import Image, display
from langchain_core.runnables.graph import CurveStyle, MermaidDrawMethod, NodeStyles

display(Image(app.get_graph().draw_mermaid_png()))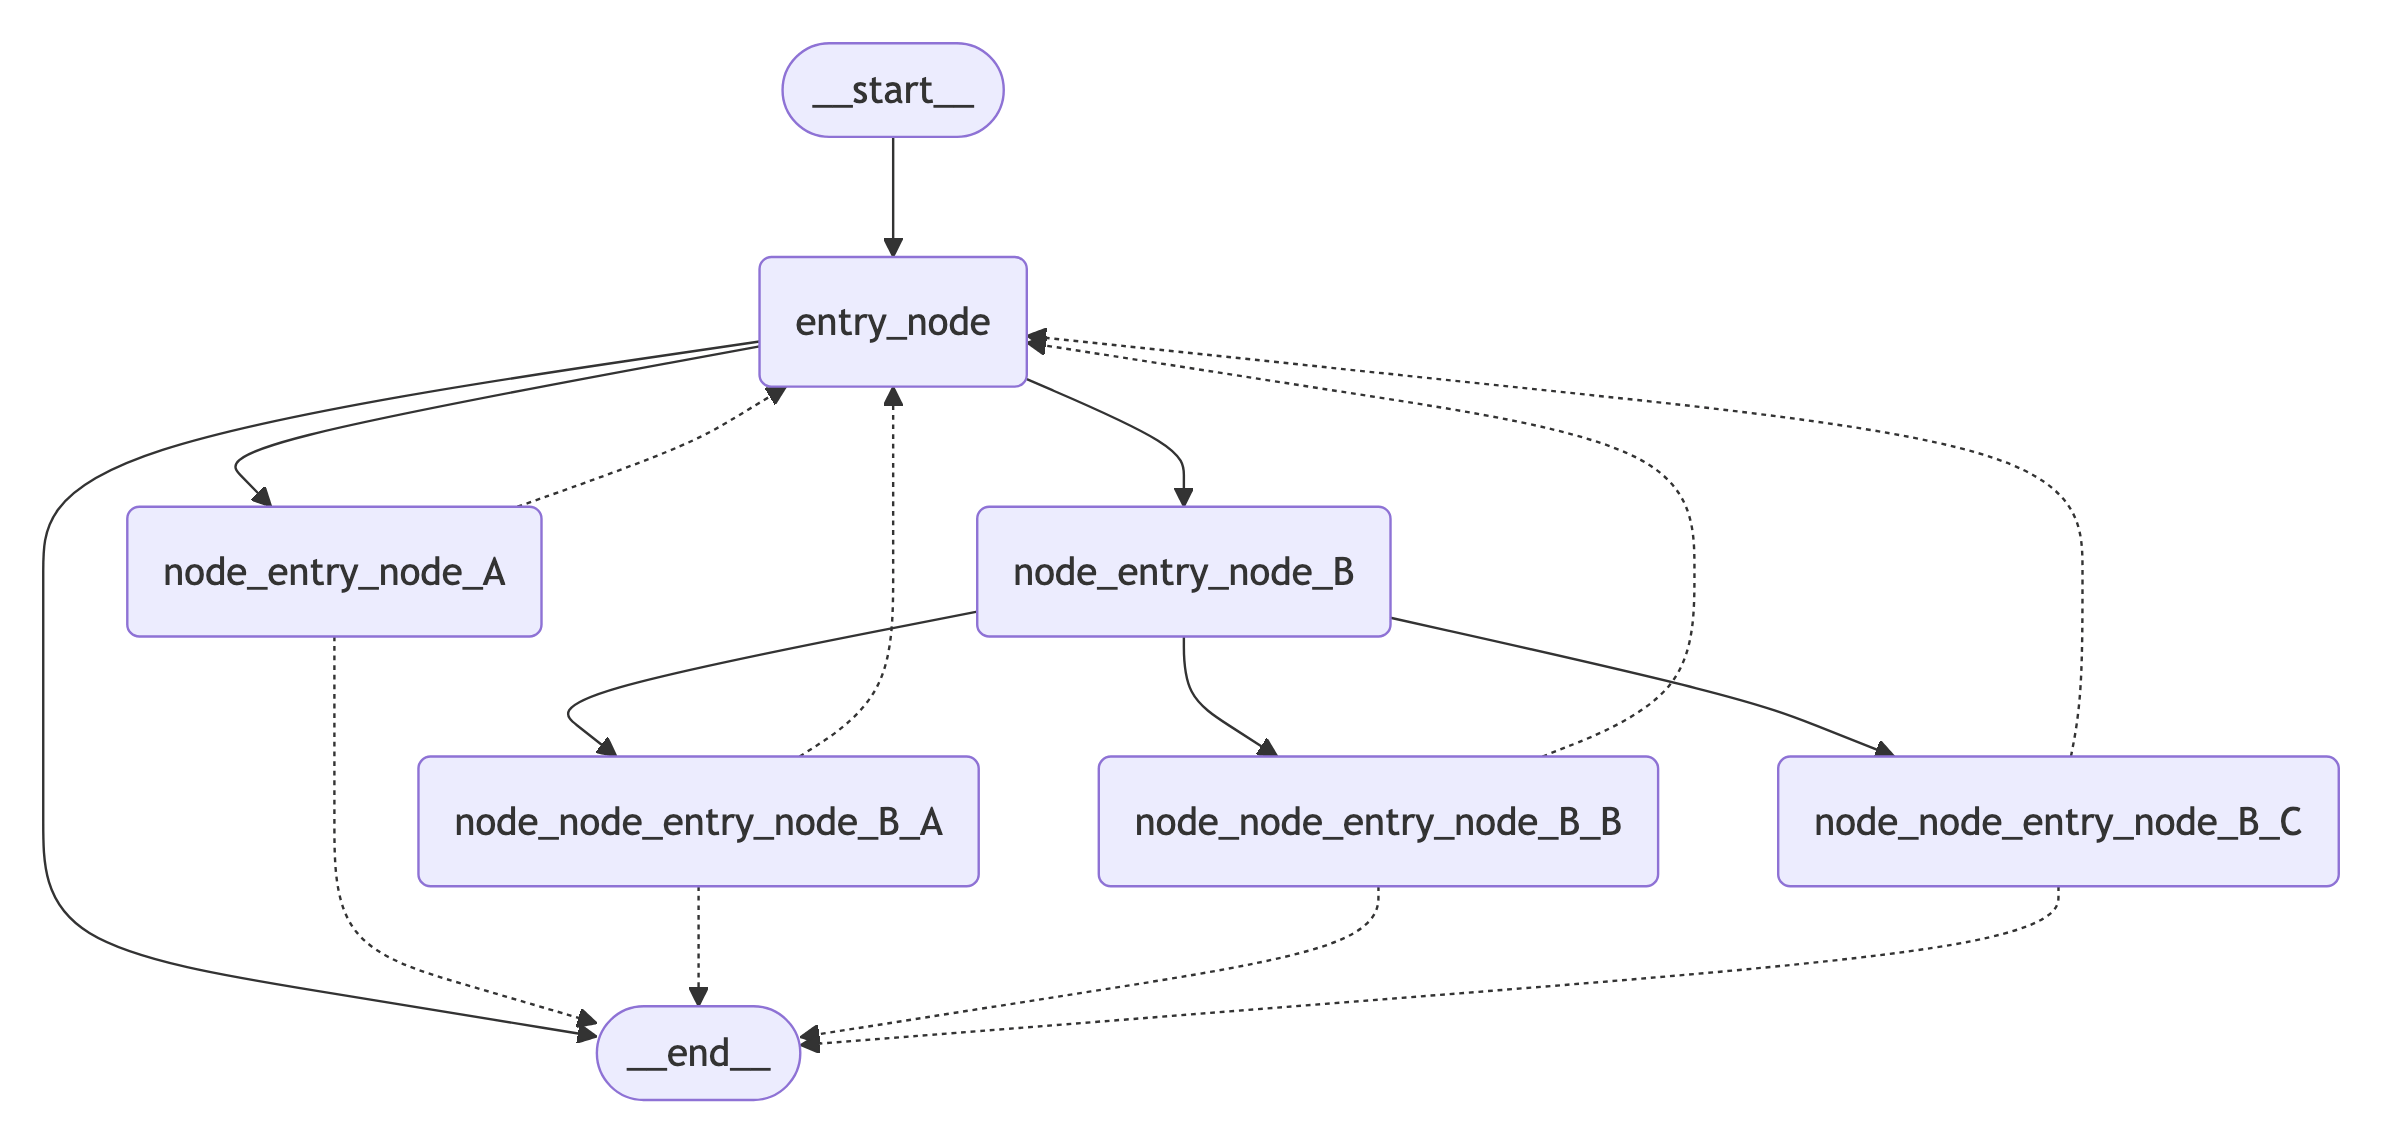
使用 Mermaid + Pyppeteer
python
import nest_asyncio

nest_asyncio.apply()  # Required for Jupyter Notebook to run async functions

display(
    Image(
        app.get_graph().draw_mermaid_png(
            curve_style=CurveStyle.LINEAR,
            node_colors=NodeStyles(first="#ffdfba", last="#baffc9", default="#fad7de"),
            wrap_label_n_words=9,
            output_file_path=None,
            draw_method=MermaidDrawMethod.PYPPETEER,
            background_color="white",
            padding=10,
        )
    )
)使用 Graphviz
python
try:
    display(Image(app.get_graph().draw_png()))
except ImportError:
    print(
        "You likely need to install dependencies for pygraphviz, see more here https://github.com/pygraphviz/pygraphviz/blob/main/INSTALL.txt"
    )