
主题
存储
LangGraph 存储提供跨线程的长期记忆,与每线程的检查点器持久化相辅相成。
存储让智能体能够跨线程持久化信息,包括用户偏好、累积的知识,以及应在单次对话之外保留的事实。与检查点器不同——后者保存作用域限定在单个线程的完整图状态——存储保存可从任何线程访问的任意键值数据。
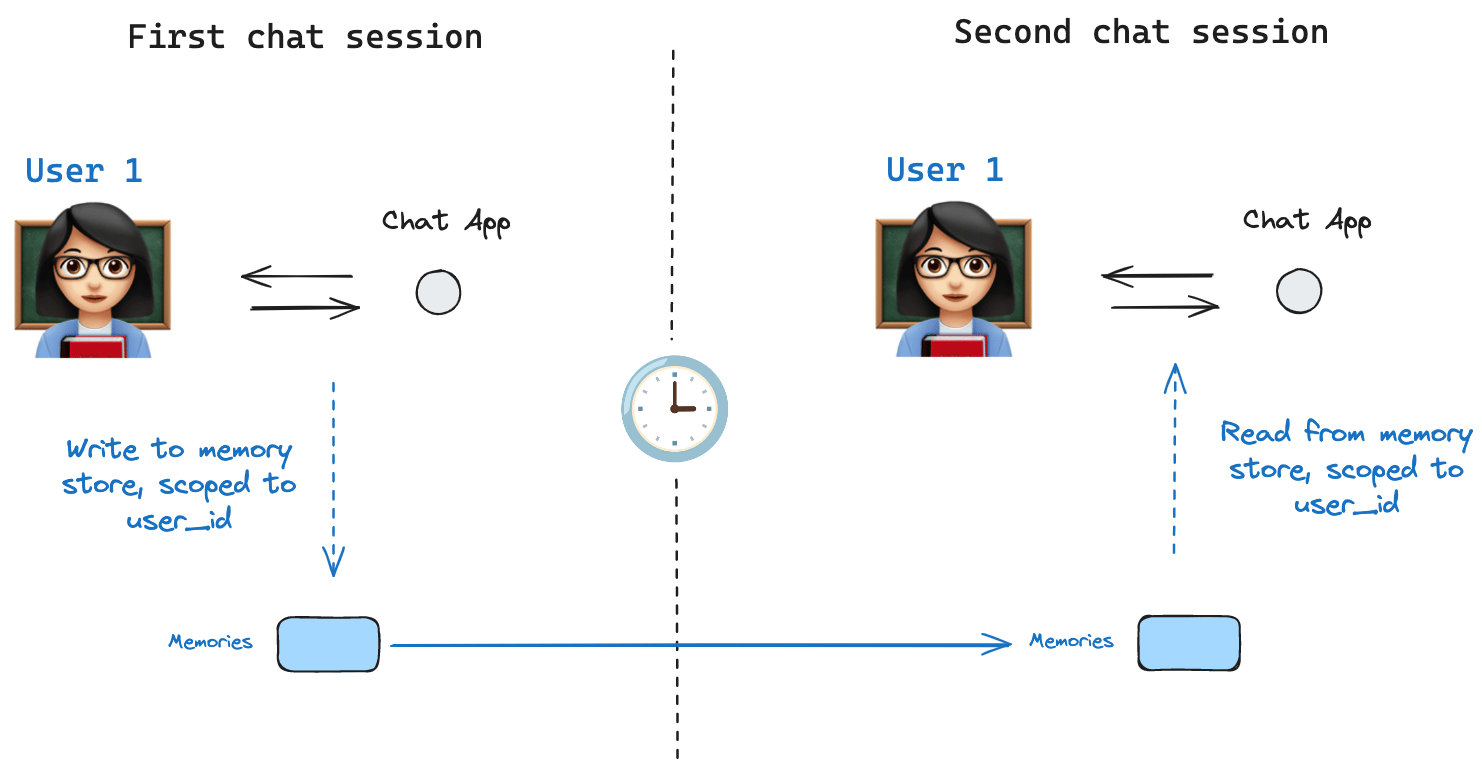
INFO
Agent Server 会自动处理存储 使用 Agent Server 时,你无需手动实现或配置存储。API 会在幕后为你处理所有存储基础设施。
NOTE
InMemoryStore 适用于开发和测试。对于生产环境,请使用持久化的存储,例如 PostgresStore、MongoDBStore、RedisStore 或 UpstashStore。所有实现都扩展自 BaseStore,后者是在节点函数签名中使用的类型注解。
NOTE
有关可用服务商的完整列表,请参阅存储集成。
基本用法
以下代码片段展示了独立使用 InMemoryStore(不使用 LangGraph)的情况:
python
from langgraph.store.memory import InMemoryStore
store = InMemoryStore()记忆以 tuple 作为命名空间,在下面的示例中是 (<user_id>, "memories")。命名空间可以是任意长度,表示任何内容,不必是用户特定的。
python
user_id = "1"
namespace_for_memory = (user_id, "memories")使用 store.put 方法将记忆保存到存储中的命名空间。指定如上定义的命名空间,以及记忆的键值对:键只是记忆的唯一标识符(memory_id),值(一个字典)就是记忆本身。
python
memory_id = str(uuid.uuid4())
memory = {"food_preference" : "I like pizza"}
store.put(namespace_for_memory, memory_id, memory)使用 store.search 方法从你的命名空间中读出记忆,它会将给定用户的记忆以列表形式返回,最多到 limit 参数指定的数量(默认为 10)。使用 InMemoryStore 时,条目按插入顺序返回,因此最近的记忆在列表最后;其他后端可能以不同方式排序记忆(请参阅列出命名空间中的条目)。
python
memories = store.search(namespace_for_memory)
memories[-1].dict()
{'value': {'food_preference': 'I like pizza'},
 'key': '07e0caf4-1631-47b7-b15f-65515d4c1843',
 'namespace': ['1', 'memories'],
 'created_at': '2024-10-02T17:22:31.590602+00:00',
'updated_at': '2024-10-02T17:22:31.590605+00:00'}每种记忆类型都是一个 Python 类(Item),具有特定的属性。我们可以通过 .dict 将其转换为字典来访问它。
它具有的属性有:
value:此记忆的值(本身是一个字典)key:此记忆在此命名空间中的唯一键namespace:一个字符串元组,即此记忆类型的命名空间
NOTE
虽然类型是 tuple[str, ...],但在转换为 JSON 时它可能会被序列化为列表(例如 ['1', 'memories'])。
created_at:此记忆的创建时间戳updated_at:此记忆的更新时间戳
列出命名空间中的条目
在既不传 query 也不传 filter 的情况下调用 store.search(或异步的 store.asearch),会返回存储在 namespace_prefix 下的条目,最多到 limit。当你不需要语义排序时,可用它来枚举命名空间中的所有内容。
python
# Return up to 100 items stored under ("alice", "memories").
items = store.search(("alice", "memories"), limit=100)需要记住三种行为:
namespace_prefix按前缀匹配,而不是精确匹配。("alice",)也会返回("alice", "memories")、("alice", "preferences")等下的条目。要限制在单个层级,请传入完整命名空间,或在客户端按item.namespace过滤返回的条目。- 超出
limit的结果会被静默截断。 没有溢出信号——请将limit设置得高于你预期的最大值,或使用offset分页。 - 默认排序取决于存储后端。
PostgresStore和AsyncPostgresStore返回按updated_at降序排列的结果(最近更新的在前)。InMemoryStore按插入顺序返回结果(最近插入的在最后)。不要依赖跨实现的一致顺序;如果顺序很重要,请在客户端按item.updated_at排序。
要翻阅一个大型命名空间:
python
page_size = 50
offset = 0
while True:
    page = store.search(("alice", "memories"), limit=page_size, offset=offset)
    if not page:
        break
    for item in page:
        pass
offset += page_size要发现存在哪些命名空间(例如,在列出每个用户的记忆之前遍历所有用户),请使用 store.list_namespaces 或 store.alist_namespaces:
python
# All namespaces that start with ("alice",), truncated to two levels deep.
namespaces = store.list_namespaces(prefix=("alice",), max_depth=2)语义搜索
除了简单的检索之外,存储还支持语义搜索,让你能够基于含义而非精确匹配来查找记忆。要启用此功能,请使用嵌入模型配置存储:
python
from langchain.embeddings import init_embeddings

store = InMemoryStore(
    index={
        "embed": init_embeddings("openai:text-embedding-3-small"),  # Embedding provider
        "dims": 1536,                              # Embedding dimensions
        "fields": ["food_preference", "$"]              # Fields to embed
    }
)现在搜索时,你可以使用自然语言查询来查找相关的记忆:
python
# Find memories about food preferences
# (This can be done after putting memories into the store)
memories = store.search(
    namespace_for_memory,
    query="What does the user like to eat?",
    limit=3  # Return top 3 matches
)你可以通过配置 fields 参数,或在存储记忆时指定 index 参数,来控制记忆中哪些部分会被嵌入:
python
# Store with specific fields to embed
store.put(
    namespace_for_memory,
    str(uuid.uuid4()),
    {
        "food_preference": "I love Italian cuisine",
        "context": "Discussing dinner plans"
    },
    index=["food_preference"]  # Only embed "food_preferences" field
)

# Store without embedding (still retrievable, but not searchable)
store.put(
    namespace_for_memory,
    str(uuid.uuid4()),
    {"system_info": "Last updated: 2024-01-01"},
    index=False
)在 LangGraph 中使用
存储与检查点器协同工作:如上所述,检查点器将状态保存到线程,而存储允许你保存任意信息以便跨线程访问。如下所示,同时使用检查点器和存储来编译图。
python
from dataclasses import dataclass
from langgraph.checkpoint.memory import InMemorySaver

@dataclass
class Context:
    user_id: str

# We need this because we want to enable threads (conversations)
checkpointer = InMemorySaver()

# ... Define the graph ...

# Compile the graph with the checkpointer and store
builder = StateGraph(MessagesState, context_schema=Context)
# ... add nodes and edges ...
graph = builder.compile(checkpointer=checkpointer, store=store)然后像之前一样使用 thread_id 调用图,同时也传入 user_id,它像之前一样作为此特定用户记忆的命名空间。
python
# Invoke the graph
config = {"configurable": {"thread_id": "1"}}

# First let's just say hi to the AI
for update in graph.stream(
    {"messages": [{"role": "user", "content": "hi"}]},
    config,
    stream_mode="updates",
    context=Context(user_id="1"),
):
print(update)你可以使用 Runtime 对象从任何节点访问存储和 user_id。当你将 Runtime 作为参数添加到节点函数时,LangGraph 会自动注入它。你可以用它来保存记忆:
python
from langgraph.runtime import Runtime
from dataclasses import dataclass

@dataclass
class Context:
    user_id: str

async def update_memory(state: MessagesState, runtime: Runtime[Context]):

    # Get the user id from the runtime context
    user_id = runtime.context.user_id

    # Namespace the memory
    namespace = (user_id, "memories")

    # ... Analyze conversation and create a new memory

    # Create a new memory ID
    memory_id = str(uuid.uuid4())

    # We create a new memory
await runtime.store.aput(namespace, memory_id, {"memory": memory})你也可以从任何节点访问存储,并使用 store.search 方法获取记忆。记忆以对象列表的形式返回,可以转换为字典。
python
memories[-1].dict()
{'value': {'food_preference': 'I like pizza'},
 'key': '07e0caf4-1631-47b7-b15f-65515d4c1843',
 'namespace': ['1', 'memories'],
 'created_at': '2024-10-02T17:22:31.590602+00:00',
'updated_at': '2024-10-02T17:22:31.590605+00:00'}你访问这些记忆,并在模型调用中使用它们。
python
from dataclasses import dataclass
from langgraph.runtime import Runtime

@dataclass
class Context:
    user_id: str

async def call_model(state: MessagesState, runtime: Runtime[Context]):
    # Get the user id from the runtime context
    user_id = runtime.context.user_id

    # Namespace the memory
    namespace = (user_id, "memories")

    # Search based on the most recent message
    memories = await runtime.store.asearch(
        namespace,
        query=state["messages"][-1].content,
        limit=3
    )
    info = "\n".join([d.value["memory"] for d in memories])

# ... Use memories in the model call如果你创建一个新线程,只要 user_id 相同,你仍然可以访问相同的记忆。
python
# Invoke the graph on a new thread
config = {"configurable": {"thread_id": "2"}}

# Let's say hi again
for update in graph.stream(
    {"messages": [{"role": "user", "content": "hi, tell me about my memories"}]},
    config,
    stream_mode="updates",
    context=Context(user_id="1"),
):
print(update)当你在本地(例如在 Studio 中)或托管式使用 LangSmith 时,基础存储默认可用,你无需在图编译期间指定它。不过,要启用语义搜索,你确实需要在 langgraph.json 文件中配置索引设置。例如:
json
{
    ...
    "store": {
        "index": {
            "embed": "openai:text-embeddings-3-small",
            "dims": 1536,
            "fields": ["$"]
        }
    }
}有关更多详细信息和配置选项,请参阅部署指南。
构建自定义存储
要使用除内置实现之外的存储后端,请继承 BaseStore 并实现其必需的方法。内置的 InMemoryStore 是最简单的参考实现。
基础契约
所有五个异步方法都是必需的。同步对应方法(put、get、delete、search、list_namespaces)是可选的,但为了与同步图执行兼容,建议实现它们。
| 方法 | 描述 |
|---|---|
aput(namespace, key, value, index=None) | 存储或覆盖单个条目 |
aget(namespace, key) | 按键检索单个条目;如果缺失则返回 None |
adelete(namespace, key) | 删除单个条目 |
asearch(namespace_prefix, *, query=None, filter=None, limit=10, offset=0) | 在某个命名空间前缀下搜索条目;可选地按语义查询搜索 |
alist_namespaces(*, prefix=None, suffix=None, max_depth=None, limit=100, offset=0) | 列出匹配前缀/后缀模式的命名空间 |
在实现之前,请查阅确切的签名:
python
import inspect
from langgraph.store.base import BaseStore
print(inspect.getsource(BaseStore))命名空间设计
命名空间是字符串元组,例如 ("user_id", "memories")。存储实现必须支持:
- 前缀匹配:
asearch(("alice",))返回("alice",)、("alice", "memories")以及任何其他子命名空间下的条目。 - 精确键查找:
aget(("alice", "memories"), "some-key")必须是 O(1) 或接近 O(1)。
对于 SQL 后端,一种常见的 schema:
sql
CREATE TABLE store_items (
    namespace   TEXT[] NOT NULL,
    key         TEXT NOT NULL,
    value       JSONB NOT NULL,
    created_at  TIMESTAMPTZ DEFAULT now(),
    updated_at  TIMESTAMPTZ DEFAULT now(),
    PRIMARY KEY (namespace, key)
);

CREATE INDEX ON store_items USING gin(namespace);序列化
存储值是普通的 Python 字典——不需要特殊的序列化器。直接使用 json.dumps / json.loads 或 JSONB 列进行序列化。不要存储无法 JSON 序列化的原始 Python 对象。
语义搜索支持
如果你的后端支持向量搜索,请在 asearch 上实现 query 参数:
- 接受一个
query: str | None参数。 - 当
query不为None时,对它进行嵌入,并按余弦相似度对结果排序。 - 当提供了
query时,结果中每个Item上应包含一个score字段。
如果你的后端不支持向量搜索,请在传入 query 时抛出 NotImplementedError。
测试
目前还没有针对自定义存储的一致性测试套件。请以 InMemoryStore 作为参考进行测试:
python
import pytest
from langgraph.store.memory import InMemoryStore
from your_module import YourStore

@pytest.fixture
async def store():
    async with YourStore.create() as s:
        yield s

@pytest.fixture
def reference():
    return InMemoryStore()

async def test_put_and_get(store, reference):
    ns = ("test", "ns")
    for s in [store, reference]:
        await s.aput(ns, "k1", {"val": 1})
        item = await s.aget(ns, "k1")
        assert item is not None
        assert item.value == {"val": 1}

async def test_delete(store, reference):
    ns = ("test", "ns")
    for s in [store, reference]:
        await s.aput(ns, "k1", {"val": 1})
        await s.adelete(ns, "k1")
        assert await s.aget(ns, "k1") is None

async def test_search_prefix(store, reference):
    for s in [store, reference]:
        await s.aput(("user", "memories"), "m1", {"text": "likes pizza"})
        results = await s.asearch(("user",))
assert any(r.key == "m1" for r in results)后续步骤
- 向 Agent Server 添加自定义存储 — 部署你的实现
- 检查点器 — 线程作用域内的状态持久化