主题
在新版本 agent 上运行回测
部署应用程序只是持续改进过程的开始。部署到生产后,你会希望通过增强提示、语言模型、工具和架构来改进系统。回测涉及使用历史数据评估应用程序的新版本,并将新输出与原始输出进行比较。与使用生产前数据集进行评估相比,回测能更清晰地表明应用程序的新版本是否优于当前部署。
以下是回测的基本步骤:
- 从生产追踪项目中选择样本运行进行测试。
- 将运行输入转换为数据集,并将运行输出记录为该数据集上的初始实验。
- 在新数据集上执行新系统,并比较实验结果。
此过程将为你提供一个具有代表性输入的新数据集,你可以对其进行版本控制并用于回测模型。
INFO
通常,你可能没有确定的 "ground truth" 答案。在这种情况下,你可以手动标注输出,或使用不依赖参考数据的评估器。如果你的应用程序允许捕获 ground-truth 标签(例如允许用户留下反馈),我们强烈建议这样做。
设置
配置环境
安装并设置环境变量。本指南需要 langsmith>=0.2.4。
INFO
为方便起见,本教程将使用 LangChain OSS 框架,但所展示的 LangSmith 功能与框架无关。
bash
pip install -U langsmith langchain langchain-anthropic langchainhub emojibash
uv add langsmith langchain langchain-anthropic langchainhub emojipython
import getpass
import os

# Set the project name to whichever project you'd like to be testing against
project_name = "Tweet Writing Task"
os.environ["LANGSMITH_PROJECT"] = project_name
os.environ["LANGSMITH_TRACING"] = "true"

if not os.environ.get("LANGSMITH_API_KEY"):
    os.environ["LANGSMITH_API_KEY"] = getpass.getpass("YOUR API KEY")

# Optional. You can swap OpenAI for any other tool-calling chat model.
os.environ["OPENAI_API_KEY"] = "YOUR OPENAI API KEY"

# Optional. You can swap Tavily for the free DuckDuckGo search tool if preferred.
# Get Tavily API key: https://tavily.com
os.environ["TAVILY_API_KEY"] = "YOUR TAVILY API KEY"定义应用程序
在此示例中,让我们创建一个可以访问一些互联网搜索工具的简单 Tweet 写作应用程序:
python
from langchain.chat_models import init_chat_model
from langchain.agents import create_agent
from langchain_community.tools import DuckDuckGoSearchRun, TavilySearchResults
from langchain.rate_limiters import InMemoryRateLimiter

# We will use GPT-3.5 Turbo as the baseline and compare against GPT-4o
gpt_3_5_turbo = init_chat_model(
    "gpt-3.5-turbo",
    temperature=1,
    configurable_fields=("model", "model_provider"),
)

# The instructions are passed as a system message to the agent
instructions = """You are a tweet writing assistant. Given a topic, do some research and write a relevant and engaging tweet about it.
- Use at least 3 emojis in each tweet
- The tweet should be no longer than 280 characters
- Always use the search tool to gather recent information on the tweet topic
- Write the tweet only based on the search content. Do not rely on your internal knowledge
- When relevant, link to your sources
- Make your tweet as engaging as possible"""

# Define the tools our agent can use
# If you have a higher tiered Tavily API plan you can increase this
rate_limiter = InMemoryRateLimiter(requests_per_second=0.08)

# Use DuckDuckGo if you don't have a Tavily API key:
# tools = [DuckDuckGoSearchRun(rate_limiter=rate_limiter)]
tools = [TavilySearchResults(max_results=5, rate_limiter=rate_limiter)]

agent = create_agent(gpt_3_5_turbo, tools=tools, system_prompt=instructions)模拟生产数据
现在让我们模拟一些生产数据:
python
fake_production_inputs = [
    "Alan turing's early childhood",
    "Economic impacts of the European Union",
    "Underrated philosophers",
    "History of the Roxie theater in San Francisco",
    "ELI5: gravitational waves",
    "The arguments for and against a parliamentary system",
    "Pivotal moments in music history",
    "Big ideas in programming languages",
    "Big questions in biology",
    "The relationship between math and reality",
    "What makes someone funny",
]

agent.batch(
    [{"messages": [{"role": "user", "content": content}]} for content in fake_production_inputs],
)将生产追踪转换为实验
第一步是基于生产输入生成数据集。然后复制所有追踪以作为基线实验。
选择要回测的运行
你可以使用 list_runs 的 filter 参数选择要回测的运行。filter 参数使用 LangSmith 追踪查询语法来选择运行。
python
from datetime import datetime, timedelta, timezone
from uuid import uuid4
from langsmith import Client
from langsmith.beta import convert_runs_to_test

# Fetch the runs we want to convert to a dataset/experiment
client = Client()

# How we are sampling runs to include in our dataset
end_time = datetime.now(tz=timezone.utc)
start_time = end_time - timedelta(days=1)
run_filter = f'and(gt(start_time, "{start_time.isoformat()}"), lt(end_time, "{end_time.isoformat()}"))'
prod_runs = list(
    client.list_runs(
        project_name=project_name,
        is_root=True,
        filter=run_filter,
    )
)将运行转换为实验
convert_runs_to_test 是一个函数,它接收一些运行并执行以下操作:
- 输入以及可选的输出会作为 Examples 保存到数据集。
- 输入和输出会存储为一个实验,就像你运行了
evaluate函数并收到了那些输出一样。
python
# Name of the dataset we want to create
dataset_name = f'{project_name}-backtesting {start_time.strftime("%Y-%m-%d")}-{end_time.strftime("%Y-%m-%d")}'
# Name of the experiment we want to create from the historical runs
baseline_experiment_name = f"prod-baseline-gpt-3.5-turbo-{str(uuid4())[:4]}"

# This converts the runs to a dataset + experiment
convert_runs_to_test(
    prod_runs,
    # Name of the resulting dataset
    dataset_name=dataset_name,
    # Whether to include the run outputs as reference/ground truth
    include_outputs=False,
    # Whether to include the full traces in the resulting experiment
    # (default is to just include the root run)
    load_child_runs=True,
    # Name of the experiment so we can apply evalautors to it after
    test_project_name=baseline_experiment_name
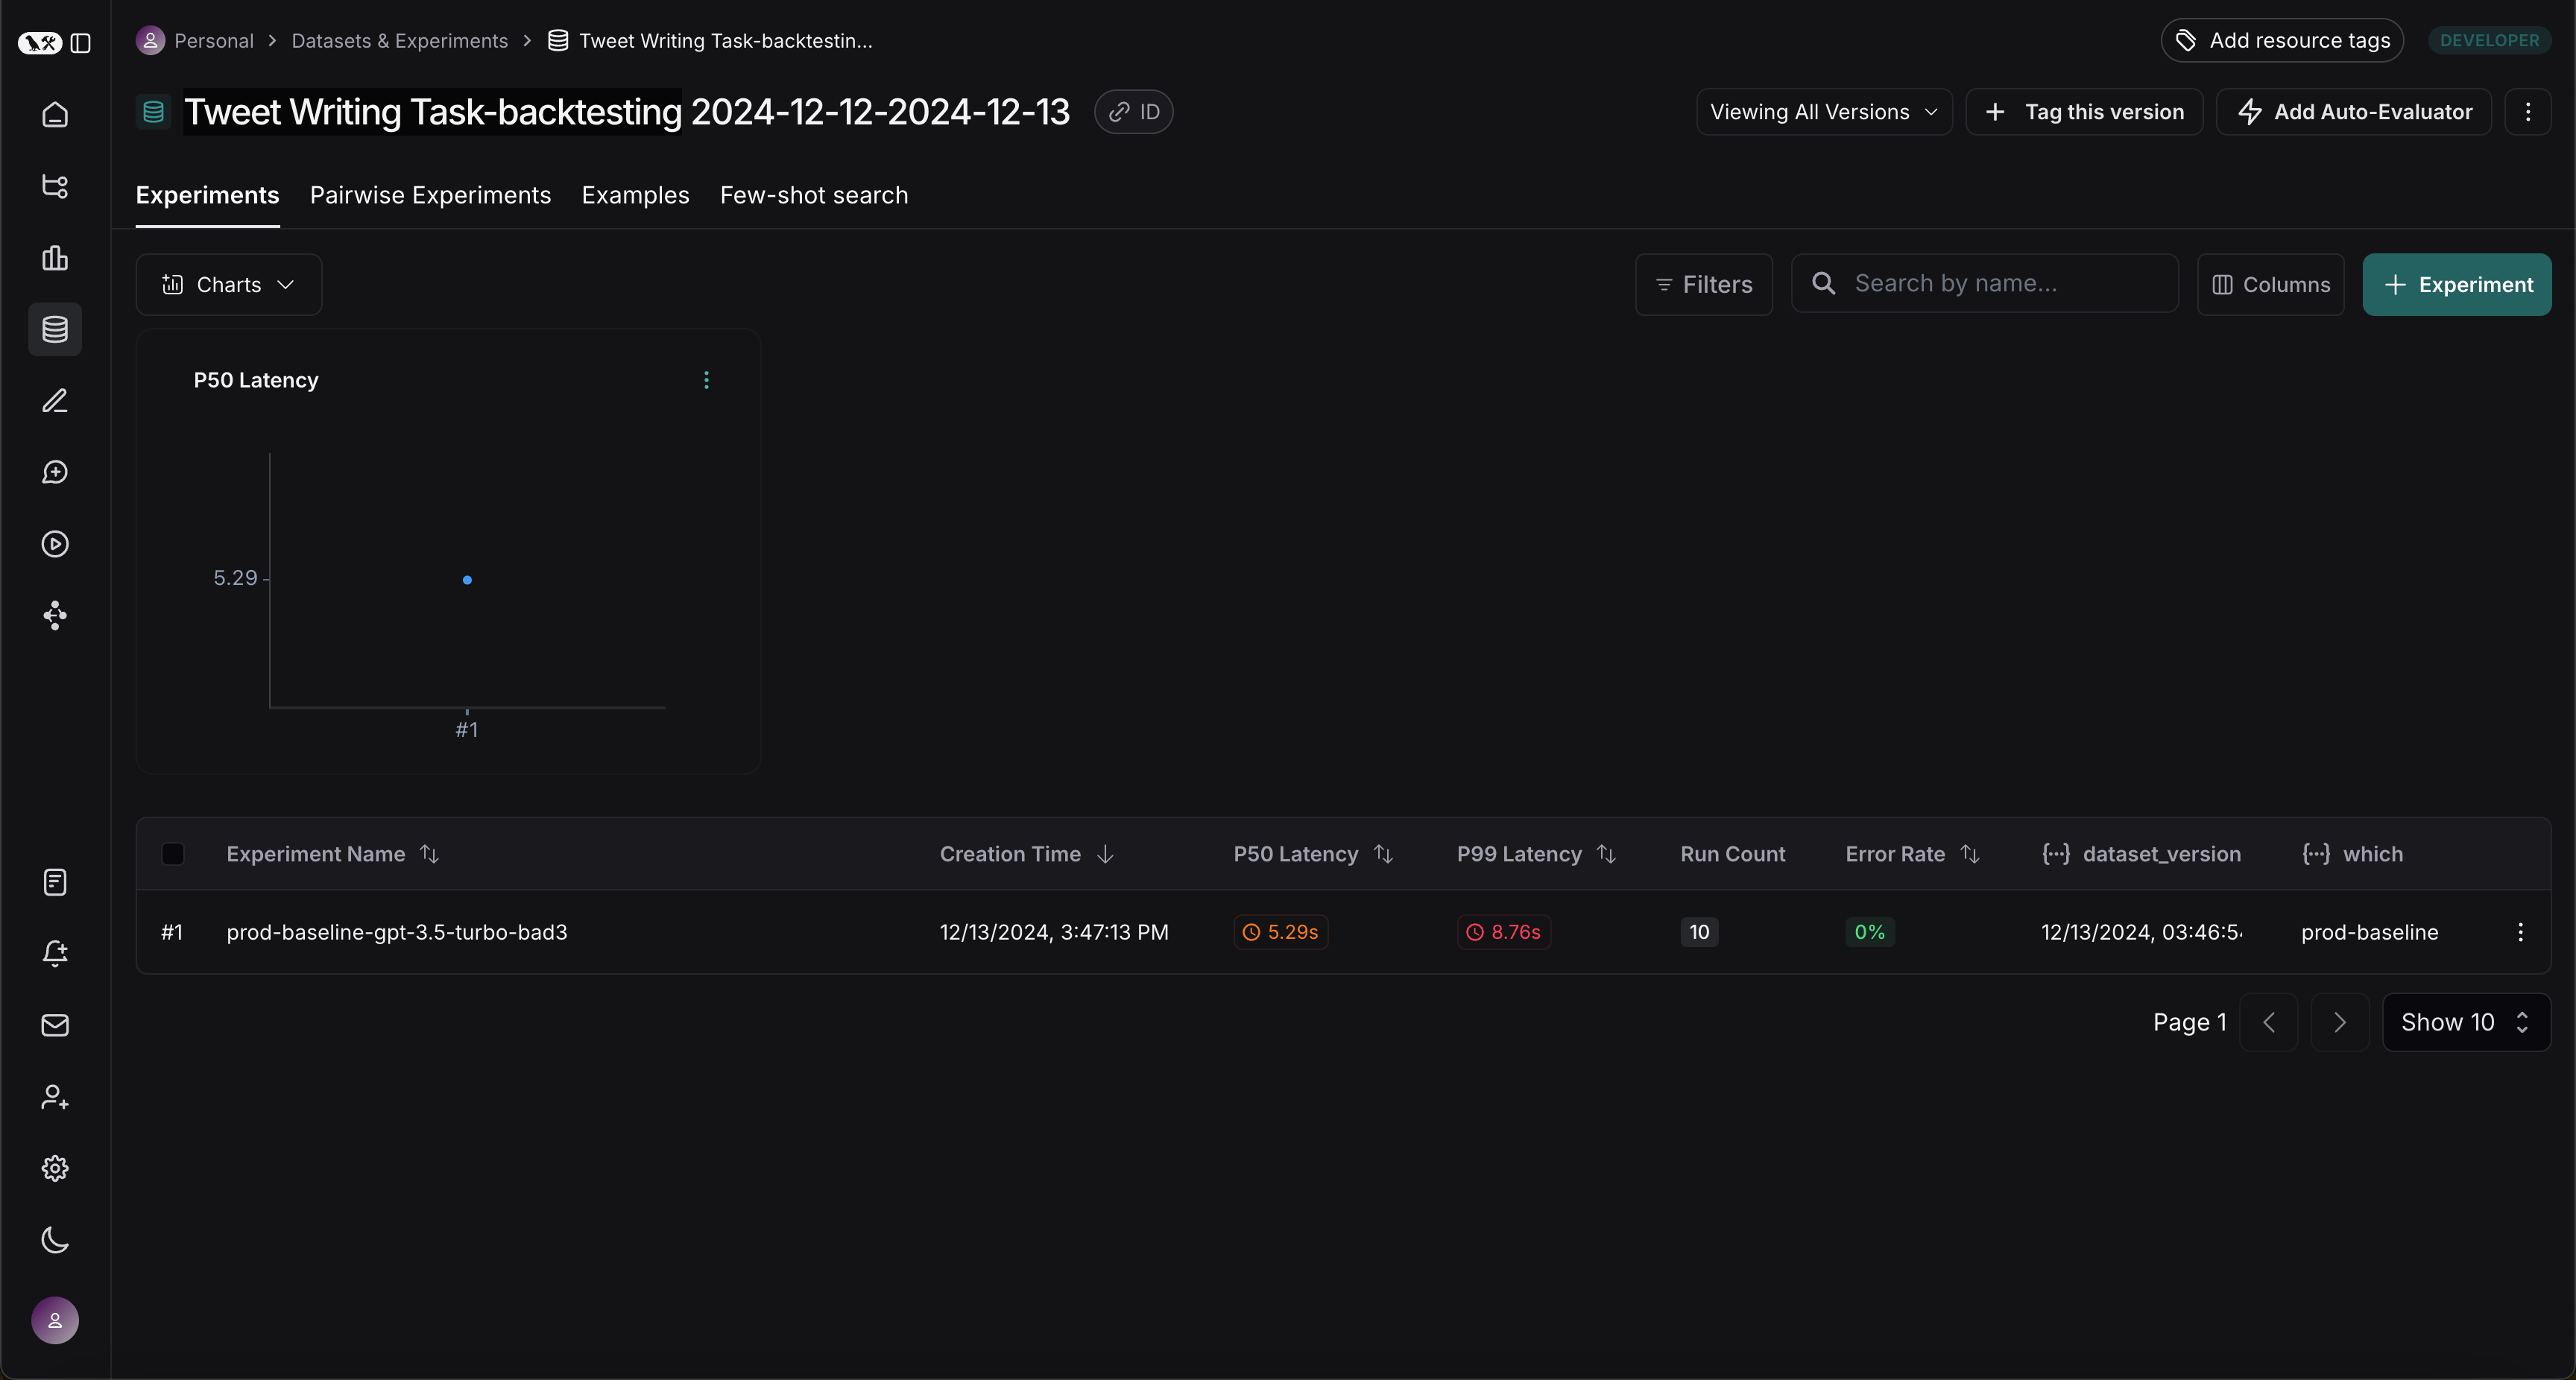
)完成此步骤后,你应该会在 LangSmith 项目中看到名为 "Tweet Writing Task-backtesting TODAYS DATE" 的新数据集,其中包含一个如下所示的实验:
与新系统进行基准比较
现在我们可以开始将生产运行与新系统进行基准比较的过程。
定义评估器
首先,让我们定义用于比较两个系统的评估器。请注意,我们没有参考输出,因此需要设计仅需要实际输出的评估指标。
python
import emoji
from pydantic import BaseModel, Field
from langchain_core.messages import convert_to_openai_messages

class Grade(BaseModel):
    """Grade whether a response is supported by some context."""
    grounded: bool = Field(..., description="Is the majority of the response supported by the retrieved context?")

grounded_instructions = f"""You have given somebody some contextual information and asked them to write a statement grounded in that context.

Grade whether their response is fully supported by the context you have provided. \
If any meaningful part of their statement is not backed up directly by the context you provided, then their response is not grounded. \
Otherwise it is grounded."""
grounded_model = init_chat_model(model="gpt-5.5").with_structured_output(Grade)

def lt_280_chars(outputs: dict) -> bool:
    messages = convert_to_openai_messages(outputs["messages"])
    return len(messages[-1]['content']) <= 280

def gte_3_emojis(outputs: dict) -> bool:
    messages = convert_to_openai_messages(outputs["messages"])
    return len(emoji.emoji_list(messages[-1]['content'])) >= 3

async def is_grounded(outputs: dict) -> bool:
    context = ""
    messages = convert_to_openai_messages(outputs["messages"])
    for message in messages:
        if message["role"] == "tool":
            # Tool message outputs are the results returned from the Tavily/DuckDuckGo tool
            context += "\n\n" + message["content"]
    tweet = messages[-1]["content"]
    user = f"""CONTEXT PROVIDED:
    {context}

    RESPONSE GIVEN:
    {tweet}"""
    grade = await grounded_model.ainvoke([
        {"role": "system", "content": grounded_instructions},
        {"role": "user", "content": user}
    ])
return grade.grounded评估基线
现在,让我们针对基线实验运行评估器。
python
baseline_results = await client.aevaluate(
    baseline_experiment_name,
    evaluators=[lt_280_chars, gte_3_emojis, is_grounded],
)
# If you have pandas installed can easily explore results as df:
# baseline_results.to_pandas()定义并评估新系统
现在,让我们定义并评估新系统。在此示例中,新系统将与旧系统相同,但会使用 GPT-4o 而不是 GPT-3.5。由于我们已将模型设为可配置,因此只需更新传递给 agent 的默认配置:
python
candidate_results = await client.aevaluate(
    agent.with_config(model="gpt-5.5"),
    data=dataset_name,
    evaluators=[lt_280_chars, gte_3_emojis, is_grounded],
    experiment_prefix="candidate-gpt-5.5",
)
# If you have pandas installed can easily explore results as df:
# candidate_results.to_pandas()比较结果
运行两个实验后,你可以在数据集中查看它们:
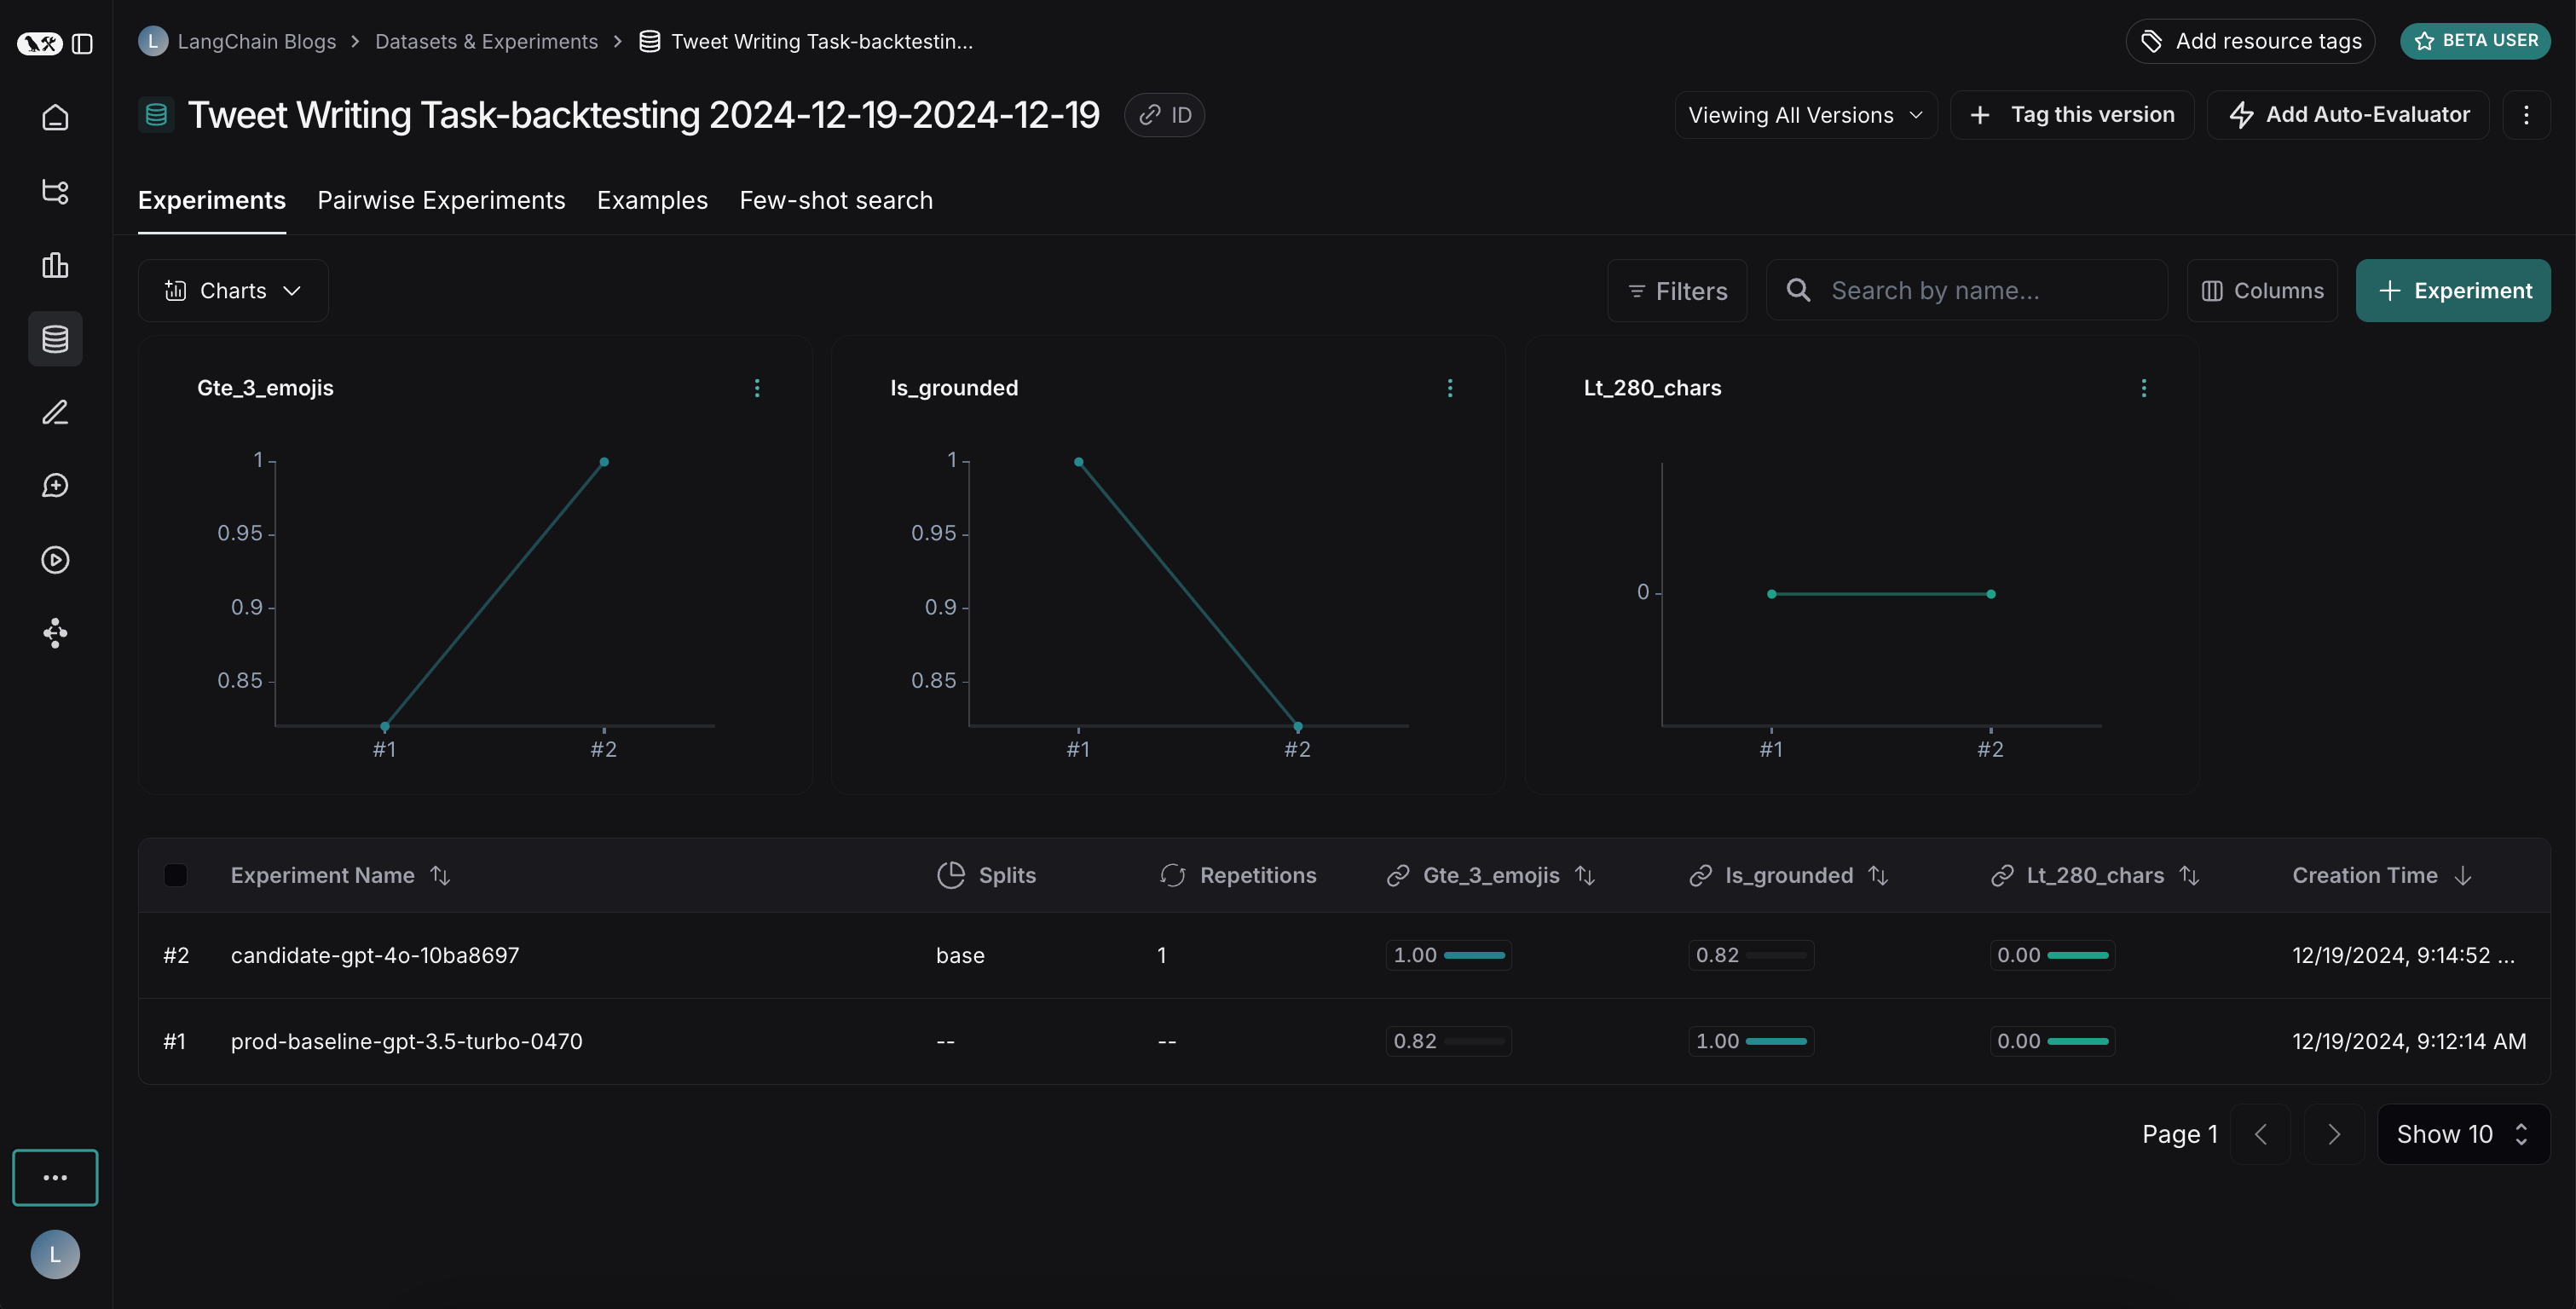
结果揭示了两者之间有趣的权衡:
- GPT-4o 在遵循格式规则方面表现出更好的性能,始终包含请求数量的 emoji
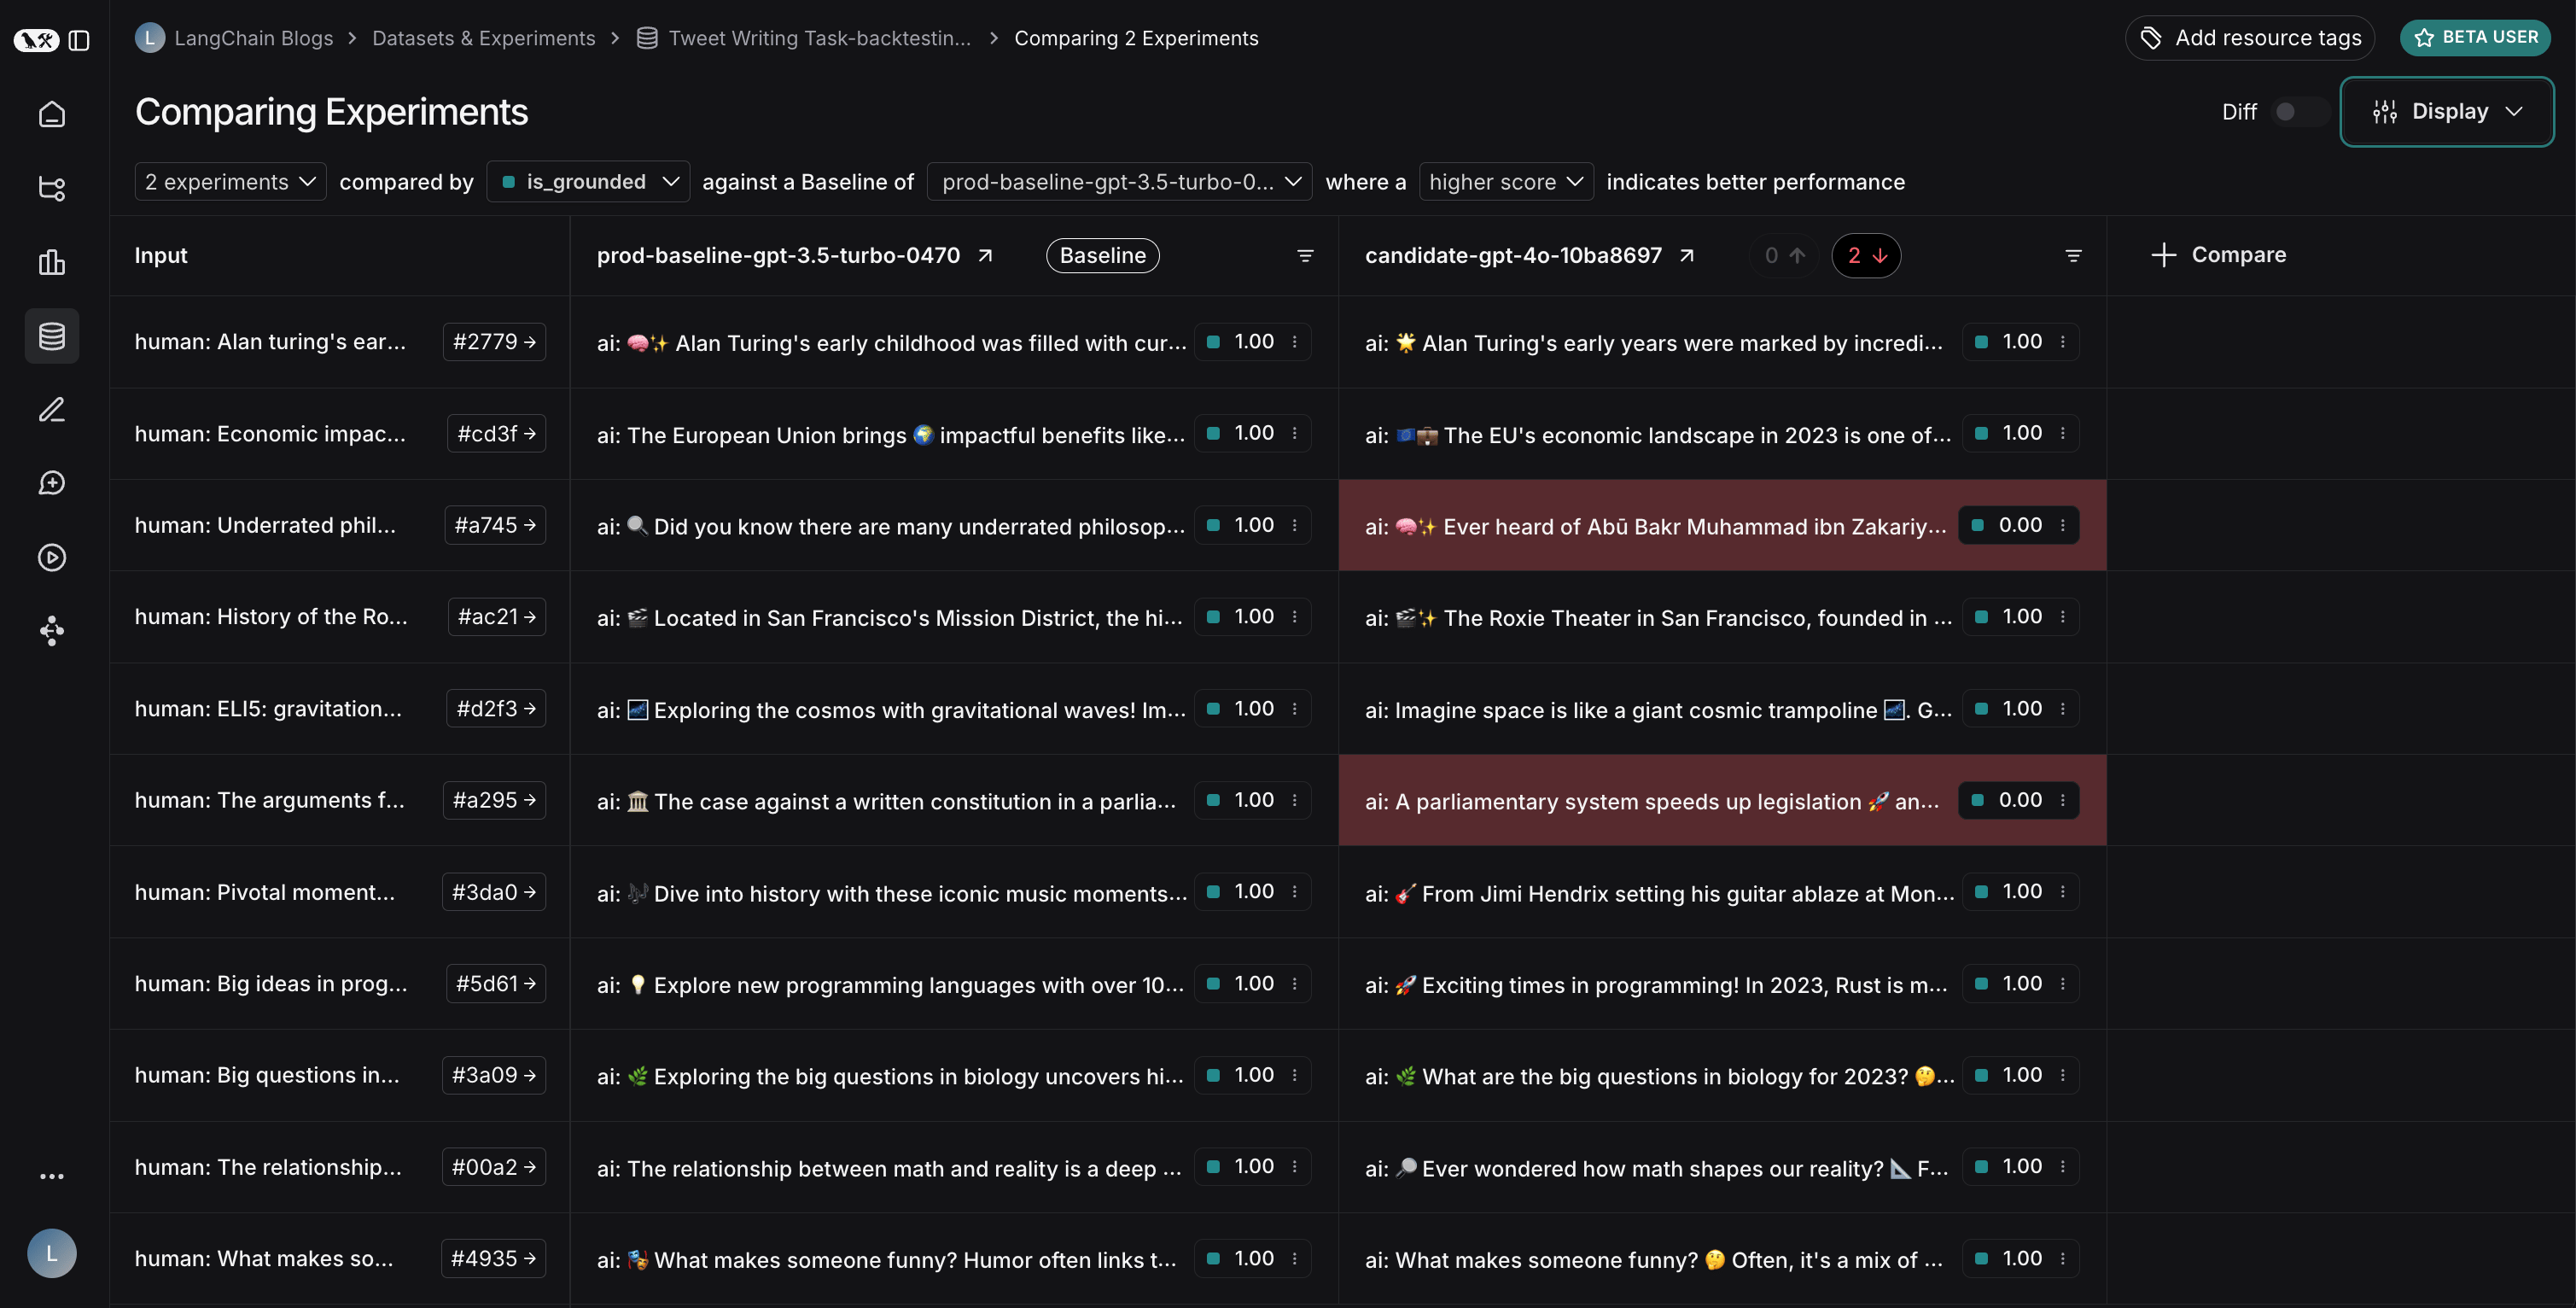
- 然而,GPT-4o 在保持基于所提供搜索结果方面不太可靠
为了说明接地问题:在此示例运行中,GPT-4o 包含了搜索结果中不存在的关于 Abū Bakr Muhammad ibn Zakariyyā al-Rāzī 医学贡献的事实。这表明它是从内部知识中提取,而不是严格使用提供的信息。
这次回测练习表明,虽然 GPT-4o 通常被认为是能力更强的模型,但仅仅升级到它并不会改进我们的推文写作器。要有效使用 GPT-4o,我们需要:
- 改进提示,更加强调仅使用所提供的信息
- 或修改系统架构,以更好地约束模型的输出
这一洞察展示了回测的价值——它帮助我们在部署前识别潜在问题。