主题
如何运行成对评估
INFO
概念:成对评估
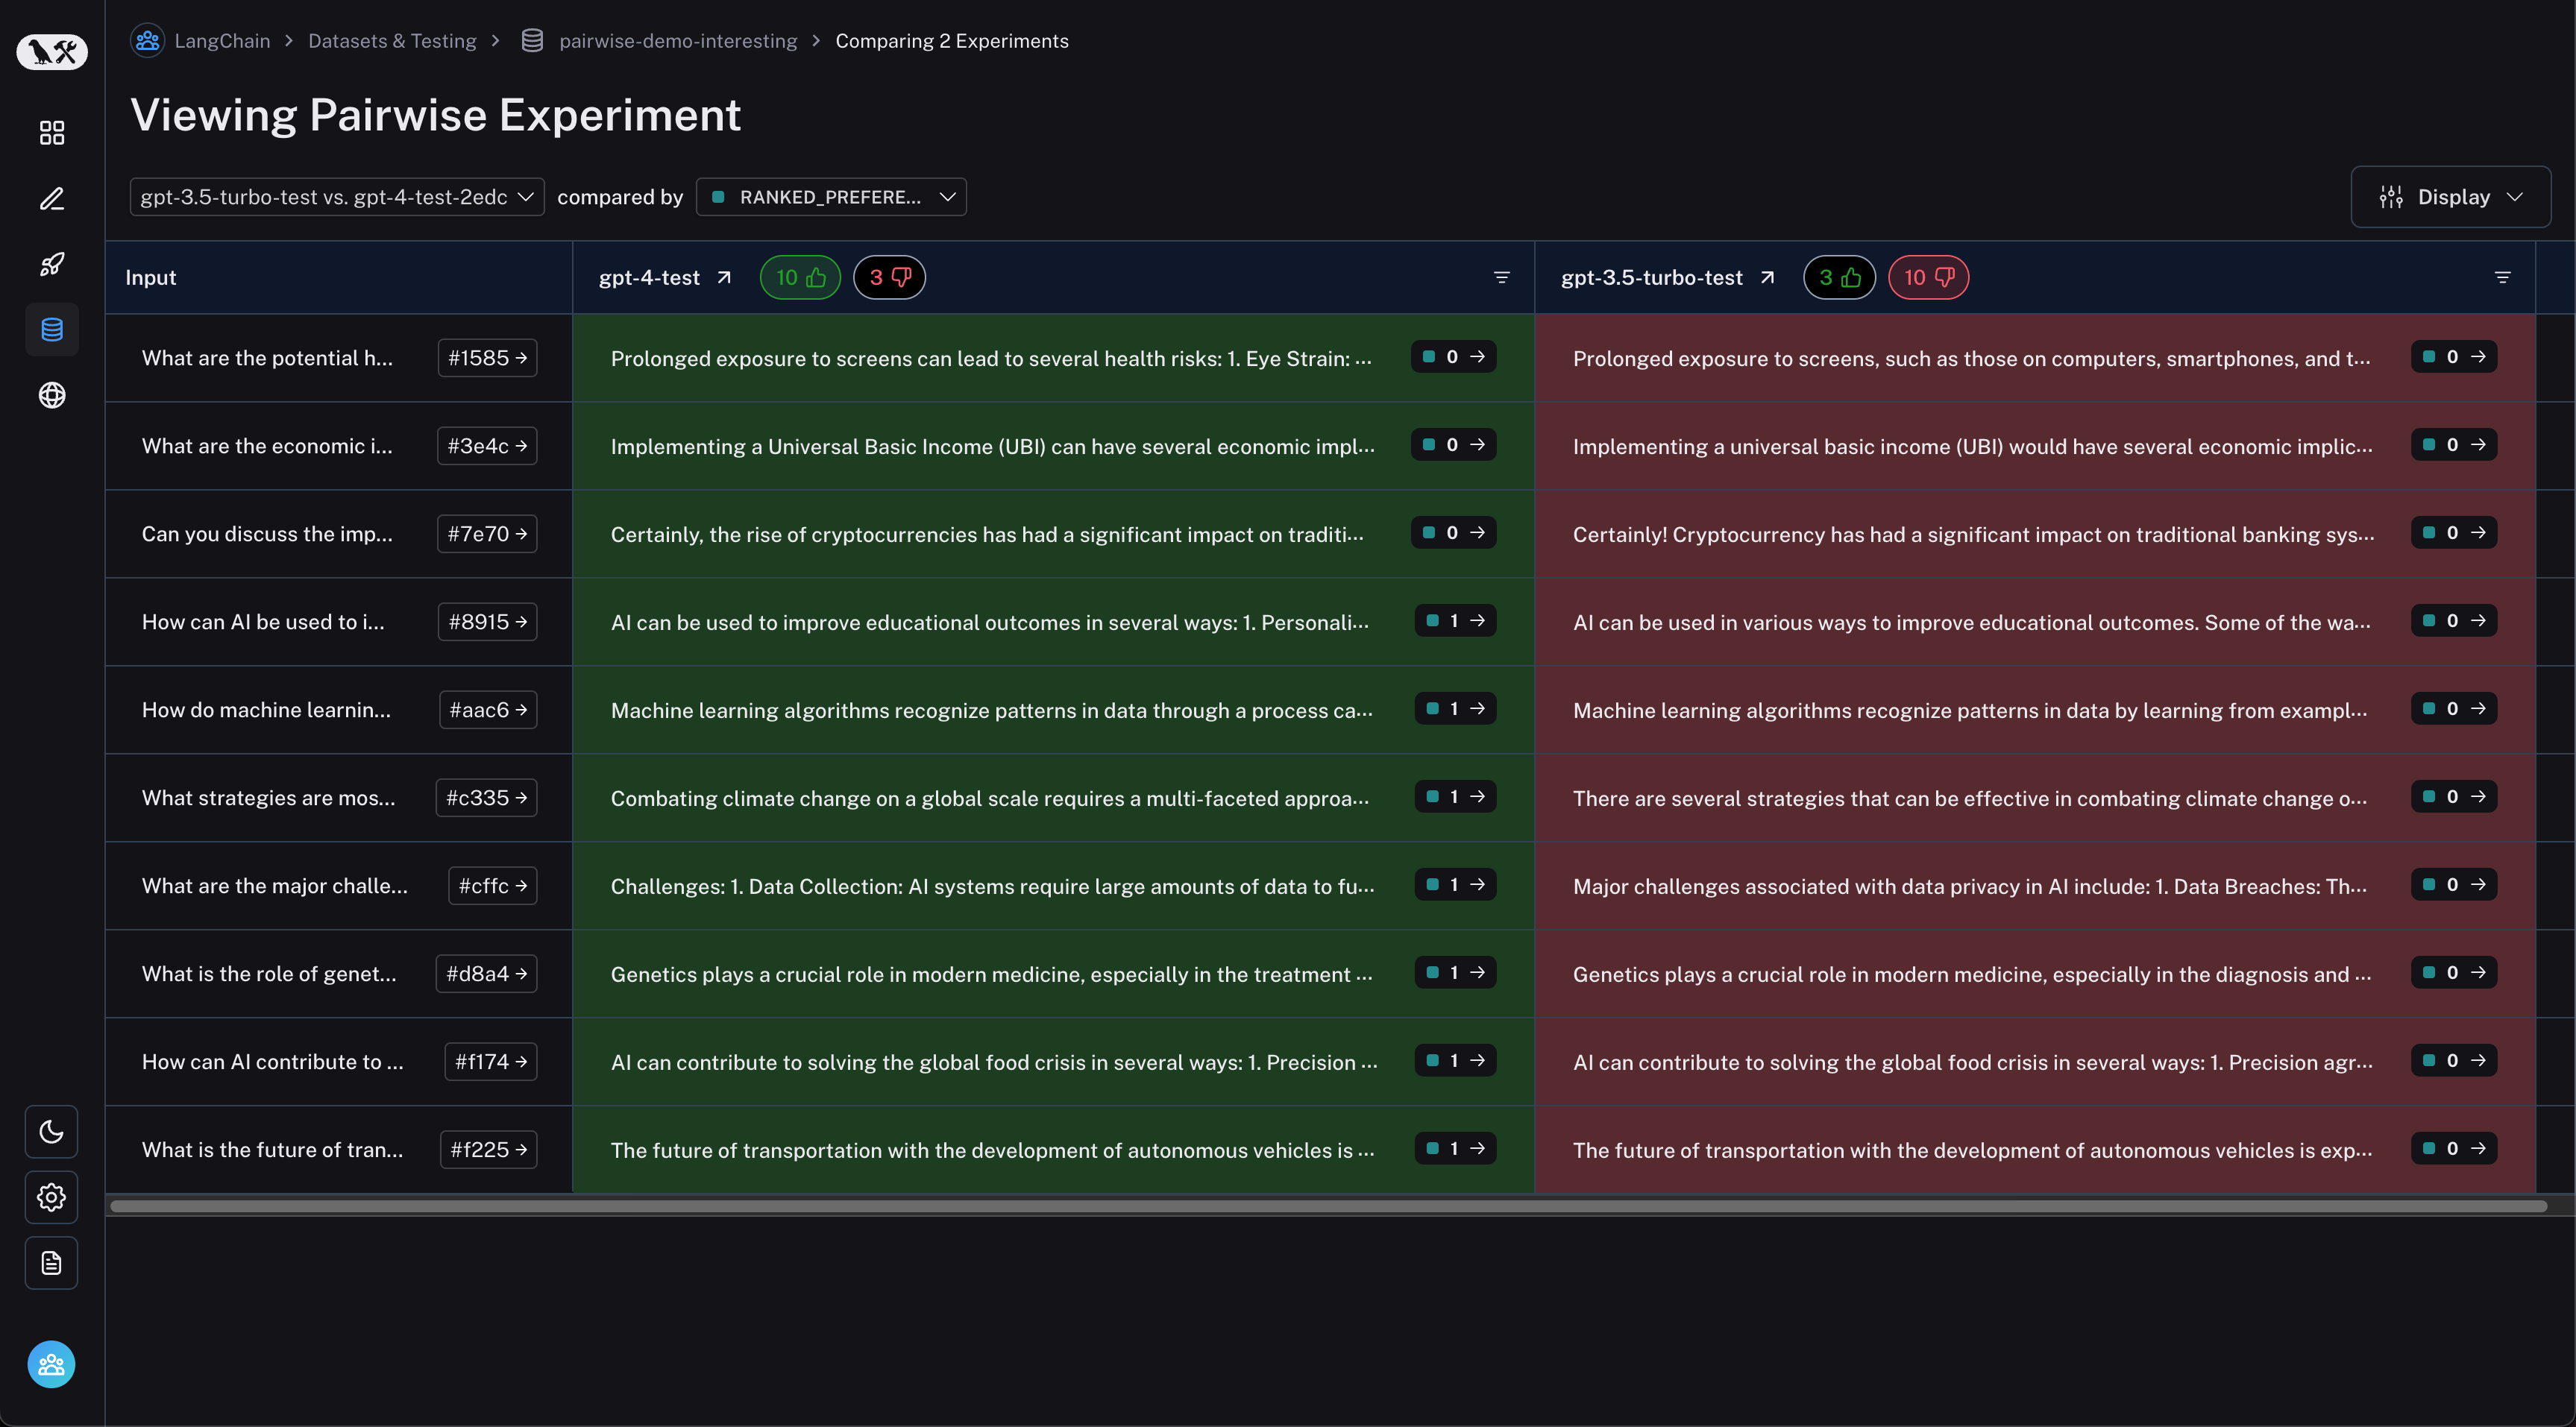
LangSmith 支持以比较方式评估现有实验。你可以同时对多个实验的输出进行相互评分,而不是一次只评估一个输出。在本指南中,你将使用 evaluate() 和两个现有实验来定义评估器并运行成对评估。最后,你将使用 LangSmith UI 查看成对实验。
前置条件
INFO
你也可以使用 evaluate_comparative() 处理两个以上的现有实验。
evaluate() 比较参数
最简单的情况下,evaluate / aevaluate 函数接受以下参数:
| 参数 | 描述 |
|---|---|
target | 你希望相互评估的两个现有实验的列表。这些可以是 uuid 或实验名称。 |
evaluators | 你希望附加到此评估的成对评估器列表。有关如何定义它们,请参阅下文。 |
除此之外,你还可以传入以下可选参数:
| 参数 | 描述 |
|---|---|
randomize_order / randomizeOrder | 可选布尔值,指示是否在每次评估时随机化输出顺序。这是减少提示中位置偏差的一种策略:通常,LLM 会基于顺序偏向其中一个响应。这主要应通过提示工程解决,但这是另一种可选缓解措施。默认为 False。 |
experiment_prefix / experimentPrefix | 要附加到成对实验名称开头的前缀。默认为 None。 |
description | 成对实验的描述。默认为 None。 |
max_concurrency / maxConcurrency | 要运行的最大并发评估数。默认为 5。 |
client | 要使用的 LangSmith 客户端。默认为 None。 |
metadata | 要附加到成对实验的元数据。默认为 None。 |
load_nested / loadNested | 是否加载实验的所有子运行。当为 False 时,仅根追踪会传递给评估器。默认为 False。 |
定义成对评估器
成对评估器只是具有预期签名的函数。
评估器参数
自定义评估器函数必须使用特定的参数名称。它们可以采用以下参数的任意子集:
inputs: dict:与数据集中单个示例对应的输入字典。outputs: list[dict]:每个实验在给定输入上生成的 dict 输出的两项列表。reference_outputs/referenceOutputs: dict:与该示例关联的参考输出字典(如果可用)。runs: list[Run]:两个实验在给定示例上生成的完整 Run 对象的两项列表。如果你需要访问每个运行的中间步骤或元数据,请使用此项。example: Example:完整数据集 Example,包括示例输入、输出(如果可用)和元数据(如果可用)。
对于大多数用例,你只需要 inputs、outputs 和 reference_outputs / referenceOutputs。仅当你需要应用实际输入和输出之外的额外追踪或示例元数据时,runs 和 example 才有用。
评估器输出
自定义评估器应返回以下类型之一:
Python 与 JS/TS
dict:包含以下键的字典:key,表示将记录的反馈键scores,运行 ID 到该运行分数的映射。comment,一个字符串。最常用于模型推理。
目前仅支持 Python
list[int | float | bool]:包含两项分数的列表。假定该列表的顺序与runs/outputs评估器参数相同。评估器函数名称用作反馈键。
请注意,你应选择一个与运行上的标准反馈不同的反馈键。我们建议为成对反馈键添加 pairwise_ 或 ranked_ 前缀。
运行成对评估
以下示例使用一个提示,要求 LLM 判断两个 AI 助手响应中哪个更好。它使用结构化输出解析 AI 的响应:0、1 或 2。
INFO
在下面的 Python 示例中,我们拉取此结构化提示,来源是 LangChain Hub,并将其与 LangChain 聊天模型包装器一起使用。
LangChain 的使用完全是可选的。 为了说明这一点,TypeScript 示例直接使用 OpenAI SDK。
- Python:需要
langsmith>=0.2.0 - TypeScript:需要
langsmith>=0.2.9
python
from langchain_classic import hub
from langchain.chat_models import init_chat_model
from langsmith import evaluate

# See the prompt: https://smith.langchain.com/hub/langchain-ai/pairwise-evaluation-2
prompt = hub.pull("langchain-ai/pairwise-evaluation-2")
model = init_chat_model("gpt-5.5")
chain = prompt | model

def ranked_preference(inputs: dict, outputs: list[dict]) -> list:
    # Assumes example inputs have a 'question' key and experiment
    # outputs have an 'answer' key.
    response = chain.invoke({
        "question": inputs["question"],
        "answer_a": outputs[0].get("answer", "N/A"),
        "answer_b": outputs[1].get("answer", "N/A"),
    })
    if response["Preference"] == 1:
        scores = [1, 0]
    elif response["Preference"] == 2:
        scores = [0, 1]
    else:
        scores = [0, 0]
    return scores

evaluate(
    ("experiment-1", "experiment-2"),  # Replace with the names/IDs of your experiments
    evaluators=[ranked_preference],
    randomize_order=True,
    max_concurrency=4,
)typescript
import { evaluate} from "langsmith/evaluation";
import { Run } from "langsmith/schemas";
import { wrapOpenAI } from "langsmith/wrappers";
import OpenAI from "openai";
import { z } from "zod";

const openai = wrapOpenAI(new OpenAI());

async function rankedPreference({
  inputs,
  runs,
}: {
  inputs: Record<string, any>;
  runs: Run[];
}) {
  const scores: Record<string, number> = {};
  const [runA, runB] = runs;
  if (!runA || !runB) throw new Error("Expected at least two runs");

  const payload = {
    question: inputs.question,
    answer_a: runA?.outputs?.output ?? "N/A",
    answer_b: runB?.outputs?.output ?? "N/A",
  };

  const output = await openai.chat.completions.create({
    model: "gpt-4-turbo",
    messages: [
      {
        role: "system",
        content: [
          "Please act as an impartial judge and evaluate the quality of the responses provided by two AI assistants to the user question displayed below.",
          "You should choose the assistant that follows the user's instructions and answers the user's question better.",
          "Your evaluation should consider factors such as the helpfulness, relevance, accuracy, depth, creativity, and level of detail of their responses.",
          "Begin your evaluation by comparing the two responses and provide a short explanation.",
          "Avoid any position biases and ensure that the order in which the responses were presented does not influence your decision.",
          "Do not allow the length of the responses to influence your evaluation. Do not favor certain names of the assistants. Be as objective as possible.",
        ].join(" "),
      },
      {
        role: "user",
        content: [
          `[User Question] ${payload.question}`,
          `[The Start of Assistant A's Answer] ${payload.answer_a} [The End of Assistant A's Answer]`,
          `The Start of Assistant B's Answer] ${payload.answer_b} [The End of Assistant B's Answer]`,
        ].join("\n\n"),
      },
    ],
    tool_choice: {
      type: "function",
      function: { name: "Score" },
    },
    tools: [
      {
        type: "function",
        function: {
          name: "Score",
          description: [
            `After providing your explanation, output your final verdict by strictly following this format:`,
            `Output "1" if Assistant A answer is better based upon the factors above.`,
            `Output "2" if Assistant B answer is better based upon the factors above.`,
            `Output "0" if it is a tie.`,
          ].join(" "),
          parameters: {
            type: "object",
            properties: {
              Preference: {
                type: "integer",
                description: "Which assistant answer is preferred?",
              },
            },
          },
        },
      },
    ],
  });

  const { Preference } = z
    .object({ Preference: z.number() })
    .parse(
      JSON.parse(output.choices[0].message.tool_calls[0].function.arguments)
    );

  if (Preference === 1) {
    scores[runA.id] = 1;
    scores[runB.id] = 0;
  } else if (Preference === 2) {
    scores[runA.id] = 0;
    scores[runB.id] = 1;
  } else {
    scores[runA.id] = 0;
    scores[runB.id] = 0;
  }

  return { key: "ranked_preference", scores };
}

await evaluate(["earnest-name-40", "reflecting-pump-91"], {
  evaluators: [rankedPreference],
});查看成对实验
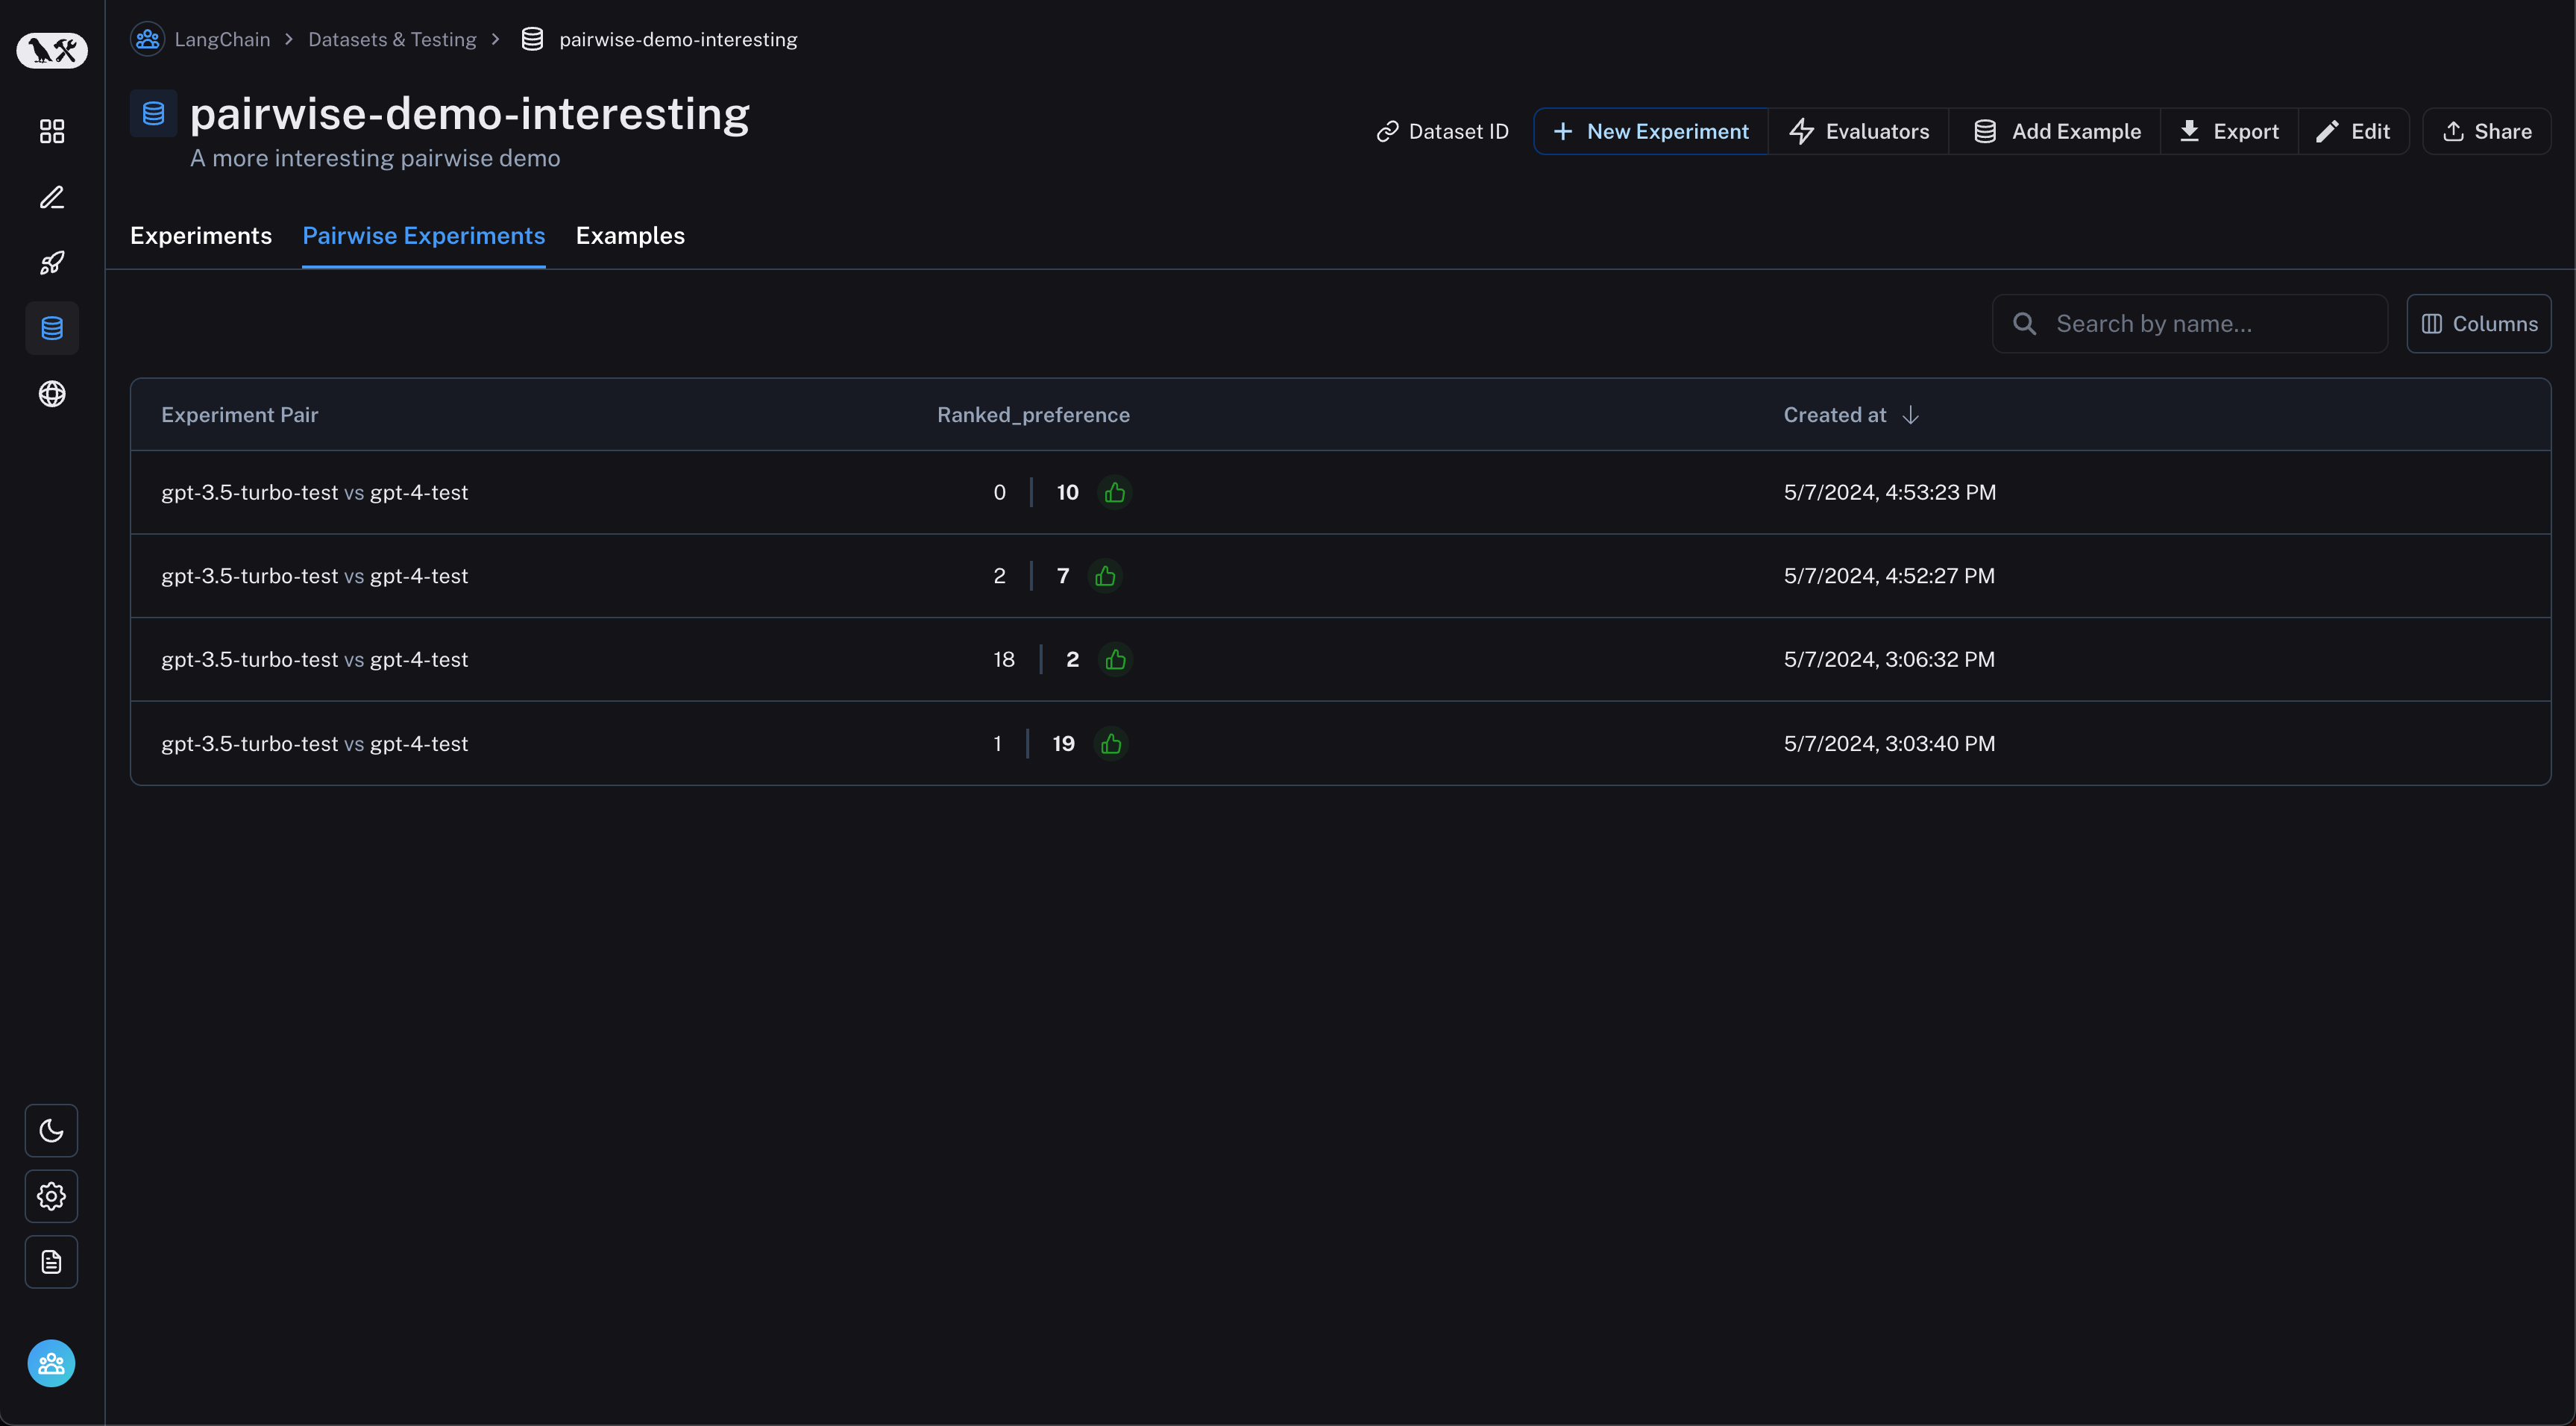
从数据集页面导航到 "Pairwise Experiments" 选项卡:
点击你想检查的成对实验,你将进入比较视图:
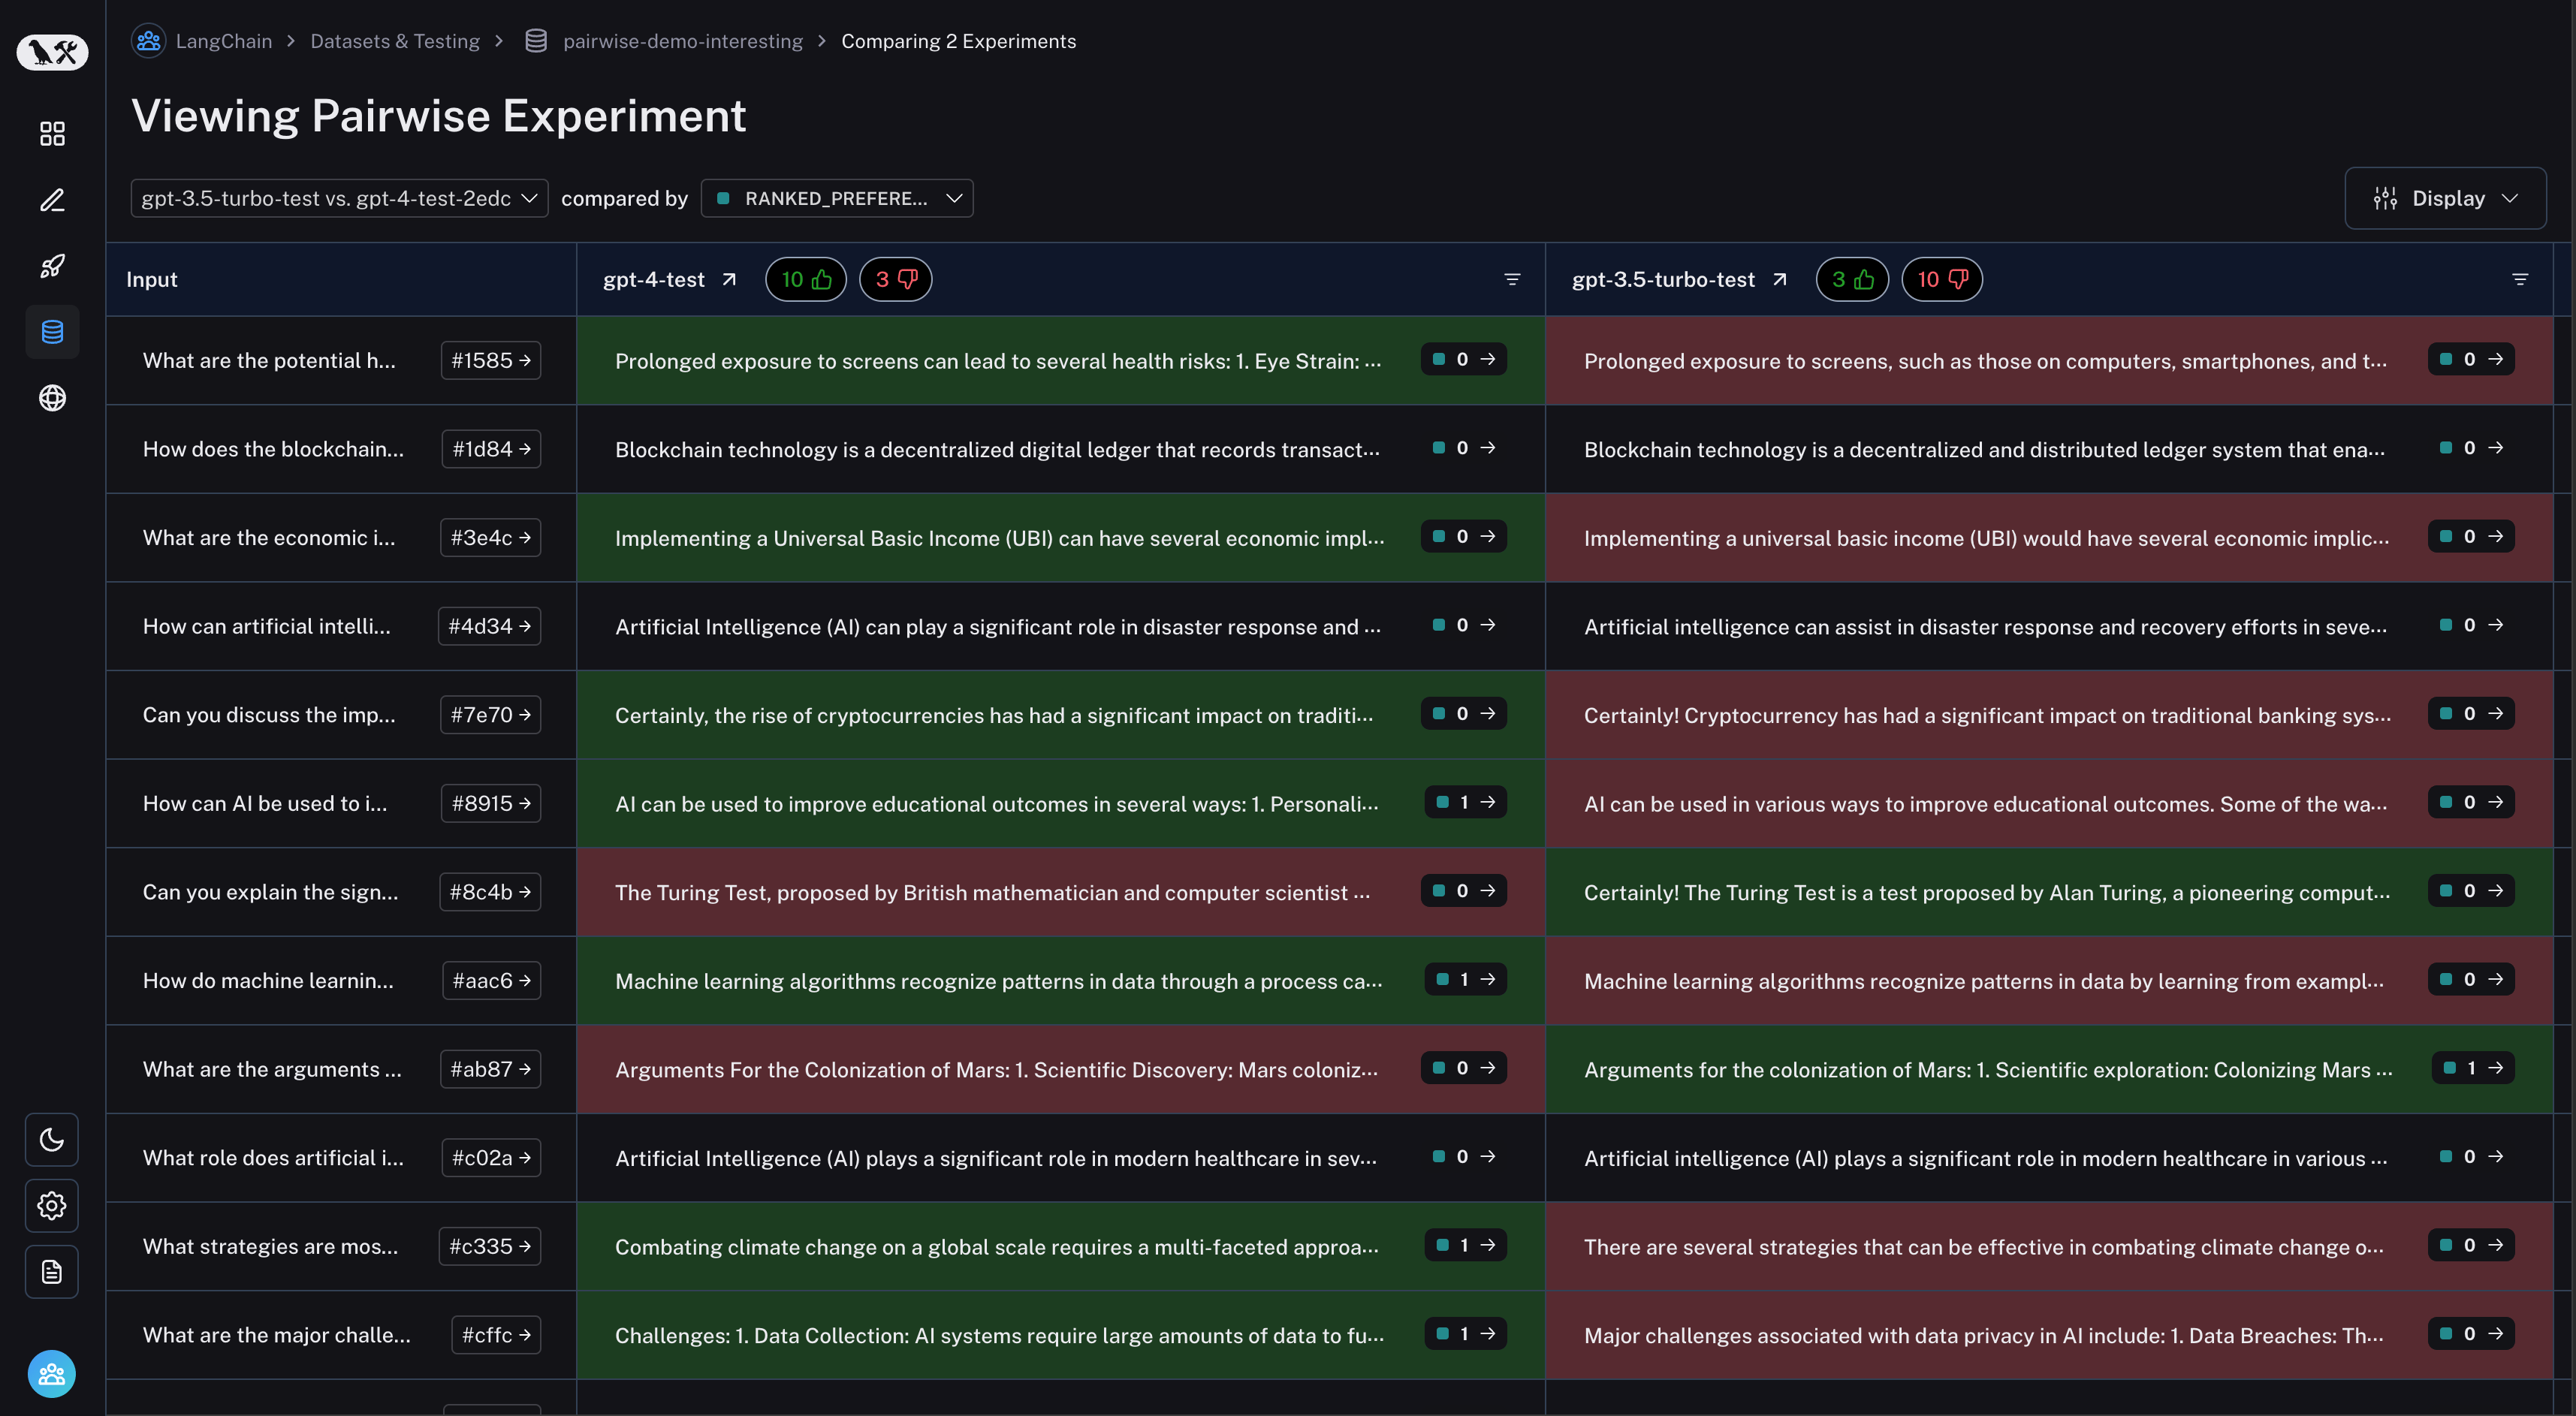
你可以点击表头中的点赞/点踩按钮,筛选出第一个实验更好的运行,或反之: