
主题
使用 openevals 包运行评估
使用开源 openevals 和 agentevals 包与 LangSmith 运行评估。
LangSmith 与开源 openevals 包集成,提供一套评估工具和提示词,可作为评估的起点。
NOTE
本操作指南将演示如何设置并运行一种评估器(LLM-as-a-judge)。有关评估工具和提示词的完整列表及用法示例,请参阅 openevals 和 agentevals 仓库。
设置
你需要安装 openevals 包才能使用 LLM-as-a-judge 评估器。
bash
pip install -U openevalsbash
yarn add openevals @langchain/core你还需要将 OpenAI API key 设置为环境变量,不过也可以选择其他提供商:
bash
export OPENAI_API_KEY="your_openai_api_key"我们还将使用 LangSmith 的 pytest 集成(Python)和 Vitest/Jest(TypeScript)来运行评估。openevals 也可与 evaluate 方法无缝集成。有关设置说明,请参阅相应指南。
运行评估器
总体流程很简单:从 openevals 导入评估器或工厂函数,然后在测试文件中使用输入、输出和参考输出运行它。LangSmith 会自动将评估器的结果记录为反馈。
请注意,并非所有评估器都需要每个参数(例如,精确匹配评估器只需要输出和参考输出)。此外,如果你的 LLM-as-a-judge 提示词需要额外变量,以 kwargs 形式传入会将它们格式化到提示词中。
按如下方式设置测试文件:
python
import pytest
from langsmith import testing as t
from openevals.llm import create_llm_as_judge
from openevals.prompts import CORRECTNESS_PROMPT

correctness_evaluator = create_llm_as_judge(
    prompt=CORRECTNESS_PROMPT,
    feedback_key="correctness",
    model="openai:o3-mini",
)

# Mock standin for your application
def my_llm_app(inputs: dict) -> str:
    return "Doodads have increased in price by 10% in the past year."

@pytest.mark.langsmith
def test_correctness():
    inputs = "How much has the price of doodads changed in the past year?"
    reference_outputs = "The price of doodads has decreased by 50% in the past year."
    outputs = my_llm_app(inputs)

    t.log_inputs({"question": inputs})
    t.log_outputs({"answer": outputs})
    t.log_reference_outputs({"answer": reference_outputs})

    correctness_evaluator(
        inputs=inputs,
        outputs=outputs,
        reference_outputs=reference_outputs
)typescript
import * as ls from "langsmith/vitest";
// import * as ls from "langsmith/jest";
import { createLLMAsJudge, CORRECTNESS_PROMPT } from "openevals";

const correctnessEvaluator = createLLMAsJudge({
    prompt: CORRECTNESS_PROMPT,
    feedbackKey: "correctness",
    model: "openai:o3-mini",
});

// Mock standin for your application
const myLLMApp = async (_inputs: Record<string, unknown>) => {
    return "Doodads have increased in price by 10% in the past year.";
};

ls.describe("Correctness", () => {
    ls.test("incorrect answer", {
        inputs: {
            question: "How much has the price of doodads changed in the past year?"
        },
        referenceOutputs: {
            answer: "The price of doodads has decreased by 50% in the past year."
        }
    }, async ({ inputs, referenceOutputs }) => {
        const outputs = await myLLMApp(inputs);
        ls.logOutputs({ answer: outputs });
        await correctnessEvaluator({
            inputs,
            outputs,
            referenceOutputs,
        });
    });
});feedback_key/feedbackKey 参数将用作实验中反馈的名称。
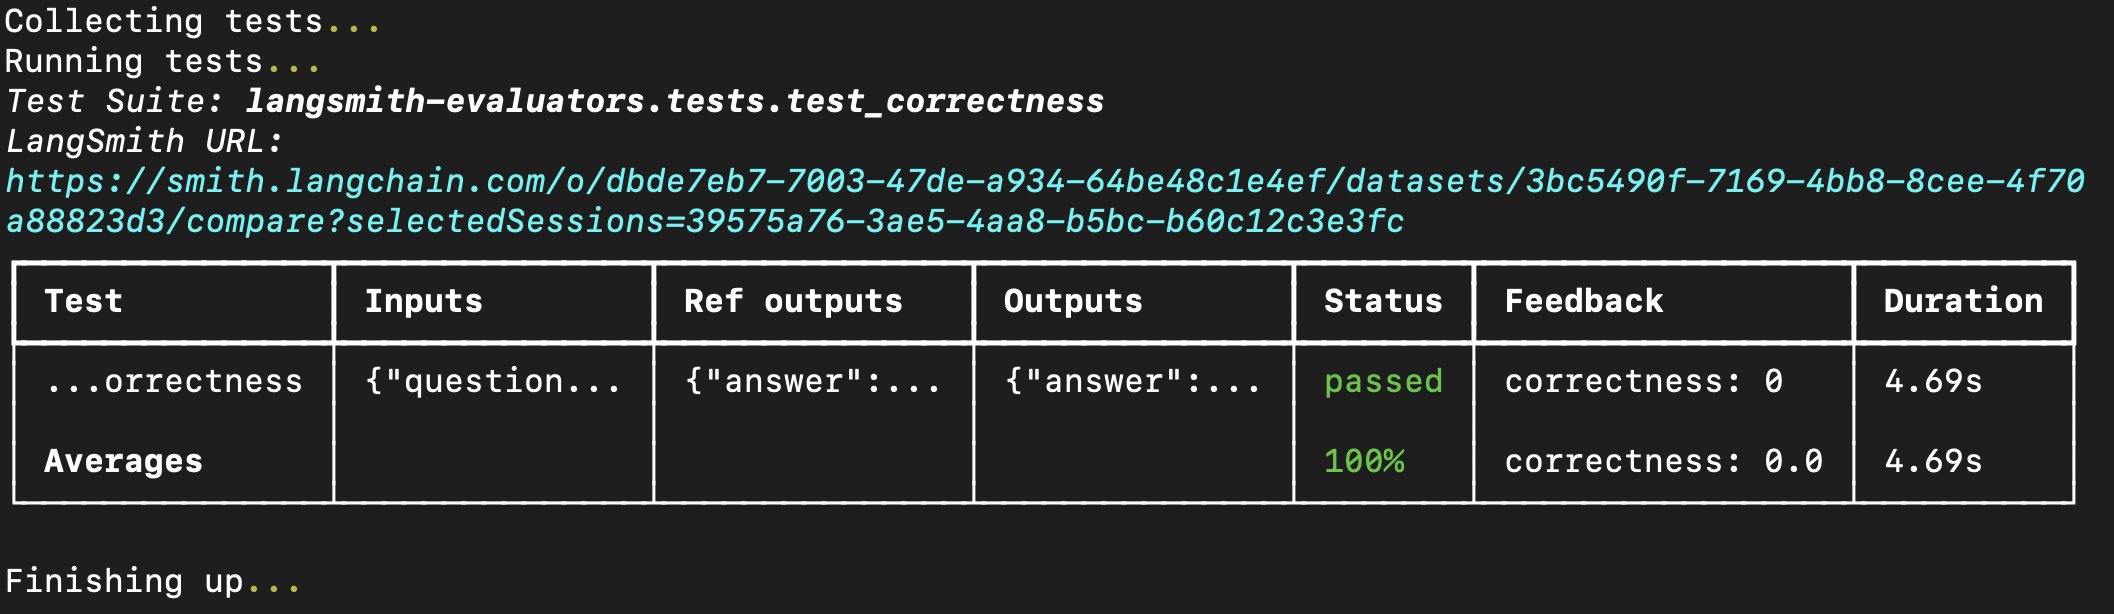
在终端中运行评估将产生类似以下内容的结果:
如果你已在 LangSmith 中创建数据集,也可以直接将评估器传入 evaluate 方法。如果使用 Python,这需要 langsmith>=0.3.11:
python
from langsmith import Client
from openevals.llm import create_llm_as_judge
from openevals.prompts import CONCISENESS_PROMPT

client = Client()
conciseness_evaluator = create_llm_as_judge(
    prompt=CONCISENESS_PROMPT,
    feedback_key="conciseness",
    model="openai:o3-mini",
)

experiment_results = client.evaluate(
    # This is a dummy target function, replace with your actual LLM-based system
    lambda inputs: "What color is the sky?",
    data="Sample dataset",
    evaluators=[
        conciseness_evaluator
    ]
)typescript
import { evaluate } from "langsmith/evaluation";
import { createLLMAsJudge, CONCISENESS_PROMPT } from "openevals";

const concisenessEvaluator = createLLMAsJudge({
    prompt: CONCISENESS_PROMPT,
    feedbackKey: "conciseness",
    model: "openai:o3-mini",
});

await evaluate((inputs) => "What color is the sky?", {
    data: datasetName,
    evaluators: [concisenessEvaluator],
});有关可用评估工具和提示词的完整列表,请参阅 openevals 和 agentevals 仓库。