
主题
LM Format Enforcer 是一个用于强制语言模型输出指定格式(JSON Schema、正则等)的库。它不只是向 LLM“建议”期望的输出结构,而是能真正“强制”LLM 的输出遵循目标 schema。
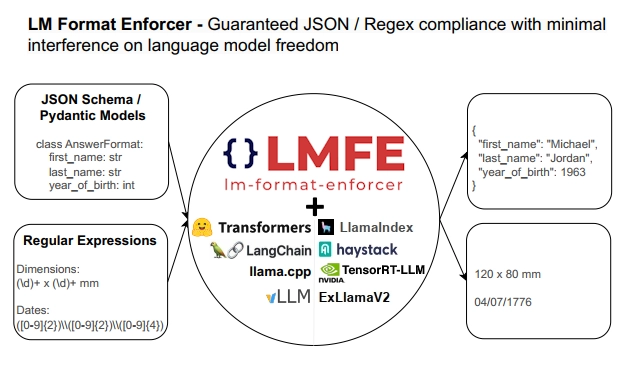
LM Format Enforcer 可与本地 LLM 一起工作(目前支持 LlamaCPP 与 HuggingfaceLLM 后端),并且只通过处理 LLM 的输出 logits 来起作用。这使它支持束搜索、批处理等进阶生成方式,不同于那些要修改生成循环本身的方案。更多细节见 LM Format Enforcer 页面中的对比表。
JSON Schema 输出
在 LlamaIndex 中,我们提供了与 LM Format Enforcer 的初步集成,让生成结构化输出(更具体说是 pydantic 对象)变得极其简单。
例如,我们想生成一张歌曲专辑,schema 如下:
class Song(BaseModel):
    title: str
    length_seconds: int

class Album(BaseModel):
    name: str
    artist: str
songs: List[Song]只需创建一个 LMFormatEnforcerPydanticProgram、指定我们想要的 pydantic 类 Album,再给出合适的提示词模板即可。
注:
LMFormatEnforcerPydanticProgram会自动把 pydantic 类的 json schema 填入提示词模板中可选的{json_schema}参数。这能帮助 LLM 更自然地生成正确的 JSON,减少格式强制器的干预强度,从而提升输出质量。
program = LMFormatEnforcerPydanticProgram(
    output_cls=Album,
    prompt_template_str="Generate an example album, with an artist and a list of songs. Using the movie {movie_name} as inspiration. You must answer according to the following schema: \n{json_schema}\n",
    llm=LlamaCPP(),
    verbose=True,
)现在我们可以带着额外的用户输入调用这个程序。这里来点惊悚风——做一张以《闪灵》为灵感的专辑。
output = program(movie_name="The Shining")我们得到了这个 pydantic 对象:
Album(
    name="The Shining: A Musical Journey Through the Haunted Halls of the Overlook Hotel",
    artist="The Shining Choir",
    songs=[
        Song(title="Redrum", length_seconds=300),
        Song(
            title="All Work and No Play Makes Jack a Dull Boy",
            length_seconds=240,
        ),
        Song(title="Heeeeere's Johnny!", length_seconds=180),
    ],
)更多细节可以玩玩这个 notebook。
正则表达式输出
LM Format Enforcer 也支持正则输出。由于 LlamaIndex 中还没有针对正则表达式的现成抽象,我们会在向 LLM 注入 LM Format Generator 之后直接用它。
regex = r'"Hello, my name is (?P<name>[a-zA-Z]*)\. I was born in (?P<hometown>[a-zA-Z]*). Nice to meet you!"'
prompt = "Here is a way to present myself, if my name was John and I born in Boston: "

llm = LlamaCPP()
regex_parser = lmformatenforcer.RegexParser(regex)
lm_format_enforcer_fn = build_lm_format_enforcer_function(llm, regex_parser)
with activate_lm_format_enforcer(llm, lm_format_enforcer_fn):
output = llm.complete(prompt)这会让 LLM 按我们指定的正则格式生成输出。我们还能解析输出以取得命名分组:
print(output)
# "Hello, my name is John. I was born in Boston, Nice to meet you!"
print(re.match(regex, output.text).groupdict())
# {'name': 'John', 'hometown': 'Boston'}更多细节见这个 notebook。