主题
在本 notebook 中,我们展示如何使用 google-genai Python SDK 与 LlamaIndex 交互,以使用 Google GenAI 模型。
如果你在 Colab 中打开这个 Notebook,需要安装 LlamaIndex 🦙 和 google-genai Python SDK。
%pip install llama-index-llms-google-genai llama-index基本用法
你需要从 Google AI Studio 获取 API 密钥。获取后,你可以将其显式传给模型,或使用 GOOGLE_API_KEY 环境变量。
import os

os.environ["GOOGLE_API_KEY"] = "..."基本用法
你可以使用提示词调用 complete:
from llama_index.llms.google_genai import GoogleGenAI

llm = GoogleGenAI(
    model="gemini-2.5-flash",
    # api_key="some key",  # uses GOOGLE_API_KEY env var by default
)

resp = llm.complete("Who is Paul Graham?")
print(resp)Paul Graham is a prominent figure in the tech world, best known for his work as a programmer, essayist, and venture capitalist. Here's a breakdown of his key contributions:
* **Programmer and Hacker:** He's a skilled programmer, particularly in Lisp. He co-founded Viaweb, which was one of the first software-as-a-service (SaaS) companies, providing tools for building online stores. Yahoo acquired Viaweb in 1998, and it became Yahoo! Store.
* **Essayist:** Graham is a prolific and influential essayist. His essays cover a wide range of topics, including startups, programming, design, and societal trends. His writing style is known for being clear, concise, and thought-provoking. Many of his essays are considered essential reading for entrepreneurs and those interested in technology.
* **Venture Capitalist and Founder of Y Combinator:** Perhaps his most significant contribution is co-founding Y Combinator (YC) in 2005. YC is a highly successful startup accelerator that provides seed funding, mentorship, and networking opportunities to early-stage startups. YC has funded many well-known companies, including Airbnb, Dropbox, Reddit, Stripe, and many others. Graham stepped down from his day-to-day role at YC in 2014 but remains involved.
In summary, Paul Graham is a multifaceted individual who has made significant contributions to the tech industry as a programmer, essayist, and venture capitalist. He is particularly known for his role in founding and shaping Y Combinator, one of the world's leading startup accelerators.你也可以使用聊天消息列表调用 chat:
from llama_index.core.llms import ChatMessage
from llama_index.llms.google_genai import GoogleGenAI

messages = [
    ChatMessage(
        role="system", content="You are a pirate with a colorful personality"
    ),
    ChatMessage(role="user", content="Tell me a story"),
]
llm = GoogleGenAI(model="gemini-2.5-flash")
resp = llm.chat(messages)

print(resp)assistant: Ahoy there, matey! Gather 'round, ye landlubbers, and listen to a tale that'll shiver yer timbers and curl yer toes! This be the story of One-Eyed Jack's Lost Parrot and the Great Mango Mayhem!
Now, One-Eyed Jack, bless his barnacle-encrusted heart, was a fearsome pirate, alright. He could bellow louder than a hurricane, swing a cutlass like a dervish, and drink rum like a fish. But he had a soft spot, see? A soft spot for his parrot, Polly. Polly wasn't just any parrot, mind ye. She could mimic the captain's every cuss word, predict the weather by the way she ruffled her feathers, and had a particular fondness for shiny trinkets.
One day, we were anchored off the coast of Mango Island, a lush paradise overflowing with the juiciest, sweetest mangoes ye ever did see. Jack, bless his greedy soul, decided we needed a cargo hold full of 'em. "For scurvy prevention!" he declared, winking with his good eye. More like for his own personal mango-eating contest, if ye ask me.
We stormed ashore, cutlasses gleaming, ready to plunder the mango groves. But Polly, the little feathered devil, decided she'd had enough of the ship. She squawked, "Shiny! Shiny!" and took off like a green streak towards the heart of the island.
Jack went ballistic! "Polly! Polly, ye feathered fiend! Get back here!" He chased after her, bellowing like a lovesick walrus. The rest of us, well, we were left to pick mangoes and try not to laugh ourselves silly.
Now, Mango Island wasn't just full of mangoes. It was also home to a tribe of mischievous monkeys, the Mango Marauders, they were called. They were notorious for their love of pranks and their uncanny ability to steal anything that wasn't nailed down.
Turns out, Polly had landed right in the middle of their territory. And those monkeys, they took one look at her shiny feathers and decided she was the perfect addition to their collection of stolen treasures. They snatched her up, chattering and screeching, and whisked her away to their hidden lair, a giant mango tree hollowed out by time.
Jack, bless his stubborn heart, followed the sound of Polly's squawks. He hacked through vines, dodged falling mangoes, and even wrestled a particularly grumpy iguana, all in pursuit of his feathered friend.
Finally, he reached the mango tree. He peered inside and saw Polly, surrounded by a horde of monkeys, all admiring her shiny feathers. And Polly? She was having the time of her life, mimicking the monkeys' chattering and stealing their mangoes!
Jack, instead of getting angry, started to laugh. A hearty, booming laugh that shook the very foundations of the tree. The monkeys, startled, dropped their mangoes and stared at him.
Then, Polly, seeing her captain, squawked, "Rum! Rum for everyone!"
And that, me hearties, is how One-Eyed Jack ended up sharing a barrel of rum with a tribe of mango-loving monkeys. We spent the rest of the day feasting on mangoes, drinking rum, and listening to Polly mimic the monkeys' antics. We even managed to fill the cargo hold with mangoes, though I suspect a good portion of them were already half-eaten by the monkeys.
So, the moral of the story, me lads? Even the fiercest pirate has a soft spot, and sometimes, the best treasures are the ones you least expect. And always, ALWAYS, keep an eye on yer parrot! Now, who's for another round of grog?流式支持
每个方法都支持通过 stream_ 前缀进行流式调用。
from llama_index.llms.google_genai import GoogleGenAI

llm = GoogleGenAI(model="gemini-2.5-flash")

resp = llm.stream_complete("Who is Paul Graham?")
for r in resp:
print(r.delta, end="")Paul Graham is a prominent figure in the tech world, best known for his work as a computer programmer, essayist, venture capitalist, and co-founder of the startup accelerator Y Combinator. Here's a breakdown of his key accomplishments and contributions:
* **Computer Programmer and Author:** Graham holds a Ph.D. in computer science from Harvard University. He is known for his work on Lisp, a programming language, and for developing Viaweb, one of the first software-as-a-service (SaaS) companies, which was later acquired by Yahoo! and became Yahoo! Store. He's also the author of several influential books on programming and entrepreneurship, including "On Lisp," "ANSI Common Lisp," "Hackers & Painters," and "A Plan for Spam."
* **Essayist:** Graham is a prolific essayist, writing on a wide range of topics including technology, startups, art, philosophy, and society. His essays are known for their insightful observations, clear writing style, and often contrarian viewpoints. They are widely read and discussed in the tech community. You can find his essays on his website, paulgraham.com.
* **Venture Capitalist and Y Combinator:** Graham co-founded Y Combinator (YC) in 2005 with Jessica Livingston, Robert Morris, and Trevor Blackwell. YC is a highly successful startup accelerator that provides seed funding, mentorship, and networking opportunities to early-stage startups. YC has funded many well-known companies, including Airbnb, Dropbox, Reddit, Stripe, and many others. While he stepped down from day-to-day operations at YC in 2014, his influence on the organization and the startup ecosystem remains significant.
In summary, Paul Graham is a multifaceted individual who has made significant contributions to computer science, entrepreneurship, and the broader tech culture. He is highly regarded for his technical expertise, insightful writing, and his role in shaping the modern startup landscape.from llama_index.core.llms import ChatMessage
messages = [
ChatMessage(role="user", content="Who is Paul Graham?"),
]
resp = llm.stream_chat(messages)
for r in resp:
print(r.delta, end="")Paul Graham is a prominent figure in the tech world, best known for his work as a programmer, essayist, and venture capitalist. Here's a breakdown of his key contributions:
* **Programmer and Hacker:** He is a skilled programmer, particularly in Lisp. He co-founded Viaweb, one of the first software-as-a-service (SaaS) companies, which was later acquired by Yahoo! and became Yahoo! Store.
* **Essayist:** Graham is a prolific and influential essayist, writing on topics ranging from programming and startups to art, philosophy, and social commentary. His essays are known for their clarity, insight, and often contrarian viewpoints. They are widely read and discussed in the tech community.
* **Venture Capitalist:** He co-founded Y Combinator (YC) in 2005, a highly successful startup accelerator. YC has funded and mentored numerous well-known companies, including Airbnb, Dropbox, Reddit, Stripe, and many others. Graham's approach to early-stage investing and startup mentorship has had a significant impact on the startup ecosystem.
In summary, Paul Graham is a multifaceted individual who has made significant contributions to the tech industry as a programmer, essayist, and venture capitalist. He is particularly influential in the startup world through his work with Y Combinator.异步用法
每个同步方法都有对应的异步版本。
from llama_index.llms.google_genai import GoogleGenAI

llm = GoogleGenAI(model="gemini-2.5-flash")

resp = await llm.astream_complete("Who is Paul Graham?")
async for r in resp:
print(r.delta, end="")Paul Graham is a prominent figure in the tech world, best known for his work as a programmer, essayist, and venture capitalist. Here's a breakdown of his key accomplishments and roles:
* **Programmer and Hacker:** He holds a Ph.D. in computer science from Harvard and is known for his work on Lisp, a programming language. He co-founded Viaweb, one of the first software-as-a-service (SaaS) companies, which was later acquired by Yahoo! and became Yahoo! Store.
* **Essayist:** Graham is a prolific and influential essayist, writing on topics ranging from programming and startups to art, philosophy, and social commentary. His essays are widely read and discussed in the tech community.
* **Venture Capitalist:** He co-founded Y Combinator (YC) in 2005, a highly successful startup accelerator that has funded companies like Airbnb, Dropbox, Reddit, Stripe, and many others. YC provides seed funding, mentorship, and networking opportunities to early-stage startups. While he stepped back from day-to-day operations at YC in 2014, he remains a significant figure in the venture capital world.
In summary, Paul Graham is a multifaceted individual who has made significant contributions to the fields of computer science, entrepreneurship, and venture capital. He is highly regarded for his insightful writing and his role in shaping the modern startup ecosystem.messages = [
ChatMessage(role="user", content="Who is Paul Graham?"),
]
resp = await llm.achat(messages)
print(resp)assistant: Paul Graham is a prominent figure in the tech world, best known for his work as a programmer, essayist, and venture capitalist. Here's a breakdown of his key accomplishments and contributions:
* **Programmer and Hacker:** He is a skilled programmer, particularly in Lisp. He co-founded Viaweb, one of the first software-as-a-service (SaaS) companies, which was later acquired by Yahoo! and became Yahoo! Store.
* **Essayist:** Graham is a prolific and influential essayist, writing on topics ranging from programming and startups to art, design, and societal trends. His essays are known for their insightful observations, contrarian viewpoints, and clear writing style. Many of his essays are available on his website, paulgraham.com.
* **Venture Capitalist and Y Combinator:** He co-founded Y Combinator (YC) in 2005, a highly successful startup accelerator that has funded numerous well-known companies, including Airbnb, Dropbox, Reddit, Stripe, and many others. YC provides seed funding, mentorship, and networking opportunities to early-stage startups. Graham played a key role in shaping YC's philosophy and approach to investing.
* **Author:** He has written several books, including "On Lisp" and "Hackers & Painters: Big Ideas from the Age of Enlightenment."
In summary, Paul Graham is a multifaceted individual who has made significant contributions to the tech industry as a programmer, essayist, and venture capitalist. He is particularly influential in the startup world through his work with Y Combinator.Vertex AI 支持
通过提供 region 和 project_id 参数(可以通过环境变量或直接传入),你可以启用通过 Vertex AI 的使用。
# Set environment variables
!export GOOGLE_GENAI_USE_VERTEXAI=true
!export GOOGLE_CLOUD_PROJECT='your-project-id'
!export GOOGLE_CLOUD_LOCATION='us-central1'from llama_index.llms.google_genai import GoogleGenAI
# or set the parameters directly
llm = GoogleGenAI(
model="gemini-2.5-flash",
vertexai_config={"project": "your-project-id", "location": "us-central1"},
# you should set the context window to the max input tokens for the model
context_window=200000,
max_tokens=512,
)Paul Graham is a prominent figure in the tech and startup world, best known for his roles as:
* **Co-founder of Y Combinator (YC):** This is arguably his most influential role. YC is a highly successful startup accelerator that has funded companies like Airbnb, Dropbox, Stripe, Reddit, and many others. Graham's approach to funding and mentoring startups has significantly shaped the startup ecosystem.
* **Essayist and Programmer:** Before YC, Graham was a programmer and essayist. He's known for his insightful and often contrarian essays on a wide range of topics, including programming, startups, design, and societal trends. His essays are widely read and discussed in the tech community.
* **Founder of Viaweb (later Yahoo! Store):** Graham founded Viaweb, one of the first application service providers, which allowed users to build and manage online stores. It was acquired by Yahoo! in 1998 and became Yahoo! Store.
In summary, Paul Graham is a highly influential figure in the startup world, known for his role in creating Y Combinator, his insightful essays, and his earlier success as a programmer and entrepreneur.缓存内容支持
Google GenAI 支持缓存内容,以便在多个请求中复用大型上下文时提升性能并节省成本。这对于 RAG 应用、文档分析以及具有一致上下文的多轮对话特别有用。
优势
- 更快的响应
- 节省成本,减少输入 token 使用量
- 一致的上下文,跨多个查询
- 非常适合大型文件的文档分析
创建缓存内容
首先,使用 Google GenAI SDK 创建缓存内容:
from google import genai
from google.genai.types import CreateCachedContentConfig, Content, Part
import time

client = genai.Client(api_key="your-api-key")

# For VertexAI
# client = genai.Client(
#     http_options=HttpOptions(api_version="v1"),
#     project="your-project-id",
#     location="us-central1",
#     vertexai="True"
# )选项 1:上传本地文件
# Upload and process local PDF files
pdf_file = client.files.upload(file="./your_document.pdf")
while pdf_file.state.name == "PROCESSING":
    print("Waiting for PDF to be processed.")
    time.sleep(2)
    pdf_file = client.files.get(name=pdf_file.name)

# Create cache with uploaded file
cache = client.caches.create(
    model="gemini-2.5-flash",
    config=CreateCachedContentConfig(
        display_name="Document Analysis Cache",
        system_instruction=(
            "You are an expert document analyzer. Answer questions "
            "based on the provided documents with accuracy and detail."
        ),
        contents=[pdf_file],  # Direct file reference
        ttl="3600s",  # Cache for 1 hour
    ),
)选项 2:具有内容结构的多个文件
# For multiple files or Cloud Storage files with VertexAI
contents = [
    Content(
        role="user",
        parts=[
            Part.from_uri(
                # file_uri=pdf_file.uri,    # you can use the uploaded file's URI too
                file_uri="gs://cloud-samples-data/generative-ai/pdf/2312.11805v3.pdf",
                mime_type="application/pdf",
            ),
            Part.from_uri(
                file_uri="gs://cloud-samples-data/generative-ai/pdf/2403.05530.pdf",
                mime_type="application/pdf",
            ),
        ],
    )
]

cache = client.caches.create(
    model="gemini-2.5-flash",
    config=CreateCachedContentConfig(
        display_name="Multi-Document Cache",
        system_instruction=(
            "You are an expert researcher. Analyze and compare "
            "information across the provided documents."
        ),
        contents=contents,
        ttl="3600s",
    ),
)

print(f"Cache created: {cache.name}")
print(f"Cached tokens: {cache.usage_metadata.total_token_count}")Cache created: projects/391.../locations/us-central1/cachedContents/267...
Cached tokens: 43102在 LlamaIndex 中使用缓存内容
创建缓存后,将其与 LlamaIndex 一起使用:
from llama_index.llms.google_genai import GoogleGenAI
from llama_index.core.llms import ChatMessage

llm = GoogleGenAI(
    model="gemini-2.5-flash",
    api_key="your-api-key",
    cached_content=cache.name,
)

# For VertexAI
# llm = GoogleGenAI(
#     model="gemini-2.5-flash",
#     vertexai_config={"project": "your-project-id", "location": "us-central1"},
#     cached_content=cache.name
# )

# Use the cached content
message = ChatMessage(
    role="user", content="Summarize the key findings from Chapter 4."
)
response = llm.chat([message])
print(response)assistant: Chapter 4, "The Abstraction: The Process," introduces the concept of a process as a running program, which is a fundamental abstraction provided by the operating system (OS). Here are the key findings:
1. **Process Definition:** A process is essentially a running program, characterized by its machine state, including memory (address space), registers (including the program counter and stack pointer), and I/O information.
2. **Process API:** The OS provides a process API that includes functions for creating processes (Create), destroying processes (Destroy), waiting for processes to complete (Wait), controlling processes (Miscellaneous Control), and obtaining status information (Status).
3. **Process Creation:** Creating a process involves loading code and static data into memory, allocating memory for the stack and heap, initializing the stack, and then starting the program at its entry point (main()).
4. **Process States:** A process can be in one of three states: Running (executing on a processor), Ready (ready to run but not currently running), or Blocked (waiting for an event, such as I/O completion).
5. **Data Structures:** The OS maintains data structures, such as a process list, to track the state of each process. These structures contain information like the register context (saved register values) and the process state.
In essence, Chapter 4 lays the groundwork for understanding how the OS manages and virtualizes the CPU by introducing the concept of a process and its associated attributes and states.在生成配置中使用缓存内容
用于请求级别的缓存控制:
import google.genai.types as types

# Specify cached content per request
config = types.GenerateContentConfig(
    cached_content=cache.name, temperature=0.1, max_output_tokens=1024
)

llm = GoogleGenAI(model="gemini-2.5-flash", generation_config=config)

response = llm.complete("List the first five chapters of the document")
print(response)Here are the first five chapters of the document, as listed in the Table of Contents:
1. A Dialogue on the Book
2. Introduction to Operating Systems
3. A Dialogue on Virtualization
4. The Abstraction: The Process
5. Interlude: Process API缓存管理
# List all caches
caches = client.caches.list()
for cache_item in caches:
    print(f"Cache: {cache_item.display_name} ({cache_item.name})")
    print(f"Tokens: {cache_item.usage_metadata.total_token_count}")

# Get cache details
cache_info = client.caches.get(name=cache.name)
print(f"Created: {cache_info.create_time}")
print(f"Expires: {cache_info.expire_time}")

# Delete cache when done
client.caches.delete(name=cache.name)
print("Cache deleted")Cache: Document Analysis Cache (cachedContents/8v3va2x...)
Tokens: 77421
Created: 2025-07-08 16:06:11.821190+00:00
Expires: 2025-07-08 17:06:10.813310+00:00
Cache deleted多模态支持
使用 ChatMessage 对象,你可以将图像和文本传给 LLM。
!wget https://cdn.pixabay.com/photo/2021/12/12/20/00/play-6865967_640.jpg -O image.jpg--2025-03-14 10:59:00-- https://cdn.pixabay.com/photo/2021/12/12/20/00/play-6865967_640.jpg
Resolving cdn.pixabay.com (cdn.pixabay.com)... 104.18.40.96, 172.64.147.160
Connecting to cdn.pixabay.com (cdn.pixabay.com)|104.18.40.96|:443... connected.
HTTP request sent, awaiting response... 200 OK
Length: 71557 (70K) [binary/octet-stream]
Saving to: ‘image.jpg’
image.jpg 100%[===================>] 69.88K --.-KB/s in 0.003s
2025-03-14 10:59:00 (24.8 MB/s) - ‘image.jpg’ saved [71557/71557]from llama_index.core.llms import ChatMessage, TextBlock, ImageBlock
from llama_index.llms.google_genai import GoogleGenAI
llm = GoogleGenAI(model="gemini-2.5-flash")
messages = [
ChatMessage(
role="user",
blocks=[
ImageBlock(path="image.jpg", image_mimetype="image/jpeg"),
TextBlock(text="What is in this image?"),
],
)
]
resp = llm.chat(messages)
print(resp)assistant: The image contains four wooden dice with black dots on a dark gray surface. Each die shows a different number of dots, indicating different values.你也可以传入文档。
from llama_index.core.llms import DocumentBlock

messages = [
    ChatMessage(
        role="user",
        blocks=[
            DocumentBlock(
                path="/path/to/your/test.pdf",
                document_mimetype="application/pdf",
            ),
            TextBlock(text="Describe the document in a sentence."),
        ],
    )
]

resp = llm.chat(messages)
print(resp)assistant: This research paper assesses and mitigates multi-turn jailbreak vulnerabilities in recent large language models (LLMs) using the Crescendo attack, evaluating prompt hardening and LLM-as-guardrail strategies across various task categories.最后,你也可以传入视频。
from llama_index.core.llms import VideoBlock

messages = [
    ChatMessage(
        role="user",
        blocks=[
            VideoBlock(
                path="/path/to/your/video.mp4", video_mimetype="video/mp4"
            ),
            TextBlock(text="Describe this video in a sentence."),
        ],
    )
]

resp = llm.chat(messages)
print(resp)assistant: A white SpaceX Crew Dragon capsule is shown approaching and docking with a module of the International Space Station, with the Earth's curvature visible in the background.结构化预测
LlamaIndex 提供直观的接口,可通过 structured_predict 将任意 LLM 转换为结构化 LLM——只需定义目标 Pydantic 类(可以嵌套),然后给定提示词,我们就会提取出所需对象。
from llama_index.llms.google_genai import GoogleGenAI
from llama_index.core.prompts import PromptTemplate
from llama_index.core.bridge.pydantic import BaseModel
from typing import List

class MenuItem(BaseModel):
    """A menu item in a restaurant."""

    course_name: str
    is_vegetarian: bool

class Restaurant(BaseModel):
    """A restaurant with name, city, and cuisine."""

    name: str
    city: str
    cuisine: str
    menu_items: List[MenuItem]

llm = GoogleGenAI(model="gemini-2.5-flash")
prompt_tmpl = PromptTemplate(
    "Generate a restaurant in a given city {city_name}"
)

# Option 1: Use `as_structured_llm`
restaurant_obj = (
    llm.as_structured_llm(Restaurant)
    .complete(prompt_tmpl.format(city_name="Miami"))
    .raw
)
# Option 2: Use `structured_predict`
# restaurant_obj = llm.structured_predict(Restaurant, prompt_tmpl, city_name="Miami")print(restaurant_obj)name='Pasta Mia' city='Miami' cuisine='Italian' menu_items=[MenuItem(course_name='pasta', is_vegetarian=False)]带流式输出的结构化预测
任何用 as_structured_llm 包装的 LLM 都支持通过 stream_chat 进行流式输出。
from llama_index.core.llms import ChatMessage
from IPython.display import clear_output
from pprint import pprint

input_msg = ChatMessage.from_str("Generate a restaurant in San Francisco")

sllm = llm.as_structured_llm(Restaurant)
stream_output = sllm.stream_chat([input_msg])
for partial_output in stream_output:
    clear_output(wait=True)
    pprint(partial_output.raw.dict())
    restaurant_obj = partial_output.raw

restaurant_obj{'city': 'San Francisco',
'cuisine': 'Italian',
'menu_items': [{'course_name': 'pasta', 'is_vegetarian': False}],
'name': 'Italian Delight'}
/var/folders/lw/xwsz_3yj4ln1gvkxhyddbvvw0000gn/T/ipykernel_76091/1885953561.py:11: PydanticDeprecatedSince20: The `dict` method is deprecated; use `model_dump` instead. Deprecated in Pydantic V2.0 to be removed in V3.0. See Pydantic V2 Migration Guide at https://errors.pydantic.dev/2.10/migration/
pprint(partial_output.raw.dict())
Restaurant(name='Italian Delight', city='San Francisco', cuisine='Italian', menu_items=[MenuItem(course_name='pasta', is_vegetarian=False)])工具/函数调用
Google GenAI 支持通过 API 直接进行工具/函数调用。使用 LlamaIndex,我们可以实现一些核心的智能体工具调用模式。
from llama_index.core.tools import FunctionTool
from llama_index.core.llms import ChatMessage
from llama_index.llms.google_genai import GoogleGenAI
from datetime import datetime

llm = GoogleGenAI(model="gemini-2.5-flash")

def get_current_time(timezone: str) -> dict:
    """Get the current time"""
    return {
        "time": datetime.now().strftime("%Y-%m-%d %H:%M:%S"),
        "timezone": timezone,
    }

# uses the tool name, any type annotations, and docstring to describe the tool
tool = FunctionTool.from_defaults(fn=get_current_time)我们可以简单地执行一次调用即可调用工具并获取结果:
resp = llm.predict_and_call([tool], "What is the current time in New York?")
print(resp){'time': '2025-03-14 10:59:05', 'timezone': 'America/New_York'}我们也可以使用更底层的 API 来实现智能体工具调用循环!
chat_history = [
    ChatMessage(role="user", content="What is the current time in New York?")
]
tools_by_name = {t.metadata.name: t for t in [tool]}

resp = llm.chat_with_tools([tool], chat_history=chat_history)
tool_calls = llm.get_tool_calls_from_response(
    resp, error_on_no_tool_call=False
)

if not tool_calls:
    print(resp)
else:
    while tool_calls:
        # add the LLM's response to the chat history
        chat_history.append(resp.message)

        for tool_call in tool_calls:
            tool_name = tool_call.tool_name
            tool_kwargs = tool_call.tool_kwargs

            print(f"Calling {tool_name} with {tool_kwargs}")
            tool_output = tool.call(**tool_kwargs)
            print("Tool output: ", tool_output)
            chat_history.append(
                ChatMessage(
                    role="tool",
                    content=str(tool_output),
                    # most LLMs like Gemini, Anthropic, OpenAI, etc. need to know the tool call id
                    additional_kwargs={"tool_call_id": tool_call.tool_id},
                )
            )

            resp = llm.chat_with_tools([tool], chat_history=chat_history)
            tool_calls = llm.get_tool_calls_from_response(
                resp, error_on_no_tool_call=False
            )
print("Final response: ", resp.message.content)Calling get_current_time with {'timezone': 'America/New_York'}
Tool output: {'time': '2025-03-14 10:59:06', 'timezone': 'America/New_York'}
Final response: The current time in New York is 2025-03-14 10:59:06.我们还可以在单次请求中同时调用多个工具,这使其能高效处理需要不同类型信息的复杂查询。
# Define another tool for temperature
def get_temperature(city: str) -> dict:
    """Get the current temperature for a city"""
    return {
        "city": city,
        "temperature": "25°C",
    }

# Create tools from functions
tool1 = FunctionTool.from_defaults(fn=get_current_time)
tool2 = FunctionTool.from_defaults(fn=get_temperature)

# Ask a question that requires both tools
chat_history = [
    ChatMessage(
        role="user",
        content="What is the current time and temperature in New York?",
    )
]

# The model will intelligently decide which tools to call
resp = llm.chat_with_tools([tool1, tool2], chat_history=chat_history)
tool_calls = llm.get_tool_calls_from_response(
    resp, error_on_no_tool_call=False
)

print(f"Model made {len(tool_calls)} tool calls:")
for i, tool_call in enumerate(tool_calls, 1):
print(f"{i}. {tool_call.tool_name} with args: {tool_call.tool_kwargs}")Model made 2 tool calls:
1. get_current_time with args: {'timezone': 'America/New_York'}
2. get_temperature with args: {'city': 'New York'}Google 搜索接地
Google Gemini 2.0 和 2.5 模型支持 Google 搜索接地,这允许模型搜索实时信息,并用网络搜索结果为其响应提供依据。这对于获取最新信息特别有用。
built_in_tool 参数接受 Google 搜索工具,使模型能够用 Google 搜索结果中的真实世界数据为其响应提供依据。
from llama_index.llms.google_genai import GoogleGenAI
from llama_index.core.llms import ChatMessage
from google.genai import types

# Create Google Search grounding tool
grounding_tool = types.Tool(google_search=types.GoogleSearch())

llm = GoogleGenAI(
    model="gemini-2.5-flash",
    built_in_tool=grounding_tool,
)

resp = llm.complete("When is the next total solar eclipse in the US?")
print(resp)The next total solar eclipse visible in the United States will occur on August 23, 2044. However, totality will only be visible in Montana, North Dakota, and South Dakota. Another total solar eclipse will occur on August 12, 2045, with a path spanning from California to Florida.Google 搜索接地工具提供多项优势:
- 实时信息:访问当前事件和最新数据
- 事实准确性:响应基于实际搜索结果
- 来源归属:接地元数据包含搜索来源
- 自动搜索决策:模型根据查询决定何时搜索
你也可以将接地工具与聊天消息一起使用:
# Using Google Search with chat messages
messages = [ChatMessage(role="user", content="Who won the Euro 2024?")]

resp = llm.chat(messages)
print(resp)

# You can access grounding metadata from the raw response
if hasattr(resp, "raw") and "grounding_metadata" in resp.raw:
    print(resp.raw["grounding_metadata"])
else:
print("\nNo grounding metadata in this response")assistant: Spain won Euro 2024, defeating England 2-1 in the final. The match took place at the Olympiastadion in Berlin. This victory marks Spain's fourth European Championship title, surpassing Germany for the most wins in the competition.
{'grounding_chunks': [{'retrieved_context': None, 'web': {'domain': None, 'title': 'olympics.com', 'uri': 'https://vertexaisearch.cloud.google.com/grounding-api-redirect/AUZIYQEkqnG_iRjkf89rilwO5fSBjbAADgm-Ad83fhYOhtAgW2qoG5Y8Gkselc-GshmvpqgMzke0vSUmkc6B8WwmXuxGBl9IPk3YWsytW2nOvGo1n8MlxqcrCpP62vvqjYFoo3wDQsb-tZ3RfZYTjKSTdKfVEBhvSfi4wSKMIgbnQkRx50DLqr2w3sjYI3hyZGWdsFyJFfviXdPSnVCZqQ=='}}, {'retrieved_context': None, 'web': {'domain': None, 'title': 'aljazeera.com', 'uri': 'https://vertexaisearch.cloud.google.com/grounding-api-redirect/AUZIYQFHwRYxryu8EgG5hG-Gwgdn9sRn88H8iehIOG7KPis7rpJcRo35EAc0onyC_5hqcjUozIddtikyjHmUdK2oIBX8_3ENpLTqpu8TyYb97EibGX6_-ZtRtlPnOsd4TukiRVwfiWMk5sk9FZCsNUEFTWb9OJzPhSjOiAPW78aoAQkM9LSKLBY5vBNyQtUsNvb7k6WEd23pHAKtofxi5i7W_qYrtZPiSkqOBTqtyJ2N69oYDw=='}}, {'retrieved_context': None, 'web': {'domain': None, 'title': 'wikipedia.org', 'uri': 'https://vertexaisearch.cloud.google.com/grounding-api-redirect/AUZIYQF2WEgQILX6A9y0uLZzBXY9UsduYELn9ahnW-FBNNHBvTQPWkuc_9cwyKmUEbfx0iton_BcIGh_85ibG5hkoE3kPvyBFfh6dEdy3UG2Vvn9gIprxruYLiUKtx8o6I06ZyFiERJqUzboU8s8Dvbd'}}, {'retrieved_context': None, 'web': {'domain': None, 'title': 'thehindu.com', 'uri': 'https://vertexaisearch.cloud.google.com/grounding-api-redirect/AUZIYQHqXK-zKOuGkYtQFyc48K49_TYwib-bRIvPqnn5UmjUcVI69vTxIiXnpXXkJtSMHa5-cBZ6Ht_4cAuWs5GuKZSzHeAQ-sHJQ2BEk52qIzjTvSteXGf7v0oBOQ_AUTqdTOpH8vXEVhqnp3o6WFVchKfexDT2sk1IDBqlqLxqQrKD9PrMsMOvU8_kfuGqH3IR_V2GHHnrPgwgR93LpiYvFdtVDlo3Wi12kj1FAgqDHHjkqyZpSc-pJ-522x0VgcdKGX6mXZ0Ssd7-aLK0YYO028ex6-o8ZeKEqeSpC9H7GP3bnw=='}}], 'grounding_supports': [{'confidence_scores': [0.97524184, 0.950235, 0.64699775], 'grounding_chunk_indices': [0, 1, 2], 'segment': {'end_index': 55, 'part_index': None, 'start_index': None, 'text': 'Spain won Euro 2024, defeating England 2-1 in the final'}}, {'confidence_scores': [0.9290034, 0.9209086], 'grounding_chunk_indices': [2, 3], 'segment': {'end_index': 109, 'part_index': None, 'start_index': 57, 'text': 'The match took place at the Olympiastadion in Berlin'}}, {'confidence_scores': [0.842964, 0.0068578157], 'grounding_chunk_indices': [2, 1], 'segment': {'end_index': 229, 'part_index': None, 'start_index': 111, 'text': "This victory marks Spain's fourth European Championship title, surpassing Germany for the most wins in the competition"}}], 'retrieval_metadata': {'google_search_dynamic_retrieval_score': None}, 'retrieval_queries': None, 'search_entry_point': {'rendered_content': '<style>\n.container {\n align-items: center;\n border-radius: 8px;\n display: flex;\n font-family: Google Sans, Roboto, sans-serif;\n font-size: 14px;\n line-height: 20px;\n padding: 8px 12px;\n}\n.chip {\n display: inline-block;\n border: solid 1px;\n border-radius: 16px;\n min-width: 14px;\n padding: 5px 16px;\n text-align: center;\n user-select: none;\n margin: 0 8px;\n -webkit-tap-highlight-color: transparent;\n}\n.carousel {\n overflow: auto;\n scrollbar-width: none;\n white-space: nowrap;\n margin-right: -12px;\n}\n.headline {\n display: flex;\n margin-right: 4px;\n}\n.gradient-container {\n position: relative;\n}\n.gradient {\n position: absolute;\n transform: translate(3px, -9px);\n height: 36px;\n width: 9px;\n}\n@media (prefers-color-scheme: light) {\n .container {\n background-color: #fafafa;\n box-shadow: 0 0 0 1px #0000000f;\n }\n .headline-label {\n color: #1f1f1f;\n }\n .chip {\n background-color: #ffffff;\n border-color: #d2d2d2;\n color: #5e5e5e;\n text-decoration: none;\n }\n .chip:hover {\n background-color: #f2f2f2;\n }\n .chip:focus {\n background-color: #f2f2f2;\n }\n .chip:active {\n background-color: #d8d8d8;\n border-color: #b6b6b6;\n }\n .logo-dark {\n display: none;\n }\n .gradient {\n background: linear-gradient(90deg, #fafafa 15%, #fafafa00 100%);\n }\n}\n@media (prefers-color-scheme: dark) {\n .container {\n background-color: #1f1f1f;\n box-shadow: 0 0 0 1px #ffffff26;\n }\n .headline-label {\n color: #fff;\n }\n .chip {\n background-color: #2c2c2c;\n border-color: #3c4043;\n color: #fff;\n text-decoration: none;\n }\n .chip:hover {\n background-color: #353536;\n }\n .chip:focus {\n background-color: #353536;\n }\n .chip:active {\n background-color: #464849;\n border-color: #53575b;\n }\n .logo-light {\n display: none;\n }\n .gradient {\n background: linear-gradient(90deg, #1f1f1f 15%, #1f1f1f00 100%);\n }\n}\n</style>\n<div class="container">\n <div class="headline">\n <svg class="logo-light" width="18" height="18" viewBox="9 9 35 35" fill="none" xmlns="http://www.w3.org/2000/svg">\n <path fill-rule="evenodd" clip-rule="evenodd" d="M42.8622 27.0064C42.8622 25.7839 42.7525 24.6084 42.5487 23.4799H26.3109V30.1568H35.5897C35.1821 32.3041 33.9596 34.1222 32.1258 35.3448V39.6864H37.7213C40.9814 36.677 42.8622 32.2571 42.8622 27.0064V27.0064Z" fill="#4285F4"/>\n <path fill-rule="evenodd" clip-rule="evenodd" d="M26.3109 43.8555C30.9659 43.8555 34.8687 42.3195 37.7213 39.6863L32.1258 35.3447C30.5898 36.3792 28.6306 37.0061 26.3109 37.0061C21.8282 37.0061 18.0195 33.9811 16.6559 29.906H10.9194V34.3573C13.7563 39.9841 19.5712 43.8555 26.3109 43.8555V43.8555Z" fill="#34A853"/>\n <path fill-rule="evenodd" clip-rule="evenodd" d="M16.6559 29.8904C16.3111 28.8559 16.1074 27.7588 16.1074 26.6146C16.1074 25.4704 16.3111 24.3733 16.6559 23.3388V18.8875H10.9194C9.74388 21.2072 9.06992 23.8247 9.06992 26.6146C9.06992 29.4045 9.74388 32.022 10.9194 34.3417L15.3864 30.8621L16.6559 29.8904V29.8904Z" fill="#FBBC05"/>\n <path fill-rule="evenodd" clip-rule="evenodd" d="M26.3109 16.2386C28.85 16.2386 31.107 17.1164 32.9095 18.8091L37.8466 13.8719C34.853 11.082 30.9659 9.3736 26.3109 9.3736C19.5712 9.3736 13.7563 13.245 10.9194 18.8875L16.6559 23.3388C18.0195 19.2636 21.8282 16.2386 26.3109 16.2386V16.2386Z" fill="#EA4335"/>\n </svg>\n <svg class="logo-dark" width="18" height="18" viewBox="0 0 48 48" xmlns="http://www.w3.org/2000/svg">\n <circle cx="24" cy="23" fill="#FFF" r="22"/>\n <path d="M33.76 34.26c2.75-2.56 4.49-6.37 4.49-11.26 0-.89-.08-1.84-.29-3H24.01v5.99h8.03c-.4 2.02-1.5 3.56-3.07 4.56v.75l3.91 2.97h.88z" fill="#4285F4"/>\n <path d="M15.58 25.77A8.845 8.845 0 0 0 24 31.86c1.92 0 3.62-.46 4.97-1.31l4.79 3.71C31.14 36.7 27.65 38 24 38c-5.93 0-11.01-3.4-13.45-8.36l.17-1.01 4.06-2.85h.8z" fill="#34A853"/>\n <path d="M15.59 20.21a8.864 8.864 0 0 0 0 5.58l-5.03 3.86c-.98-2-1.53-4.25-1.53-6.64 0-2.39.55-4.64 1.53-6.64l1-.22 3.81 2.98.22 1.08z" fill="#FBBC05"/>\n <path d="M24 14.14c2.11 0 4.02.75 5.52 1.98l4.36-4.36C31.22 9.43 27.81 8 24 8c-5.93 0-11.01 3.4-13.45 8.36l5.03 3.85A8.86 8.86 0 0 1 24 14.14z" fill="#EA4335"/>\n </svg>\n <div class="gradient-container"><div class="gradient"></div></div>\n </div>\n <div class="carousel">\n <a class="chip" href="https://vertexaisearch.cloud.google.com/grounding-api-redirect/AUZIYQGDOexAA_YpsZfc0vWPcNeDtSIFrZMwVD_d1Q6i1QKRUnNE0tqaCODc0dJCDKb0RZXm8CleNUU51BEFDcSDr9NNTgUvIxinjvxoyeNHaIJ_pFwyJoxnqAdbSkltDOX9ls8U-9RGYbCf9_hBLtvo6ohIFaXXnAMMa9f1oeGve-Ze5VoTWFXh4OGTp9GH8ZqjP2lFozkV">who won euro 2024</a>\n </div>\n</div>\n', 'sdk_blob': None}, 'web_search_queries': ['who won euro 2024']}代码执行
built_in_tool 参数还接受代码执行工具,使模型能够编写和执行 Python 代码来解决问题、执行计算和分析数据。这对于数学计算、数据分析和生成可视化特别有用。
from llama_index.llms.google_genai import GoogleGenAI
from llama_index.core.llms import ChatMessage
from google.genai import types

# Create code execution tool
code_execution_tool = types.Tool(code_execution=types.ToolCodeExecution())

llm = GoogleGenAI(
    model="gemini-2.5-flash",
    built_in_tool=code_execution_tool,
)

resp = llm.complete("Calculate 20th fibonacci number.")
print(resp)Okay, I can calculate the 20th Fibonacci number. I will use a python script to do this.
The 20th Fibonacci number is 6765.访问代码执行详情
当模型使用代码执行时,你可以通过原始响应访问执行的代码、结果和其他元数据。这包括:
- executable_code:实际执行的 Python 代码
- code_execution_result:运行代码的输出
- text:模型的解释和评论
让我们看看实际效果:
# Request a calculation that will likely use code execution
messages = [
    ChatMessage(
        role="user", content="What is the sum of the first 50 prime numbers?"
    )
]

resp = llm.chat(messages)

# Access the raw response to see code execution details
if hasattr(resp, "raw") and "content" in resp.raw:
    parts = resp.raw["content"].get("parts", [])

    for i, part in enumerate(parts):
        print(f"Part {i+1}:")

        if "text" in part and part["text"]:
            print(f"  Text: {part['text'][:100]}", end="")
            print(" ..." if len(part["text"]) > 100 else "")

        if "executable_code" in part and part["executable_code"]:
            print(f"  Executable Code: {part['executable_code']}")

        if "code_execution_result" in part and part["code_execution_result"]:
            print(f"  Code Result: {part['code_execution_result']}")
else:
print("No detailed parts found in raw response")Part 1:
Text: Okay, I need to calculate the sum of the first 50 prime numbers. I can use a python script to genera ...
Part 2:
Executable Code: {'code': "def is_prime(n):\n if n <= 1:\n return False\n if n <= 3:\n return True\n if n % 2 == 0 or n % 3 == 0:\n return False\n i = 5\n while i * i <= n:\n if n % i == 0 or n % (i + 2) == 0:\n return False\n i += 6\n return True\n\nprimes = []\nnum = 2\nwhile len(primes) < 50:\n if is_prime(num):\n primes.append(num)\n num += 1\n\nprint(f'{sum(primes)=}')\n", 'language': <Language.PYTHON: 'PYTHON'>}
Part 3:
Code Result: {'outcome': <Outcome.OUTCOME_OK: 'OUTCOME_OK'>, 'output': 'sum(primes)=5117\n'}
Part 4:
Text: The sum of the first 50 prime numbers is 5117.图像生成
部分模型还支持图像输出以及图像输入。使用 response_modalities 配置,我们可以用 Gemini 模型生成和编辑图像!
from llama_index.llms.google_genai import GoogleGenAI
import google.genai.types as types

config = types.GenerateContentConfig(
    temperature=0.1, response_modalities=["Text", "Image"]
)

llm = GoogleGenAI(
    model="gemini-2.5-flash-image-preview", generation_config=config
)from llama_index.core.llms import ChatMessage, TextBlock, ImageBlock
messages = [
ChatMessage(role="user", content="Please generate an image of a cute dog")
]
resp = llm.chat(messages)from PIL import Image
from IPython.display import display
for block in resp.message.blocks:
if isinstance(block, ImageBlock):
image = Image.open(block.resolve_image())
display(image)
elif isinstance(block, TextBlock):
print(block.text)Here's a cute dog for you!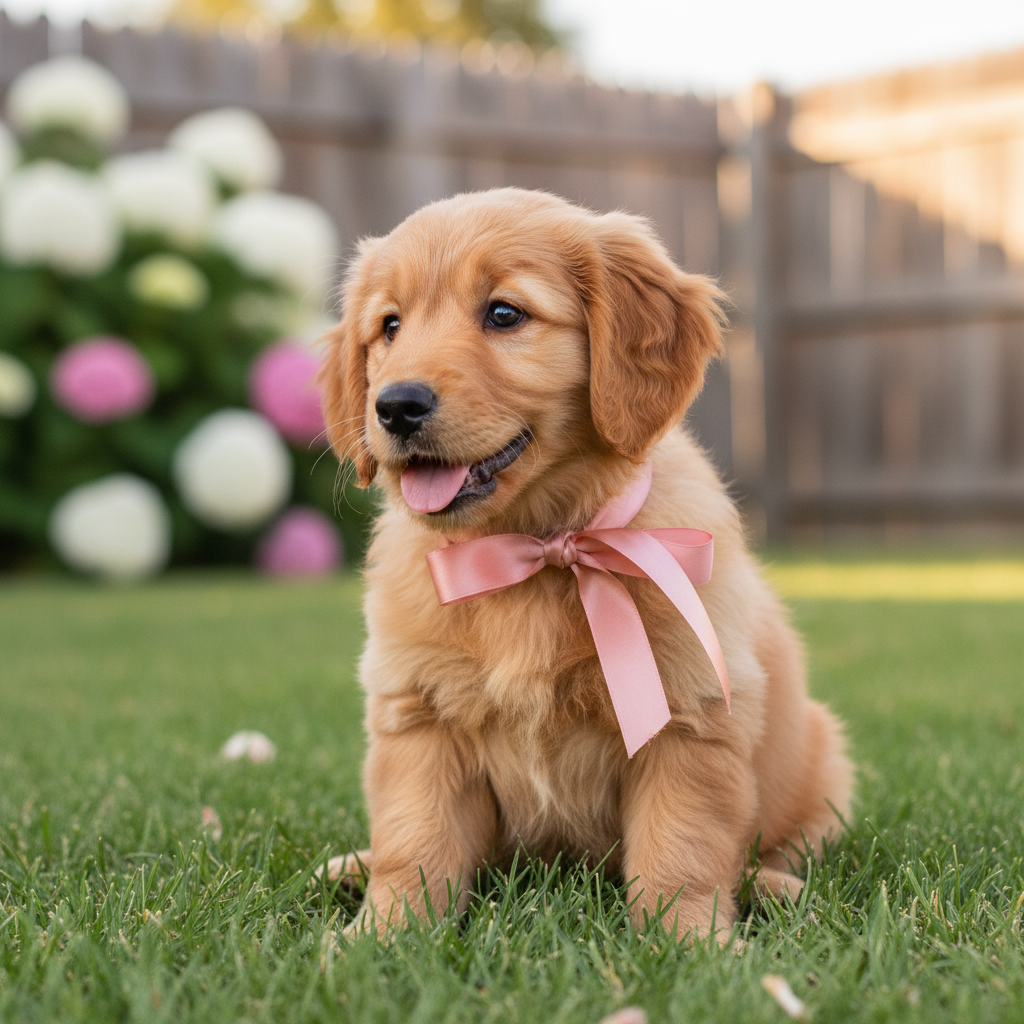
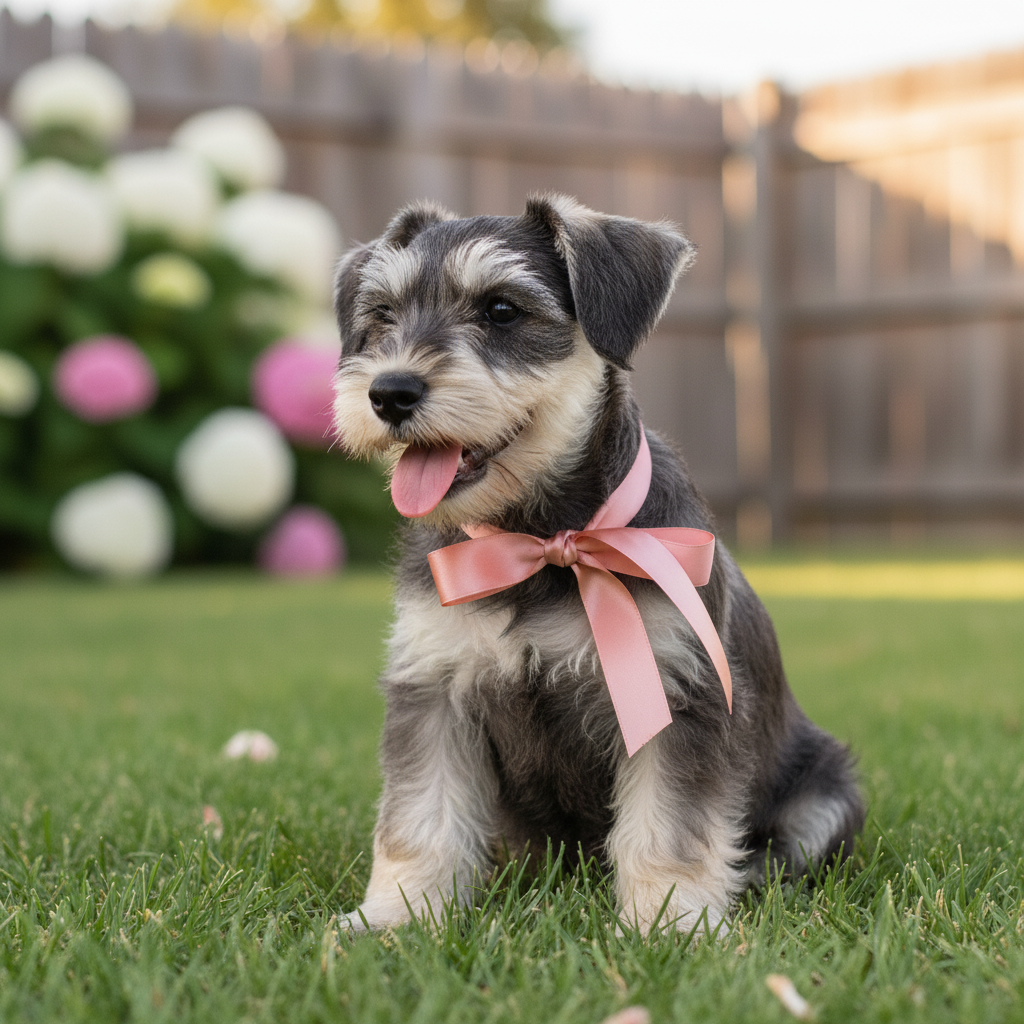
我们还可以编辑图像!
messages.append(resp.message)
messages.append(
    ChatMessage(
        role="user",
        content="Please edit the image to make the dog a mini-schnauzer, but keep the same overall pose, framing, background, and art style.",
    )
)

resp = llm.chat(messages)

for block in resp.message.blocks:
    if isinstance(block, ImageBlock):
        image = Image.open(block.resolve_image())
        display(image)
    elif isinstance(block, TextBlock):
print(block.text)Here's your mini-schnauzer!